
Pipeline hazards, interlocks and forwarding
About this chapter Datapath, microarchitecture and ISA
In this chapter
- Pipeline hazards, interlocks and forwarding
- Why hazards exist
- The correctness problem created by overlap
- Dependency terminology
- Register hazard equations in a simple pipeline
- Forwarding: use the value before architectural writeback
- Forwarding is a network, not a copy operation
- The load-use hazard
- Stalls and interlocks
- Structural hazards
- Resource occupancy and variable latency
- Memory dependencies are not register dependencies
- Flags and implicit architectural dependencies in x86
- Partial registers complicate dependency tracking
- Bubble semantics and side-effect suppression
- Priority among stall, flush and exception
- Control hazards as a boundary to the next chapter
- ChrisCPU: why these hazards are currently absent
- Architectural dependencies still matter in a functional interpreter
- Designing hazard metadata for a future ChrisCPU pipeline
- Forwarding priority invariant
- Stall correctness invariant
- Interaction with exceptions
- Interaction with stores and device I/O
- Complexity and scaling
- Verification plan for a future hazard model
- Current limitations
- Roadmap boundary
- Revision record
Why hazards exist
Pipelining overlaps instructions that would be separate in a sequential machine. The overlap improves throughput only if the processor prevents one instruction from observing state at the wrong time or competing for an unavailable resource.
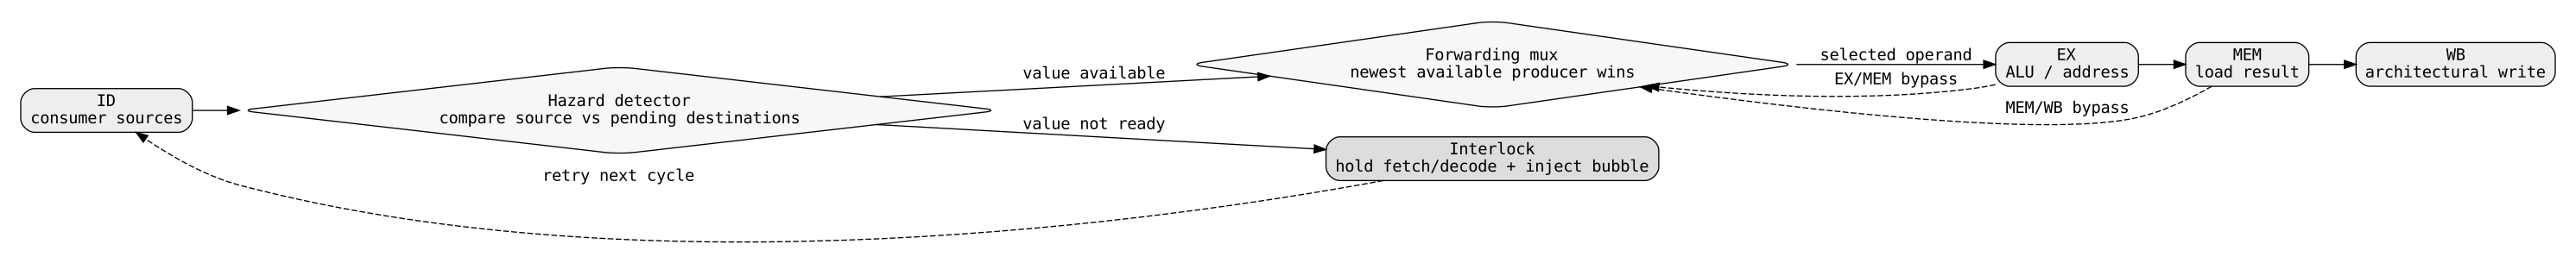
A pipeline hazard is a condition in which naive advancement of the next instruction would violate correctness or the pipeline's resource contract. Hazards are normally classified as:
- structural hazards — two operations require the same non-duplicated resource at the same time;
- data hazards — an instruction depends on data produced or consumed by another instruction;
- control hazards — the correct next instruction address is not yet known.
This chapter focuses on structural and data hazards plus the mechanisms that resolve them. Control hazards, prediction and speculation are treated in the following chapter.
The correctness problem created by overlap
Consider:
add rax, rbx
sub rcx, rax
The second instruction needs the value of RAX produced by the first. In a sequential interpreter this dependency is naturally respected because the ADD completes before SUB starts. In a five-stage teaching pipeline, however, SUB may attempt to read RAX in ID while ADD does not write it to the architectural register file until WB.
If the pipeline reads the old RAX and continues, execution is wrong. The processor must either:
- make the new value available early through forwarding/bypassing; or
- delay the dependent instruction with a stall/interlock until the value is available.
A hazard mechanism is therefore not an optional performance feature. Its first responsibility is correctness.
Dependency terminology
Let instruction A appear before instruction B in program order.
Read after write — RAW
B reads a location that A writes.
A: r1 <- ...
B: ... <- r1
RAW is a true data dependency. B requires the value produced by A.
In a simple in-order scalar pipeline, RAW is the principal register dependency that can produce a hazard.
Write after read — WAR
A reads a location and B later writes it.
A: ... <- r1
B: r1 <- ...
WAR is an anti-dependency. The architectural program requires A to observe the old value before B replaces it.
A basic in-order pipeline that reads operands before later instructions can write them naturally preserves this ordering. WAR becomes important when execution is allowed to move out of order. Register renaming removes many WAR constraints by giving the two logical uses different physical storage.
Write after write — WAW
A writes a location and B later writes the same location.
A: r1 <- ...
B: r1 <- ...
The final visible value must come from B. An in-order pipeline that commits writes in order usually preserves WAW automatically. Out-of-order completion can violate it unless retirement or renaming machinery preserves architectural order.
The distinction matters: RAW expresses a real value flow. WAR and WAW arise from reusing architectural names.
Register hazard equations in a simple pipeline
Suppose the instruction in ID has source registers Rs1 and Rs2. Older instructions in EX/MEM and MEM/WB may have destination registers Rd_EXMEM and Rd_MEMWB. A simple RAW detector asks whether a valid older instruction will write a register that the younger instruction needs.
Conceptually:
hazard_EXMEM =
    EXMEM.valid
    and EXMEM.reg_write
    and EXMEM.rd != NONE
    and (EXMEM.rd == ID.rs1 or EXMEM.rd == ID.rs2)

hazard_MEMWB =
    MEMWB.valid
    and MEMWB.reg_write
    and MEMWB.rd != NONE
    and (MEMWB.rd == ID.rs1 or MEMWB.rd == ID.rs2)
This is only a teaching equation. Real x86 decoding must account for implicit operands, partial registers, flags, memory dependencies, vector state, control registers and operation-specific semantics.
For example, ADC reads the carry flag in addition to explicit operands. A branch may read condition flags. PUSH and CALL interact with RSP. REP-prefixed string operations use implicit registers. A hazard model that tracks only explicit ModR/M registers is incomplete.
Forwarding: use the value before architectural writeback
Forwarding routes a newly produced value directly from a later pipeline stage to an earlier consumer instead of waiting for the register file to be updated.
Consider:
add rax, rbx
sub rcx, rax
If ADD computes its result in EX during cycle 3 and SUB needs that operand in EX during cycle 4, the value can be forwarded from the EX/MEM pipeline register into the ALU input of SUB.
A forwarding selector for one operand can be described by priority:
if EXMEM writes required source:
    use EXMEM.result
else if MEMWB writes required source:
    use MEMWB.result
else:
    use register_file_value
The newest matching producer must win. If two older instructions target the same architectural register, the younger of those producers contains the value required by the consumer.
Example:
mov rax, 1
mov rax, 2
add rcx, rax
If both older instructions are simultaneously in hazard-relevant stages, forwarding must select the value 2, not 1.
Forwarding is a network, not a copy operation
Hardware forwarding requires:
- comparators between source and destination identifiers;
- muxes on execution-unit inputs;
- control logic selecting the correct producer;
- wires crossing physical regions of the core;
- metadata indicating whether a result is valid and available.
With multiple issue width and many execution units, the bypass network can become expensive in area, routing and timing. A theoretically simple "forward the newest value" rule can become one of the physical design limits of a wide processor.
A software timing simulator faces a different cost. It usually performs explicit comparisons and selects values algorithmically. For S source operands and P possible producers, a straightforward implementation performs O(S*P) dependency comparisons per instruction. Hardware may perform these comparisons concurrently, while simulator cost is sequential CPU work.
The load-use hazard
Forwarding cannot eliminate every RAW delay.
Consider a classic five-stage pipeline:
load rax, [rbx]
add  rcx, rax
The load's data becomes available only after the MEM stage. The dependent ADD ordinarily needs its operand at the beginning of EX one cycle too early.
A common solution inserts one bubble:
| Cycle | IF | ID | EX | MEM | WB |
|---|---|---|---|---|---|
| 1 | LOAD | — | — | — | — |
| 2 | ADD | LOAD | — | — | — |
| 3 | next | ADD | LOAD | — | — |
| 4 | stalled | ADD | bubble | LOAD | — |
| 5 | ... | next | ADD | bubble | LOAD |
The load result can then be forwarded from MEM/WB or an equivalent point into the consumer.
A teaching detector might use:
if IDEX.is_load
   and IDEX.rd != NONE
   and (IDEX.rd == IFID.rs1 or IDEX.rd == IFID.rs2):
    stall_fetch = true
    stall_decode = true
    inject_bubble_into_execute = true
The exact timing depends on the pipeline organization. Some designs can forward data from a cache path sooner; others require longer stalls on cache misses.
Stalls and interlocks
An interlock is control logic that detects a condition requiring delay and prevents the pipeline from advancing incorrectly.
A stall must preserve the blocked instruction. If decode is waiting for an operand:
- the PC/fetch state may need to stop;
- IF/ID must keep the same instruction;
- a bubble may be inserted into ID/EX;
- older instructions continue toward completion.
The ordering of these control actions matters. Accidentally allowing IF/ID to advance while ID is stalled loses the blocked instruction. Accidentally re-executing an older side-effecting stage can duplicate memory or device effects.
For a simulator, the safest approach is to derive a complete next-cycle state from a read-only current-cycle snapshot. Stall control then chooses which records are copied forward, held, invalidated or replaced by bubbles.
Structural hazards
A structural hazard occurs when concurrent instructions need the same finite resource.
A classic example is a machine with one memory port shared by instruction fetch and data access. During a cycle in which a load uses memory in MEM, the IF stage cannot fetch a new instruction through the same port.
Possible resolutions include:
- stall one requester;
- duplicate or multi-port the resource;
- separate instruction and data caches;
- queue requests;
- arbitrate with priority or fairness rules.
Other examples include:
- one multiplier used by several issue slots;
- too few register-file read/write ports;
- a full load/store queue;
- a full reorder buffer;
- insufficient decoder bandwidth;
- saturated cache miss tracking structures.
A structural stall is not necessarily evidence of a data dependency. Two independent instructions can conflict because the implementation lacks simultaneous capacity.
Resource occupancy and variable latency
For fixed one-cycle execution units, a busy bit may be sufficient. Multi-cycle or variable-latency units require richer state.
A divider could expose:
| Field | Meaning |
|---|---|
| valid | operation is active |
| remaining | cycles until nominal completion |
| destination | architectural or physical destination |
| operands/result | internal operation state |
| exception | divide error or other fault |
| owner age | instruction identity/order |
If a unit is not pipelined internally, no new divide can begin until it becomes free. If it is pipelined, it may accept a new operation every cycle even though each result takes several cycles.
Thus latency and initiation interval are different properties. A multiplier can have latency 4 cycles but initiation interval 1 cycle.
Memory dependencies are not register dependencies
Consider:
store [rax], rbx
load  rcx, [rdx]
Whether the load depends on the store depends on the addresses, not register names alone. If RAX and RDX resolve to the same address, executing the load too early may read stale data.
A simple in-order pipeline can avoid much complexity by performing memory operations in program order. More advanced processors use load/store queues and address-disambiguation logic to allow independent loads to proceed while preserving memory-order rules.
The problem becomes harder because effective addresses may be unknown until execution, and stores may have known addresses but unavailable data, or vice versa.
This is one reason a future timing model should introduce register hazards before attempting aggressive memory speculation.
Flags and implicit architectural dependencies in x86
x86-64 has dependencies that are easy to omit in a simplified model.
Examples:
- ADD writes status flags.
- ADC reads carry and writes flags.
- CMP writes flags without a general-purpose destination.
- Jcc reads flags.
- INC/DEC have flag behavior different from ADD/SUB.
- CALL and PUSH read and write RSP.
- RET reads stack memory and changes RSP and RIP.
- string operations use implicit RSI, RDI, RCX and flags depending on the instruction.
A correct x86 dependency model therefore needs a normalized description of every instruction's read set and write set.
One useful simulator representation is:
ReadSet  = {architectural resources consumed by instruction}
WriteSet = {architectural resources produced by instruction}
A hazard exists when a younger ReadSet intersects an older pending WriteSet. Out-of-order models additionally care about write/write and write/read name conflicts until renaming resolves them.
The current ChrisInsn structure records decoded operation fields but does not expose a complete generic read/write-set abstraction. Adding one would be useful before building a timing pipeline.
Partial registers complicate dependency tracking
x86 register names overlap. AL, AX, EAX and RAX refer to different-width views of the same architectural register family. Writes can also have special extension behavior: a 32-bit write to EAX zero-extends into RAX.
A hazard model that treats each textual register as independent would be wrong.
A practical normalized representation can track:
- register family identifier, such as RAX;
- byte/bit mask of the portion read;
- byte/bit mask written;
- whether the write defines upper bits.
Then overlap checks operate on masks rather than names.
For an educational first pipeline, another defensible choice is conservative family-level dependency: any access to AL/AX/EAX/RAX conflicts with any pending write in the RAX family. It may introduce unnecessary stalls, but remains correct. Optimization can come after validation.
Bubble semantics and side-effect suppression
A bubble must not produce side effects. This sounds simple, but every side-effecting path must obey validity.
A valid bit should gate:
- register writeback;
- memory stores;
- I/O port writes;
- MMIO writes;
- exception delivery;
- branch redirect;
- counter events attributed to committed instructions.
If a flushed slot still reaches a store stage with its stale control bits, a wrong-path memory write can escape. In hardware this is a correctness failure; in a simulator it is an implementation bug with the same architectural consequence.
The strongest design pattern is to make side-effecting functions require an instruction record that is explicitly valid and authorized to commit.
Priority among stall, flush and exception
Several conditions can occur in one cycle. Control must define precedence.
A reasonable teaching policy is:
- reset/machine shutdown;
- oldest synchronous exception;
- branch or control redirect from the oldest valid instruction requiring it;
- structural/data stalls;
- ordinary advancement and fetch.
The exact policy depends on where conditions are discovered, but it must be deterministic and consistent with instruction age.
For example, a branch misprediction that flushes a younger load should normally make that load's dependency stall irrelevant. A stalled wrong-path instruction should not block redirection.
Control hazards as a boundary to the next chapter
A branch creates uncertainty about the next fetch address. Without prediction, an in-order pipeline can stall fetch until the branch resolves. With prediction, it can continue along a guessed path and flush if wrong.
The hazard machinery built here is still required:
- branch source operands may need forwarding;
- branch condition flags may have RAW dependencies;
- a branch may stall waiting for a load;
- flush logic must invalidate younger operations.
Prediction changes performance behavior, not the fundamental dependency correctness rules.
ChrisCPU: why these hazards are currently absent
At revision e05a17fd76333114a3fb5c2452f38ca747d4ac56, cpu_run processes one instruction completely before beginning the next.
The reviewed execution path is:
fetch_insn
    -> chris_decode
    -> chris_execute
    -> RIP update when required
    -> maybe_irq
    -> step/TSC accounting
    -> next instruction
Register helpers such as chris_read_gpr and chris_write_gpr operate on the architectural state used by the current instruction. Once chris_execute returns, the next loop iteration sees the resulting architectural state.
Consequences:
- there is no simultaneous older and younger instruction competing for one emulated pipeline resource;
- a dependent instruction naturally reads the state left by its predecessor;
- there is no load-use timing gap because memory access is synchronous from the interpreter's point of view;
- there is no need for a register forwarding network;
- there is no pipeline bubble or interlock state.
This is a property of the current abstraction, not of x86 hardware.
Architectural dependencies still matter in a functional interpreter
Although timing hazards are absent, instruction dependencies still matter semantically.
For example:
add rax, rbx
adc rcx, rdx
ADC depends on the carry flag produced by ADD. The interpreter preserves this because ADD updates arch.rflags before the next instruction executes.
Similarly:
mov eax, 1
add rbx, rax
requires the architectural zero-extension behavior of the EAX write to be correct before ADD reads RAX. Functional emulation can therefore validate dependency semantics even though it does not model the temporal mechanism hardware uses to satisfy them.
This makes the interpreter an appropriate oracle for a future pipelined backend.
Designing hazard metadata for a future ChrisCPU pipeline
Before implementing forwarding, the decoder should expose normalized dependency metadata.
A possible internal record is:
| Field | Purpose |
|---|---|
| src[] | source resource identifiers |
| src_mask[] | bit/byte coverage of each source |
| dst[] | destination resource identifiers |
| dst_mask[] | written coverage |
| reads_flags | required RFLAGS subset |
| writes_flags | produced RFLAGS subset |
| mem_read | instruction may read memory |
| mem_write | instruction may write memory |
| serializing | requires stronger pipeline control |
| variable_latency | result availability is not fixed |
This record can be derived from ChrisInsn after decode. It should not replace instruction semantics; it is scheduling metadata.
A minimal scalar implementation can then compute:
for each source of decode instruction:
    find newest older producer
    if producer result is forwardable:
        select bypass
    else if producer not yet available:
        stall
The newest producer rule preserves program-order value flow.
Forwarding priority invariant
Suppose three instructions are in flight:
I1: rax <- 1
I2: rax <- 2
I3: rcx <- rax + 3
I3 must consume I2's value. Therefore the forwarding search must traverse producers from youngest older instruction toward oldest, or explicitly assign priority to the nearest pipeline stage containing the most recent definition.
Invariant:
For every source operand, the selected producer must be the youngest older valid instruction whose pending write overlaps that source.
If no such instruction exists, the architectural register file is the source.
This invariant generalizes beyond a fixed five-stage pipeline.
Stall correctness invariant
When a dependent instruction cannot advance:
- its identity remains unchanged;
- its source/destination metadata remains unchanged;
- older instructions are allowed to progress unless another condition blocks them;
- no copy of the stalled instruction is created downstream;
- fetch does not overwrite upstream state that must be retried.
A useful test is to attach a monotonically increasing internal instruction sequence number. After every cycle, assert that a valid sequence number exists in at most one pipeline slot unless the implementation intentionally duplicates metadata references without duplicating execution ownership.
Interaction with exceptions
Hazard machinery must not hide or duplicate exceptions.
If an instruction is stalled before execution, it should not repeatedly raise an execution exception because execution has not occurred. If a fault is discovered in an older stage, younger stalled instructions must be flushed when the fault redirects control.
A forwarded value from an instruction that will later be squashed cannot become architectural state through the consumer. This is straightforward in a non-speculative in-order pipeline if forwarding only occurs from older valid instructions that are guaranteed to complete. It becomes more subtle with speculation and out-of-order execution.
Interaction with stores and device I/O
Stores, MMIO writes and port I/O are externally visible effects. A timing model must not perform them simply because an instruction reached an early execution stage.
A safe teaching design delays irreversible side effects until the instruction is known not to be flushed by an older event. Alternatively, it can record the operation in a store/output buffer and release it at commit.
This matters especially for ChrisVM because device models are part of the same process. Executing a wrong-path MMIO write could mutate emulator device state even if architectural CPU state is later rolled back.
Therefore a future pipeline must define commit semantics for:
- RAM stores;
- MMIO;
- port I/O;
- interrupt acknowledgement;
- shutdown or halt effects.
Complexity and scaling
For a scalar pipeline with two source operands and a small fixed number of older producer stages, dependency detection is small and deterministic.
For width W with H in-flight hazard-visible groups, a naive comparator count scales roughly with:
O(W * sources_per_instruction * H * W)
depending on organization. Physical implementations use parallel comparators, banking, clustered execution and other techniques to contain timing and wiring cost.
A software simulator may choose data structures better suited to sequential execution. A scoreboard mapping each architectural resource to its newest pending producer can reduce repeated searches. However, scoreboard updates must correctly handle flushes and multiple definitions.
This is a trade-off between implementation simplicity and simulator speed.
Verification plan for a future hazard model
Directed tests should begin with dependency kernels whose architectural results are obvious.
ALU forwarding
mov rax, 4
add rax, 3
add rbx, rax
Expected: RBX consumes 7 without an unnecessary long stall.
Newest producer wins
mov rax, 1
mov rax, 9
add rbx, rax
Expected: consumer sees 9.
Load-use
load rax, [address]
add  rbx, rax
Expected: pipeline inserts the required delay for the chosen memory timing and produces the same architectural result as the functional interpreter.
Flag dependency
cmp rax, rbx
je  target
Expected: branch consumes the flags produced by CMP.
Flush plus dependency
Construct a taken/mispredicted branch where a wrong-path dependent instruction has already entered the pipeline. Expected: no register or memory side effect from that instruction.
Exception plus younger store
Cause an older instruction to fault while a younger store is resident. Expected: the younger store never reaches architectural memory or device state.
Differential testing should compare committed state against the functional ChrisCPU backend after each retired instruction.
Current limitations
The current ChrisCPU implementation does not model:
- pipeline RAW stalls;
- structural resource contention;
- forwarding muxes;
- load-use timing;
- register scoreboards;
- per-stage valid/bubble state;
- memory dependency speculation;
- superscalar hazard detection.
These mechanisms are theory and future design material in this chapter.
The source also does not yet expose a complete normalized instruction read/write set. Any future pipeline should derive that metadata from decoded semantics rather than guess dependencies from opcode names.
Roadmap boundary
A disciplined implementation sequence is:
- add normalized read/write metadata for decoded instructions;
- implement a scalar pipeline with no forwarding, stalling conservatively on every pending RAW;
- validate architectural equivalence against the functional interpreter;
- add EX/MEM and MEM/WB forwarding;
- add a defined load-use interlock;
- model structural occupancy for selected multi-cycle resources;
- define store/MMIO commit behavior;
- add control-hazard prediction only after stall/flush precedence is proven;
- introduce more aggressive scheduling only after the in-order model is stable.
This sequence keeps correctness evidence ahead of performance sophistication.
Revision record
This chapter was reconciled against ChrisOS main revision e05a17fd76333114a3fb5c2452f38ca747d4ac56. Claims about the current emulator are limited to the declared source files. Hazard equations, forwarding networks and pipeline timing are architectural theory and proposed validation structure, not claims that those mechanisms already exist in ChrisCPU.