
PMM allocation algorithms and invariants
About this chapter Frames and address translation
In this chapter
- PMM allocation algorithms and invariants
- Scope
- Core representation
- Invariant: allocation searches only USABLE ranges
- Initialization invariant
- Next-fit-like single-page search
- Cursor rollback on free
- Search boundaries
- Eight-page skip optimization
- Run-detection state machine
- Claim is a separate state transition
- Why pmm_claim_at validates twice conceptually
- pmm_foreach_free_run
- Recursive lock requirement
- Interrupt-state invariant
- CPU-indexed recursion state
- Lock-order invariant
- Zero as failure sentinel
- Allocation linearization point
- Single-page allocation complexity
- Contiguous allocation strategy
- Fragmentation implications
- Free semantics
- Accounting invariant
- DMA32 as a nested allocator
- DMA32 fragmentation
- DMA32 ownership boundary
- Initialization cost
- Why a buddy allocator would differ
- Per-CPU page caches
- Validation strategy for allocator algorithms
- Debugging allocator failures
- Current limitations
- Source map
Scope
The physical-memory chapter defines what the PMM owns. This chapter concentrates on how the current allocator searches, claims, frees and synchronizes frames.
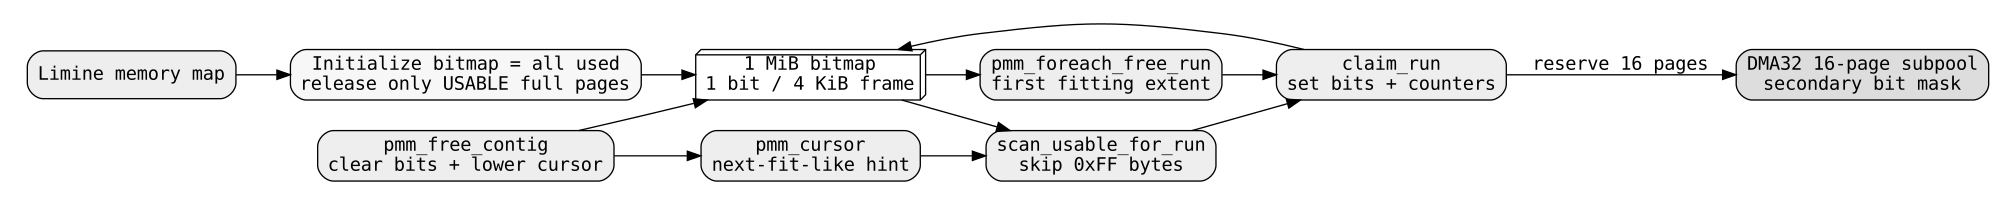
The implementation is not a generic bitmap allocator in the abstract. It combines:
- a fixed one-bit-per-frame representation;
- a Limine memory-map filter;
- a next-fit-like cursor for one-page allocation;
- byte-level skip optimization;
- free-run enumeration for contiguous allocation;
- all-or-nothing claim validation;
- same-CPU recursive locking;
- a second bitmap-like state for DMA32 suballocation.
The important properties are not just the data structures but the invariants connecting them.
Core representation
For physical frame number (i):
The representation supports constant-time state tests and mutations.
A bit alone does not encode:
- owner;
- reference count;
- allocation generation;
- memory-map type;
- NUMA node;
- zeroed/dirty state.
Those properties either live elsewhere or are not modeled.
The allocator therefore has a deliberately narrow state space:
Invariant: allocation searches only USABLE ranges
Bitmap state is necessary but not sufficient for allocation.
scan_usable_for_run and pmm_foreach_free_run iterate the Limine memory map and only scan entries whose type is LIMINE_MEMMAP_USABLE.
This creates a two-part allocation predicate:
allocatable(frame) =
    frame belongs to current USABLE memmap interval
    AND bitmap bit is clear
    AND frame lies below PMM_MAX_PHYS
That is stronger than “bitmap bit is zero.”
This matters because the bitmap itself does not store the memory-map type.
Initialization invariant
The allocator begins with all bits set.
Then complete pages inside USABLE intervals are cleared.
Protected ranges are set again where required.
The intended invariant after initialization is:
Every frame the allocator may return is represented by a clear bit inside a Limine USABLE interval and below 32 GiB.
The first 1 MiB is forcibly reserved, so it is excluded even if the firmware map might otherwise make some portion usable.
This conservative initialization makes “unknown” default to unavailable.
Next-fit-like single-page search
pmm_alloc does not always start at page zero.
It searches from pmm_cursor:
After a successful claim:
This resembles next-fit because the search hint advances after allocation.
It differs from a textbook circular next-fit implementation because the scanner itself traverses memory-map entries and the caller explicitly performs a second scan from zero.
The behavior avoids rescanning low addresses for every normal allocation.
Cursor rollback on free
pmm_free_contig contains another policy:
This causes newly freed lower memory to re-enter the near-term search path.
Without rollback, a long-lived cursor near the top of RAM could leave reusable holes untouched until wraparound.
The policy does not guarantee immediate reuse of the exact freed frame because another free frame may exist earlier in the resumed scan interval.
Search boundaries
For each USABLE memory-map entry, the scanner computes:
If from_phys is above the aligned start, the start is moved upward to align_up(from_phys).
A run never crosses from one memory-map entry into another. Even if two entries happen to be physically adjacent, the algorithm resets run state at the entry boundary.
That is conservative because distinct firmware entries may encode separate ownership histories even when addresses are consecutive.
Eight-page skip optimization
The bitmap is byte-addressable, so one byte describes eight frames.
When:
the scanner knows all eight pages are unavailable and advances by:
instead of checking each bit.
This optimization only applies when the current page is aligned to the first bit of the bitmap byte.
It is especially useful across densely allocated spans.
Worst-case asymptotic complexity remains linear in scanned pages, but the constant factor improves.
Run-detection state machine
For a request of count pages, the scanner tracks:
run: current consecutive free-page count;run_start: physical address of the candidate run.
Pseudo-code:
run = 0

for each candidate page:
    if used:
        run = 0
        run_start = next_page
    else:
        if run == 0:
            run_start = page
        run += 1

        if run == count:
            claim(run_start, count)
            return run_start
This is a one-pass contiguous-run detector.
It requires O(1) auxiliary state regardless of the run length.
Claim is a separate state transition
claim_run assumes the caller already established that the run is free and valid.
It does not revalidate every bit.
For each page it:
- sets the bitmap bit;
- decrements free count;
- increments used count.
Then it advances the cursor.
This separation keeps the hot mutation path simple, but correctness depends on callers not invoking claim_run for an overlapping or invalid extent.
The function is static, which limits direct call sites to the PMM implementation.
Why pmm_claim_at validates twice conceptually
pmm_claim_at is exposed to other kernel code, so it cannot assume the selected run is still free merely because a caller observed it earlier.
It first loops over all pages and rejects the request if any page:
- is outside the managed range;
- is misaligned;
- has its used bit set.
Only then does it call claim_run.
Because PMM locking surrounds the entire operation, another CPU cannot claim one of those pages between validation and mutation.
This gives all-or-nothing semantics.
pmm_foreach_free_run
The enumeration API is an algorithmic building block rather than just a diagnostic iterator.
It scans USABLE regions and invokes a callback once for each maximal free run.
A callback return of zero terminates enumeration immediately.
The heap uses this to consume large PMM extents during initialization.
The PMM does not allocate an array of run descriptors, which would create an early-boot dependency on the heap.
Recursive lock requirement
pmm_foreach_free_run executes while the PMM lock is held.
The heap callback may call pmm_claim_at.
This creates:
A standard non-recursive spinlock would self-deadlock.
The PMM therefore maintains pmm_depth[cpu].
The same CPU increments its depth rather than reacquiring the lock.
This recursion is not a convenience feature for arbitrary call patterns; it exists to support a specific callback architecture.
Interrupt-state invariant
The outermost pmm_enter uses irq_save.
That:
- captures RFLAGS;
- executes
cli; - acquires the PMM spinlock.
The outermost pmm_leave releases the spinlock and restores IF only when it was set in the saved flags.
The invariant is:
While a CPU owns the PMM lock at outer depth, a maskable interrupt on that CPU cannot re-enter PMM and confuse same-CPU recursion state.
Without disabling interrupts, an IRQ could run while pmm_depth[cpu] > 0, be mistaken for legitimate recursion and access PMM state without independently owning the lock context.
CPU-indexed recursion state
Recursion depth and saved IRQ flags are arrays indexed by smp_current_cpu().
If the reported index is outside SMP_CPU_CAP, the code falls back to index zero.
Under normal execution, each online CPU must have a stable unique index.
The fallback is defensive, but if an unexpected CPU identity collision actually occurred during concurrent PMM use, two CPUs could share recursion bookkeeping incorrectly.
This makes correct SMP CPU identity an implicit dependency of PMM synchronization.
Lock-order invariant
The heap source explicitly documents:
PMM never acquires the heap lock.
This is a partial order.
If subsystem A may acquire PMM while holding its own lock, and PMM never calls back into A while locked, deadlock cycles are easier to avoid.
The free-run callback is a special case because the PMM intentionally calls caller code while locked. That is why the callback's allowed operations must respect the recursion/lock-order contract.
Zero as failure sentinel
The API uses physical address zero to mean allocation failure.
That convention is safe only because initialization reserves the entire first 1 MiB, including frame zero. A legitimate allocation can therefore never collide with the sentinel.
This is a small but important invariant connecting initialization policy to API design:
frame 0 permanently unavailable
    -> pmm_alloc can return 0 on failure
    -> callers can test "if (phys == 0)"
If a future allocator ever made physical page zero allocatable, the public return-value contract would become ambiguous and would need to change.
The same sentinel is used by contiguous and claim-at operations. Code must not interpret zero as “physical address zero was successfully allocated.”
Allocation linearization point
Under the PMM lock, the conceptual linearization point of an allocation is the transition where claim_run sets the bitmap bits.
Before that transition the selected frames are free; after it, no other correctly synchronized allocator call may return them.
For pmm_claim_at, validation and mutation happen inside one critical section, so there is no unlocked gap between “observed free” and “claimed.”
For free, the transition is the clearing of each bit while the same global lock is held.
These lock-scoped state transitions are what provide uniqueness across CPUs; the bitmap representation alone does not provide concurrency safety.
Single-page allocation complexity
Let (P) be the number of usable pages scanned before success or exhaustion.
A successful lookup can be near O(1) when the cursor immediately points to a free page.
Worst case is O(P).
With the byte skip, a fully used block of eight aligned pages is tested in one byte comparison.
The worst-case pattern for the skip optimization is a sparse bitmap where every byte has at least one zero bit but no acceptable run appears until late.
Then most pages still require bit-level examination.
Contiguous allocation strategy
pmm_alloc_contig(k) first asks pmm_foreach_free_run for the first maximal free run with at least (k) pages.
This is first-fit by memory-map traversal order.
After a candidate is found, pmm_claim_at performs full validation and claim.
The fallback scanner then performs another first-fit-style run search from zero if necessary.
Therefore the allocator does not optimize for best-fit fragmentation reduction.
It chooses the first adequate run.
Fragmentation implications
Consider free runs:
A 6-page request succeeds in the 7-page run.
After many variable-sized contiguous allocations/frees, total free pages can remain large while the largest free run shrinks.
The bitmap representation cannot move allocations to compact physical memory.
Thus:
does not imply:
This is external fragmentation.
Free semantics
pmm_free_contig(base, k) walks each page.
If the page is outside the representable range or misaligned, the kernel panics.
If its bit is set, the function clears it and adjusts counters.
If its bit is already clear, the function does nothing for that page.
This makes free idempotent with respect to the bitmap bit, but not necessarily semantically safe.
A repeated free may hide an ownership bug instead of exposing it.
Accounting invariant
Normal claims and frees are intended to preserve:
where usable is the post-static-reservation pool.
If a caller frees a frame that was reserved but not counted as a dynamic PMM allocation, accounting can become misleading.
Therefore the counter invariant relies on valid API ownership, not only on arithmetic in the functions.
This is another reason provenance tracking would improve debug builds.
DMA32 as a nested allocator
DMA32 uses two allocation layers.
First, PMM claims 16 contiguous pages globally.
Then a 16-bit availability mask manages subranges.
For request length (k):
need = (1 << k) - 1
for i where i + k <= 16:
    mask = need << i
    if (dma32_free & mask) == mask:
        clear mask
        return dma32_base + i * 4096
This is a tiny first-fit bit-run allocator.
Its maximum search space is fixed at 16 positions.
Complexity is effectively constant.
DMA32 fragmentation
Even inside 16 pages, fragmentation can matter.
Example:
There may be eight total free pages but no free run of eight.
The same distinction between total capacity and contiguous capacity applies.
Because the pool is small, the implementation chooses simple linear bit scanning rather than a more elaborate free-list.
DMA32 ownership boundary
The global PMM bitmap keeps all 16 pool frames marked used for the entire lifetime of the reserved pool.
pmm_free_dma32 only modifies dma32_free.
This is crucial:
A DMA32 subpage becoming free does not make it visible to general PMM scans.
Otherwise the same frame could simultaneously be handed to a normal PMM caller and later reallocated through the DMA32 mask.
The two-layer representation preserves isolation between allocators.
Initialization cost
PMM initialization has several linear components:
- filling the 1 MiB bitmap;
- walking the memory map;
- freeing USABLE pages one by one;
- reserving protected ranges page by page;
- scanning for the DMA32 run.
If (P) is the number of representable pages covered by those ranges, initialization is O(P) in the current implementation.
For the fixed 32 GiB ceiling, the maximum bitmap represents 8,388,608 frames.
This work occurs once during boot.
Why a buddy allocator would differ
A buddy allocator groups free blocks by power-of-two order.
It can find aligned contiguous power-of-two runs without linearly scanning every frame and can merge buddies when both halves become free.
ChrisOS does not currently implement those order lists or merge rules.
The bitmap approach has different trade-offs:
advantages - very small conceptual state; - direct O(1) page-status lookup; - easy early initialization; - no heap dependency.
costs - linear search; - weaker contiguous-allocation behavior under fragmentation; - no order-aware coalescing metadata.
A future replacement should be justified by measured allocation patterns and contention rather than by terminology alone.
Per-CPU page caches
Every general PMM operation currently funnels through the global PMM lock.
On a larger SMP workload, this can become contention.
A common extension is to maintain small per-CPU free-page caches and refill/drain them in batches from a global allocator.
ChrisOS does not currently have that layer.
Adding it would complicate the meaning of global counters because pages in a CPU cache are free for allocation but not necessarily present in the global free structure.
Validation strategy for allocator algorithms
A strong PMM test suite should test invariants, not only successful calls.
Useful cases include:
- allocate until exhaustion and prove no duplicate frames;
- free/reallocate and verify bitmap/counter restoration;
- random allocate/free sequences against a reference model;
- contiguous allocations under controlled fragmentation;
pmm_claim_atcollision rejection;- enumeration of runs at memory-map boundaries;
- concurrent SMP allocation uniqueness;
- interrupt-context re-entry behavior;
- DMA32 fragmentation and reuse;
- intentional double free to characterize current behavior;
- attempts at misaligned/out-of-range free;
- accounting equality after each valid transition.
The current built-in self-test covers only a subset: distinct pages, HHDM data integrity and reuse of a released page.
Debugging allocator failures
Symptoms often appear far from the allocator.
Duplicate allocation can manifest as:
- corrupt page tables;
- process memory changing unexpectedly;
- heap metadata damage;
- device descriptors mutating;
- impossible TLB behavior.
Useful diagnostic fields include:
- physical frame address;
- bitmap byte/bit;
- current cursor;
- used/free counters;
- caller/subsystem;
- current CPU;
- whether the frame is in DMA32;
- memory-map interval/type.
The current production representation stores only part of that information, so source-level tracing may be required.
Current limitations
Algorithmically, the current PMM lacks:
- strict double-free detection;
- owner/provenance records;
- reference counting;
- per-CPU caches;
- NUMA locality;
- buddy-order free structures;
- compaction;
- explicit allocation zones beyond the small DMA32 island;
- statistically informed search policy;
- bounded-latency allocation guarantees.
Therefore worst-case allocation latency grows with the amount of memory scanned.
The design remains appropriate as a small research kernel allocator, but those constraints matter as concurrency and RAM capacity grow.
Source map
The bitmap primitives, cursor scan, run detector, claim/free transitions, DMA32 mask and recursive lock protocol are in kernel/metal/pmm.c.
kernel/metal/heap.c provides the important callback/re-entry use case.
kernel/metal/spin.c/spin.h define the CAS lock and interrupt-state helpers.
kernel/metal/smp.c provides CPU identity used for recursion bookkeeping.
All implementation claims were reconciled against ChrisOS revision e05a17fd76333114a3fb5c2452f38ca747d4ac56.