
Out-of-order execution, register renaming and retirement
About this chapter Datapath, microarchitecture and ISA
In this chapter
- Out-of-order execution, register renaming and retirement
- Scope
- Why in-order execution leaves performance unused
- True and false dependencies
- Architectural registers and physical registers
- Why the old physical mapping cannot be freed immediately
- Free list
- Reorder Buffer
- Instruction window and scheduler
- Wakeup/select complexity
- Physical register readiness
- Execution units
- Completion versus retirement
- Precise exceptions
- Current ChrisCPU exception model versus OoO requirements
- Rename checkpoints for branch recovery
- Committed map versus speculative map
- Memory operations and the Load/Store Queue
- Store-to-load forwarding
- Memory disambiguation
- Stores retire differently from register results
- Branches in the ROB
- Resource backpressure
- Retirement
- In-order retirement and serializing behavior
- Flags renaming
- Partial register renaming
- Micro-operations
- Common Data Bus as a teaching abstraction
- Tomasulo's algorithm and modern renaming
- Dataflow view
- Head-of-line blocking at retirement
- Window size and latency hiding
- Interrupts and retirement boundaries
- TLB and translation side effects
- Atomic and locked operations
- Current ChrisCPU execution model
- Refactoring boundary for a future OoO backend
- Proposed minimal simulator structures
- Cycle ordering in a simulator
- Recovery resource accounting
- Invariants
- Differential validation
- Directed validation cases
- Performance metrics
- Complexity in a software simulator
- Current limitations
- Roadmap boundary
- Revision record
Scope
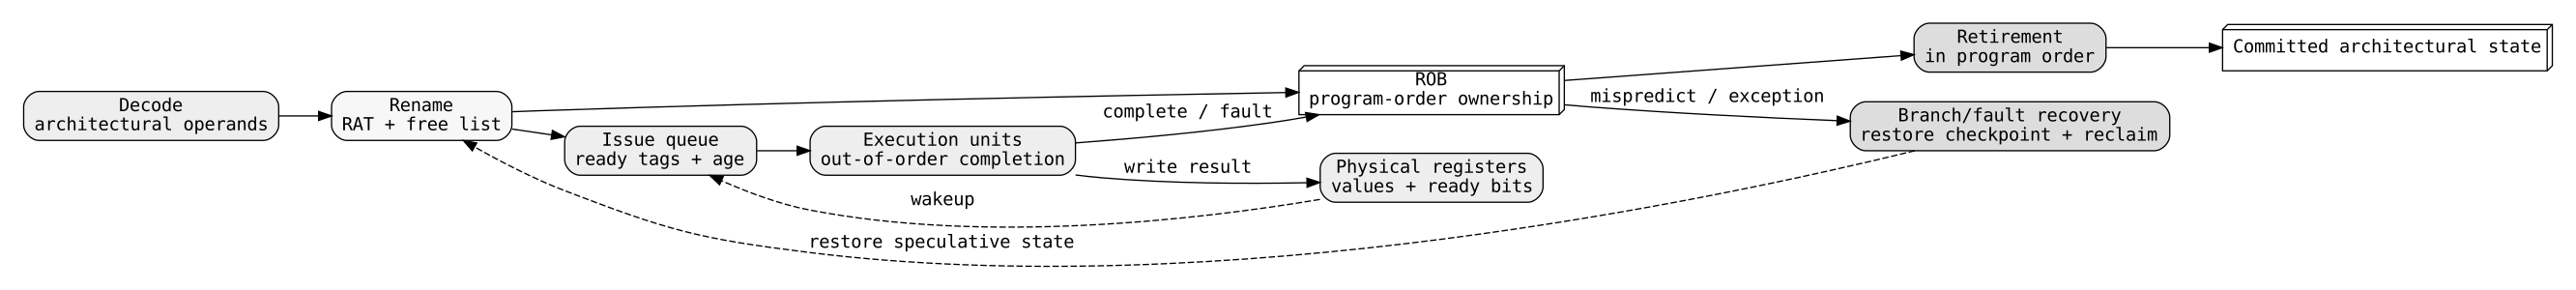
A pipeline can overlap instructions and forward values, but an in-order machine still stops useful younger work when an older instruction waits on a long-latency dependency. Out-of-order (OoO) execution separates program order from execution order: independent younger operations may execute while older operations are waiting, provided architectural state is committed as if the ISA's ordering rules had been respected.
This requires more than a scheduler. A complete OoO design needs machinery for:
- identifying true dependencies;
- eliminating false register-name dependencies;
- allocating speculative result storage;
- tracking which operands are ready;
- choosing ready operations for execution;
- remembering original program order;
- preserving precise exceptions;
- controlling stores and other irreversible effects;
- recovering from branch misprediction;
- reclaiming physical resources safely.
The core principle is:
Execution can be out of order; architectural retirement must preserve the defined program-order abstraction.
The current ChrisCPU implementation does not contain a reorder buffer, physical register file, rename map, issue queue, load/store queue or retirement engine. It executes one instruction completely before the next. This chapter therefore documents general microarchitecture and a possible future timing backend while explicitly identifying the source changes such a backend would require.
Why in-order execution leaves performance unused
Consider:
I1: load rax, [slow_address]
I2: add  rbx, rax
I3: add  rcx, rdx
I4: xor  r8, r9
I2 truly depends on I1, but I3 and I4 do not. A simple in-order issue machine may block I3 and I4 behind I2 while waiting for the load.
An OoO scheduler can recognize:
- I2 is not ready because RAX is pending;
- I3 is ready;
- I4 is ready.
It can execute I3 and I4 first while keeping architectural retirement ordered.
This ability exposes instruction-level parallelism (ILP) already present in the program. OoO hardware does not change the program's dependency graph; it attempts to find independent nodes that are ready earlier than their textual position suggests.
True and false dependencies
Three register dependency classes matter.
RAW — read after write
I1: rax <- ...
I2: ... <- rax
This is a true data dependency. I2 needs the value produced by I1. Renaming cannot remove it.
WAR — write after read
I1: ... <- rax
I2: rax <- ...
This is a name dependency. I1 needs the old RAX before I2 overwrites the architectural name.
WAW — write after write
I1: rax <- ...
I2: rax <- ...
Both instructions use the same architectural destination name. Final architectural state must reflect I2's value.
Register renaming maps each architectural destination to a new physical register. WAR and WAW disappear as scheduling constraints because different definitions use different physical storage.
Architectural registers and physical registers
The ISA might expose architectural register RAX. An OoO core can internally map that name to a physical register, for example P37.
A Rename Map Table (RAT) holds:
architectural register -> newest speculative physical register
Example:
Before rename:
RAX -> P5
RBX -> P9
Rename:
I1: ADD RAX, RBX
Steps:
- source RAX maps to P5;
- source RBX maps to P9;
- allocate new physical register P37;
- destination RAX becomes P37 in the speculative map;
- record old mapping P5 for later reclamation.
The renamed operation is effectively:
P37 <- P5 + P9
A later consumer of RAX uses P37 even before RAX is architecturally retired.
Why the old physical mapping cannot be freed immediately
When RAX is remapped from P5 to P37, P5 may still be needed.
Reasons include:
- an older in-flight instruction may read P5;
- branch recovery may need to restore the mapping that existed before P37;
- committed architectural state may still refer to P5 until I1 retires.
A common policy frees the previous committed/speculative mapping only when the redefining instruction retires and recovery can no longer require the old mapping.
This introduces a resource-lifetime invariant:
A physical register may return to the free list only when no older consumer, committed map or recovery checkpoint can still reference it.
Incorrect reclamation creates silent data corruption.
Free list
A free list tracks physical registers available for new destinations.
Operations:
allocate():
    remove one free physical register

release(p):
    return p after lifetime proof
The implementation can use:
- bitmap;
- stack;
- queue;
- circular free list.
For a fixed number P of physical registers, a bitmap allocator can use O(P/word_size) worst-case scanning unless it maintains a hint or hierarchy. A stack/free queue supports O(1) allocate/release but requires correct rollback semantics when speculative allocations are squashed.
A simulator should track ownership explicitly because "just decrement the next register index" fails once branches recover or the window wraps.
Reorder Buffer
The Reorder Buffer (ROB) records instructions in program order even when execution occurs out of order.
A conceptual ROB entry can contain:
| Field | Meaning |
|---|---|
| valid | slot contains an in-flight instruction |
| sequence | monotonic age |
| RIP | architectural instruction address |
| op | decoded or micro-op identity |
| destination architectural reg | architectural mapping affected |
| new physical reg | result location |
| old physical reg | mapping to release at retirement |
| completed | execution finished |
| exception | deferred fault descriptor |
| branch metadata | prediction/checkpoint information |
| store metadata | pending irreversible effect |
| result/status | information required for retirement |
ROB allocation happens in program order. Execution completion can be arbitrary. Retirement examines the oldest entry first.
If the oldest entry is incomplete, younger completed instructions normally cannot retire past it. This is the mechanism that reconstructs ordered architectural visibility.
Instruction window and scheduler
After rename, operations wait until their source operands and execution resources are ready.
A scheduler or issue queue entry might track:
- source physical register IDs;
- readiness bits;
- destination physical register;
- operation class;
- immediate;
- age/ROB index;
- execution-unit requirements;
- memory-operation metadata.
Wakeup occurs when a producer completes and announces that a destination physical register is ready.
Selection chooses among ready operations for available units.
Conceptually:
for each completed destination P:
    for each waiting source:
        if source.phys == P:
            source.ready = true

choose ready operations
subject to unit availability and policy
Real hardware performs many comparisons in parallel. A simple simulator can instead maintain consumer lists or readiness tables to reduce repeated scanning.
Wakeup/select complexity
A naive simulator with Q queue entries and S sources per instruction can scan O(Q*S) metadata for every completed result.
With W results per cycle, naive work can approach O(WQS).
Alternative simulator structures include:
- physical-register readiness array: O(1) readiness test at issue selection;
- per-register consumer lists;
- heaps or queues partitioned by execution class;
- event-driven wakeup lists.
Physical hardware faces different constraints: comparator fanout, wire delay and arbitration timing. Software complexity and hardware delay should not be equated, but both reflect the cost of a large instruction window.
Physical register readiness
A physical register normally has at least:
- allocated/free state;
- ready/not-ready state;
- value;
- optional producer identity.
At rename, a newly allocated destination is marked not ready.
When its producer executes successfully:
phys[new_dst].value = result
phys[new_dst].ready = true
Consumers can wake immediately, even though the producing instruction has not retired.
This is the key distinction between result availability and architectural commitment.
Execution units
OoO does not mean every operation can execute anywhere.
The machine may have:
- integer ALUs;
- branch units;
- shift units;
- multiply/divide units;
- address-generation units;
- load units;
- store-data units;
- vector units.
A scheduler selects ready operations whose required unit has capacity.
An operation can be data-ready but resource-blocked. That is a structural hazard represented at the scheduler rather than by freezing the whole front end.
Variable-latency operations need explicit completion events.
Completion versus retirement
These terms must remain distinct.
Completion means execution produced its result or exception status.
Retirement means the instruction is the oldest eligible architectural operation and its externally visible effects are accepted.
An ADD can complete many cycles before retirement because an older cache miss blocks the ROB head.
A younger fault can also "complete" by producing an exception descriptor, but that exception is not architecturally delivered until it reaches the retirement point and is still on the correct path.
Precise exceptions
Precise exceptions require the machine to appear as though:
- every older instruction completed architecturally;
- the faulting instruction did not complete beyond the architecture-defined point;
- no younger instruction committed.
OoO execution naturally violates execution order internally, so the ROB restores precise state.
If ROB head has an exception:
- retire all older entries already before it;
- do not commit the faulting instruction's normal destination;
- flush all younger entries;
- restore speculative rename/predictor state to committed state;
- deliver the exception using the faulting instruction's architectural RIP and error information.
This is a central reason exceptions from speculative execution cannot directly call architectural handlers at execution time.
Current ChrisCPU exception model versus OoO requirements
Current ChrisCPU helpers can call chris_raise during instruction execution. That is correct for the current sequential interpreter because no younger instruction exists in flight.
In an OoO backend, direct immediate mutation is unsafe. A speculative operation might fault and later be squashed by an older branch. Therefore execution should instead produce something like:
ExecResult {
    value;
    flags;
    fault_valid;
    fault_vector;
    fault_error;
    memory_effect;
    control_effect;
}
The ROB entry holds that result until retirement decides whether it becomes architectural.
This implies a significant refactoring boundary: instruction semantics need a non-committing form, or the timing backend must operate on shadow state rather than directly on ChrisArchitectureState.
Rename checkpoints for branch recovery
When a branch is predicted, younger instructions continue renaming architectural destinations.
If prediction fails, the rename map must return to the state that existed immediately after the branch, before wrong-path definitions.
Recovery approaches include:
- full RAT checkpoint per branch — simple, fast recovery, more storage;
- history buffer — record mapping changes and undo them;
- rebuild from committed map plus surviving ROB entries — less checkpoint storage, slower recovery.
For a teaching simulator, full checkpoints are often easiest to verify.
If there are A architectural register mappings and each physical-register ID requires log2(P) bits, one full checkpoint costs approximately:
A * ceil(log2(P)) bits
plus metadata.
x86 complications include flags, partial registers, vector registers and other renameable state.
Committed map versus speculative map
A robust design often distinguishes:
- speculative RAT — newest mapping used by incoming renamed instructions;
- retirement/committed map — mappings representing architecturally committed state.
At retirement of a destination instruction, committed map for that architectural register becomes the instruction's new physical register.
After a full pipeline flush caused by exception or interrupt, speculative RAT can be restored from committed map.
This separation gives a clean invariant:
The committed map always names physical values corresponding to architectural retirement state.
Memory operations and the Load/Store Queue
Registers are easy to rename because each definition can receive a new physical register. Memory addresses are dynamically computed and can alias.
An OoO machine therefore needs ordered tracking for loads and stores, commonly in a Load/Store Queue (LSQ).
A store entry can track:
- program-order age;
- effective address known/unknown;
- data known/unknown;
- size;
- fault state;
- commit permission.
A load entry can track:
- age;
- address;
- size;
- result;
- dependency/replay state.
The scheduler may execute a younger load before older stores only when ordering rules permit and alias risk is handled.
Store-to-load forwarding
If an older in-flight store targets the same bytes a younger load requests, the load may obtain data from the store queue rather than cache/memory.
Conceptually:
for older stores from youngest to oldest:
    if store address overlaps load address:
        if required bytes are available:
            forward newest matching bytes
        else:
            load must wait
The youngest older store wins for overlapping bytes because it is the latest program-order definition of that memory location.
Partial overlap complicates merging and byte masks.
Memory disambiguation
A younger load may have its address ready while some older stores still have unknown addresses.
Options:
- conservative: wait until all older store addresses are known;
- speculative: execute the load and later detect if an older store resolves to the same location.
Speculation improves memory-level parallelism but requires replay or recovery on violation.
A first educational ChrisCPU OoO model should prefer conservative memory ordering until register scheduling and retirement are proven.
Stores retire differently from register results
A speculative register result can sit harmlessly in a physical register. A store that writes RAM, MMIO or port-I/O can create irreversible external effects.
Therefore stores normally wait until they are non-speculative/retired before becoming globally visible, even if address and data were computed earlier.
For ChrisVM, this distinction is critical because MMIO callbacks can mutate device state. Wrong-path device writes cannot be "rolled back" safely unless the device model itself is transactional.
A future backend should therefore buffer store/I/O effects and release them at a defined commit point.
Branches in the ROB
A branch can execute early and resolve its prediction.
If correct: - mark branch completed; - keep younger work.
If wrong: - redirect fetch; - invalidate ROB/scheduler/LSQ entries younger than the branch; - reclaim their physical registers; - restore rename checkpoint; - restore speculative predictor history; - retain the branch and all older operations.
The branch itself still retires in program order later.
Recovery must not free physical registers belonging to older surviving instructions.
Resource backpressure
Finite OoO structures create front-end stalls.
Rename/dispatch must stop when any required resource is unavailable:
- ROB full;
- issue queue full;
- free physical register unavailable;
- load queue full;
- store queue full;
- branch checkpoint slots exhausted.
This is backpressure. A wide front end can only sustain high throughput if retirement and execution free resources fast enough.
A simulator should expose counters for each stall reason; otherwise a single "pipeline stalled" number hides the actual limiting structure.
Retirement
Retirement examines the oldest ROB entry or a bounded number of oldest entries per cycle.
An entry can retire when:
- valid;
- completed;
- no unresolved exception before it;
- required architectural side effects are safe to commit.
For a register-writing instruction:
- update committed architectural mapping;
- release the previous physical register if safe;
- account the instruction as retired;
- remove ROB entry.
For a store:
- perform or enqueue the committed memory/device effect;
- handle architectural fault policy;
- retire entry.
For a branch: 1. commit architectural control history if represented; 2. train predictor according to policy; 3. retire.
Retirement width R limits the maximum architectural completion rate to at most R instructions per cycle even if execution completes faster.
In-order retirement and serializing behavior
Some operations require stronger ordering.
Examples may include:
- privileged state changes;
- interrupt-enable transitions;
- page-table root changes;
- certain I/O operations;
- instructions treated as serializing by the chosen architectural model.
A teaching backend can conservatively mark these operations as requiring the ROB to drain before execution or retirement. This sacrifices performance but simplifies correctness.
The exact x86 serialization semantics should be implemented from architectural specifications, not inferred from instruction names.
Flags renaming
x86 condition flags create dependencies similar to registers.
Options for a simulator include:
- treat RFLAGS as one renameable resource;
- rename groups of flags;
- maintain per-flag producer metadata;
- serialize conservatively around flag-producing/consuming operations.
Treating RFLAGS as one resource is simplest but introduces false dependencies because different instructions may affect different subsets.
A more precise model tracks masks:
flags_read_mask
flags_write_mask
flags_preserve_mask
Then rename/scheduling can distinguish independent flag subsets.
Correctness should precede optimization.
Partial register renaming
AL, AH, AX, EAX and RAX overlap. EAX writes also zero the upper half of RAX.
A naive physical mapping per textual name is incorrect.
A first implementation can normalize every access to a register family and conservatively require full-family dependencies. A more advanced design can maintain byte masks and merge semantics.
The decoded semantic layer should tell rename:
- which architectural family is read;
- which bytes/bits are required;
- which bytes/bits are written;
- whether upper bits are defined, preserved or zeroed.
Without this normalization, rename can create subtle wrong results.
Micro-operations
Complex x86 instructions often map poorly to a single simple scheduler entry. A timing model can translate one architectural instruction into one or more internal micro-operations.
The ROB must still preserve the architectural instruction boundary for:
- exception reporting;
- RIP;
- retirement counting;
- atomicity requirements;
- rollback.
A group may retire only when all required micro-ops have completed successfully.
For an initial ChrisCPU backend, keeping one scheduler operation per currently supported ChrisInsn can be simpler. Micro-op decomposition should be introduced only when an instruction's resource/timing model actually requires it.
Common Data Bus as a teaching abstraction
Classic Tomasulo descriptions use a Common Data Bus (CDB) that broadcasts completed tags and values to waiting stations.
Modern machines can use multiple result networks, but the abstraction is useful:
producer completes P37 = value
broadcast tag P37
waiting consumers whose source tag == P37 capture/mark ready
A simulator need not literally copy values into every waiting entry. It can set P37 ready in a physical-register file and let consumers read it when selected.
This separates the conceptual dataflow algorithm from a particular hardware wiring model.
Tomasulo's algorithm and modern renaming
Tomasulo's algorithm combines dynamic scheduling with register renaming through reservation stations/tags. Modern OoO processors often use explicit physical registers plus ROB and issue queues, but the underlying goals are related:
- wait on true dependencies by tag;
- remove false name dependencies;
- execute when operands become available;
- preserve architectural state precisely.
The documentation should distinguish historical algorithmic concepts from the exact implementation chosen for ChrisCPU if such a backend is built.
Dataflow view
After rename, the instruction window approximates a dynamic dependency graph.
Each operation becomes a node. RAW dependencies become edges from producer physical registers to consumers.
An operation is ready when:
all required source edges have produced values
AND required execution resource is available
AND memory/order constraints allow issue
OoO scheduling is therefore a constrained dynamic graph traversal over a bounded window.
The hardware does not construct a general graph object, but this model is useful for reasoning and simulator design.
Head-of-line blocking at retirement
OoO execution can complete many younger instructions while the oldest ROB entry waits.
Example:
I1: long cache-miss load
I2..I40: independent ALU operations
I2..I40 may complete, filling physical registers and ROB entries, but cannot retire past I1. Eventually ROB/free-list pressure stops rename.
This shows why a large instruction window hides latency only up to a bound. Finite state eventually fills.
Window size and latency hiding
If the machine can inspect N in-flight operations, it can only find independent work within that window.
Larger N can expose more ILP and memory-level parallelism but increases:
- storage;
- wakeup/select complexity;
- branch recovery state;
- energy;
- simulator cost.
There is no universally optimal ROB size.
For documentation experiments, parameterizing the window is more useful than hard-coding a number that implies realism.
Interrupts and retirement boundaries
External interrupts require a precise architectural state.
A simple OoO model can accept an interrupt request asynchronously but deliver it only when:
- an architecturally permitted retirement boundary is reached;
- older instructions have retired;
- younger speculative entries are flushed;
- committed RAT/state is available.
This mirrors the core principle already used for exceptions: interrupt delivery operates on committed state, not arbitrary speculative execution state.
TLB and translation side effects
Loads/stores can trigger address translation and faults. A detailed timing model may also have speculative TLB fills and page-walk state.
For a first OoO ChrisCPU implementation, translation can remain functionally synchronous while the memory operation is scheduled. Faults should be captured in the ROB rather than immediately delivered.
If speculative TLB timing is added later, the model must decide which microarchitectural translation effects survive squashes. Architectural page faults still cannot be delivered from a wrong-path operation.
Atomic and locked operations
Atomic/locked operations constrain memory scheduling and visibility.
A conservative initial policy can:
- wait until the operation reaches ROB head;
- drain conflicting older memory effects;
- execute it non-speculatively;
- block younger memory operations until completion.
This is slower than real hardware but provides a correctness-first model.
Once memory ordering and cache coherence are explicitly modeled, atomic behavior can be refined.
Current ChrisCPU execution model
Current cpu_run is fundamentally sequential:
fetch instruction bytes
decode into ChrisInsn
execute against ChrisArchitectureState
update/redirect RIP
recognize pending IRQ
increment step/TSC
repeat
chris_execute invokes helpers that read and write architectural registers and memory directly. The current ChrisCpu has one ChrisArchitectureState and no speculative physical state.
This makes the functional interpreter a good correctness oracle but a poor substrate for naive OoO execution: the very property that makes it simple—immediate architectural mutation—must be isolated before speculative scheduling can be correct.
Refactoring boundary for a future OoO backend
A timing backend should separate three layers:
1. Decode/semantic description
Produce a side-effect-free description:
- sources;
- destinations;
- flag masks;
- memory intent;
- control-flow class;
- operation parameters;
- privilege/serialization properties.
2. Execute/evaluate
Given explicit input values and a memory/translation interface, produce:
- result values;
- destination values;
- flags;
- effective addresses;
- branch outcome;
- fault descriptors;
- proposed side effects.
Do not commit architectural state here.
3. Retirement/commit
At ROB head:
- publish architectural mapping/state;
- release buffered stores/I/O;
- deliver deferred exceptions;
- update committed control state;
- free old physical resources.
This decomposition lets the current interpreter continue using immediate commit while a timing backend uses the same semantic core through deferred results.
Proposed minimal simulator structures
A teaching implementation could begin with:
RobEntry rob[64]
IssueEntry iq[32]
PhysReg phys[96]
int rat[ARCH_REG_COUNT]
int committed_rat[ARCH_REG_COUNT]
FreeList free_regs
LoadQueue lq[24]
StoreQueue sq[24]
These counts are examples, not claims about hardware or current code.
Each structure should be parameterized where practical.
Cycle ordering in a simulator
A deterministic software simulator should define a phase order so same-cycle events are unambiguous.
One possible order:
- retire;
- resolve branch recovery/exception redirection;
- complete execution events;
- write physical results and wake consumers;
- issue ready operations;
- dispatch/rename decoded operations;
- decode/fetch;
- advance cycle counters.
However, if a completion in phase 3 is allowed to wake and issue a dependent operation in phase 5 of the same simulated cycle, that is a specific timing assumption. A stricter edge model may defer readiness until the next cycle.
The model must document this explicitly. Otherwise "cycle-accurate" traces are not reproducible.
Recovery resource accounting
On a branch squash, the machine must reclaim resources allocated by younger instructions:
- ROB slots;
- issue entries;
- load/store queue entries;
- physical registers;
- branch checkpoints;
- speculative predictor history.
A robust simulator can identify younger entries by monotonic sequence number.
For every reclaimed physical register:
- ensure it belongs only to a squashed destination;
- ensure it is not referenced by committed RAT;
- ensure surviving instructions do not reference it.
These assertions catch recovery bugs early.
Invariants
A future implementation should continuously check:
- Every speculative architectural mapping points to an allocated physical register.
- Every committed mapping points to an allocated, ready physical register.
- A physical register is either free or owned/referenced, never both.
- ROB age order is unambiguous.
- No instruction retires before every older instruction.
- No instruction with an exception retires normal side effects.
- No younger instruction survives a flush that should remove it.
- Every scheduler source tag references a valid producer or committed value.
- A store becomes externally visible only under the defined commit rule.
- Old physical mappings are freed exactly once.
- Branch recovery restores a rename state equivalent to the surviving program prefix.
- Architectural retirement matches the functional interpreter.
Assertions are particularly valuable in an emulator because internal structures are directly inspectable.
Differential validation
The current functional ChrisCPU should remain a reference backend.
A differential harness can run both models from identical initial state.
After each OoO retirement group:
- advance the functional interpreter by the same number of architectural instructions;
- compare GPRs, RIP, RFLAGS and relevant privileged state;
- compare architecturally visible memory effects;
- compare exception/interrupt boundary when applicable.
The timing backend may have: - different cycle count; - speculative instructions not present in functional trace; - physical-register mappings; - predictor state.
Those are not compared as architectural outputs.
Directed validation cases
Independent scheduling
long_load rax
add rcx, rdx
xor r8, r9
Independent ALU operations should complete while load waits.
RAW dependency
add rax, rbx
sub rcx, rax
Consumer cannot execute until producer physical register is ready.
WAW removal
mov rax, 1
mov rax, 2
Different physical destinations; final committed RAX must be 2.
WAR removal
add rbx, rax
mov rax, 9
First operation reads old RAX physical mapping; second writes a new mapping.
Precise fault
older valid ops
faulting load
younger completed ops
Only older operations retire; younger results are discarded; fault is delivered at the correct RIP.
Branch recovery
Create several renamed destinations after a mispredicted branch. Recovery must restore RAT and free-list state exactly.
Store suppression
A wrong-path store/MMIO operation must never mutate guest-visible memory/device state.
ROB pressure
Use an unresolved oldest operation until ROB fills. Rename must stall without corrupting queue state.
Performance metrics
Useful counters include:
- cycles;
- instructions decoded;
- instructions renamed;
- instructions issued;
- instructions completed;
- instructions retired;
- average ROB occupancy;
- maximum ROB occupancy;
- issue queue occupancy;
- rename stalls by reason;
- ROB-full stalls;
- free-register stalls;
- load/store queue stalls;
- branch flushes;
- replay count;
- execution-unit utilization.
Derived metrics include IPC:
IPC = retired_instructions / cycles
and average retirement width.
These metrics describe the configured simulator model, not a physical x86 processor unless calibrated against one.
Complexity in a software simulator
Representative costs for straightforward structures:
- RAT lookup: O(1);
- physical-register readiness lookup: O(1);
- ROB allocate/retire: O(1) with circular indices;
- free-list stack allocate/free: O(1);
- naive ready-instruction selection: O(Q);
- naive wakeup after one result: O(Q*S);
- conservative older-store scan for a load: O(SQ);
- branch squash scanning window: O(N).
More elaborate indexing can reduce simulator work at the cost of implementation complexity.
For an educational ChrisCPU backend, transparent invariants are more important than prematurely optimizing queue algorithms.
Current limitations
The current source revision contains no:
- physical register file;
- rename map;
- free list for register renaming;
- reorder buffer;
- issue queue/reservation stations;
- wakeup/select network;
- load/store queue;
- speculative retirement engine;
- rename checkpoint system;
- OoO replay mechanism.
Current instruction execution mutates architectural state directly.
Roadmap boundary
A safe development order is:
- refactor decoded instructions into explicit read/write semantic metadata;
- create side-effect-free execution results;
- implement committed and speculative register maps;
- add physical register allocation;
- add an in-order ROB with deferred commit;
- prove precise exceptions before out-of-order issue;
- add issue queue and readiness tracking;
- permit independent ALU operations to execute out of order;
- integrate branch checkpoints and recovery;
- add conservative LSQ behavior;
- add store-to-load forwarding;
- only then consider speculative load disambiguation, replay and wider issue.
The transition from functional interpreter to OoO timing model should be evolutionary, with differential testing after every stage.
Revision record
This chapter was reconciled against ChrisOS main revision e05a17fd76333114a3fb5c2452f38ca747d4ac56. Statements about current behavior are limited to the declared source files. ROB, physical-register, rename, scheduler and LSQ mechanisms described here are architectural theory and proposed design boundaries, not claims that the present ChrisCPU implements out-of-order execution.