
Spinlocks, interrupt exclusion and lock ordering
About this chapter Concurrency and ownership
In this chapter
- Spinlocks, interrupt exclusion and lock ordering
- Scope
- Atomic compare-and-swap
- Basic acquire loop
- PAUSE
- Unlock
- Initialization
- Spinlocks are not recursive
- Interrupt reentrancy
- irq_save
- irq_restore
- The PMM locking pattern
- Controlled PMM recursion
- Heap lock ordering
- Lock-order graph
- Heap interrupt-safety boundary
- AC97 example
- Job queue
- Atomic counters outside the queue lock
- MM's custom acquire loop
- TLB shootdown serialization
- KMutex is currently a spinlock wrapper
- Condition-variable model
- Serial and kernel log locks
- Fairness
- Starvation and priority
- Memory ownership is separate from locking
- Critical-section design
- Lock initialization order
- Error paths and locks
- Performance model
- False sharing
- Validation evidence
- Current limitations
- Recommended discipline for current ChrisOS
- Revision boundary
Scope
Once more than one CPU can execute kernel code, shared mutable state needs explicit synchronization.
ChrisOS uses a small spinlock primitive built around an atomic compare-and-swap operation.
The primitive is intentionally minimal:
There is no owner field, recursion count, wait queue, fairness policy or sleeping path.
A waiter repeatedly tries to change locked from 0 to 1 and executes the x86 PAUSE hint while the lock remains unavailable.
This simplicity makes the primitive easy to reason about locally, but correct kernel synchronization depends on much more than the lock implementation itself.
The caller must also reason about:
- which shared state the lock protects;
- interrupt reentrancy on the same CPU;
- lock ordering across subsystems;
- whether work inside the critical section can block or call another allocator;
- object lifetime after the lock is released;
- progress requirements such as TLB acknowledgement.
Atomic compare-and-swap
cas_u32 is implemented with:
It returns true only when the previous value equals expected and the atomic operation replaces it with desired.
For the lock acquire path:
Only one contending CPU can successfully perform that transition for a given unlocked state.
All others observe failure and retry.
The source expresses atomicity through GCC's legacy __sync builtins rather than through C11 atomic types.
That is an implementation dependency of the current kernel toolchain.
Basic acquire loop
spin_lock is:
This is a busy-wait lock.
A waiting CPU continues executing instructions and consuming a hardware thread.
Spinlocks are therefore appropriate when:
- the protected critical section is short;
- the lock holder is expected to make progress quickly;
- sleeping is unavailable or more expensive than waiting;
- the context cannot sleep, such as low-level kernel paths.
They are inappropriate for long unbounded waits.
PAUSE
The loop executes the x86 PAUSE instruction after a failed acquire.
PAUSE does not release the CPU or place the thread on a scheduler wait queue.
It is a processor hint intended for spin-wait loops.
The current spinlock remains fundamentally polling.
The kernel's job workers also use PAUSE in cooperative waiting paths, but those are not automatically spinlocks.
Unlock
spin_unlock calls:
which releases the lock state back to zero using the compiler's synchronization builtin.
Correctness requires the protected writes to become visible according to the acquire/release contract of the chosen compiler/architecture model.
The chapter on atomics and memory ordering covers the broader theory.
Here the important source-level rule is that protected state must be accessed consistently under the same synchronization discipline.
Initialization
spin_init simply writes:
The lock must not be concurrently used before initialization has been published.
Most current locks are static objects initialized during subsystem boot before workers begin concurrent use.
Examples include heap_lock, pmm_lock, g_q_lock and g_serial_lock.
Spinlocks are not recursive
The generic Spinlock contains no owner CPU and no recursion depth.
If a CPU that already holds a Spinlock calls spin_lock on the same object again, its CAS can never succeed until the outer acquisition releases it.
But the outer code cannot run while the nested path spins.
The result is self-deadlock.
The PMM's recursion behavior is therefore not a feature of Spinlock.
PMM builds its own per-CPU recursion layer around one non-recursive pmm_lock.
Interrupt reentrancy
SMP is not the only source of concurrency.
An interrupt can preempt code on the same CPU.
Suppose ordinary code does:
and the interrupt handler also attempts:
The handler spins forever because the interrupted code cannot resume to unlock L until the handler returns.
This is a same-CPU deadlock.
A plain spin_lock does not disable interrupts and therefore does not prevent this failure.
irq_save
spin.h provides a separate helper:
On the freestanding kernel it:
- reads RFLAGS;
- executes CLI;
- returns the saved flags.
This preserves whether IF was previously set.
The operation has a compiler memory clobber so ordinary memory operations are not freely moved across the inline assembly by the compiler.
In CHRIS_HOST_METAL tests the privileged CLI/STI behavior is compiled as a no-op.
irq_restore
irq_restore examines the saved flags.
If IF had been set, it executes STI.
If IF was already clear before irq_save, it leaves interrupts disabled.
This is important for nesting with code that entered an already interrupt-disabled region.
A naive unconditional STI on exit would violate the caller's previous interrupt state.
The PMM locking pattern
The PMM is the clearest current example of combining local interrupt exclusion with an inter-CPU lock.
At outer entry, pmm_enter:
- derives current CPU index;
- saves IF and disables local interrupts;
- acquires pmm_lock;
- records recursion depth 1.
At outer exit, pmm_leave:
- clears recursion depth;
- releases pmm_lock;
- restores the original interrupt state.
This protects the bitmap from:
- another CPU entering PMM simultaneously;
- an IRQ on the same CPU re-entering PMM while that CPU owns the lock.
The two problems need two mechanisms.
Controlled PMM recursion
PMM allows a specific form of same-CPU nested entry.
If pmm_depth[cpu] is already positive, pmm_enter increments the depth and returns without reacquiring pmm_lock.
This is needed because pmm_foreach_free_run invokes a callback while holding the PMM lock, and heap initialization can call pmm_claim_at from that callback.
The outer entry has already disabled interrupts, so an IRQ cannot impersonate legitimate recursion on the same CPU.
This design demonstrates a general principle:
recursion policy belongs to the subsystem contract, not to the generic spinlock primitive.
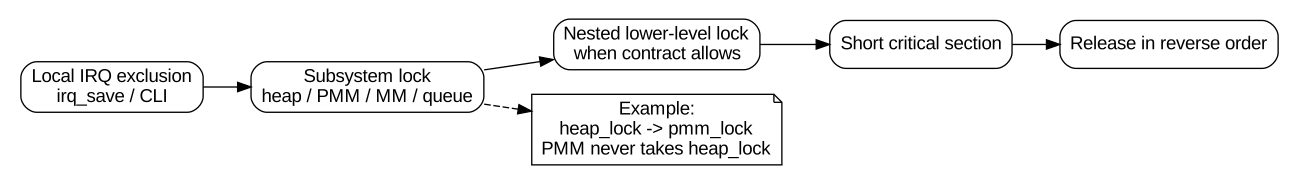
Heap lock ordering
The heap uses a plain global heap_lock.
kmalloc may hold heap_lock and then call PMM during heap growth.
Therefore the current order is:
The PMM source explicitly avoids allocating from the heap.
That absence of the reverse edge is essential.
If both directions existed, two CPUs could deadlock:
Lock ordering is therefore a graph property across subsystems, not a property visible in spin.c alone.
Lock-order graph
A useful model is to treat each lock as a graph node.
If code is allowed to acquire B while holding A, create edge:
A consistent global order produces an acyclic graph.
A cycle:
means there is a possible circular-wait deadlock if separate CPUs acquire the locks at different points in the cycle.
The current ChrisOS documentation should preserve explicit order relationships as the kernel gains more subsystems.
Heap interrupt-safety boundary
heap.c uses heap_lock but does not wrap normal kmalloc/kfree in irq_save/irq_restore.
Therefore heap_lock by itself is not safe against arbitrary same-CPU heap reentrancy from interrupt context.
The current contract should be treated as:
- kmalloc/kfree are SMP-serialized;
- callers must not assume they are automatically IRQ-reentrant;
- interrupt paths that can race with an interrupted heap holder need a stronger design before calling the heap.
This is a constraint, not proof that every current IRQ path violates it.
AC97 example
The audio subsystem demonstrates a lock explicitly paired with interrupt exclusion.
A producer path saves local interrupt state before taking g_ac97_lock.
This matters because the same device state can also be affected by its IRQ handler.
The pattern is:
flags = irq_save()
spin_lock(device_lock)
modify shared device/ring state
spin_unlock(device_lock)
irq_restore(flags)
The exact requirements vary per subsystem.
Not every spinlock should automatically disable interrupts, because some protected state is never accessed from interrupt context.
Job queue
The kernel job queue uses g_q_lock to protect:
- head;
- tail;
- count;
- ring entries during enqueue/dequeue.
job_submit acquires the lock, inserts one entry, updates queue indices/count, increments g_inflight atomically and releases.
job_worker_once acquires the lock only long enough to remove an entry.
The callback itself executes after the queue lock is released.
That is an important design rule.
Running arbitrary job callbacks while holding g_q_lock would make the critical section unbounded and could create lock-order cycles with whatever subsystem the callback enters.
Atomic counters outside the queue lock
g_completed and g_inflight are updated through atomic_add_u32.
This illustrates another synchronization choice: a variable does not always require the main structure lock if its operation can be represented by an independent atomic update.
However, atomics do not automatically make a compound invariant correct.
The queue indices and count still need the lock because they must change together with ring contents.
MM's custom acquire loop
The MM subsystem owns mm_lock, but mm_enter does not call generic spin_lock directly.
Instead it performs:
The reason is liveness.
A CPU waiting for mm_lock can simultaneously be required to acknowledge a TLB generation.
If it spun inside a generic loop without polling, another CPU could wait indefinitely for an acknowledgement from a peer stuck waiting for MM.
This is an example where synchronization needs a progress hook beyond mutual exclusion.
Generic locking primitives should not hide protocol-specific liveness requirements.
TLB shootdown serialization
The TLB publisher uses another CAS-based flag, mm_tlb_busy, rather than a Spinlock object.
Its wait loop also calls mm_tlb_poll.
Only one global shootdown generation/range can be published at a time, but waiters remain able to participate in another CPU's shootdown.
Again, the synchronization mechanism is adapted to the protocol's progress requirements.
KMutex is currently a spinlock wrapper
kthread.h defines:
kmutex_lock and kmutex_unlock simply call spin_lock and spin_unlock.
Therefore KMutex is not currently a sleeping mutex.
A contending kthread busy-waits on the underlying CPU.
The name expresses a higher-level synchronization interface, but the implementation remains spin-based.
This matters when estimating blocking cost.
Condition-variable model
KCond stores a volatile sequence counter.
kcond_wait:
- reads the sequence;
- unlocks the KMutex;
- waits until the sequence changes;
- on a uniprocessor, executes job_worker_once to preserve progress;
- with multiple CPUs, uses PAUSE;
- reacquires the mutex.
kcond_signal increments seq.
This is a lightweight cooperative condition mechanism, not a scheduler-backed sleep queue.
The sequence increment is currently a plain volatile increment rather than atomic_add_u32.
If multiple CPUs signal the same KCond concurrently without another protecting discipline, updates can race.
The intended synchronization context must therefore include the condition's external protocol.
Serial and kernel log locks
serial.c uses g_serial_lock around each COM1 character output.
klog.c uses g_lock around ring-buffer mutation/copy.
These locks serialize output/data across CPUs.
Neither primitive automatically disables interrupts.
Diagnostic code can be called from exceptional or IRQ-related paths, so reentrancy deserves particular care: a CPU interrupted while holding a diagnostic lock cannot safely reacquire the same non-recursive lock from the handler.
This is a general low-level logging hazard and a reason panic/IRQ diagnostics should keep locking dependencies minimal.
Fairness
The generic spinlock has no ticket number or queue.
Every waiter repeatedly competes for the same unlocked transition.
There is no FIFO guarantee.
A CPU can theoretically lose repeatedly to other contenders.
The implementation therefore provides mutual exclusion, not fairness.
For short critical sections this may be acceptable at the current project scale.
A heavily contended future kernel may need ticket locks, MCS locks or another queued design.
Starvation and priority
There is no priority-aware handoff.
ChrisOS also does not currently have a general preemptive priority scheduler for these lock users.
Still, the conceptual risk remains: a busy-wait lock assumes the holder will run and release promptly.
If scheduling evolves, priority inversion and preemption while holding spinlocks will need explicit treatment.
Memory ownership is separate from locking
A lock can prove that two CPUs do not mutate an object simultaneously.
It does not prove that the object remains alive after the lock is released.
For example:
- CPU A removes an object from a shared table under lock;
- CPU A releases the lock and frees the object;
- CPU B may still hold a reference acquired before removal.
The correct solution may require reference counting, epoch reclamation, TLB shootdown, hardware quiescence or another lifetime protocol.
The TLB quarantine subsystem is a concrete ChrisOS example where ordinary locks are insufficient.
Critical-section design
A good spinlock critical section should minimize:
- loops over large datasets;
- I/O waits;
- serial output;
- callbacks;
- allocation through unknown lock chains;
- hardware operations with unbounded latency.
Current code often releases locks before executing arbitrary callbacks or freeing through another subsystem.
For example, kthread_join detaches its stack under g_slot_lock, releases the slot lock, then calls kfree.
This reduces lock nesting.
Lock initialization order
Static zero-initialization may make a lock appear unlocked, but the code still calls spin_init as an explicit subsystem contract.
This matters because initialization ordering communicates when the protected object becomes valid.
Concurrent workers should not observe partially initialized protected state merely because the lock word happened to be zero.
Publication of subsystem readiness remains separate from lock initialization.
Error paths and locks
Every return or panic path inside a locked region must be reviewed for unlock symmetry.
The heap provides examples where invalid kfree conditions release heap_lock before calling panic in cases discovered after acquisition.
A missed release can permanently wedge future users even if the original operation simply intended to report an error.
This is one reason narrow critical sections are easier to verify.
Performance model
Uncontended acquisition is approximately one atomic CAS operation plus normal critical-section work.
Under contention, each waiter repeatedly performs failed atomic operations separated by PAUSE.
Heavy CAS traffic can increase cache-coherence traffic on the lock's cache line.
The current implementation has no test-and-test-and-set optimization that first performs passive reads before attempting a write CAS.
It also has no backoff.
So contention cost can rise rapidly as CPU count increases.
False sharing
Spinlock is one 32-bit field.
The type does not align each lock to a cache line.
If a lock shares a cache line with unrelated frequently modified data, coherence traffic can couple those objects.
Likewise, multiple Spinlock objects placed close together can false-share.
The current implementation does not provide a cacheline-padded lock type.
At the project's current CPU scale this is a reasonable simplification, but it is a known scalability dimension.
Validation evidence
Current evidence is distributed across subsystem tests rather than one dedicated spinlock unit test.
Examples include:
- tools/test_pmm_heap_smp: four host threads concurrently exercise PMM and heap locking;
- smp_job_selftest: kernel workers contend on the global job queue;
- tools/test_job_saturate: validates full/drain/reuse queue behavior;
- tools/test_kthread_smp: exercises kthread operations under simulated SMP;
- runtime TLB tests depend on CAS-based serialization and progress-aware loops.
These validate real users of the primitive.
A dedicated future stress test could repeatedly increment protected counters across many host threads and verify interrupt-state nesting separately.
Current limitations
The generic spinlock currently has:
- no owner tracking;
- no recursive acquisition;
- no trylock API;
- no timeout;
- no fairness;
- no queueing;
- no backoff;
- no sleeping;
- no lockdep graph checking;
- no cacheline padding;
- no built-in irqsave variant;
- no debug metadata recording acquisition site.
These omissions keep the primitive small but move more responsibility to subsystem design.
Recommended discipline for current ChrisOS
For each shared object, documentation and code review should answer:
- Which lock protects it?
- Can interrupt context access it?
- If yes, where is local IF disabled?
- Can the critical section call another subsystem?
- What lock order does that create?
- Can the holder wait for work that requires another CPU to acquire this lock?
- Is the protected object's lifetime guaranteed after unlock?
- Are error paths symmetrical?
- Is contention expected to remain short?
This checklist captures more of real synchronization correctness than simply asking whether a spinlock exists.
Revision boundary
This chapter was reconciled against ChrisOS main revision e05a17fd76333114a3fb5c2452f38ca747d4ac56.
The current source-backed model is:
atomic CAS -> generic busy-wait mutual exclusion
PAUSE      -> spin-loop hint
irq_save   -> optional same-CPU interrupt exclusion
lock order -> subsystem-level deadlock prevention
custom CAS loops -> protocol-specific liveness when generic spin_lock is insufficient
lifetime protocol -> separate problem from mutual exclusion
Future preemption, lockdep, queued locks, per-CPU allocators or scheduler-backed mutexes will require this model to be extended.