
Block storage stack
About this chapter Block transport and media
In this chapter
- Block storage stack
- Scope
- The BlockDevice contract
- Error model
- Read and write guards
- Flush semantics
- Fixed 512-byte sector model
- Capacity representation
- Device registry
- Device flags
- Discovery sequence
- Root selection phase 1: raw ChrisFS
- Root selection phase 2: GPT partition
- Partition wrapper ownership
- Root selection phase 3: format an empty disk
- Default disk geometry
- ATA path
- ATA DMA addressability
- AHCI path
- NVMe path
- VirtIO Block path
- Synchronous interface over asynchronous hardware
- Timeouts are ownership events
- Range safety
- Read/write verification at boot
- Root persistence probe
- Layered failure diagnosis
- Concurrency model
- Security and integrity
- Performance trade-offs
- Validation boundary
- Current limitations
- Source map
Scope
Persistent storage is exposed to ChrisOS through a sector-oriented block abstraction rather than through filesystem-specific device code. The filesystem, installer and partition layer operate on a common BlockDevice contract, while ATA, AHCI, NVMe, VirtIO Block and USB storage implement the transport-specific mechanisms underneath.
The current design has three major responsibilities:
- normalize device I/O into 512-byte logical sectors;
- register discovered devices and select the root storage object;
- preserve controller-specific DMA, timeout and completion rules below the common interface.
This architecture is intentionally narrower than a general Linux-style block subsystem. It has no request scheduler, merge queue, elevator algorithm, asynchronous bio layer or page cache in the block layer itself.
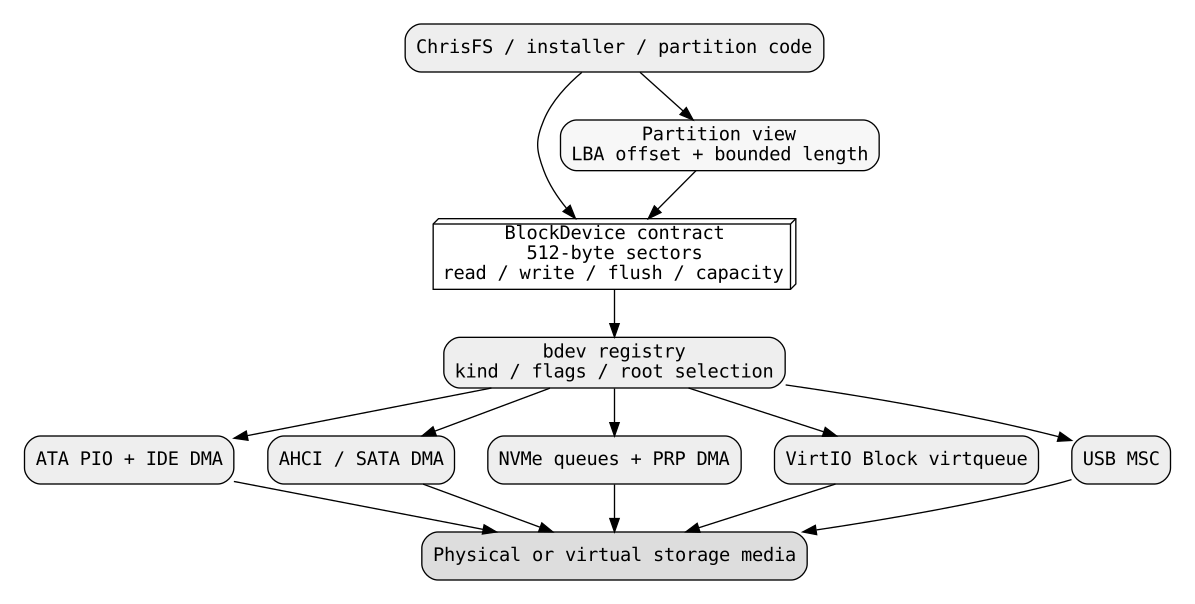
The BlockDevice contract
BlockDevice contains:
- a driver-specific context pointer;
- sector_size;
- sector_count;
- read callback;
- write callback;
- optional flush callback;
- writable flag.
The callbacks operate in logical sectors:
The current generic contract requires sector_size to equal 512 bytes.
bd_range_ok rejects:
- null device;
- zero-sector request;
- any device whose sector size is not 512;
- an LBA at or beyond sector_count;
- a count that would extend beyond the device.
The range test uses:
rather than adding count to lba, which avoids unsigned wraparound in the bounds check.
Error model
The generic block layer defines a compact set of negative status values:
This is one of the most important normalization points in the storage stack.
Controllers report failures in different ways:
- ATA status bits;
- AHCI task-file status and command completion;
- NVMe completion status;
- VirtIO status bytes and used-ring progress.
Drivers translate those protocol-specific results into the common BD_* domain before the filesystem sees them.
That separation prevents ChrisFS from depending on transport details.
Read and write guards
bd_read rejects null destination, missing device or missing read function as BD_EINVAL.
It then applies bd_range_ok.
bd_write additionally checks writable.
A read-only device therefore fails with BD_EROFS before the driver callback executes.
The generic wrappers do not split requests or allocate bounce buffers. Chunking belongs to individual drivers because maximum transfer length and DMA layout are transport-specific.
Flush semantics
bd_flush calls the device flush callback when one exists.
If the device has no flush callback, the current implementation returns BD_OK.
That means “flush function absent” is treated as “no explicit operation required,” not as an unsupported-command error.
This is a practical abstraction choice, but callers should not interpret it as proof that every controller/media combination has durable write-back semantics identical to a successful hardware cache flush.
Durability guarantees ultimately depend on the driver and device.
Fixed 512-byte sector model
storage_limits.h defines:
The entire current stack is designed around that logical block size.
This affects:
- BlockDevice validation;
- ChrisFS geometry;
- GPT reads;
- ATA transfers;
- AHCI transfer sizes;
- NVMe namespace acceptance;
- VirtIO block copying.
NVMe probing explicitly rejects a namespace whose selected LBA format is not 512 bytes by checking the LBA data size field for 2^9 bytes.
The abstraction therefore does not currently normalize native 4 KiB logical sectors to 512-byte sectors.
A 4Kn device or namespace is outside the accepted current contract.
Capacity representation
BlockDevice sector_count is uint32_t.
At 512 bytes per sector, the largest directly representable capacity is approximately:
Several drivers explicitly reject capacity values whose upper 32-bit portion is nonzero.
For example, the NVMe path rejects a namespace whose NSZE upper dword is nonzero.
VirtIO Block similarly rejects capacity when the high 32 bits are nonzero.
This is a deliberate current limitation, not an inherent limit of NVMe or VirtIO.
Device registry
bdev.c maintains a static registry.
The maximum number of slots is:
Each registry entry stores:
- a copied BlockDevice;
- a short name;
- a kind;
- flags;
- an internal ID.
The public kinds include ATA, AHCI, NVMe, VirtIO, USB, RAM and partition.
bd_add_kind copies the supplied BlockDevice structure into the registry.
The registry therefore stores callback/context references, not a deep copy of arbitrary driver state.
The context pointer must continue to refer to valid driver-owned state.
Device flags
The registry has flags for:
- boot;
- root;
- test.
claim_root marks the selected registry entry with BOOT and ROOT.
bd_installable excludes devices that are:
- not writable;
- already BOOT, ROOT or TEST;
- RAM-backed;
- partition views.
This keeps the installer from accidentally choosing the currently mounted root, a synthetic RAM disk, or a partition wrapper as a raw target.
Discovery sequence
storage_init attempts several controller families.
The current order begins with legacy ATA configuration and identify, then probes:
- AHCI;
- NVMe;
- VirtIO Block;
- USB mass storage;
- xHCI HID probing as part of broader hardware discovery.
Successfully discovered block devices register themselves through bd_add_kind.
The presence of multiple drivers does not mean one “wins” simply by probe order.
Root selection is a separate policy implemented by discover_root.
Root selection phase 1: raw ChrisFS
discover_root first scans registered non-RAM devices and checks whether ChrisFS is directly present at the device's expected superblock location.
disk_has_cfs reads the superblock sector and attempts cfs_super_decode.
The first matching device becomes root.
This supports disks where ChrisFS occupies the raw block device without a partition wrapper.
Root selection phase 2: GPT partition
If no direct filesystem is found, discover_root scans non-RAM devices for a GPT partition matching the ChrisFS type GUID or an accepted legacy Linux filesystem-data GUID.
gpt_find_cfs:
- reads LBA 1;
- checks the EFI PART signature;
- verifies the GPT header CRC over the supported 92-byte header form;
- reads the partition-entry-array LBA and geometry;
- scans at most 128 entries;
- finds an accepted partition type;
- validates start and end LBAs;
- returns a 32-bit start/count range.
part_open then creates a bounded BlockDevice view over that range.
The partition wrapper translates:
and caps its visible sector_count to the partition length.
ChrisFS can then mount the partition as if it were an independent device.
Partition wrapper ownership
PartView does not allocate a new physical device.
It keeps a pointer to the parent BlockDevice and exposes another BlockDevice whose callbacks forward to the parent with an LBA offset.
The writable state is inherited.
This is a useful example of abstraction composition:
The same read/write API works at each boundary.
Root selection phase 3: format an empty disk
If no existing ChrisFS root is found, discover_root looks for a writable non-RAM device large enough for the configured default disk geometry.
It reads sector zero and requires the first eight bytes to be zero.
Only then can storage_format_if_empty format the device.
This is a safety policy.
A disk containing unknown nonzero data is not automatically reformatted.
If the ChrisFS superblock is invalid but the prefix is not zero, storage_format_if_empty returns CFS_EFORMAT, and storage_init later treats unknown disk content as fatal rather than overwriting it.
Default disk geometry
storage_limits.h defines:
which corresponds to 512 MiB.
That value is used as a minimum in the automatic empty-disk root path.
It should not be confused with a universal maximum disk size.
ChrisFS geometry can be calculated for other supported capacities, while several device drivers currently accept up to the 32-bit sector-count ceiling.
ATA path
The ATA driver supports both PIO and an IDE bus-master DMA path.
For DMA, the current implementation keeps device-local persistent buffers rather than allocating a new PRDT for every transfer.
The DMA data area supports up to 16 sectors in one DMA chunk.
If DMA fails, ata_bd_read and ata_bd_write:
- abort/stop the DMA engine;
- soft-reset the ATA control path;
- fall back to PIO;
- continue in chunks up to 255 sectors for the PIO command count field.
This creates a resilience path in which DMA is an optimization, not the only I/O mechanism.
ATA status polling distinguishes:
- device missing;
- timeout;
- generic I/O error.
ATA DMA addressability
The current IDE DMA path requires both the data buffer and PRDT to fit below 4 GiB.
ata_dma_acquire rejects physical addresses above 0xffffffff.
That reflects 32-bit bus-master addressability.
The driver obtains contiguous PMM memory and accesses it through HHDM.
This is a concrete example of why CPU-addressable RAM and device-addressable RAM are not identical sets.
AHCI path
AHCI uses MMIO registers and DMA command structures.
The current driver:
- discovers PCI class 0x0106;
- maps BAR 5;
- enables the AHCI controller;
- examines implemented ports;
- requires a device-present link state;
- allocates DMA pages for controller structures and data;
- starts a port;
- issues IDENTIFY;
- determines sector capacity;
- registers a 512-byte writable BlockDevice.
I/O is issued in chunks of up to eight sectors.
The driver builds host-to-device FIS and PRDT-related structures in DMA-visible memory.
Completion is currently polled through command-issue and task-file state rather than exposed to the generic block layer as asynchronous completion.
NVMe path
NVMe uses PCIe MMIO plus submission and completion queues in DMA memory.
The current implementation allocates:
- admin submission queue;
- admin completion queue;
- I/O submission queue;
- I/O completion queue;
- data buffer.
The queues are intentionally tiny in the current driver: the head/tail arithmetic uses two entries.
The driver creates the I/O queues through admin commands, identifies namespace 1, validates 512-byte LBAs, records the namespace size and registers a BlockDevice.
Read/write operations are chunked to at most eight sectors.
The generic block interface hides the NVMe command identifier, phase bit, doorbell and completion-status details.
VirtIO Block path
VirtIO Block discovers compatible PCI devices, parses VirtIO PCI capabilities, maps common/notify/device configuration regions and creates a small virtqueue.
It allocates DMA areas for:
- queue structures;
- command/status storage;
- transfer data.
Each request constructs a descriptor chain for:
- request header;
- data;
- status byte.
The driver kicks the queue and waits for used-ring progress plus status success.
The current code uses finite polling budgets and returns BD_ETIMEOUT when completion does not arrive.
Read/write requests are chunked to at most eight sectors.
Synchronous interface over asynchronous hardware
AHCI, NVMe and VirtIO are naturally capable of queued/asynchronous operation.
The current BlockDevice API is synchronous.
A caller invokes read or write and does not regain control until the driver returns success or failure.
Drivers therefore hide queueing hardware behind bounded polling loops.
This simplifies filesystem code, but it limits concurrency and throughput.
A future asynchronous block layer would need explicit request objects, completion ownership and cancellation/reset semantics.
Timeouts are ownership events
A timeout is not merely a number returned to the filesystem.
For DMA-capable hardware, timeout raises a deeper question:
Can the controller still access the memory buffer?
The ATA DMA path explicitly aborts the engine and resets the port before falling back.
Other drivers use finite waits, but a fully hardened design must know whether a timed-out command can still complete later.
Reusing a DMA buffer while hardware may still write into it causes memory corruption.
Timeout recovery therefore belongs to the ownership model.
Range safety
The common BlockDevice layer prevents requests beyond sector_count.
Partition views add another boundary by exposing a reduced sector_count and translating requests relative to start.
These two layers prevent a filesystem mounted on a partition from intentionally issuing an LBA outside the visible partition through the normal bd_read/bd_write wrappers.
However, PartView callbacks call the parent driver callbacks directly rather than the parent's bd_read/bd_write wrappers.
Safety relies on part_open having validated and capped start/count and on the child range checks being applied before the partition callback is invoked.
Read/write verification at boot
storage_init runs bdev_rw_tests after mounting root.
The test skips:
- the root device;
- read-only devices;
- RAM devices;
- devices smaller than two sectors.
For each remaining device it:
- reads the final sector;
- writes a deterministic test pattern;
- reads it back;
- compares bytes;
- restores the original sector.
This is destructive-but-restored validation on non-root writable devices.
Its purpose is to verify the complete read/write path, not only controller discovery.
A failure does not necessarily prove media corruption; it identifies that the current block path could not complete and verify the round trip.
Root persistence probe
After ChrisFS mounts, storage_init calls hello_probe.
The function reads HELLO.TXT.
If missing, it writes the string persistent.
On a later boot, it expects to read the same content.
This is a simple end-to-end persistence signal spanning:
It is stronger than an in-memory unit test because it checks that data survives a reboot boundary when the storage backend persists.
Layered failure diagnosis
A storage failure can occur at multiple layers:
filesystem metadata
    -> partition translation
        -> BlockDevice range/permission contract
            -> transport driver
                -> DMA/MMIO/port I/O
                    -> controller
                        -> media or VM backend
The same symptom, such as “mount failed,” can originate from:
- invalid filesystem superblock;
- wrong partition LBA;
- sector-size mismatch;
- controller timeout;
- DMA addressability;
- device absent;
- read-only target;
- corrupted media.
Diagnosis should preserve those layers instead of collapsing all failures into “disk error.”
Concurrency model
The generic BlockDevice interface does not contain locks or request IDs.
Concurrency policy lives in each driver and in the calling architecture.
Several current drivers use global/static controller state and one reusable DMA buffer.
That strongly implies a single-owner synchronous model for each driver instance.
Calling the same controller concurrently from multiple CPUs without additional serialization could corrupt command state, DMA buffers or queue indices.
A mature block layer would make concurrency guarantees explicit.
Security and integrity
Block I/O sits below filesystem integrity.
If a driver writes the wrong LBA, filesystem checksums cannot prevent physical corruption of unrelated sectors.
Important integrity boundaries include:
- LBA range checks;
- partition offset validation;
- GPT header CRC validation;
- refusing to format unknown nonzero media;
- explicit writable checks;
- bounded controller waits;
- correct DMA buffer lifetime.
These are safety properties even in a single-user research kernel.
Performance trade-offs
The current stack favors simplicity and deterministic control flow over peak throughput.
Examples:
- synchronous BlockDevice calls;
- small transfer chunks;
- polling completion;
- small NVMe/VirtIO queues;
- persistent bounce buffers;
- no request merging;
- no block cache at this layer;
- no scheduler for reordering LBAs.
The architecture is sufficient to make several device families usable under one filesystem contract.
Scaling to high-throughput NVMe would require a substantially different request model.
Validation boundary
Current source provides evidence for:
- common range/error semantics;
- 512-byte sector enforcement;
- device registry and root policy;
- GPT partition lookup;
- ATA DMA with PIO fallback;
- AHCI discovery and synchronous DMA I/O;
- NVMe admin/I/O queue initialization;
- VirtIO descriptor-chain I/O;
- boot-time non-root read/write round trips;
- cross-boot ChrisFS persistence probe.
That does not establish universal hardware compatibility.
PCI topologies, controller revisions, firmware quirks, native 4 KiB sectors, very large disks, hotplug and error-recovery corner cases require separate evidence.
Current limitations
The current block subsystem has several explicit limits:
- eight registered device slots;
- 512-byte logical sectors only;
- uint32_t sector count, effectively about 2 TiB at 512 bytes;
- synchronous API;
- no generic asynchronous request/completion abstraction;
- no request scheduler or merge layer;
- limited per-driver queue depth;
- several drivers use one shared DMA data area;
- no hotplug lifecycle in the generic layer;
- no generic cancellation contract;
- flush is optional and may be a no-op at the abstraction layer;
- automatic root formatting only occurs on clearly empty media;
- physical-hardware compatibility is narrower than the protocols themselves allow.
These are implementation boundaries, not limitations of ATA, AHCI, NVMe or VirtIO as standards.
Source map
kernel/fs/block_device.h defines the normalized sector I/O contract and BD_* errors.
kernel/fs/bdev.c and bdev.h implement the static device registry, kinds, flags and installability policy.
kernel/fs/storage.c performs probe orchestration, root discovery, safe empty-disk formatting, mount, persistence probing and non-root read/write testing.
kernel/fs/part.c implements GPT lookup and partition BlockDevice views.
kernel/fs/ata_pio.c implements legacy ATA PIO plus IDE bus-master DMA fallback behavior.
kernel/fs/ahci.c implements the current SATA/AHCI MMIO and DMA path.
kernel/fs/nvme.c implements the current small-queue NVMe path.
kernel/fs/virtio_blk.c implements the current VirtIO Block PCI/virtqueue path.
The implementation claims in this chapter were reconciled against ChrisOS revision e05a17fd76333114a3fb5c2452f38ca747d4ac56.