
ChrisFS journaling and recovery
About this chapter ChrisFS structures and recovery
In this chapter
- ChrisFS journaling and recovery
- Scope
- Region geometry
- Journal magic
- Header layout
- Journal states
- In-memory journal object
- Header sequence
- Record layout
- Payload checksum
- Missing target-LBA validation during replay
- Beginning a transaction
- Logging a sector
- How cache writes enter the journal
- Why this is not a classical write-ahead transaction
- jnl_data and partial coverage
- Operation coverage
- mkdir coverage
- unlink coverage and record pressure
- Concrete unlink limit
- Consequence of journal exhaustion
- Commit sequence
- No durability barriers
- Crash windows around commit
- Mount-time replay
- BEGIN replay
- COMMIT replay
- Oversized record-count bug
- Undersized journal-region interaction
- fsck journal checks
- Format-time initialization
- Validation evidence
- Missing failure tests
- What the journal currently guarantees
- Current limitations
- Roadmap boundary
- Source map and revision note
Scope
ChrisFS contains a small redo-style journal intended to improve metadata recovery after interrupted filesystem operations.
The current implementation is not a general transaction manager and does not provide full ACID semantics.
Its main mechanisms are:
- one journal header sector;
- up to 30 logged sector images;
- explicit BEGIN, COMMIT and EMPTY states;
- per-record payload checksums;
- mount-time replay of committed records;
- discard of uncommitted BEGIN state;
- a superblock clean/dirty flag.
The journal is tightly integrated with the write-through sector cache. Any write that passes through cache_write while journaling is active and jnl_data == 0 is logged before the corresponding home-sector write.
This chapter documents the implementation at ChrisOS revision e05a17fd76333114a3fb5c2452f38ca747d4ac56.
Region geometry
The normal filesystem format reserves:
journal sectors.
The region contains:
sector 0     journal header

for record i:
sector 1 + 2*i     record metadata
sector 2 + 2*i     full 512-byte payload
With:
the maximum normal space consumed is:
leaving three spare sectors in the normal 64-sector journal region.
The v5 superblock validator currently accepts journal regions smaller than this; that decoder limitation is documented in the superblock chapter.
Journal magic
The journal magic is:
On little-endian storage the bytes are:
or:
A zero magic is also treated as an empty journal representation by replay.
Therefore two empty encodings can occur in practice:
- a CJNL header with state EMPTY;
- an all-zero header.
Formatting creates the first form. Dropping a BEGIN transaction during replay creates the second.
Header layout
The journal header occupies one 512-byte sector.
The active fields are:
| Offset | Size | Field |
|---|---|---|
| 0 | 4 | magic |
| 4 | 4 | sequence |
| 8 | 4 | state |
| 12 | 4 | record count |
| 16 | 4 | checksum |
Bytes 20..511 are zeroed when the header is generated.
The checksum is computed over:
and therefore protects:
- magic;
- sequence;
- state;
- nrec.
The checksum field itself and the remaining sector are not included.
Journal states
The defined states are:
Other nonzero state values cause replay to return:
when the header otherwise has valid magic/checksum.
In-memory journal object
Jnl stores:
At BEGIN:
fspoints to the mounted filesystem;seqis copied fromfs->super.generation;nrecbecomes zero.
rec_lba[] is filled as records are logged.
At the documented revision, that array is not consulted later for deduplication, validation or replay.
It therefore records bookkeeping information but does not change behavior.
Header sequence
jnl_begin uses:
COMMIT uses the same sequence.
Normal jnl_commit then writes EMPTY with:
However, replay does not compare or validate sequence values.
After COMMIT replay, the code clears the header buffer and writes an EMPTY header without restoring sequence, leaving it as zero.
Sequence is therefore persisted but is not currently an enforced transaction-order invariant.
Record layout
Each journal record uses two sectors.
Record metadata sector
Active fields:
| Offset | Size | Field |
|---|---|---|
| 0 | 4 | target home LBA |
| 4 | 4 | checksum of payload |
The rest of the metadata sector is zero.
Payload sector
The following sector contains the complete 512-byte image that should be written to the target LBA.
This is sector-image redo logging, not a byte-range log.
Payload checksum
jnl_log computes the checksum over all:
Replay verifies that checksum before applying the payload.
This detects payload corruption.
It does not protect the target LBA field in the metadata sector.
A bit flip or corruption that changes only:
can therefore redirect an otherwise valid payload without failing the payload checksum.
There is no independent checksum over the record metadata sector.
Missing target-LBA validation during replay
Replay reads the target LBA from the record and passes it directly to:
There is no explicit journal-layer check that the target is:
- inside the filesystem-declared volume;
- outside the journal itself;
- a valid metadata region;
- one of the sectors originally expected for that operation.
The underlying block-device layer may reject an out-of-device write, but an in-device corrupted LBA can target unrelated filesystem metadata or data.
For recovery hardening, the target address needs explicit validation and the record metadata itself needs integrity coverage.
Beginning a transaction
jnl_begin performs:
- initialize the in-memory
Jnl; - set
super.clean = 0; - encode the superblock;
- write the dirty superblock through
cache_write_raw; - write the journal header in BEGIN state.
Important detail:
is used for the dirty-superblock write.
Its return value is ignored.
If that write fails but the BEGIN header write succeeds, jnl_begin reports success while the on-disk clean flag may remain unchanged.
That weakens the clean/dirty protocol.
Logging a sector
When journal logging is enabled, jnl_log:
- rejects the request if
nrec >= 30; - calculates the next two-sector journal slot;
- writes record metadata with target LBA and payload checksum;
- writes the 512-byte payload;
- stores target LBA in
rec_lba[nrec]; - increments
nrec.
There is no deduplication.
Repeated writes to the same home sector consume repeated records.
How cache writes enter the journal
The normal sector-write path is:
If:
then:
is called before:
The resulting order in source is:
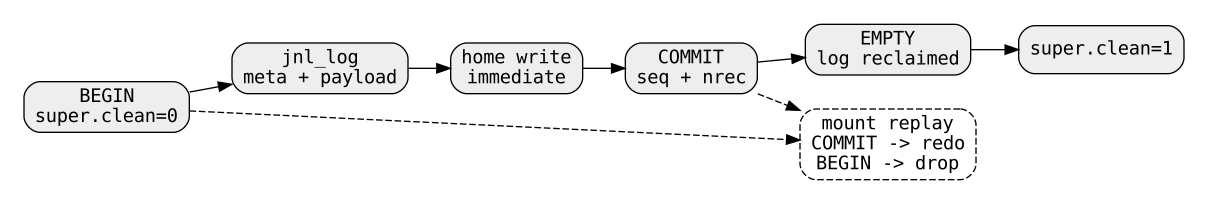
The home write occurs immediately.
The transaction does not wait until COMMIT before modifying home locations.
Why this is not a classical write-ahead transaction
A classical redo journal normally relies on a durability order resembling:
- persist log records;
- persist commit marker;
- apply home writes;
- later reclaim log.
ChrisFS instead applies each home write immediately after writing that record, before COMMIT.
Therefore, if a crash happens in BEGIN state, some home-sector changes can already be present.
Replay then treats BEGIN as uncommitted and simply clears the journal.
It does not restore the old home-sector contents.
So discarding BEGIN is not rollback.
jnl_data and partial coverage
ChrisFS uses jnl_data to suppress logging.
In cfs_write and cfs_write_at:
during data writes and block-tree/allocation activity.
Only near the final inode update does the code switch:
As a result, these operations can modify without journal records:
- file data blocks;
- bitmap sectors;
- indirect pointer blocks;
- double/triple-indirect metadata;
- allocation-related metadata written while data mode is active.
The final inode sector is normally logged.
The mechanism is therefore not “metadata journaling” in the strong sense; some filesystem metadata is deliberately excluded during file-write paths.
Operation coverage
The current source calls jnl_begin in exactly four public operation paths:
cfs_mkdir;cfs_unlink;cfs_write;cfs_write_at.
Other namespace or metadata operations do not begin journal transactions, including:
cfs_create;cfs_rmdir;cfs_rename;cfs_chmod.
cfs_truncate delegates to whole-file write behavior and therefore inherits that path's journal behavior when it reaches cfs_write.
Coverage is intentionally or historically uneven.
mkdir coverage
cfs_mkdir runs with:
for its metadata changes.
That means inode allocation, directory inode type update and parent dirent insertion can all generate records.
This is broader metadata coverage than the normal file-write path.
However, the same immediate-home-write ordering still applies.
unlink coverage and record pressure
cfs_unlink also keeps:
while:
- removing the parent dirent;
- freeing each file data block in the bitmap;
- freeing pointer-table blocks;
- clearing the inode.
Every bitmap update can therefore consume a journal record.
Because repeated writes to the same bitmap sector are not deduplicated, freeing many blocks can exhaust the 30-record journal even when all those updates target the same bitmap sector.
Concrete unlink limit
For a regular file in the single-indirect range, a typical unlink logs at least:
2 records    parent directory sector + parent inode
N records    one bitmap write for each data block
1 record     bitmap write freeing the indirect pointer block
1 record     final inode clear
Total:
With a 30-record maximum:
fits.
A 27-block file can reach record 31 when clearing the inode.
Twenty-seven 512-byte blocks correspond to a full size of:
with the 27th block beginning once file size exceeds:
Thus an ordinary roughly 13 KiB+ single-indirect file can encounter journal-record exhaustion during unlink.
The exact failure point can vary if extra writes occur, but the key issue is structural: the log limit counts writes, not unique sectors or high-level operations.
Consequence of journal exhaustion
When jnl_log reaches its limit it returns:
before performing that particular home write.
But prior logged home writes have already been applied.
The operation returns without commit.
For unlink, that can leave a state such as:
- parent dirent already removed;
- some or all data-block bitmap bits already cleared;
- inode still allocated and still pointing at blocks now marked free;
- journal still in BEGIN state.
A later mount drops the BEGIN log rather than undoing those changes.
fsck may detect secondary inconsistencies, but the journal itself does not restore the pre-operation state.
Commit sequence
jnl_commit writes:
in that order.
No record payloads are copied to home sectors at commit time because they were already written during the operation.
COMMIT therefore mainly provides a replay marker for records whose home writes might not all have reached durable storage.
No durability barriers
The journal functions call:
which ultimately calls:
They do not call:
between:
- record metadata;
- record payload;
- home-sector write;
- COMMIT header;
- EMPTY header;
- clean-superblock write.
Therefore the logical program order is not necessarily the durable device order.
Controllers, emulators or storage hardware with write caching can persist sectors in a different order.
The separate cfs_sync API calls bd_flush, but journal commit does not invoke it.
Several current block backends also expose no real flush callback, which further weakens persistence guarantees.
Crash windows around commit
Because the sequence is:
with no barriers, several states are possible.
Crash after COMMIT is durable but before EMPTY
Mount sees COMMIT and replays records.
This is the intended redo case.
Crash after EMPTY but before clean superblock
Mount sees EMPTY but the superblock may still be dirty.
Replay does nothing.
Higher boot logic can run fsck because the clean flag remains false.
Reordered persistence
Without barriers, EMPTY could become durable while some preceding record, payload or home write is not.
That breaks the simple source-code ordering argument.
The current journal protocol does not provide a formal durability proof under reordering.
Mount-time replay
cfs_mount:
- reads and decodes the superblock;
- resets the cache;
- temporarily marks the filesystem mounted;
- reads the journal header for diagnostic state;
- calls
jnl_replay; - validates root inode 0.
Replay failure aborts mount.
The initial diagnostic header read validates magic/checksum before deciding what serial message to print.
Actual recovery correctness comes from the second read inside jnl_replay.
BEGIN replay
For:
replay:
- zeros the complete header sector;
- writes it back.
No record is applied.
No old data is restored.
The superblock clean flag is not changed by replay, so a previously persisted dirty flag remains available to trigger later fsck logic.
COMMIT replay
For COMMIT, replay iterates records in increasing index order.
For each record:
- read record metadata sector;
- read payload sector;
- verify payload checksum;
- extract target LBA;
- write payload to target home sector;
- increment replay count.
After the loop it writes a CJNL EMPTY header.
There is no flush before clearing the COMMIT marker.
Oversized record-count bug
Replay loops with:
If a valid-checksum COMMIT header claims:
replay applies only the first 30 records.
It does not reject the oversized count.
Afterward, it clears the journal to EMPTY.
Therefore excess records are silently ignored rather than treated as corruption.
A robust implementation should require:
before replay begins.
Undersized journal-region interaction
The v5 superblock validator permits:
but a full 30-record log uses 61 sectors.
Neither jnl_log nor jnl_replay checks each calculated record slot against:
A crafted v5 volume with a short journal can therefore direct normal log access beyond the declared journal region.
Self-formatted volumes reserve 64 sectors and avoid this condition.
fsck journal checks
cfs_fsck reads the journal header and reports:
for some states.
However, its journal precheck does not recompute the journal-header checksum.
It examines magic and state only.
Thus a malformed header with plausible magic/state but bad header checksum can be treated differently by fsck and mount replay.
Mount replay is stricter because it verifies the checksum.
Format-time initialization
cfs_format already zeros the complete metadata region before writing final metadata.
It then creates a CJNL EMPTY header with:
- magic;
- state EMPTY;
- checksum.
Finally it calls:
This gives format a final persistence request that normal journal transactions themselves do not issue.
Validation evidence
tools/test_cfs_journal.c covers four main cases.
Geometry
It verifies:
- historical journal LBA;
- journal sector count;
- CJNL magic after format.
BEGIN discard
The test:
- starts a transaction;
- logs a synthetic inode-sector payload;
- does not write that payload to its home sector through the normal cache path;
- remounts;
- verifies BEGIN is dropped.
This validates log discard behavior.
It does not reproduce the normal cache_write sequence where the home sector is written immediately after logging.
Therefore it does not prove rollback of ordinary interrupted operations.
Forced COMMIT replay
The test manually forces a COMMIT header after logging a modified inode sector.
On remount it verifies that replay applies the payload.
This proves the redo path.
fsck dirty detection
The test writes a BEGIN header and verifies that fsck reports:
Missing failure tests
There are no dedicated host tests for:
- crash after normal home write but before COMMIT;
- device-write reordering;
- flush/barrier semantics;
- 30/31-record boundary;
- large unlink journal exhaustion;
- corrupted record target LBA;
- record metadata corruption with valid payload;
nrec > JNL_MAX_REC;- journal region smaller than the accessed record range;
- failure of the dirty-superblock write in
jnl_begin; - crash between COMMIT and EMPTY;
- crash between EMPTY and clean-superblock write.
These are important future recovery tests.
What the journal currently guarantees
Under the narrow assumptions that:
- block writes occur in source order;
- required journal sectors exist;
- logged target LBAs are valid;
- record count is within range;
- no write fails at an uncovered point;
the journal can:
- identify an operation that reached COMMIT;
- redo up to 30 logged full-sector images;
- discard an uncommitted log header;
- preserve a dirty superblock indication for some interrupted operations.
It does not guarantee:
- rollback of BEGIN transactions;
- atomic namespace mutation;
- atomic allocation;
- full metadata coverage;
- ordered durable commit under write caching;
- all-or-nothing file data updates.
Current limitations
At the documented revision:
- maximum 30 log records;
- record limit counts writes, not unique LBAs;
- no LBA deduplication;
rec_lba[]is not used for policy or validation;- no record-metadata checksum;
- target LBA is not validated during replay;
- sequence is not validated during replay;
- oversized
nrecis truncated rather than rejected; - record-slot bounds are not checked against declared journal size;
- BEGIN discard is not rollback;
- home writes happen before COMMIT;
- no durable flush/barrier protocol;
- dirty-superblock write failure in
jnl_beginis ignored; jnl_dataexcludes important allocation metadata in file-write paths;- journal coverage differs by public operation;
- create/rmdir/rename/chmod are not journal transactions;
- large unlink can exhaust the journal after partial home updates;
- fsck does not validate the journal-header checksum;
- test coverage does not exercise key crash windows.
Roadmap boundary
A stronger recovery design should consider:
- explicit transaction objects with abort semantics;
- record deduplication by home LBA;
- metadata checksum covering target LBA and record fields;
- strict
nrec <= JNL_MAX_RECvalidation; - strict slot bounds against declared journal geometry;
- target-region validation before replay;
- checked dirty-superblock persistence;
- flush/barrier ordering around log, COMMIT, home writes and log reclamation;
- consistent journaling policy for every namespace and metadata mutation;
- enough log capacity for worst-case operations or multi-transaction chunking;
- replay sequence validation;
- failure-injection tests at every persistence boundary;
- a clear choice between redo journaling, undo journaling or copy-on-write semantics.
Those remain roadmap items until implemented and covered by reproducible recovery tests.
Source map and revision note
kernel/fs/cfs.h defines journal states, record limit and the in-memory Jnl object. kernel/fs/cfs.c implements the write interception path, header generation, logging, commit and replay. kernel/fs/cfs_format.h provides the checksum helpers and persistent filesystem geometry. kernel/fs/cfs_fsck.c performs the current journal-state checks. tools/test_cfs_journal.c provides the primary host-side recovery evidence.
All current-behavior claims in this chapter were reconciled against ChrisOS revision e05a17fd76333114a3fb5c2452f38ca747d4ac56.