
Pixels, framebuffer memory and presentation
About this chapter Pixel memory and composition
In this chapter
- Pixels, framebuffer memory and presentation
- Scope and prerequisites
- From charge to an observable image
- Color is an integer contract
- Two arrays with different row strides
- Initialization and ownership
- The first presentation in kstart
- Pixel writes and clipping
- Damage tracking as an algorithm
- Presentation and its boundaries
- Cost model and bandwidth
- Validation and remaining risks
Scope and prerequisites
This chapter follows the concrete framebuffer path in kernel/gfx/graphics.c and its first caller, kstart in kernel/metal/start.c. It explains how an integer color becomes a memory update, how a two-dimensional coordinate becomes an address, why damage tracking is part of correctness, and what presentation does and does not guarantee. It assumes binary integers, pointers, array layout, physical versus virtual addresses and heap allocation. These prerequisites are linked above; the mathematical examples below make the coordinate calculations explicit.
A pixel is a discrete sample of an image. A physical display contains light-emitting or light-modulating elements, while software manipulates an encoded color value. A framebuffer is the memory representation used along a display path. A software store does not directly control a transistor in the panel: it changes memory, after which a display controller or a virtual device transports image data toward scanout. The distinction matters when diagnosing a black screen. Correct rendering, valid memory mapping, successful device presentation and an active output are separate conditions.
From charge to an observable image
The physical foundation is a chain of interfaces. Semiconductor devices implement switching and stored state. Registers hold operands and addresses. An instruction computes a value or issues a memory operation. Address translation selects the physical destination of a virtual address; caches and the memory subsystem implement the transfer under their memory-type rules. Display hardware eventually samples image memory and drives an output. None of these layers can be inferred merely from a non-null C pointer.
In an emulator, the same guest-visible contract can be implemented with host memory and a host display window. The guest pixel does not know whether its destination is physical display memory or a modeled resource. Conversely, identical C code does not prove identical cache attributes, timing or synchronization on two backends. ChrisOS therefore needs separate evidence for the software framebuffer algorithm and for the device path consuming its output.
Color is an integer contract
gfx_rgb shifts red into bits 23–16, green into bits 15–8 and blue into bits 7–0. Its result is 0x00RRGGBB; the upper byte is zero. For red 0x12, green 0x34 and blue 0x56, the integer is 0x00123456. On little-endian x86, increasing byte addresses contain 56 34 12 00. Integer channel naming and byte order are different descriptions of the same storage. Calling those bytes “RGBA” without specifying the convention would misdescribe their order.
| Bits | Meaning in gfx_rgb |
Value in the example |
|---|---|---|
| 31–24 | Zero, not opacity supplied by gfx_rgb |
00 |
| 23–16 | Red | 12 |
| 15–8 | Green | 34 |
| 7–0 | Blue | 56 |
gfx_blit_rgba has a different input contract, documented in graphics.h: its source pixels are 0xAARRGGBB. It skips alpha zero, copies RGB directly for alpha 255, and blends intermediate values against the current destination. Per channel the integer calculation is (source * alpha + destination * (255-alpha)) / 255, with truncation. This is straight-alpha arithmetic in the stored channel values. The function does not establish a color-managed, linear-light compositing pipeline, nor does it preserve a composited alpha channel in the destination. These distinctions affect translucent edges even when address calculations are correct.
Two arrays with different row strides
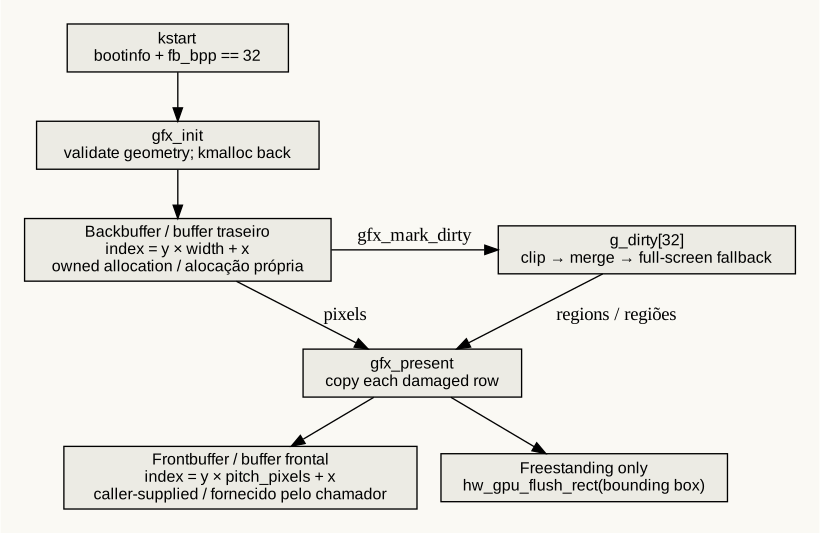
GfxFramebuffer contains front, back, width, height and pitch_pixels. The front pointer is supplied by the caller. The back pointer identifies a separate allocation owned by the graphics implementation. A logical image has width * height active pixels, but the front buffer may include unused bytes between rows. That separation is the reason the structure records pitch independently from width.
For a four-byte pixel at coordinate (x,y), the byte offsets are:
back_offset  = 4 * (y * width + x)
front_offset = y * pitch_bytes + 4 * x
pitch_pixels = pitch_bytes / 4
Take width 4, height 3 and pitch 24 bytes, as in the host test. The backbuffer uses 16 bytes per row and 48 bytes in total. The front row occupies 24 bytes: four active pixels followed by two padding pixels. Pixel (1,1) is at back offset 20 but front offset 28. Copying all 12 active pixels as one contiguous region would overwrite padding and place later rows at the wrong address. gfx_present avoids that by copying each damaged row separately.
| Coordinate | Back pixel index | Front pixel index | Interpretation |
|---|---|---|---|
(0,0) |
0 | 0 | First active pixel |
(3,0) |
3 | 3 | Last active pixel in row zero |
(0,1) |
4 | 6 | Padding exists only on the front path |
(1,1) |
5 | 7 | Same image coordinate, different array index |
(3,2) |
11 | 15 | Last active pixel of the image |
The valid domain is 0 <= x < width and 0 <= y < height. Exclusive upper bounds make an image width equal to the number of valid columns. A rectangle [x0,x1) × [y0,y1) therefore contains (x1-x0)*(y1-y0) pixels and can be empty without a special coordinate convention.
Initialization and ownership
gfx_init rejects a null address, nonpositive dimensions, dimensions above GFX_MAX_WIDTH or GFX_MAX_HEIGHT, a pitch smaller than a row, and a pitch not divisible by four. The header caps the dimensions at 1920 by 1080. Those checks validate the geometry expected by this implementation; they do not prove that the pointer spans a writable mapping of the required size, or that the device uses the expected channel masks.
The function frees an existing private backbuffer and allocates a new width * height * sizeof(uint32_t) region with kmalloc. On success it installs both pointers and the geometry, clears the damage count and marks the full image dirty. The initial dirty rectangle is not an initialization of pixel values. kstart performs a clear before presenting so that the newly allocated backbuffer is populated first.
There is a significant failure-path distinction during reinitialization. The old allocation is freed before the new allocation succeeds. If allocation then fails, the function returns false without restoring the old framebuffer state; g_gfx.back may still contain the freed address. At the boot call site, failure leads to panic, so the caller does not continue drawing. A future runtime mode-switch caller must not assume transactional rollback. This observation is based on the ordering in the source; this documentation change does not repair the kernel behavior.
The first presentation in kstart
The startup path initializes physical memory, virtual memory and the heap before requesting graphics storage. It also initializes the bootstrap processor's SSE support before the graphics clear and copy path. After obtaining boot information, it checks fb_bpp == 32 and calls gfx_init with the framebuffer address, width, height and byte pitch. A rejected framebuffer causes a panic. The code then calls virtio_gpu_boot, discards its return value, clears the image to 0x00101828 and presents it.
This sequence establishes a useful debugging boundary: a visible background depends on the basic allocation and presentation path, but it does not prove that the desktop, input, language compiler, filesystem or network is ready. Those components have separate initialization later in the entry function. The early graphics operation occurs before the subsequent SMP initialization, but that ordering alone does not establish a general concurrency policy for all later rendering.
Pixel writes and clipping
put_pixel_raw returns without writing if the backbuffer is absent or the coordinate is outside the valid domain. Otherwise it stores into back[y * width + x]. gfx_put_pixel calls this helper and then marks a one-pixel rectangle dirty. Damage clipping discards rectangles that have no intersection with the screen, so an ordinary off-screen pixel does not create a valid damage entry.
gfx_fill_rect clips a rectangle to the visible extent and fills each surviving row with gfx_fast_fill_u32. Its work scales with the number of pixels written. Unlike the raw pixel helper, this routine does not independently guard every invalid initialization state. API callers must respect successful initialization. Furthermore, clipping expressions such as x + width are signed integer calculations. Extreme untrusted input can overflow before clipping is applied. Screen clipping is not a replacement for validating an external ABI's argument range.
Damage tracking as an algorithm
Damage means that the backbuffer differs from the last presented contents in a region that must be copied. ChrisOS stores at most 32 GfxDirtyRect records in a static array. Each record has four integer endpoints. The count determines which records are active; there is no dynamic allocation per update.
gfx_mark_dirty first rejects nonpositive extents, computes the far endpoint, clips to the screen and rejects an empty result. It scans the current array for touching rectangles. For a match it replaces the candidate with the bounding rectangle of both regions, removes the old record by moving the final record into its slot, decrements the count and restarts scanning from index zero. Restarting matters: expansion can make the candidate touch a rectangle examined before the merge.
The merge uses a bounding box, not an exact union of covered pixels. Two diagonal or edge-adjacent regions may cause unchanged pixels inside that bounding box to be copied too. This is conservative: over-copying wastes bandwidth, whereas failing to copy an altered pixel leaves stale output. The implementation treats shared boundaries as touching because rects_touch uses inclusive comparisons between the exclusive endpoints.
With D stored rectangles, one call can do quadratic comparison work in the worst case because each merge can restart the scan. Here D is capped at 32, which bounds the metadata cost. When a disjoint new rectangle would exceed that capacity, the algorithm replaces the list with one full-screen rectangle. That fallback preserves coverage under saturation. It trades more copy traffic for a fixed-size structure and a simple failure-free insertion path.
Presentation and its boundaries
For each dirty rectangle, gfx_present visits rows from y0 through y1-1, computes the destination using pitch_pixels, computes the source using width, and copies x1-x0 pixels. In a freestanding build it also forms one bounding box around all damage and calls hw_gpu_flush_rect. Finally it clears the count. A hosted unit test omits that conditional device operation.
This is a copy-based presentation path. It is not an atomic pointer exchange between hardware scanout buffers. A display engine can potentially read the frontbuffer while a copy is in progress; a software backbuffer alone does not prove tear-free output or vertical-blank synchronization. Similarly, the flush call's existence is not proof of device completion. Device-specific code and its synchronization contract must supply that evidence.
No lock in this file protects g_dirty_count, the rectangle array or pixel stores. Concurrent writers or a writer racing with presentation require coordination outside this implementation. In particular, clearing the count after a racing update could lose its damage record. It would be incorrect to label these globals thread-safe merely because stores of an individual aligned pixel may be naturally atomic on the target processor.
Cost model and bandwidth
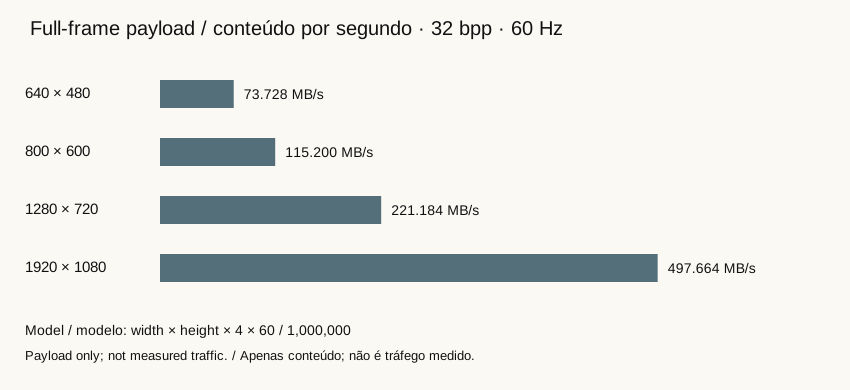
An unpadded 1920 by 1080 image with four bytes per pixel occupies 8,294,400 bytes, about 7.91 MiB. A full copy at 60 presentations per second moves 497,664,000 bytes of image payload per second into the destination. Reading the source and writing the destination accounts for roughly twice that many transferred bytes before cache effects, write allocation or device transactions. This is an arithmetic model, not a measured ChrisOS benchmark.
Let A be the summed area of the disjoint dirty records and R their total number of covered row segments. Copy work is proportional to A, with call and row overhead proportional to R. Bounding-box merging can increase A, while full-screen fallback sets it to width*height. Small scattered writes can therefore be more expensive than their count suggests. Alternative representations include a tile bitmap or per-row spans, but either would change metadata, merge behavior and the presentation loop. Replacement should follow measured workloads rather than an assumption that a more elaborate structure is always faster.
Validation and remaining risks
tools/test_graphics_present.c supplies host malloc and free implementations for kmalloc and kfree. It checks padded-row preservation, a partial rectangle, no copy when damage is empty, overflow fallback after 33 separated updates, and nearest-neighbor scaling. The padding sentinel 0xdeadbeef is especially useful because it detects a contiguous-copy error that a tightly packed image would hide.
| Evidence | Establishes | Does not establish |
|---|---|---|
| Padded frontbuffer test | Active rows respect the supplied pitch | Hardware memory attributes |
| Partial rectangle test | Neighbors outside that region remain unchanged | All clipping and overflow cases |
| Empty-damage test | An unmarked direct back write is not presented | Correctness of all callers' damage reporting |
| 33-update test | Saturation becomes a full-screen copy | Optimal bandwidth |
| Host execution | Tested software path works in that build | Guest boot, GPU completion or physical scanout |
The implementation therefore has a concrete software contract and reproducible tests, while reinitialization failure, untrusted extreme coordinates, concurrency ownership, color-format validation and tear-free presentation remain separate review topics. Future changes must preserve both the address invariant and the damage invariant. A source-only inspection cannot certify those wider system properties.