
Semantic analysis and type systems
About this chapter Compiler construction
In this chapter
- Semantic analysis and type systems
- Scope
- Semantic analysis as a set of invariants
- ChrisC semantic state
- The ChrisC Symbol model
- Scopes and name lookup in ChrisC
- Declaration insertion and duplicate detection
- Typedefs as semantic parser state
- Structure and union identity
- Aggregate layout in ChrisC
- Incomplete and nested aggregate types
- Cast semantics in ChrisC
- Lvalues in ChrisC
- Pointer semantics in ChrisC
- Floating classification in ChrisC
- _Generic in ChrisC
- Functions and call semantics in ChrisC
- KCC type representation
- KCC Val and value categories
- KCC symbol lookup
- Builtin type normalization in KCC
- Structures and alignment in KCC
- Member access in KCC
- Address-of and dereference in KCC
- Array decay in KCC
- Assignability in KCC
- volatile in KCC
- Floating-point boundary in KCC
- Constant-expression semantics
- sizeof as a semantic transaction
- Static assertions
- Diagnostics and failure model
- Complexity and storage costs
- Concurrency and reentrancy
- Security and robustness
- Validation evidence
- Current limitations
- Roadmap boundary
- Source map and revision
Scope
Semantic analysis determines whether a syntactically valid program has a meaning supported by the language implementation. It resolves names, classifies types, checks operations against those types, computes layout, validates assignability, selects conversions and carries information required by later code generation.
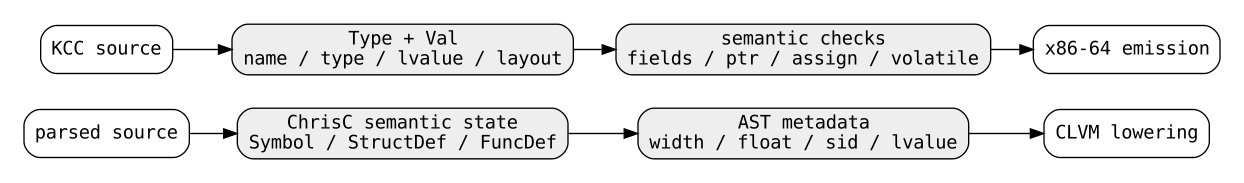
ChrisOS currently has two substantially different C-like compiler paths.
ChrisC parses into AST-like Node records for CLVM lowering. Its semantic state is distributed across Symbol, StructDef, FuncDef, typedef tables, constants and metadata embedded in nodes. Semantic work happens during parsing and again during lowering.
KCC has no separate AST semantic pass. It uses Type and Val records while parsing and emits x86-64 assembly immediately. Name resolution, type propagation, lvalue checking, layout and backend emission therefore occur in one syntax-directed pipeline.
Neither path implements a complete ISO C type system. Both implement project-specific profiles shaped by the programs ChrisOS needs to build.
Semantic analysis as a set of invariants
A useful model is to treat semantic analysis as preservation of invariants.
For every identifier use, there must be a visible declaration or another recognized meaning such as an enum constant, builtin or function.
For every field access, the base must identify a structure type and the field must exist.
For every assignment target, the expression must designate writable storage in the supported model.
For every pointer operation, the compiler must know enough about the pointee to compute address arithmetic or reject the operation.
For every aggregate, the compiler must assign a stable size and field offsets before generated code depends on those offsets.
For every conversion, the compiler must preserve the subset's intended width, signedness, floating classification and pointer semantics.
The implementation does not encode these invariants in one semantic-pass object. They are enforced by several tables and local checks.
ChrisC semantic state
ChrisC stores the main semantic universe inside Compiler.
Important fixed-capacity tables include:
- Symbol syms[] for variables and objects;
- StructDef structs[] for structure and union layouts;
- FuncDef funcs[] for functions;
- typedef arrays for names, widths, pointer classification, structure identity and array metadata;
- constant tables for enums and compile-time names;
- Node nodes[] for parsed expressions and statements.
This architecture avoids dynamic compiler-side allocation for many common objects, but introduces explicit saturation limits. A full table is a compile-time failure rather than a growable condition.
The design also means identity is usually an integer index. A structure is referred to through a structure ID, a symbol through its table index and an AST child through a node index.
The ChrisC Symbol model
Symbol is not a single canonical C type descriptor. It is a compact storage-oriented record carrying the properties needed by the current compiler.
It records, among other fields:
- name and storage address;
- scalar width;
- float classification;
- packed byte classification;
- array and pointer flags;
- unsigned and const flags;
- scope identifier;
- pointee width;
- structure ID;
- stride;
- array count;
- global and thread-local state.
This is enough for the current compiler to answer practical questions such as:
How many bytes does this object occupy?
Does indexing advance by 1, 4, 8 or a structure size?
Is the value represented as a floating value?
Does member access need structure metadata?
Is assignment to this symbol forbidden because it is const?
It is less expressive than a recursive type graph. Deep declarator structure is compressed into flags and side metadata.
Scopes and name lookup in ChrisC
Local scopes use numeric scope IDs.
scope_enter increments a sequence and pushes the new ID onto a bounded scope stack. scope_leave removes the active scope. scope_visible determines whether a stored symbol belongs to any currently active scope.
sym_find_local walks symbols from newest to oldest. This provides normal shadowing behavior for visible local declarations: the most recent matching declaration wins.
sym_find first checks visible locals, then checks translation-unit-mangled static names when applicable, then global names through the symbol hash table.
The lookup model therefore combines:
- stack-like lexical visibility for locals;
- hash-based lookup for globals;
- translation-unit mangling for file-local static symbols.
The local reverse scan is O(n) in the number of recorded symbols in the worst case. Global hash lookup is expected near constant time under ordinary table occupancy, but the tables are fixed-size and use project-specific hashing rather than an unbounded compiler data structure.
Declaration insertion and duplicate detection
sym_add first attempts permitted global reuse, then scans declarations in the current scope for a duplicate.
A same-scope duplicate produces a diagnostic. Shadowing in a nested scope is allowed because the scope ID differs.
When the declaration is accepted, the compiler normalizes storage properties. Pointer objects use width 8 for the pointer itself while preserving pointee width separately. Non-pointer small values can still reserve a minimum storage slot according to the current CLVM-oriented memory model.
This is an important distinction:
object width != pointee width != allocation stride
The compiler therefore cannot infer pointer arithmetic correctly from pointer object width alone.
Typedefs as semantic parser state
typedef_find searches the typedef table.
Typedef knowledge is required before parsing can even choose the correct syntactic interpretation. is_typename_at consults typedefs when distinguishing a cast from a parenthesized expression, and parse_type_n imports the stored typedef width, pointer classification, structure ID, array count and element width.
This makes typedef resolution both syntactic and semantic state.
Forward structure typedefs are a special case. A typedef can be recorded while a structure is still incomplete. typedef_refresh_struct and typedef_live_width later reconcile the typedef width with the completed structure size.
That behavior prevents an early placeholder width from permanently corrupting operations such as sizeof or pointer stride.
Structure and union identity
struct_find maps a tag to StructDef.
Each StructDef contains:
- field names;
- field widths;
- floating and pointer classification;
- field offsets;
- nested structure IDs;
- array element widths;
- bit-field width and bit offset;
- aggregate size;
- packed and union flags.
field_find performs field-name lookup by linear scan inside one aggregate.
Because FIELD_MAX bounds the number of fields, lookup has a small fixed upper bound, but it is still O(f) in field count.
Aggregate layout in ChrisC
parse_struct_def and struct_recompute_layout compute the current ChrisC structure representation.
For ordinary non-packed fields, widths of one or two bytes are promoted to a four-byte storage unit by this layout model. Wider fields consume their recorded width. Packed structures use the recorded width directly.
Union fields receive offset zero and aggregate size becomes the maximum field storage requirement.
Bit fields are packed into 32-bit units when supported. struct_recompute_layout starts a new unit when the current field would cross the 32-bit boundary and records both byte offset and bit offset.
This is a project ABI decision. It must not be generalized into a claim that ChrisC reproduces every host or System V C aggregate-layout rule.
Incomplete and nested aggregate types
A StructDef can exist before all fields are known. That enables tagged forward references.
Nested structures carry fstruct IDs. Pointer fields retain pointer classification separately so that a pointer to a structure is not confused with an embedded structure value.
When a structure body completes, semantic metadata must become internally consistent before code generation uses member offsets or pointer stride.
The type system therefore has a temporal aspect: some types transition from declared/incomplete to layout-complete.
Cast semantics in ChrisC
CastType is the temporary semantic representation used by parse_cast_type.
It records:
- result width;
- float classification;
- unsignedness;
- pointer state;
- void and boolean classification;
- pointee width;
- pointee float state;
- structure ID.
The AST stores cast information in compact encoded form. Width and flags are packed into the N_CAST node payload.
This saves representation space but couples semantic interpretation to bit encodings known by later lowering code.
Supported casts include integer-width changes, boolean normalization, float/integer conversions in the supported profile, pointer-shaped casts and selected structure-aware pointer metadata.
A cast is therefore not merely syntax removal: it changes how subsequent lowering interprets the value.
Lvalues in ChrisC
ChrisC does not expose a universal first-class Type plus value-category object for every expression. Instead, assignability is inferred from node kind and referenced symbol metadata.
Supported assignment targets include ordinary variables and specialized AST forms for:
- array indexing;
- fields;
- pointer dereference;
- pointer-field access.
When no accepted storage form matches, assignment fails with an "assignment needs lvalue" diagnostic.
Const is tracked on symbols and assignment paths consult that state for the supported direct cases.
The approach is pragmatic but decentralized: adding a new expression that can denote storage requires updating the semantic and code-generation paths that recognize lvalues.
Pointer semantics in ChrisC
Pointer objects are eight bytes, but Symbol.pointee and Symbol.stride retain the information required to advance addresses.
Pointer increment and decrement use expr_ptr_stride. Array and field operations similarly use element widths or structure metadata.
This realizes the central pointer-arithmetic rule:
address_delta = integer_delta * pointee_stride
The system supports the pointer categories required by the current codebase, but it is not a full recursive C declarator model. Multi-level pointer distinctions and qualifiers are represented only to the degree implemented by the stored fields and cast encoding.
Floating classification in ChrisC
Node contains an is_float flag, and Symbol and StructDef carry corresponding float metadata.
Arithmetic lowering inspects operand float classification and can insert integer-to-float conversion where one side requires it.
Pointer dereference requires special handling because "pointer value is not float" and "pointee is float" are different statements. deref_pointee_float follows cast metadata, symbol pointee classification and expression metadata to determine the loaded value class.
This is another example of semantic information spread across AST nodes and symbol records rather than one recursive type object.
_Generic in ChrisC
ChrisC supports a project subset of _Generic.
The controlling expression is parsed and its semantic classification is inspected to choose among supported associations. The implementation is narrower than the full ISO C notion of compatible types.
The important architectural point is that generic selection consumes semantic type information during parsing. It is not deferred to a later tree pass.
Functions and call semantics in ChrisC
FuncDef stores function names, argument count, per-argument width and floating classification, return classification, body node and generated entry metadata.
Function lookup is separate from ordinary variable lookup.
During call construction, ChrisC distinguishes builtins, known functions and function-pointer-shaped values. Return metadata is propagated into the call node so later expressions can classify the result.
This is enough for the current CLVM ABI, but it does not amount to a general function-type compatibility engine covering all C prototype rules.
KCC type representation
KCC uses a more explicit Type record.
Type contains:
- kind;
- is_ptr;
- pointee_size;
- array_len and inner_len;
- struct_id;
- size and alignment;
- volatile state;
- pointee volatile state;
- function-pointer state.
type_make initializes a scalar type. type_ptr derives a pointer while retaining pointee size, structure identity and pointee volatility.
This representation is still compact, but it is carried directly by expressions through Val.
KCC Val and value categories
Val combines semantic type with the current value category and backend state.
It records:
- Type type;
- lvalue flag;
- function classification;
- lvalue location kind;
- frame slot;
- immediate-value state;
- global symbol name.
The lvalue location enum distinguishes:
LV_LOCAL
LV_GLOBAL
LV_ADDR
This is significant because two expressions can have the same Type while requiring completely different load/store sequences.
Semantic analysis in KCC therefore classifies both "what type is this?" and "where does this value live?".
KCC symbol lookup
KCC stores Sym records in a fixed table.
sym_find scans backward for an alive matching symbol. This naturally gives the newest declaration priority.
Unlike ChrisC's explicit numeric visibility stack, KCC uses symbol liveness and parser-controlled lifetime to represent current visibility.
The worst-case lookup cost is O(n) in active plus retained symbols.
Typedefs are held separately as name-to-Type mappings in g_td_name and g_td_type. td_find is a linear search over that fixed table.
Builtin type normalization in KCC
parse_base recognizes the compiler's builtin and typedef type vocabulary.
The implementation maps several familiar C spellings into a smaller internal universe. For example, multiple 64-bit integer typedef names converge on the same internal width-oriented Type representation.
That simplification is practical for kernel compilation but means source-level distinctions are not always preserved as separate semantic kinds.
KCC also records volatile, structure identity, pointer depth in the supported forms, array geometry and alignment.
Structures and alignment in KCC
KCC StructDef stores Field records, aggregate size and aggregate alignment.
Each Field owns a full Type plus a byte offset.
Structure parsing computes field layout immediately. A field offset is aligned to the selected alignment unless packed behavior reduces alignment. Aggregate alignment becomes the maximum applicable field alignment, and final size is rounded up to that alignment.
The tests explicitly exercise ordinary and packed layouts.
This model is closer to a conventional native compiler layout description than ChrisC's CLVM-oriented compact field arrays, but it is still the layout implemented by KCC rather than a claim of complete ABI conformance.
Member access in KCC
postfix_tail performs semantic checks for dot and arrow.
For arrow:
- the base must be a pointer;
- the type must carry a valid structure ID.
For dot:
- the base must not be a pointer;
- the type must carry a valid structure ID.
The field name is then searched in the selected StructDef. Missing fields fail immediately.
The resulting Val becomes an address lvalue with the field's Type.
Thus member selection simultaneously performs name resolution, type checking, offset calculation and value-category construction.
Address-of and dereference in KCC
Address-of requires an lvalue. If the operand is not addressable, compilation fails.
On success, gen_addr materializes the address and type_ptr converts the operand type to a pointer type.
Dereference performs the opposite check. The operand must be a pointer or supported array-like form. The pointee size is used to build the resulting element Type, and the result becomes an LV_ADDR lvalue.
The semantic transitions are:
lvalue T --&--> rvalue pointer-to-T

pointer-to-T --*--> lvalue T
These transitions are directly connected to emitted assembly.
Array decay in KCC
load_val contains array-to-pointer decay behavior.
If a Val is an array lvalue, loading it does not load the whole array. The compiler generates its address, clears the lvalue category and converts its type with type_ptr.
This is a semantic rule implemented inside a backend-facing helper, illustrating again that KCC does not separate semantic analysis from lowering.
Indexing computes an element address from base plus index multiplied by element size, then returns an address lvalue with the element Type.
Assignability in KCC
Simple and compound assignments require out->lvalue.
Simple assignment additionally rejects array values as assignment destinations.
The compiler saves the destination Val before parsing the right side, evaluates the right side into RAX and calls store_val with the saved destination description.
Increment and decrement use the same idea. inc_lv rejects non-lvalues, derives a step of one for scalars or pointee_size for pointers, computes the new value and stores it through the original destination category.
volatile in KCC
Type records volatile at the object level and separately for pointees.
load_val and store_val change behavior for volatile memory. In particular, volatile globals bypass the dead-store elimination logic used for ordinary globals.
The test suite verifies repeated volatile stores and loads remain present in emitted assembly while redundant ordinary stores can be reduced.
This is a meaningful semantic property: volatile affects observable access behavior, not only type spelling.
Floating-point boundary in KCC
KCC recognizes float in its type vocabulary, but current native code generation deliberately rejects ordinary float value operations through reject_float.
Therefore the existence of TY_FLOAT does not imply a complete native floating-point implementation.
Documentation must distinguish:
- parsing/recognition of the type;
- storage of type metadata;
- executable operations actually supported by code generation.
The current semantic boundary reports float as outside the supported subset for paths that require a native value load or store.
Constant-expression semantics
KCC has a separate evaluator for constant expressions.
ce_primary, ce_unary, ce_bin and ce_expr are used for contexts such as:
- array bounds;
- enum values;
- preprocessor conditions;
- static assertions.
The evaluator computes uint64_t values directly and checks conditions such as division by zero and invalid shift counts.
Because runtime expression parsing and constant-expression parsing are separate implementations, semantic parity between them is an explicit maintenance risk. Operator precedence and accepted forms can diverge unless tests cover both.
sizeof as a semantic transaction
parse_sizeof_type accepts either a type form or an expression.
For a type, size is obtained from Type metadata.
For an expression, KCC must discover the resulting Type without retaining runtime code-generation side effects. It snapshots assembly length, overflow state, dead-store state, temporary count and frame state, parses the expression, then restores the backend state.
This is effectively a semantic transaction over an otherwise fused parser/backend.
If the resulting type has no valid positive size, sizeof reports an incomplete-type error.
Static assertions
_Static_assert uses the constant-expression evaluator.
The condition is parsed and evaluated at compile time. A zero result produces a compile failure.
This is semantic validation because the statement can be syntactically well formed while still being invalid due to its constant value.
Diagnostics and failure model
Both compilers are predominantly fail-fast.
ChrisC records source coordinates through its token stream and returns diagnostics through ChrisResult.
KCC maintains KccDiag with file, line, column, severity and message.
Semantic errors include classes such as:
- duplicate variable;
- unknown symbol or field;
- assignment to a non-lvalue;
- address-of a non-addressable expression;
- dereference of a non-pointer;
- dot or arrow on an incompatible base;
- invalid array bound;
- incomplete type in sizeof;
- unsupported builtin or type operation.
There is no general multi-error semantic recovery pass. Once parser and backend state are partially mutated, continuing safely would require a more explicit transactional or multi-phase architecture.
Complexity and storage costs
The dominant semantic operations are bounded table operations.
ChrisC local name lookup is linear in stored symbols; global, typedef and structure lookup use fixed hash tables in several paths; field lookup is linear in fields.
KCC symbol, typedef, enum and field searches are primarily linear scans over fixed arrays.
Aggregate layout is linear in field count.
Expression type propagation is performed during the same traversal as parsing, so it adds O(1) local semantic work to most expression nodes. Overall normal compilation remains approximately linear in source size aside from lookup factors, preprocessing expansion and any repeated scans.
The fixed-table approach gives predictable allocation behavior and avoids allocator dependence inside important compiler paths, at the cost of hard capacity limits.
Concurrency and reentrancy
ChrisC keeps most state in an explicit Compiler instance, which is structurally more suitable for independent compilations.
KCC stores much of its compiler state in file-scope globals such as g_p, g_struct, g_sym, g_td_type and assembly buffers.
KCC is therefore not a reentrant compiler context in the current implementation. Concurrent compilations in one process would require serialization or refactoring into an explicit context object.
This is an implementation property, not a general limitation of the language profile.
Security and robustness
Compiler inputs can be hostile even when the compiler is primarily a project tool.
Relevant semantic robustness boundaries include:
- fixed table saturation;
- aggregate and array size arithmetic;
- invalid or incomplete types;
- recursive declarator depth;
- malformed field graphs;
- pointer-width assumptions;
- rollback correctness in speculative semantic parsing;
- diagnostics after partial state mutation.
Current code contains explicit bounds and many fail-fast checks, but neither compiler should be described as hardened against arbitrary adversarial source solely from those checks.
Validation evidence
ChrisC validation includes test_chrisc_c17.c, which exercises typedefs, structures, arrays, casts, sizeof, _Generic, function pointers, compound literals and other C-profile features. test_chrisc_lang.c compiles and executes ChrisC programs on CLVM. test_fuzz_chrisc.c supplies malformed inputs to robustness paths.
KCC validation in test_kcc.c compiles both focused snippets and real ChrisOS source files. Tests cover structure layout, packed structures, nested aggregates, enums, volatile access, pointer-oriented operations, static assertions and native object/link flows.
These tests provide implementation evidence. They do not establish full language-standard conformance.
Current limitations
At the documented revision:
- neither compiler has a clean standalone semantic-analysis pass;
- neither implements complete ISO C compatibility rules;
- ChrisC distributes type facts across symbols, AST flags and side tables;
- KCC fuses type checking with native emission;
- KCC uses global compiler state and is not reentrant;
- KCC native float operations remain outside the supported subset;
- type compatibility is narrower than a full recursive canonical type system;
- semantic diagnostics are largely fail-fast;
- symbol and type tables have fixed capacities;
- constant and runtime expression semantics are maintained by separate KCC paths;
- qualifier propagation is implemented only for the subset represented in current metadata;
- function compatibility is not a complete ISO C prototype-compatibility engine;
- source-level distinctions can collapse into width-oriented internal types.
These boundaries should remain explicit when evaluating what code the toolchains can compile.
Roadmap boundary
Possible future work includes:
- one recursive canonical type representation shared by declarations and expressions;
- explicit semantic-analysis passes over a stable AST or typed IR;
- type compatibility and conversion routines separated from parsing;
- richer qualifier propagation;
- complete function types and prototype checking;
- structured semantic diagnostic codes;
- multiple-error recovery;
- context-based reentrant KCC state;
- unified constant/runtime operator semantics;
- property tests for layout and pointer arithmetic;
- differential tests against declared language-profile rules;
- clearer ABI contracts for aggregate layout.
These are roadmap directions, not claims about current implementation.
Source map and revision
ChrisC semantic behavior is concentrated in compiler/chrisc/chrisc.c around Symbol, StructDef, DeclType, CastType, scope and symbol lookup, structure layout, parse_type_n, parse_cast_type, primary/postfix/unary expression construction, assignment validation and CLVM lowering.
KCC semantic behavior is concentrated in compiler/kcc/kcc.c around Type, Field, StructDef, Sym, Val, type_make, type_ptr, parse_base, parse_primary, postfix_tail, parse_unary, parse_binary, load_val, store_val, constant expressions and structure layout.
All current-behavior claims in this chapter were reconciled against ChrisOS revision e05a17fd76333114a3fb5c2452f38ca747d4ac56.