
Machine emulation: architectural state, instruction steps and faults
About this chapter Architectural semantics
In this chapter
- Machine emulation: architectural state, instruction steps and faults
- The contract being reproduced
- State as an explicit data structure
- Fetch is a guest memory operation
- Decoding and operand interpretation
- The actual order in cpu_run
- Interrupts and a bounded pending state
- Guest virtual, guest physical and host storage
- Faults, exits and precision
- Complexity and optimization boundaries
- Current virtualization boundary
- Evidence and reproducible validation
The contract being reproduced
A functional machine emulator reproduces the guest-visible behavior of a target machine using software. Its host need not share the target instruction set. A hardware virtualizer instead uses facilities of a compatible processor to execute guest instructions directly while retaining control over privileged transitions and selected events. Both need a machine model for memory and devices. A graphical window, an ELF loader or a command-line interface does not determine which mechanism is underneath.
The relevant standard for an interpreter is architectural behavior: register values, memory effects, exceptions, device interactions and execution ordering observable by the guest. Reproducing a commercial processor's pipeline, caches and branch prediction is a separate microarchitectural or timing goal. ChrisCPU's step counter is not evidence of that stronger model. This distinction makes a small functional interpreter valuable without presenting it as a cycle-accurate processor simulator.
This chapter follows chriscpu.c, mmu.c, the shared architecture header and the machine tests at the declared revision. It assumes instruction-set architecture, integer representation, address translation and memory-mapped versus port-mapped I/O. The details of individual opcode encodings belong to the decoding chapter; here the subject is the state-transition framework that gives decoded instructions meaning.
State as an explicit data structure
Abstractly, execution transforms a machine state S under an instruction and an external-event input. The state includes registers, memory and devices, not just the next instruction pointer. A useful conceptual equation is step(S, input) -> (S', outcome). The outcome can be continued execution, a guest exception, a debugger stop or a host-facing machine exit. The implementation must keep those cases distinct so that a guest fault is not confused with a failure of the host program itself.
ChrisArchitectureState provides the shared representation of registers and architectural control state. General-purpose registers can be addressed through the gpr[16] array or named members of the union. The surrounding CPU object also tracks execution machinery such as halt state, pending interrupts, tracing and exit reason. Those implementation fields are not all guest-visible x86 registers. Separating them avoids treating a debugger breakpoint flag as part of the guest's architectural ABI.
The ChrisCpuBackend table supplies lifecycle and execution operations. The interpreter and reserved hardware backend occupy the same interface. A common state structure is a useful boundary for a future backend, but it does not prove that all state can already be imported into or exported from actual virtualization hardware.
Fetch is a guest memory operation
An interpreter must retrieve instruction bytes using the guest's current execution address and access rules. Dereferencing the numerical guest instruction pointer as a host pointer would bypass guest translation and expose an invalid host address. ChrisCPU uses chris_va_read with the execute access class while fetching from cpu->arch.rip.
The current fetch_insn helper attempts to read 15 bytes, one byte at a time, before decoding. Fifteen is the x86 instruction-length limit, but a particular instruction can be much shorter. That implementation choice creates an important review case: a short instruction near the end of a mapped page can cause the helper to inspect bytes in the next page that the instruction itself does not require. An incremental fetch/decode strategy can avoid such unnecessary access, but must handle prefixes and incomplete encodings carefully. The source establishes the eager-read behavior; a boundary test is needed to characterize every resulting exception path.
Instruction fetch also demonstrates why ordinary RAM and device access cannot be treated interchangeably. A physical map may route an address to a device callback. An extra read can have an observable effect if that region has side-effectful access semantics. Correct instruction length therefore affects both decoding and the boundary of memory operations performed on behalf of the guest.
Decoding and operand interpretation
chris_decode converts fetched bytes into a ChrisInsn. A negative decode result causes the run loop to request an invalid-opcode exception through chris_raise. Decoding determines instruction length and operand form; execution then applies semantics. Keeping these responsibilities separate permits byte-level decoding tests and state-transition tests to isolate different errors.
For x86, operand size, address size, register extensions and memory addressing can depend on prefixes and encoding fields. A displacement is not necessarily an absolute address, and an immediate can require sign extension before participating in a wider operation. A decoder that produces the right mnemonic but the wrong width can still corrupt upper register bits or calculate incorrect flags. Documentation must identify the representation and width at the boundary between decode and execute rather than treating disassembly text as a correctness certificate.
Arithmetic flags are also architectural outputs. Carry describes unsigned overflow while overflow describes the signed-range condition. For an eight-bit example, 0xff + 1 produces zero with carry; 0x7f + 1 produces 0x80 with signed overflow. The same result bits can be interpreted under different signedness, but the emulator must compute the flag definitions of the instruction. The existing flag tests include corresponding 64-bit boundary cases.
The actual order in cpu_run
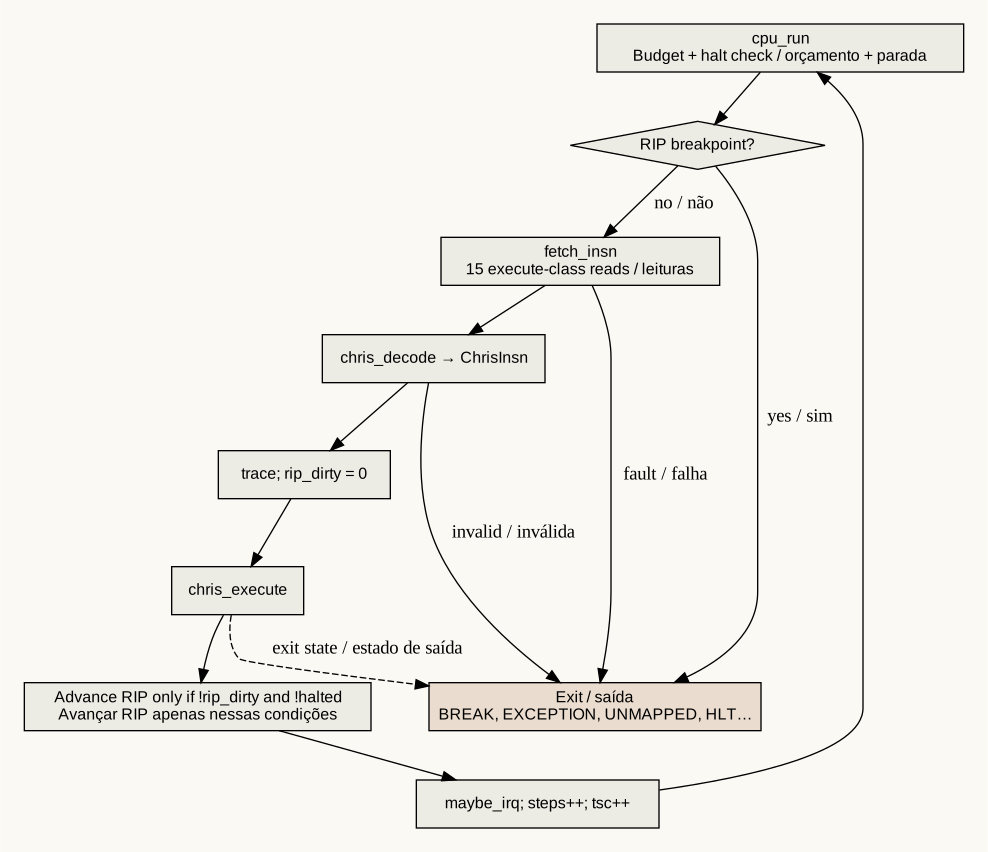
The run function rejects a null CPU, clears the halt flag and generally resets the exit reason, preserving the special breakpoint case handled in the source. It then loops while its local count is below max_steps and the CPU has not halted. Each iteration checks the configured RIP breakpoint, fetches and decodes bytes, formats the instruction for diagnostics, optionally logs it and pushes an entry into the trace history.
Before executing, it clears rip_dirty. The instruction executor can mark the instruction pointer as explicitly changed. After execution, the loop advances RIP by the decoded length only if RIP was not explicitly changed and the CPU is not halted. This convention prevents a taken branch, return or exception-directed transfer from receiving an additional fall-through increment.
Next, maybe_irq considers pending interrupt delivery. Finally the loop increments steps, the modeled tsc and its local iteration counter. Early exits before that point, such as a fetch failure or decode failure, do not traverse the same counting path. Consequently, the counter should be interpreted according to this control flow, not casually described as the number of all architecturally retired instructions. If the budget ends without a halt, the exit reason becomes CHRIS_EXIT_STEP_LIMIT.
Interrupts and a bounded pending state
maybe_irq first handles sti_delay: when set, it clears the field and returns without delivery in that call. It then rejects delivery for a halted CPU or absent pending IRQ, and checks the interrupt-enable bit in RFLAGS. When delivery proceeds, it clears the pending flag and calls chris_raise with the stored vector. The intended delayed-delivery contract must be evaluated together with the instruction executor that sets the delay field.
cpu_inject stores one pending flag and one vector. This is a single pending slot, not a general queue of arbitrarily many interrupts. Repeated injection before consumption can replace the stored vector. A complete device interrupt model needs to specify whether a line remains asserted, whether edges are latched, how priority is represented and when acknowledgment occurs. The presence of a callback accepting a vector is not evidence that those wider interrupt-controller contracts are complete.
The run-loop handling of halt and later invocations is likewise an explicit implementation policy: the next cpu_run call clears the halt flag. Interpreting guest HLT, host pause, shutdown and debugger stop as interchangeable would hide important lifecycle behavior. The exit enumeration gives callers a way to distinguish the modeled reasons, and tests should inspect those values as well as register results.
Guest virtual, guest physical and host storage
A guest virtual address is translated under guest control registers and page-table contents. Its resulting guest physical address is then resolved through the machine memory map. Host storage is the implementation backing for RAM or devices. These three address spaces must not be conflated even if an initial identity map makes two numerical values equal.
chris_translate bypasses paging when the modeled CR0 paging bit is clear. With paging enabled, it checks canonicality and walks four levels using shifts 39, 30, 21 and 12, extracting nine-bit indices. Each entry is read from guest physical memory. The walker checks presence and selected write, user and execute permissions, updates accessed and dirty state through writes, and recognizes large-page leaves at the relevant levels. This describes the code's four-level model, not all optional x86 translation modes or every reserved-bit rule.
chris_va_read and chris_va_write divide an operation into chunks at page boundaries. A request spanning two pages therefore invokes translation for each part. The result can differ across those parts: one page may be writable while the next is absent. The implementation's partial effects and fault delivery must be examined for operations spanning a boundary. The wrapper structure alone does not prove instruction-wide transactional rollback.
Faults, exits and precision
An absent or disallowed guest page should be visible through the guest exception mechanism when the model supports that delivery. An invalid host backing range can instead lead to a machine exit. In the current virtual-read path, noncanonical addresses request a general-protection exception; ordinary translation faults record CR2 and request a page fault; an inaccessible page-table backing can set CHRIS_EXIT_UNMAPPED and halt. The code also treats faults encountered while already delivering an exception specially.
Precise exceptions require the state visible to a handler to match the architectural point at which the fault occurs. Updating a register too early, advancing RIP twice or writing part of an operand before a fault can violate that contract. Some instructions have explicitly defined partial-progress semantics, so a universal “undo everything” rule is not sufficient either. The correct review unit is the particular instruction, its memory accesses and the documented architectural exception behavior.
For that reason, a smoke test reaching HLT proves only its exercised path. It cannot establish correctness of every exception nesting case, privilege transition or cross-page write. The machine source separates exception delivery into its own module, which should be read alongside the executor when auditing these interactions.
Complexity and optimization boundaries
The outer run loop is bounded by the requested step budget, but host work per iteration is not constant across every instruction and machine state. Decoding has a bounded input length. A four-level page walk reads up to four entries per translation, plus possible updates. Repeating translation for each of the 15 eager fetch bytes adds work even when they share a page. String operations, device callbacks, tracing and exception handling contribute different costs.
A decoded-instruction cache could reduce decoding work, but must invalidate when code bytes change. A translation cache must respect guest page-table changes and invalidation semantics. A dynamic translator must preserve flags, memory faults and instruction boundaries even while combining host operations. Optimizations therefore require an invalidation contract and semantic regression tests; they are not safe merely because they produce faster host execution on one guest.
The source's cpu_tlb operation increments a generation field. That is an implementation mechanism at the backend seam. Its presence alone is not proof of a complete translation cache, all invalidation scopes or hardware-equivalent TLB behavior. Documentation should trace actual consumers of any generation value before assigning it a broader capability.
Current virtualization boundary
The chrishv.c backend explicitly reports that hardware assistance is not implemented at this revision. Initialization fails; its run path does not execute a virtual machine. The file reserves an interface for future VMX or SVM integration and does not use KVM. Thus the ecosystem diagram's ChrisHV branch is an architectural intention, whereas ChrisCPU supplies the current interpreter path.
Implementing that branch would require privileged host execution, capability checks, hardware state management, guest entry and exit, interrupt handling, memory virtualization and resource cleanup. A shared structure and backend name solve interface organization, not those mechanisms. The documentation must not turn their existence into a claim that the ChrisOS desktop already boots through a functioning hardware hypervisor.
Evidence and reproducible validation
chrisvm/tests/test_chrisvm.c includes arithmetic flag boundaries, arithmetic execution, memory and call behavior, serial and port operations, invalid instructions, page faults, noncanonical addressing, divide-by-zero and step-limit behavior. The Makefile also builds small arithmetic and splash guests and runs headless checks. These are concrete test definitions in the repository; a report of their execution must additionally state the build result and revision.
| Validation layer | Useful observation | Remaining scope |
|---|---|---|
| Flags helper | Defined result and flag bits for selected operands | Other widths and operations |
| Short guest program | Decode, execute and exit interaction | Unexercised instruction families |
| Page-fault case | Selected exception and CR2 result | All permissions and nested delivery |
| Headless splash | Guest writes reach the modeled framebuffer path | Complete desktop boot and hardware scanout |
| Full operating-system boot | Many subsystem interactions | Exhaustive ISA or timing conformance |
The Intel architecture manuals specify the architectural target. The local source specifies the current implemented subset. Tests provide evidence for exercised behavior. Keeping those three roles separate is necessary for expanding ChrisCPU without either understating its useful implementation or overstating its compatibility.