
TLB shootdown, CPU fencing and safe physical-frame reclamation
About this chapter Concurrency and ownership
In this chapter
- TLB shootdown, CPU fencing and safe physical-frame reclamation
- Scope
- Why a normal lock is not enough
- Current consumer: JIT teardown
- Protocol data model
- Initialization and CPU membership
- Generation publication
- The current range API
- Shootdown serialization
- Why shootdown must not wait while holding mm_lock
- Selecting IPI targets
- LAPIC delivery
- Remote IPI handling
- Polling outside the interrupt path
- Heartbeats
- Wait-state result
- Per-CPU quiet fencing
- Additional forced fencing
- What mm_tlb_retire_mask actually does now
- Cooperative fenced-CPU stop
- NMI support exists but is not the active fence-delivery mechanism
- Reuse safety predicate
- Quarantine
- Quarantine overflow behavior
- Final reuse wait
- Why acknowledgement and halt are separate
- A fenced CPU does not rejoin automatically
- Generation wrap behavior
- Memory ordering model
- IPI send failure handling
- Complexity
- Failure and recovery model
- Validation evidence
- What the host test does not prove
- Locking and deadlock summary
- Current architectural constraints
- Recommended future direction
- Revision boundary
Scope
A TLB shootdown is the coordination protocol used when a translation change on one CPU must become effective on other CPUs before memory can be safely reclaimed.
The key problem is not merely "make every CPU see a new PTE." The difficult case is teardown:
remove mapping
    |
    | stale translations may still exist remotely
    v
prove every relevant CPU can no longer use the old mapping
    |
    v
reuse backing physical memory
ChrisOS implements this as an explicit runtime protocol with:
- generation numbers;
- CPU membership states;
- a published invalidation range;
- local and remote polling;
- LAPIC IPI delivery using vector 0xF0;
- per-CPU acknowledgement;
- heartbeat-based progress detection;
- fencing of CPUs that fail to acknowledge;
- a requirement that fenced CPUs both invalidate and halt before reuse is considered safe;
- physical-frame quarantine when immediate reuse cannot yet be proven safe.
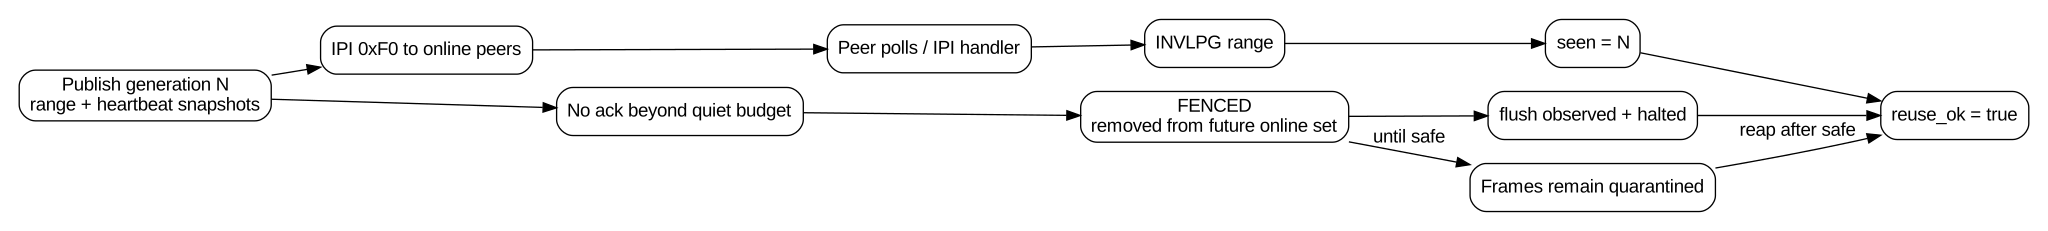
This chapter documents the source as it exists at revision e05a17fd76333114a3fb5c2452f38ca747d4ac56. It intentionally distinguishes implemented behavior from stale comments or unused support code.
Why a normal lock is not enough
mm_lock serializes page-table mutation.
Suppose CPU 0 acquires mm_lock, clears a PTE, releases the lock and returns the physical frame to PMM.
CPU 1 does not need mm_lock to use a cached translation. Its load/store pipeline can continue using a translation already present in processor state.
Therefore:
The lock protects the central data structure. Shootdown protects the lifetime of references derived from that structure.
This is the same conceptual distinction seen in concurrent reclamation generally: removing an object from a shared index does not prove that every execution context has discarded an older reference.
Current consumer: JIT teardown
The most concrete current consumer is jit_free.
The JIT executable alias occupies a shared high kernel virtual range. Its physical storage can have been used by work running on different CPUs.
The teardown sequence is:
- clear each executable PTE with unmap_4k;
- perform local INVLPG for each page as part of unmap_4k;
- call mm_tlb_shootdown_range for the complete virtual span;
- if the shootdown returns success, return the physical frames to PMM;
- if the shootdown cannot yet prove reuse safe, quarantine those frames instead.
The code makes reclamation conditional on synchronization result.
That is the core correctness property.
Protocol data model
tlb_proto.h defines a fixed CPU-capacity model:
and three CPU states:
| State | Meaning |
|---|---|
| TLB_CPU_ABSENT | CPU slot is not a shootdown member |
| TLB_CPU_ONLINE | CPU participates in current/future generations |
| TLB_CPU_FENCED | CPU is removed from future online membership and must satisfy stop conditions before old frames can be reused |
Each TlbCpu stores:
- state;
- seen generation;
- heartbeat counter;
- halted flag;
- flushed flag.
TlbWorld stores:
- the CPU array;
- current generation;
- virtual range base;
- byte count;
- heartbeat snapshots;
- per-CPU quiet counters;
- quiet limit;
- whether a generation has been published;
- reuse_ok.
The protocol therefore separates membership, progress, acknowledgement and reclamation safety.
Initialization and CPU membership
mm_init calls tlb_runtime_init.
That initializes every slot as ABSENT, brings CPU 0 online and marks the runtime ready.
Application processors join later.
In smp.c, after an AP has switched to its assigned stack and completed essential CPU-local setup, ap_c_entry calls:
before entering the permanent job worker.
This means the TLB membership set is not inferred solely from cpu_online_count.
The protocol owns its own per-slot state.
There is a static assertion in mm.c requiring:
so every SMP CPU slot has a corresponding TLB-protocol slot.
Generation publication
tlb_publish is the pure state-machine operation behind tlb_runtime_publish.
Publication performs the following steps:
- write the invalidation virtual address;
- write the byte count;
- execute a compiler barrier;
- increment the generation;
- avoid generation value zero after integer wrap;
- mark a generation as published;
- snapshot every CPU heartbeat;
- reset every quiet counter;
- ensure the initiating CPU is online;
- mark the initiating CPU as already having seen the generation;
- recompute whether physical reuse is safe.
The initiating CPU is considered current because mm_tlb_shootdown_range invalidates the requested local range before publishing the generation.
This ordering is important:
The protocol therefore does not ask the initiating CPU to acknowledge work it has not yet done.
The current range API
mm_tlb_shootdown_range receives:
If MM is ready and bytes is nonzero, it first calls mm_invlpg_span locally.
Then it calls the shared internal shootdown function with the same range.
The initiator performs local invalidation twice in common JIT teardown:
- unmap_4k already executes INVLPG for each page;
- mm_tlb_shootdown_range again executes mm_invlpg_span over the complete range.
That duplication is conservative but has a performance cost.
The current design favors a straightforward proof that the initiating CPU is clean before publishing the generation.
Shootdown serialization
Only one publication protocol should manipulate the single global TlbWorld range/generation payload at a time.
ChrisOS uses:
as a simple shootdown serialization flag.
tlb_shoot_lock acquires it with CAS.
While waiting, the CPU calls mm_tlb_poll and executes PAUSE.
This matters because a CPU waiting to initiate its own shootdown may simultaneously be a required participant in another shootdown.
The wait loop therefore remains responsive to protocol work.
The serialization flag is distinct from mm_lock.
Why shootdown must not wait while holding mm_lock
The source contains an explicit deadlock warning.
The initiator must not hold mm_lock while waiting for remote acknowledgements.
A remote CPU can receive an interrupt or execute a path that itself needs memory-management work.
If CPU 0 held mm_lock and waited for CPU 1 while CPU 1 spun trying to acquire mm_lock before it could reach the required acknowledgement path, the system could deadlock.
The current implementation avoids that structure:
- page-table mutation occurs under mm_lock;
- mm_lock is released;
- the shootdown protocol is serialized separately with mm_tlb_busy;
- remote CPUs can acknowledge without taking mm_lock.
This is a concrete lock-ordering invariant.
Selecting IPI targets
After publication, tlb_runtime_ipi_targets scans all TLB_CPU_CAP slots.
A target is included only when:
- it is not the initiating CPU;
- its state is ONLINE;
- its seen generation differs from the published generation;
- the output target array still has capacity.
The protocol does not assume that online CPUs form a dense numeric prefix.
That matters after fencing.
For example:
A later shootdown must still target CPU 2.
The host test test_hole_is_not_a_prefix validates exactly this condition.
LAPIC delivery
For each selected target, mm_tlb_shootdown_with resolves the CPU index to a LAPIC ID through smp_lapic_of.
If the LAPIC ID is known, the initiator calls:
apic_ipi programs the local APIC ICR and waits for the delivery-status bit to clear, with a bounded spin count.
Its return value is currently ignored by the shootdown caller.
Therefore an IPI send attempt is an acceleration mechanism, not the sole proof of completion.
The protocol still waits on per-CPU generation state.
Remote IPI handling
irq_dispatch recognizes vector 0xF0 before the generic high-vector return path.
The handler:
- calls mm_tlb_poll();
- sends LAPIC EOI;
- returns.
mm_tlb_poll resolves the current CPU index and calls mm_tlb_poll_cpu.
The poll operation:
- asks tlb_runtime_pending whether this CPU has an unseen generation;
- increments the CPU heartbeat;
- if work is pending, calls mm_invlpg_span on the published range;
- acknowledges the generation;
- on CPU 0, attempts to reap quarantined frames.
Thus an acknowledgement is emitted only after the range invalidation operation in that poll path.
Polling outside the interrupt path
The protocol deliberately does not depend exclusively on IPIs.
mm_tlb_poll appears in:
- mm_enter while waiting for the MM lock;
- tlb_shoot_lock while waiting for another shootdown;
- the desktop/window-manager wait loop;
- job workers through mm_tlb_poll_cpu;
- the 0xF0 IPI handler.
AP workers also poll on every job-worker iteration.
This provides several progress opportunities even when interrupt delivery is delayed or a CPU is in a polling path.
It also allows early and transitional states to participate before all interrupt behavior is equally mature.
Heartbeats
Every call to mm_tlb_poll_cpu increments the TLB heartbeat for that CPU.
At publication, the current heartbeat is copied into hb_snap.
tlb_wait_step compares current heartbeat to the snapshot.
If it changed:
- the snapshot is refreshed;
- the CPU quiet counter is reset.
If it did not change:
- the quiet counter increases until saturation.
This distinguishes a CPU that is making observable protocol progress from one that appears silent.
Heartbeat is a liveness signal, not an acknowledgement.
A CPU can keep heartbeating while still failing to acknowledge the current generation.
Wait-state result
tlb_wait_step returns one of three states:
| Return | Meaning |
|---|---|
| 0 | every ONLINE CPU has seen the generation |
| 1 | at least one ONLINE CPU still has not acknowledged |
| 2 | silent non-acknowledging CPUs were fenced and no unfenced ONLINE laggard remains |
The function can return 2 even though reuse is still unsafe.
Why? Because a newly fenced CPU must still prove both:
- flushed = 1;
- halted = 1.
Fencing ends the wait for that CPU as an online participant, but it does not immediately make its stale translation harmless.
This distinction is central to the reclamation model.
Per-CPU quiet fencing
tlb_wait_step can fence a CPU whose quiet counter exceeds quiet_limit.
The runtime initializes:
as the quiet budget.
When a CPU is fenced:
- its state changes from ONLINE to FENCED;
- halted becomes 0;
- flushed becomes 0;
- future target selection ignores it as an online CPU.
The initiator receives a bitmask of newly fenced CPU slots.
mm_tlb_retire_mask handles that mask.
Additional forced fencing
mm_tlb_shootdown_with contains a second progress bound.
The initiator counts its own wait-loop spins.
If the protocol is still returning "waiting" after more than 2,000,000 iterations, it calls:
This fences every other ONLINE CPU that has not acknowledged, regardless of its quiet counter.
The source comment explains the target case: a CPU that continues to heartbeat but never acknowledges could otherwise keep resetting its quiet timer and make the wait effectively unbounded.
The protocol therefore has both:
- per-CPU silence detection;
- a global initiator-side upper bound for non-acknowledging peers.
What mm_tlb_retire_mask actually does now
This is an important reconciliation point.
mm_tlb_retire_mask logs each fenced CPU and calls:
The current smp_retire_cpu implementation decrements cpu_online_count, bounded at a minimum of one.
It does not use the CPU argument to maintain an exact bitmap.
The source comment correctly notes that the TLB protocol's per-slot state, not cpu_online_count, decides future shootdown membership.
More importantly, the active mm_tlb_retire_mask path does not send an NMI.
There is an apic_ipi_nmi implementation and there is an NMI entry path capable of calling mm_tlb_nmi_stop, but no current source call invokes apic_ipi_nmi.
An older header comment says a nonresponsive CPU "receives an NMI." That description is not the behavior of the current active retirement path.
The implemented path is cooperative worker fencing.
Cooperative fenced-CPU stop
job_worker_forever checks:
at the top of every iteration.
When true, the AP worker:
- calls mm_tlb_poll_cpu(cpu_index);
- calls tlb_runtime_mark_halted(cpu_index);
- disables interrupts;
- enters an infinite HLT loop.
The first step is critical.
Because the CPU is fenced but still has not seen the published generation, mm_tlb_poll_cpu performs the published INVLPG range and tlb_runtime_ack marks flushed = 1 for a fenced CPU.
Then mark_halted sets halted = 1.
Only after both become true can reuse_ok become true for that fenced CPU.
The pure host-side helper tlb_cpu_stop models both actions together.
NMI support exists but is not the active fence-delivery mechanism
idt_stubs.asm contains nmi_entry, and mm_tlb_nmi_stop performs:
- mm_tlb_poll_cpu(current_cpu);
- tlb_runtime_mark_halted(current_cpu);
- returns 0 on CPU 0;
- returns nonzero for an AP so the NMI stub can halt it.
apic.c also contains apic_ipi_nmi.
However, the reviewed source has no call from the shootdown path to apic_ipi_nmi.
Therefore the correct current statement is:
- NMI-assisted stop support exists;
- the active fencing path relies on the worker observing its FENCED state;
- documentation must not claim that fencing currently forces an NMI to a stuck CPU.
This has a direct liveness implication: a CPU truly unable to return to its worker loop may remain fenced without reaching halted/flushed state.
Reuse safety predicate
recompute_reuse defines the formal safety predicate.
When a generation is published, reuse is blocked if either condition exists:
- an ONLINE CPU has seen != current generation;
- a FENCED CPU lacks halted or flushed.
In logical form:
ABSENT CPUs impose no requirement.
This predicate is stronger than "all online CPUs acknowledged."
A fenced CPU remains part of the reclamation proof until its stop state is complete.
Quarantine
If mm_tlb_shootdown_range returns -1, the caller cannot prove immediate reuse safe.
jit_free then calls mm_tlb_quarantine.
The quarantine stores physical base/page-count pairs in fixed arrays:
If reuse is already safe, mm_tlb_quarantine frees the frames immediately.
Otherwise it appends them to the quarantine.
Once tlb_runtime_reuse_ok becomes true, mm_tlb_reap returns every quarantined extent to PMM.
CPU 0 calls the reaper from mm_tlb_poll_cpu.
This converts an incomplete coherence proof into delayed reclamation instead of unsafe reuse.
Quarantine overflow behavior
The quarantine has a fixed maximum of 128 extents.
When full, mm_tlb_quarantine prints:
and returns without freeing the incoming frames.
This can leak physical memory, but it avoids the more dangerous alternative of returning possibly stale-reachable frames to PMM.
The failure mode therefore prefers loss of capacity over memory corruption.
That is a reasonable safety direction for the current experimental kernel, but a production design would need bounded recovery or expandable quarantine state.
Final reuse wait
After fencing, mm_tlb_shootdown_with performs an additional bounded loop:
It does not itself poll remote CPUs during this final loop.
If reuse becomes safe, the function returns 0.
Otherwise it returns -1 so the caller can quarantine.
This final bound prevents the initiator from waiting forever for cooperative fenced-CPU shutdown.
Why acknowledgement and halt are separate
The host test test_halt_without_invlpg_blocks_reuse makes the invariant explicit.
A fenced CPU that halts without invalidating still blocks reuse.
Likewise, an acknowledgement alone does not restore a fenced CPU to ONLINE.
Once fenced, that CPU stays fenced.
The test sequence proves:
This is stronger than simply reducing cpu_online_count.
A fenced CPU does not rejoin automatically
tlb_cpu_online changes a CPU to ONLINE only when its state is ABSENT.
A FENCED slot is not converted back to ONLINE by tlb_cpu_online.
The tests verify that a fenced CPU remains fenced after acknowledgement.
There is no current hot-unfence/recovery protocol.
Returning a retired CPU to service would therefore require a new explicit lifecycle design rather than simply invoking the existing online function.
Generation wrap behavior
Generation is a 64-bit counter.
tlb_publish increments it and, if the result wraps to zero, replaces zero with one.
This keeps zero available as the initial "nothing observed yet" value.
The practical wrap interval is enormous, but the code still defines deterministic behavior.
One limitation remains: the protocol does not attach an epoch or otherwise prove correctness if a CPU remained stalled across a full 64-bit wrap. That is not a realistic current runtime concern, but it is the theoretical boundary of the simple equality scheme.
Memory ordering model
The protocol uses volatile fields and a compiler barrier before publishing the new generation.
It does not implement the shared state with C11 atomics or explicit x86 memory-fence instructions.
On x86-64, the hardware memory model is comparatively strong, but compiler ordering and cross-CPU protocol correctness still deserve an explicit proof.
The current host tests validate the state-machine logic, not weak-memory execution on real SMP hardware.
This should be treated as a current validation limitation rather than assuming the volatile model constitutes a complete formal memory-order specification.
IPI send failure handling
apic_ipi returns -1 if:
- LAPIC is unavailable;
- delivery-status polling does not clear within its limit.
mm_tlb_shootdown_with currently ignores this return value.
Safety does not immediately depend on successful return from apic_ipi because completion is still measured through seen generations and fencing.
However, ignoring the error removes useful diagnostic distinction between:
- IPI delivered but remote CPU slow;
- LAPIC route unavailable;
- IPI request failed locally.
A future implementation could record those outcomes separately while preserving the same reuse proof.
Complexity
Let:
- C = TLB_CPU_CAP;
- P = number of pages in the invalidation range;
- Q = number of quarantined extents.
The main costs are:
| Operation | Complexity |
|---|---|
| publish heartbeat snapshots | O(C) |
| select IPI targets | O(C) |
| one wait-step scan | O(C) |
| local/remote range invalidation | O(P) per participating CPU |
| retire a fenced mask | O(C) |
| recompute reuse predicate | O(C) |
| reap quarantine | O(Q) |
C is currently fixed at 16 and Q at 128.
The protocol is therefore intentionally bounded and simple rather than optimized for large CPU counts.
Failure and recovery model
The current system handles several classes of failure explicitly.
Remote CPU acknowledges normally
The peer invalidates the range, updates seen and the generation completes.
CPU is silent
After the quiet budget it can be fenced.
The worker must later invalidate and halt before reuse becomes safe.
CPU remains active but never acknowledges
The initiator-side spin bound can force fencing even if heartbeats continue.
Fenced CPU does not reach worker halt
The final reuse wait expires.
The shootdown returns failure and physical frames are quarantined.
Quarantine fills
New unresolved extents are not freed, preventing unsafe reuse at the cost of a leak.
This is a fail-safe bias toward preserving memory correctness.
Validation evidence
tools/test_tlb_proto.c contains focused host tests for the pure protocol state.
All CPUs acknowledge
test_all_ack verifies:
- reuse is blocked before remote acknowledgement;
- all peers can acknowledge;
- the wait terminates with no fencing;
- all CPUs remain online;
- reuse becomes allowed.
Silent CPU fencing
test_silent_cpu_is_fenced verifies:
- a silent peer becomes FENCED;
- online count in the protocol excludes it;
- fencing alone does not permit reuse;
- acknowledgement alone does not unfence it;
- reuse is allowed after the fenced CPU both invalidates and is marked halted.
Membership holes
test_hole_is_not_a_prefix proves later shootdowns still include a high-numbered online CPU after a lower-numbered CPU was fenced.
Halt without flush
test_halt_without_invlpg_blocks_reuse proves halted is not enough without flushed.
Heartbeat progress
test_heartbeat_resets_quiet proves a moving heartbeat prevents the per-CPU silent timer from fencing a live peer prematurely.
These tests are valuable because they exercise protocol invariants separately from LAPIC and real TLB hardware.
What the host test does not prove
The host test does not validate:
- real INVLPG execution on all cores;
- LAPIC delivery;
- interrupt-disabled edge cases;
- compiler/CPU memory-order races;
- a CPU stuck forever outside the worker loop;
- simultaneous real shootdown initiators beyond the modeled serialization;
- quarantine under sustained runtime pressure;
- interaction with CPU hotplug;
- process address-space migration.
Those require runtime SMP testing or stronger formal reasoning.
Locking and deadlock summary
The important current lock/liveness relationships are:
mm_lock
  protects page-table mutation
  must not be held while waiting for remote shootdown ack

mm_tlb_busy
  serializes the one global published generation/range
  waiters poll TLB work while spinning

job queue lock
  unrelated to shootdown state
  workers poll TLB before ordinary job execution
This separation prevents the most obvious circular wait between page-table mutation and acknowledgement.
Current architectural constraints
The protocol is tailored to the current system:
- fixed maximum of 16 TLB CPU slots;
- global generation/range, not per address space;
- 4 KiB range invalidation using repeated INVLPG;
- shared kernel mapping reclamation as the main SMP use case;
- user processes remain BSP-only;
- fenced CPUs are not automatically recovered;
- one global quarantine;
- one global shootdown publication at a time.
These constraints make the state machine understandable, but they are not a general solution for a large SMP production kernel.
Recommended future direction
A future revision could improve the design by introducing:
- explicit atomic memory-order semantics;
- exact online/retired CPU bitmaps in SMP rather than count-only retirement;
- explicit IPI error telemetry;
- a reliable forced-stop path for CPUs that cannot return to workers;
- per-address-space residency masks;
- batched or context-wide invalidation heuristics;
- PCID/INVPCID-aware invalidation;
- scalable reclamation queues;
- dedicated runtime stress tests with fault injection;
- a defined CPU recovery/hotplug state after fencing.
These are roadmap items. They are not current behavior.
Revision boundary
This chapter was reconciled against ChrisOS main revision e05a17fd76333114a3fb5c2452f38ca747d4ac56.
The current source-backed contract is:
- local range invalidation occurs before generation publication;
- ONLINE peers must acknowledge the same generation;
- IPIs accelerate polling but acknowledgement state is authoritative;
- silent or persistently unacknowledging CPUs can become FENCED;
- the active retirement path is cooperative worker fencing, not an NMI send;
- a fenced CPU must both invalidate and halt before reuse becomes safe;
- unresolved physical frames are quarantined rather than unsafely recycled.
Any future change to the worker lifecycle, NMI usage, SMP membership, PCID policy or memory-order implementation requires this chapter to be reconciled again.