
ChrisFS architecture: layout, allocation, journaling and validation
About this chapter ChrisFS structures and recovery
In this chapter
- ChrisFS architecture: layout, allocation, journaling and validation
- Scope
- Layer position
- Core in-memory object
- On-disk high-level layout
- Dynamic v5 geometry
- Superblock as persistent ABI
- Format versions
- Formatting a volume
- Inode table
- Inode integrity
- Data-block addressing
- An important file-size API asymmetry
- Whole-file write path
- Incremental write path
- Truncate implementation
- Free-space bitmap
- Allocation rollback
- Pointer-block lifetime
- Directory representation
- Directory capacity
- Path syntax
- Path traversal
- Object operations
- Rename semantics
- Permissions
- Modification time
- Sector cache
- Cache coherence inside ChrisFS
- Read-ahead
- Filesystem lock
- Concurrency consequences
- Journal structure
- Journal begin
- Journal logging
- Data-vs-metadata switch
- Commit ordering
- Replay behavior
- Why BEGIN-drop is not full rollback
- Clean flag and fsck
- fsck architecture
- fsck limits
- Error model
- Mount validation
- Persistence boundary
- Validation evidence
- Performance profile
- Security and integrity boundaries
- Current limitations
- Roadmap boundary
- Source map and revision note
Scope
ChrisFS is the native filesystem used by ChrisOS for persistent system trees, installed images and ordinary file/directory operations. It sits directly on the project's generic BlockDevice abstraction and currently assumes 512-byte sectors.
The implementation combines several concerns in one compact filesystem:
- versioned on-disk geometry;
- a bitmap allocator;
- fixed-size inodes;
- direct and multi-level indirect block addressing;
- fixed-size directory entries;
- pathname parsing and traversal;
- a small read cache;
- a metadata-oriented journal mechanism;
- permission bits;
- a global reentrant filesystem lock;
- an offline-style consistency checker callable at runtime.
This chapter is the architectural overview. The later ChrisFS chapters split these mechanisms into their detailed on-disk and algorithmic contracts.
Current behavior was reconciled against ChrisOS revision e05a17fd76333114a3fb5c2452f38ca747d4ac56.
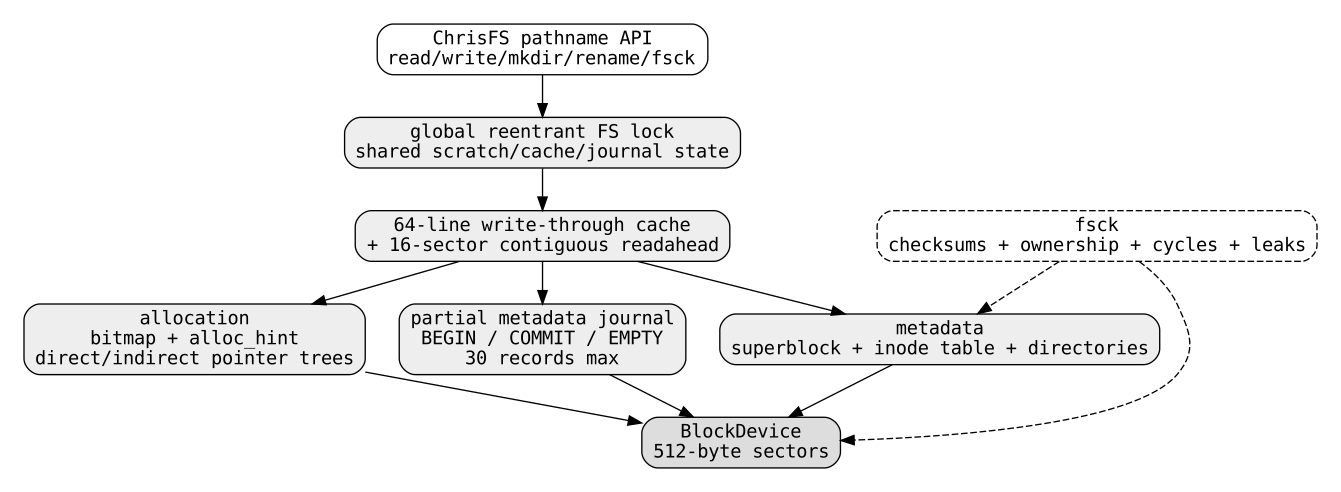
Layer position
ChrisFS does not talk to ATA, AHCI, NVMe, VirtIO Block or USB directly.
Its I/O boundary is:
A GPT-installed system normally exposes ChrisFS through a PartView. Older images may place ChrisFS directly at LBA 0 of a whole disk.
At mount time the filesystem therefore sees only a logical 512-byte-sector block device and a sector count.
Core in-memory object
The mounted state is represented by Cfs.
Important fields are:
dev             backing BlockDevice
super           decoded superblock
cache[64]       sector cache lines
sector[512]     shared scratch sector
clock           cache age counter
cache_hits
cache_misses
mounted
jnl             journal transaction state
jnl_active
jnl_data
alloc_hint      next preferred allocation index
This object is deliberately small enough to remain understandable, but several fields are shared scratch state. That is why filesystem-level serialization is part of the correctness model rather than merely a performance choice.
On-disk high-level layout
A current v5 volume is logically:
LBA 0                    superblock
bitmap region            free/used data-block map
inode region             2048 fixed-size inodes
journal region           64 sectors
data region              file, directory and pointer blocks
Unlike older fixed-layout versions, v5 computes bitmap size from the backing device's sector count.
The inode region and journal size remain fixed.
Legacy geometry
Versions 3 and 4 are accepted with the historical 512-MiB geometry:
sector size          512
total sectors        1,048,576
bitmap start         1
bitmap sectors       256
inode start          257
inode sectors        512
journal start        769
journal sectors      64
data start           833
A 512-MiB v5 volume naturally resolves to the same data-start LBA, preserving layout compatibility while allowing larger v5 block devices to receive a larger bitmap.
Dynamic v5 geometry
cfs_geom_for_count computes the bitmap iteratively.
Each bitmap sector describes:
The algorithm reserves:
- one superblock sector;
- 512 inode sectors;
- 64 journal sectors;
- enough bitmap sectors to cover the remaining data region.
It iterates until the chosen bitmap can describe all resulting data sectors.
The invariant checked afterward is:
with bitmap capacity at least equal to data_sectors.
This keeps v5 geometry derived from the real block-device capacity instead of silently truncating every filesystem to the old 512-MiB layout.
Superblock as persistent ABI
CfsSuper stores:
- format version;
- generation;
- clean flag;
- total sectors;
- bitmap LBA/count;
- inode LBA/count;
- journal LBA/count;
- data LBA/count.
The encoder does not dump a C struct directly. It writes defined little-endian offsets into a 512-byte sector.
The sector contains:
magic
version
sector size
geometry fields
root inode id
clean flag
generation
journal geometry
checksum
The checksum is the project's FNV-1a-like 32-bit checksum over the first 60 bytes.
The decoder validates magic, supported version, sector size, checksum and geometry before later code trusts the stored ranges.
That is a security and reliability boundary: unvalidated metadata-derived LBAs would otherwise become arbitrary reads or writes through the block device.
Format versions
Current constants define:
v3/v4 decoding requires the exact legacy geometry.
v5 stores and validates dynamic geometry.
The explicit encode/decode layer is important because a filesystem is a persistent ABI. Changing CfsSuper or CfsInode in memory must not accidentally redefine old disks through compiler padding or field alignment.
Formatting a volume
cfs_format requires:
- a non-null block device;
- 512-byte sectors;
- writable media;
- geometry that can be represented by v5.
The format path:
- computes v5 geometry;
- zeroes every metadata sector from LBA 0 up to the data region;
- marks data-block index 0 allocated in the bitmap;
- initializes all inode slots as free;
- creates root inode 0 as a directory;
- points root's first direct block at the first data LBA;
- zeroes that first root-directory block;
- writes the encoded superblock;
- initializes the journal header as empty;
- calls
bd_flush.
The root inode therefore consumes the first data block from the beginning.
Inode table
The inode size is:
and the filesystem contains:
Four inodes fit in one 512-byte sector.
Inode 0 is reserved for root. Allocation scans inode IDs starting at 1.
A CfsInode includes:
- type;
- flags;
- file size;
- generation;
- 12 direct block pointers;
- one indirect pointer;
- one double-indirect pointer;
- one triple-indirect pointer;
- uid/gid;
- permission mode;
- 64-bit modification time split into high/low words;
- checksum in the encoded representation.
Free inodes have type zero.
Inode integrity
Each encoded inode has a checksum over its first 124 bytes, stored in the final four bytes.
inode_read refuses an inode when the checksum does not match and surfaces filesystem corruption.
Because four inodes share a sector, inode updates follow a read-modify-write pattern through the cache.
Data-block addressing
A 512-byte pointer block holds:
The addressing tree is:
The lower three levels before triple indirection cover:
Including triple indirection, the address tree can describe 2,113,676 blocks, about 1.008 GiB, although actual file size is additionally constrained by the backing volume and by which public API is used.
An important file-size API asymmetry
The current APIs do not all expose the same maximum.
cfs_write and cfs_truncate enforce:
which corresponds to direct + indirect + double-indirect addressing.
However, file_lba implements triple-indirect traversal, while cfs_write_at and cfs_read_at check against:
Here CFS_DATA_SECTORS is the legacy compile-time geometry constant, not the mounted v5 fs->super.data_sectors. Incremental I/O can therefore exercise triple indirection, but a larger v5 filesystem does not raise this API ceiling.
This is current behavior, not a unified design guarantee. The API limits should eventually be derived from one mounted-volume contract.
Whole-file write path
cfs_write is a replace-style whole-file operation.
If the file does not exist, it first creates it.
The algorithm then:
- loads the inode;
- calculates old and new block counts;
- begins a journal transaction;
- allocates/resolves each required file block;
- writes every new data sector;
- frees excess old data blocks when shrinking;
- prunes now-unused pointer structures;
- updates size, mtime and inode generation;
- writes the inode;
- increments filesystem generation;
- commits the journal.
The data path zero-fills the last partial sector before copying user bytes.
Incremental write path
cfs_write_at updates a byte range.
It can create a missing file, extend file size and perform read-modify-write on partial sectors.
For every touched block it:
- resolves or allocates the file LBA;
- reads the sector;
- patches only the target byte range;
- writes the sector.
After data changes, it updates the inode and commits the journal transaction.
There is no valid sparse-hole representation. A distant extension is especially problematic: cfs_write_at raises inode size to offset + size but allocates only the blocks actually touched by the write. Full blocks skipped between the old EOF and the new offset can remain unallocated, so later sequential reads may return CFS_ECORRUPT and fsck may report size vs blocks. Callers should currently avoid extending across unallocated block gaps.
Truncate implementation
cfs_truncate is intentionally simple but expensive.
It allocates a work buffer of:
reads the entire file into that buffer, zero-fills any newly extended region, then calls cfs_write for the final size.
Consequences include:
- up to about 8.07 MiB of temporary memory;
- O(file size) copying even for small truncation changes;
- no support for truncating files beyond the whole-file
cfs_writelimit even if they were grown bycfs_write_at.
This is a functional implementation, not a scalable truncate algorithm.
Free-space bitmap
Every data block corresponds to one bitmap bit.
bitmap_get and bitmap_set translate a data-block index into:
Allocation uses a first-fit-style scan starting from alloc_hint.
Without the hint, repeated allocation would restart at bit zero, producing increasingly expensive scans during large installs.
With the hint, sequential allocations usually continue near the last successful position.
Worst-case allocation is still:
when space is heavily occupied or fragmented.
Allocation rollback
When block_alloc finds a free bit it:
- marks the bit used;
- zeroes the corresponding data block;
- if zeroing fails, clears the bit again;
- advances
alloc_hint.
This handles one local failure window, but allocation is not a globally transactional operation across every metadata structure involved in a larger filesystem mutation.
Pointer-block lifetime
Pointer blocks themselves come from the same data-block allocator.
When files shrink or are deleted, ChrisFS frees:
- data blocks;
- indirect blocks;
- second-level blocks;
- triple-indirect tree blocks.
The implementation has explicit pruning/free helpers because freeing only data leaves but retaining pointer blocks would leak bitmap space.
Directory representation
A directory is an inode whose data blocks contain fixed-size CfsDirent records.
Each dirent is:
and contains:
- inode number;
- type;
- name length;
- flags;
- 64 bytes of name storage.
Only:
entries fit in one sector; 32 bytes per directory sector remain unused.
Directory names are byte strings and matching is case-sensitive.
The tests explicitly verify that foo and Foo are separate names.
Directory capacity
Directories intentionally use only:
rather than the full double/triple-indirect file tree.
At six dirents per block, the structural ceiling is approximately:
assuming enough free inodes and blocks.
Deleted entries become reusable empty slots.
Directory inode size is updated in 80-byte logical increments, but lookup/listing scans the supported directory block range rather than using size as the sole authority.
Path syntax
The parser accepts either relative-looking paths such as:
or a single leading slash:
Important limits are:
The parser rejects:
- empty interior components;
- trailing slash after a non-root path;
- backslashes;
.;..;- components longer than 64 bytes;
- more than 32 components.
There is no current working-directory semantics inside ChrisFS itself; traversal starts at root.
Path traversal
walk_parent resolves every component except the final leaf.
walk_full resolves the complete path.
Every intermediate object must be a directory and must pass the WALK permission check.
Directory lookup is linear over directory blocks and entries.
For a path with depth d and directories containing n entries, lookup is therefore broadly O(d × n) in the simple case, not indexed by hash or tree.
Object operations
The public API currently includes:
- create;
- mkdir;
- rmdir;
- unlink;
- rename;
- stat;
- read;
- read_at;
- write;
- write_at;
- truncate;
- list;
- list_at;
- chmod;
- permission check;
- mtime query;
- sync;
- fsck.
There are no symlinks, hard links, device nodes, sockets, extended attributes or open-file handles in the ChrisFS layer itself.
Operations are mostly pathname based.
Rename semantics
cfs_rename:
- resolves old and new parents;
- checks both parent write permissions;
- rejects destination name collisions;
- adds a new dirent pointing to the same inode;
- removes the old dirent.
It can rename across directories inside the same filesystem.
There is no separate cross-filesystem object here, so CFS_EXDEV exists in the error enum but this function operates within one Cfs instance.
A significant current limitation is that rename does not wrap the add/remove sequence in the journal transaction helpers. Failure between the two directory operations can therefore leave a partial rename state. There is also no descendant/ancestor check: moving a directory into one of its own descendants can create a directory cycle.
Permissions
ChrisFS defines four permission bits:
New inodes are initialized with all four.
The current policy is not a Unix multi-user permission model.
cfs_perm_need rejects any inode with:
and otherwise checks the effective permission bitmask.
So uid/gid exist in the format, but the implemented runtime semantics effectively support root-owned objects with a simple mode mask.
chmod stores the low four bits into both mode and legacy-compatible flags.
Modification time
Each inode stores a 64-bit modification time as two 32-bit fields.
ChrisFS maintains a global logical clock.
cfs_set_now can seed the clock from an external time source, while modifications increment it before storing mtime.
This is not itself a persistent wall-clock service; it is an inode timestamp mechanism driven by the caller/kernel environment.
Sector cache
Each mounted Cfs owns:
plus tag/age metadata.
The cache is read-through and write-through.
A hit updates an age counter. On a miss, the victim is either an invalid line or the line with the smallest age, making replacement approximately LRU.
Writes go to the block device immediately and then refresh a cache line.
There are no dirty cache lines requiring later writeback.
Cache coherence inside ChrisFS
Before installing a new cached value for an LBA, the implementation invalidates duplicate lines for that LBA.
Direct multi-sector readahead also drops corresponding cached sectors to avoid stale duplicates after bypassing the single-sector cache.
The global filesystem lock protects the shared scratch sector, cache metadata and readahead buffer.
Read-ahead
For aligned file reads, cfs_read_at detects physically contiguous file blocks.
It reads up to:
in one underlying bd_read.
That is up to 8192 bytes per contiguous run.
Fragmented or unaligned reads fall back to individual cached sector reads.
This optimization depends on physical block adjacency; logical file adjacency alone is not sufficient.
Filesystem lock
All major public ChrisFS operations enter the global g_cfs_lock.
The lock stores:
- locked flag;
- owner ID;
- reentrancy depth.
Kernel owner identity is:
so a call chain on the same CPU can re-enter the filesystem lock.
The header explicitly states that the lock must not be taken from interrupt handlers.
Waiters spin using pause with interrupts left enabled.
Despite a source comment calling it a “yielding lock,” there is no scheduler yield in the current primitive; it is a reentrant spin-style wait that avoids disabling interrupts.
Concurrency consequences
The global lock makes high-level filesystem operations serialized across CPUs.
This protects:
fs->sectorshared scratch data;- cache lines;
- journal transaction state;
alloc_hint;- global readahead buffer;
- filesystem metadata mutations.
The trade-off is no parallel ChrisFS I/O even when two requests target independent files.
The host test_cfs_lock runs concurrent writer/reader threads and checks that reads are not torn and the final filesystem passes fsck.
Journal structure
The journal region is 64 sectors.
The journal header contains:
States are:
Each record consumes two sectors:
- metadata sector containing target LBA and checksum;
- full 512-byte payload sector.
The in-memory maximum is:
which fits within the fixed journal region together with its header.
Journal begin
jnl_begin:
- binds the transaction to the mounted filesystem;
- uses current filesystem generation as sequence;
- sets record count to zero;
- marks the superblock
clean = 0; - writes that superblock directly;
- writes a BEGIN journal header.
The return value from writing the dirty superblock is currently ignored; the BEGIN-header write determines the function result.
That is a real error-propagation gap.
Journal logging
When journaling is active and jnl_data == 0, cache_write first calls jnl_log.
jnl_log writes:
- destination LBA;
- payload checksum;
- payload sector.
After the log record succeeds, cache_write still immediately writes the same sector to its home LBA.
This ordering is important to understand: the current mechanism is not a classic design where all home metadata waits until a durable commit record.
Data-vs-metadata switch
jnl_data suppresses journal logging.
For cfs_write and cfs_write_at, it is set to 1 while file data and allocation/pointer changes are performed, then set to 0 for the final inode write.
Consequently, during those operations the current journal does not capture every changed structure.
Bitmap and pointer updates that happen while jnl_data == 1 are also outside the journal, not only user payload sectors.
Other operations such as mkdir and unlink enable metadata logging differently.
Some mutating operations, notably cfs_create, cfs_rmdir and cfs_rename, do not consistently wrap all changes in jnl_begin/jnl_commit.
The journal must therefore be described as partial recovery infrastructure, not as universal filesystem transaction atomicity.
Commit ordering
jnl_commit currently performs:
There is no bd_flush between these states.
Because cache_write_raw is write-through but not a durability barrier, storage devices that reorder or buffer writes can expose ordering weaker than the logical source sequence.
A robust transactional journal would require explicit persistence ordering and a clearly defined home-write protocol.
Replay behavior
At mount:
- the journal header is inspected;
jnl_replayvalidates magic/header checksum;- EMPTY means no action;
- BEGIN is treated as uncommitted and the journal is cleared;
- COMMIT replays each valid record to its target LBA;
- the journal is rewritten EMPTY.
Each replay record verifies the payload checksum before applying it.
If the header state is invalid, or a record checksum fails, mount reports corruption/I/O failure instead of silently continuing.
Why BEGIN-drop is not full rollback
The host journal test proves that a record explicitly logged but never committed is dropped on remount.
However, ordinary cache_write writes a journal record and then also writes the home block before transaction commit.
Therefore a crash in BEGIN state may leave some home-location changes already present even though replay discards the log.
There is no undo log to restore old contents.
The journal test does not currently model this ordinary home-write-before-commit crash window.
This is one of the most important current recovery limitations.
Clean flag and fsck
Transactions mark the in-memory/superblock clean flag false at begin and true at successful commit.
During system storage initialization, a mounted filesystem whose superblock is marked clean can skip the expensive fsck path.
An unclean filesystem is checked.
Because journal replay does not blindly convert every prior dirty state into a clean superblock, fsck remains a second line of validation after interrupted operations.
fsck architecture
cfs_fsck validates cross-structure invariants rather than merely checking local checksums.
It examines:
- superblock decode/checksum;
- journal state;
- bitmap contents;
- every inode;
- inode type and checksum;
- file size versus referenced blocks;
- direct/indirect pointer trees;
- duplicate/invalid data-block ownership;
- root inode type;
- directory entries;
- directory cycles;
- inode references;
- leaked bitmap allocations.
It builds “seen” allocation state and compares that against the on-disk bitmap.
The directory-graph portion is less complete than the block-ownership portion: it currently inspects only the 12 direct directory blocks, not the single-indirect directory range; duplicate-name tracking resets per directory block; and allocated inode reachability from root is not enforced.
File-size validation is also asymmetric: direct pointers are checked against EOF strictly, while required occupancy of single/double/triple trees is not derived exactly from inode size. Extra indirect blocks beyond EOF can therefore remain accepted as owned blocks. The checker also does not treat super.clean == 0 as an error by itself.
For larger v5 bitmaps it can allocate checker working maps dynamically instead of relying only on the legacy fixed-size arrays.
fsck limits
The checker is primarily a validator.
It reports a reason string and error count/status; it is not a general automatic repair engine.
Examples of reported reasons include:
super checksum
journal dirty
journal pending replay
inode checksum
inode type
size vs blocks
dir cycle
bitmap leak
A production-grade filesystem repair tool would require explicit repair policies and conflict resolution, which ChrisFS does not currently provide.
Error model
ChrisFS has its own error space, including:
CFS_EINVAL
CFS_EIO
CFS_EFORMAT
CFS_ENOENT
CFS_EEXIST
CFS_ENOSPC
CFS_EFBIG
CFS_ENAMETOOLONG
CFS_ECORRUPT
CFS_ENOTMOUNTED
CFS_ENOTDIR
CFS_ENOTEMPTY
CFS_EISDIR
CFS_EXDEV
CFS_EPERM
Underlying block-device failures are generally collapsed to CFS_EIO.
That keeps the filesystem API simple but loses distinctions such as timeout versus media error unless they are logged below the filesystem layer.
Mount validation
cfs_mount rejects:
- null filesystem/device;
- non-512-byte sectors;
- zero-size block device;
- unreadable superblock;
- unsupported/corrupt superblock;
- backing device smaller than the volume declared by the superblock;
- unrecoverable journal corruption;
- invalid root inode or root type.
It resets cache state, runs journal replay, then confirms that inode 0 is a directory.
The backing device may be larger than the filesystem's recorded total sector count.
Persistence boundary
cfs_sync currently calls only:
The effectiveness of sync therefore depends entirely on the block backend.
Several current ChrisOS block drivers register no flush callback, and the generic bd_flush treats a missing callback as success.
Thus ChrisFS can request a persistence boundary, but many current devices do not yet implement a real hardware cache flush.
This also limits the durability guarantees that journaling can provide.
Validation evidence
ChrisFS has broader host-side coverage than most individual storage drivers.
Relevant tests include:
test_cfs_host
Covers:
- format/mount;
- reboot persistence;
- cached reads;
- injected I/O failures;
- unknown superblock protection;
- whole-file maximum size;
- name-length limits;
- large directory/file populations.
test_cfs_paths
Covers:
- nested directories;
- case-sensitive names;
- listing;
- same-directory and cross-directory rename;
- unlink/rmdir;
.and..rejection;- path-depth limit;
- remount persistence;
- fsck.
test_cfs_journal
Covers:
- legacy geometry expectations;
- BEGIN record dropped on remount;
- forced COMMIT replay;
- dirty-journal fsck detection.
test_cfs_lock
Uses two host threads to exercise concurrent read/write serialization and verifies that no torn file contents appear.
test_cfs_maxwrite
Verifies the exact whole-file CFS_MAX_FILE_SIZE boundary.
test_cfs_v5
Verifies:
- v4 compatibility;
- dynamic v5 geometry;
- allocation beyond the historical 512-MiB boundary.
Additional indirect-pointer and fsck tests cover deeper block trees and corruption detection.
Performance profile
ChrisFS favors transparency over sophisticated data structures.
Costs include:
- linear inode allocation scan;
- bitmap allocation scan;
- linear directory lookup;
- a global filesystem lock;
- write-through cache;
- pathname-based APIs with repeated traversal;
- full-file buffering in truncate.
Useful optimizations already present include:
- allocation hint;
- 64-line metadata/data cache;
- 16-sector contiguous read-ahead;
- reusable fixed-size metadata formats;
- multi-level block pointers.
The current design is appropriate for an experimental operating-system filesystem, but scaling to large volumes, many files or high I/O concurrency would require additional indexing and finer-grained synchronization.
Security and integrity boundaries
Important defenses include:
- explicit little-endian decoders;
- superblock checksum and geometry validation;
- inode checksum validation;
- path/component/depth limits;
- rejection of
.,..and backslashes; - block-range checks;
- dirent inode-range checks;
- fsck ownership/cycle checks;
- global serialization.
Current gaps include:
- no cryptographic integrity;
- no authentication;
- no per-user credential model beyond the simple uid/mode check;
- no ACL lists;
- no immutable/read-only mount mode;
- incomplete crash atomicity;
- limited underlying flush guarantees;
- no online repair;
- no quota system.
Current limitations
At the documented revision, ChrisFS still has these architectural limits:
- 512-byte sectors only;
- 32-bit block/LBA accounting;
- 2048 fixed inode slots;
- linear inode allocation;
- bitmap allocator with linear worst case;
- directory lookup without indexing;
- approximately 840 entries per directory under the current directory block policy;
- no symlinks or hard links;
- no sparse files;
- no file handles at this layer;
- global filesystem serialization;
- write-through cache only;
- partial rather than fully atomic journaling;
- no flush barriers inside journal state transitions;
- several mutating operations not uniformly journaled;
cfs_write/truncatemaximum differs from the capacity reachable throughwrite_at;- memory-heavy truncate;
- simple root-owned permission model;
- fsck validates but does not generally repair;
- no robust recovery guarantee when the backing block driver lacks real flush support.
Roadmap boundary
A stronger future ChrisFS would benefit from:
- a unified file-size contract;
- 64-bit block addressing;
- scalable inode allocation;
- indexed directories;
- sparse extents or extent trees;
- a journal with explicit durability barriers and complete transaction coverage;
- consistent journaling of rename/create/rmdir and allocation metadata;
- flush propagation through partition views and hardware backends;
- finer-grained locking;
- writeback policy with explicit dirty-state ownership;
- online/offline repair tooling;
- stronger user/permission semantics;
- fuzzing of crash points and corrupted metadata.
Those are roadmap items until they exist in source and reproducible tests.
Source map and revision note
kernel/fs/cfs_format.h defines the persistent superblock, inode and dirent encodings and geometry rules. kernel/fs/cfs.c implements mount, allocation, block mapping, paths, directories, cache, journaling and public file operations. kernel/fs/cfs_fsck.c implements consistency validation. kernel/fs/fs_lock.h defines filesystem serialization. kernel/fs/storage.c integrates mounting and conditional fsck into boot storage discovery. tools/test_cfs_*.c provide host-side behavioral evidence.
All current-behavior claims in this chapter were reconciled against ChrisOS revision e05a17fd76333114a3fb5c2452f38ca747d4ac56.