
Kernel model, protection domains and trust boundaries
About this chapter Trust boundaries and exception entry
In this chapter
- Kernel model, protection domains and trust boundaries
- Scope
- Classification must describe protection, not directory layout
- What monolithic means here
- What modular means here
- Monolithic versus microkernel
- Monolithic versus hybrid
- Protection domain
- Ring 0
- Ring 3
- CPL
- User page permission
- Kernel high-half mapping
- Mapping is part of the security boundary
- Native ELF user range
- Native entry path
- System-call boundary
- Current native syscall set
- User pointers are hostile inputs
- Ring transition does not sanitize arguments
- Syscall ownership
- Process failure containment
- Kernel failure behavior
- Failure-domain consequence
- CLVM is a separate execution model
- CLVM guest address is not native virtual address
- CLVM syscall boundary
- Software sandbox consequence
- CLVM capability checks
- Hardware gate
- Hardware capability versus hardware isolation
- DMA bypasses CPU page checks
- DMA ownership
- Trusted Computing Base
- TCB is not equivalent to kernel size
- Internal API boundary
- Device abstraction boundary
- Why modular monolith is still valuable
- Kernel build as evidence
- Static linking and privileged reachability
- Kernel initialization graph
- Kernel/user split
- CLVM split
- Two application boundaries coexist
- Kernel jobs
- Kernel threads
- Stack separation is not address-space separation
- SMP architecture
- Why BSP-only user scheduling matters
- SMP does not imply multi-core userspace
- Shared kernel mappings
- TLB as a safety problem
- Fenced CPUs
- Interrupts are asynchronous kernel entry
- Lock order
- Recursive PMM rule
- Filesystem lock differs
- Network residual race
- Audio IRQ synchronization
- Mechanism versus policy
- Resource ownership is architecture
- Process-owned memory
- JIT ownership
- Device-owned resources
- Boot resources
- Failure domains
- Panic policy
- Why microkernel-style restart is not currently available
- Hardware root of trust boundaries
- User-access bit
- W^X
- Executable validation
- Parser code belongs to the TCB
- Filesystem is privileged
- Network parsing is privileged
- Graphics is privileged
- Window manager is privileged
- Compiler/toolchain code is privileged in the current image
- Self-hosting and privilege are separate goals
- Kernel tools are also linked in
- Experimental architecture and explicit boundaries
- Architecture quality is not determined by one taxonomy label
- Current dependency direction
- Core versus policy-heavy code
- Authority inventory
- API surface and authority surface differ
- Native process CR3 ownership
- Kernel thread address space
- Context versus domain
- Scheduler ownership
- What would change for multi-core userspace
- What would make ChrisOS more microkernel-like
- What would make ChrisOS more hybrid-like
- Why no forced redesign is required
- Observability as part of kernel architecture
- Build identity and reproducibility
- Host tests versus privileged integration
- Validation ladder
- Stubs must remain visible as stubs
- Trust-boundary table
- Privilege-minimization roadmap
- Driver isolation is particularly difficult
- CLVM as an intermediate isolation laboratory
- Native ring-3 path as stronger hardware isolation
- User-copy maturity
- Resource handles instead of raw authority
- Global state is the main modular-monolith pressure point
- Current process table
- Current job queue
- Current filesystem state
- Current network state
- Current graphics state
- Current window manager
- Current compiler integration
- Why source atlas matters
- AI maintenance and architectural contracts
- Reproducible checker
- Current architecture summary
- What ChrisOS is not currently
- What ChrisOS already has that supports future evolution
- Architecture evolution should preserve facts
- Validation boundary
- Review triggers
- Primary references
Scope
The word kernel describes privileged system software, but it does not by itself specify an architecture.
Two systems can both use ring 0, virtual memory, processes and device drivers while having radically different trust boundaries.
The relevant questions are:
- which components execute with supervisor privilege;
- which components share one address space;
- which calls cross a hardware protection boundary;
- which calls are merely internal APIs;
- which resources a component can directly corrupt;
- which failures can be contained;
- which state is global;
- which CPUs may mutate it;
- which actors can access physical memory without CPU page checks.
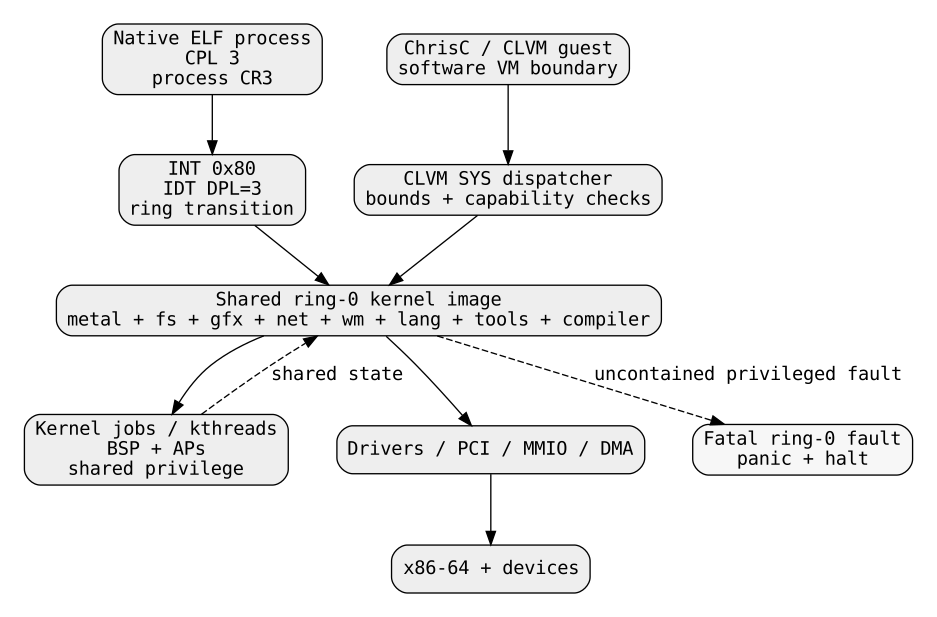
At the reviewed revision, ChrisOS is best described as a modular monolithic x86-64 kernel with two application execution models:
- native ring-3 ELF processes protected by x86 privilege levels and page tables;
- ChrisC/CLVM programs executed through a software virtual-machine boundary and kernel service dispatcher.
Most operating-system services, drivers, graphics, storage, networking, desktop code, language-runtime integration and a substantial part of the compiler/toolchain are linked into the same privileged kernel ELF.
Source modularity is extensive.
Hardware fault isolation between those kernel modules is not.
Classification must describe protection, not directory layout
A source tree can look highly modular while still producing one privileged executable.
ChrisOS has directories for:
kernel/metal
kernel/fs
kernel/gfx
kernel/net
kernel/wm
kernel/lang
kernel/tools
kernel/crypto

compiler/chrisc
compiler/clvm
compiler/jit
compiler/kcc
compiler/chrisasm
compiler/chrisld
...
That organization expresses cohesion and responsibility.
It does not automatically create isolated execution domains.
The makefile is the decisive evidence.
Its kernel object list directly includes objects from:
kernel/metal/*
kernel/fs/*
kernel/gfx/*
kernel/net/*
kernel/wm/*
kernel/lang/*
kernel/tools/*
kernel/crypto/*

compiler/chrisc/*
compiler/clvm/*
compiler/jit/*
compiler/kcc/*
compiler/chrisasm/*
compiler/chrisld/*
...
Those objects are linked into the same kernel ELF.
A call from filesystem code to storage code is an ordinary in-kernel call.
A call from graphics code to PMM is an ordinary in-kernel call.
The CPU does not perform a ring transition merely because the source files are in different directories.
What monolithic means here
In this chapter, monolithic means that the major operating-system services execute inside one privileged protection domain.
This includes current implementations of:
- physical-memory management;
- page-table management;
- process management;
- exception and interrupt handling;
- scheduler-related state;
- filesystem;
- storage drivers;
- PCI access;
- network stack;
- VirtIO network;
- graphics;
- framebuffer management;
- VirtIO-GPU;
- VirGL integration;
- audio;
- input;
- window manager;
- desktop loop;
- kernel language runtime;
- much of the self-hosted compiler/toolchain path.
The word does not imply that all code is in one source file or that APIs do not exist.
What modular means here
ChrisOS is modular in the software-engineering sense.
Subsystems expose functions, headers and ownership contracts.
Examples include:
PMM
    physical page ownership

MM
    mapping and translation

proc
    process lifecycle

syscall
    ring-3 service entry

bdev
    block-device abstraction

fs
    filesystem frontend

gfx
    rendering/device abstraction

sock
    socket ownership

job
    SMP kernel work

CLVM
    software guest execution
These boundaries improve:
- cohesion;
- code navigation;
- testing;
- replacement of implementations;
- auditing;
- dependency reasoning.
But an internal C boundary is not a hardware security boundary.
Monolithic versus microkernel
A microkernel normally tries to keep a smaller set of mechanisms in the most privileged domain.
Typical candidates for privileged retention are:
- low-level address-space management;
- thread scheduling;
- interrupt delivery;
- IPC primitives.
Drivers, filesystems and other services may execute in isolated user processes.
If one server crashes, hardware page protection can prevent direct corruption of the microkernel or another service.
ChrisOS does not currently implement that service-placement model.
Its filesystem, storage stack, graphics stack, network stack and desktop infrastructure are linked into the privileged image.
Therefore source modularity must not be described as microkernel isolation.
Monolithic versus hybrid
The term hybrid kernel is used inconsistently across operating-system literature and product documentation.
Some systems use a microkernel-derived architecture but execute many services in a privileged shared address space for performance or compatibility.
Other uses of the term are mostly historical branding.
For ChrisOS, the precise statement is more useful than the label:
major OS services and drivers
    execute in shared ring-0 kernel space

native applications
    can execute in ring 3

CLVM applications
    execute through a software VM boundary
That concrete placement currently matches a modular monolithic design.
The existence of user processes, a VM, a JIT or separate source modules does not by itself make the kernel hybrid.
Protection domain
A protection domain is a set of code and data that can directly access the same privileged resources without crossing an isolation mechanism.
For native x86 execution, important isolation mechanisms include:
- CPL/ring checks;
- page-table U/S bits;
- page-table R/W bits;
- NX;
- I/O privilege controls;
- controlled interrupt/trap gates.
Within the kernel image, ordinary modules mostly share the same ring-0 domain.
Ring 0
Ring 0 code can execute privileged instructions and access supervisor mappings.
Current ChrisOS ring-0 capabilities include operations such as:
MOV CR3
LGDT
LIDT
LTR
CLI
STI
IN / OUT
MMIO access
page-table mutation
physical-page allocation
interrupt-controller programming
PCI configuration
DMA descriptor construction
A kernel bug in one privileged subsystem can therefore have system-wide consequences.
Ring 3
ChrisOS also implements a native user execution path.
enter_user constructs an IRETQ frame using:
and enters user mode with IRETQ.
This is a real hardware privilege transition.
CPL
The Current Privilege Level is derived from the low bits of CS.
For native user execution:
For kernel execution:
The CPU enforces privileged-instruction restrictions and page access based on this architectural state.
User page permission
Native user mappings are created with MM_USER.
The ELF loader begins segment mapping with:
and then adds write permission only for writable segments and NX for non-executable segments.
Thus native application isolation is not merely a convention in the loader.
It is represented in page-table permissions.
Kernel high-half mapping
New process roots copy the kernel upper-half PML4 entries.
Conceptually:
The kernel remains reachable to ring 0 while a process CR3 is active.
Correct U/S permissions prevent ring-3 code from directly accessing those shared supervisor mappings.
Mapping is part of the security boundary
A ring distinction is useful only if page permissions match the intended model.
A kernel page accidentally mapped with user permission can expose privileged state despite CPL 3.
A user page missing MM_USER can fault despite being numerically in the user address range.
Security comes from actual translation permissions, not from high-versus-low addresses alone.
Native ELF user range
The current native ELF loader restricts loadable user segments to:
as its accepted load window.
This is a deliberately small current policy.
It is not an architectural x86 limitation.
Native entry path
The simplified native path is:
ELF bytes
    ↓
elf_load
    ↓
proc_create
    ↓
new CR3
    ↓
user PT_LOAD pages with MM_USER
    ↓
proc_switch
    ↓
enter_user
    ↓
IRETQ
    ↓
CPL 3
The process/syscall chapters expand each stage.
System-call boundary
The current native syscall path uses:
syscall_init modifies IDT vector 0x80 to a user-accessible gate.
The DPL permits ring-3 software to invoke it.
The interrupt entry machinery then transfers execution to ring 0.
That is a hardware trust-boundary crossing.
Current native syscall set
The current syscall interface includes operations for:
- process exit;
- writing output;
- pixel output;
- file open;
- file read;
- file write;
- file close;
- key state.
This ABI is intentionally small compared with a general-purpose OS ABI.
Its size does not change the architectural significance of the boundary.
User pointers are hostile inputs
A syscall executes in ring 0 even when its arguments originated in ring 3.
Therefore every pointer, length, identifier and resource handle received from user mode must be treated as untrusted.
The current syscall implementation contains page-translation and MM_USER checks for memory ranges.
Not every syscall path has yet been consolidated behind one universal copy-from-user/copy-to-user abstraction.
The repository audit explicitly keeps hostile-user-pointer coverage as an open hardening area.
Ring transition does not sanitize arguments
The CPU validates the privilege transition itself.
It does not validate:
- buffer length;
- filesystem path;
- file descriptor ownership;
- integer overflow;
- pointer range;
- semantic permissions.
Those are kernel responsibilities.
Syscall ownership
Native file descriptors store a process owner.
Process teardown invokes cleanup that closes descriptors and sockets owned by the destroyed process.
This illustrates an important rule:
The two are related but not identical.
Process failure containment
The page-fault path distinguishes user faults from kernel faults.
For a user page fault:
- demand-paging logic may resolve it;
- otherwise the current user process can be recorded and destroyed;
- the kernel can return to its own control path.
Therefore at least some native user failures are contained at process scope.
Kernel failure behavior
panic and panic_exception disable interrupts, print diagnostic identity and halt forever.
A fatal ring-0 exception is not treated as an isolated service crash.
This matches the current monolithic trust model: corruption of core privileged invariants is assumed unsafe to continue.
Failure-domain consequence
The current containment hierarchy is roughly:
native user failure
    potentially one process

CLVM guest fault
    potentially one VM/slot

driver/kernel bug
    potentially entire kernel/system

hardware fault
    depends on device and path
Not all failures have equal blast radius.
CLVM is a separate execution model
ChrisC programs commonly execute through CLVM.
CLVM memory is represented by VM-managed memory and guest offsets.
The interpreter validates addresses against VM memory size.
Examples include:
This is a software-enforced boundary.
It is not the same as CPL 3.
CLVM guest address is not native virtual address
For CLVM:
For native ring-3 execution:
Treating both as one generic pointer model would hide important security differences.
CLVM syscall boundary
A CLVM SYS instruction dispatches through a VM callback and kernel-side service implementation.
The interpreter can reject invalid VM memory accesses before an arbitrary host pointer is formed.
This is a software sandbox boundary.
The CPU remains in the kernel's privilege domain while the interpreter itself executes.
Software sandbox consequence
A correct interpreter can confine many guest mistakes.
But a memory-safety bug in the interpreter or CLVM syscall bridge executes inside privileged kernel code.
Thus CLVM reduces the authority of guest bytecode only to the extent that the VM implementation correctly validates it.
It is not a separate hardware protection domain.
CLVM capability checks
The CLVM service layer includes capability checks for selected driver/hardware operations.
This creates an application-level authority model above the VM boundary.
A capability check is useful policy.
It is still implemented by privileged kernel code.
Hardware gate
kernel/gfx/hwgate.c exposes mediated operations for:
- PCI configuration writes;
- BAR mapping;
- MMIO reads/writes;
- DMA allocation;
- disk access;
- GPU queue operations.
This file sits close to the most dangerous authority boundary in the system.
It can transform a high-level request into physical-memory and device side effects.
Therefore it belongs to the effective Trusted Computing Base even if a caller is capability-checked.
Hardware capability versus hardware isolation
A software capability can reject an unauthorized operation.
It does not itself stop a bug inside hwgate or a driver from writing the wrong physical address.
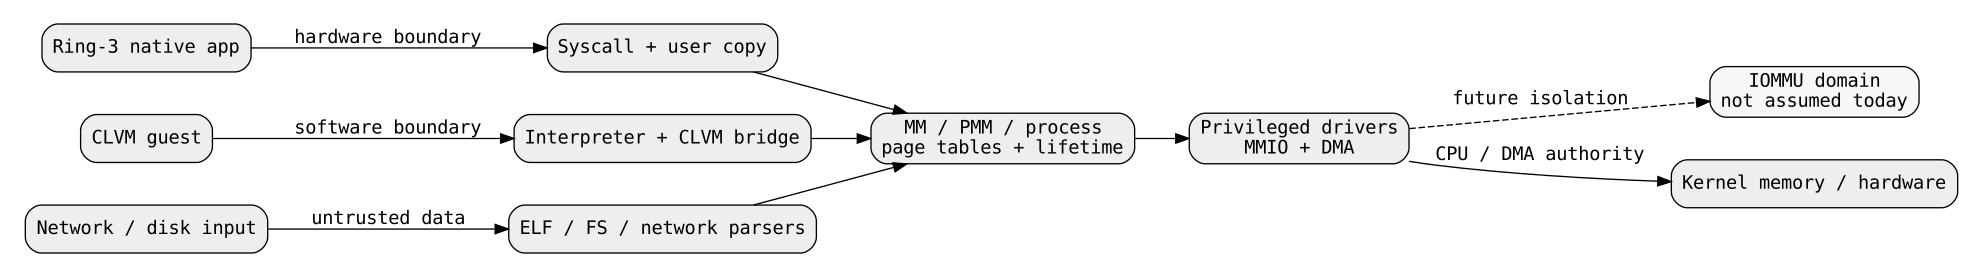
An IOMMU would add a separate hardware layer capable of restricting device DMA.
Current documentation must not assume an IOMMU domain unless ChrisOS actually programs one.
DMA bypasses CPU page checks
A DMA-capable device does not perform an ordinary user-mode CPU load or store.
If programmed with a physical address, it can access memory according to platform/device/IOMMU rules.
Therefore:
Drivers that program DMA addresses are part of memory protection.
DMA ownership
Safe DMA requires at least:
- valid physical buffer;
- address width compatible with device;
- buffer lifetime longer than the request;
- no PMM reuse before completion;
- descriptor lifetime;
- completion detection;
- cache/order rules;
- isolation or trust of the device.
The bus/DMA chapters expand these requirements.
Trusted Computing Base
The TCB is the set of components whose correctness is required for a claimed protection property.
For native ring-3 isolation, the current TCB includes at least:
- GDT/TSS setup;
- IDT entry;
- interrupt stubs;
- page-table code;
- PMM lifetime rules;
- process creation/destruction;
- ELF loader;
- user-copy/syscall validation;
- CR3 switching;
- kernel exception handling.
For filesystem integrity, the TCB expands to filesystem and storage code.
For DMA safety, it expands to relevant drivers and descriptor logic.
The TCB depends on the property being discussed.
TCB is not equivalent to kernel size
A large window manager function may be irrelevant to one page-table isolation proof.
A five-line PTE helper can be central to it.
Security auditing should follow authority and invariants, not source-line count.
Internal API boundary
Suppose kernel/fs/fs.c calls a storage function.
The API can enforce:
- types;
- return codes;
- ownership conventions;
- error propagation.
But both sides are ring 0.
Hardware does not stop fs.c from corrupting storage globals if a memory bug occurs.
That is an API boundary, not a security domain.
Device abstraction boundary
A block-device interface separates filesystem logic from AHCI, NVMe, ATA, VirtIO Block and USB storage implementations.
This is a strong architectural boundary for dependency management.
It is still within privileged memory.
Replacing a driver can be easier.
Containing a wild pointer in the driver is not provided by that interface alone.
Why modular monolith is still valuable
The absence of hardware isolation between kernel modules does not make modularity cosmetic.
Well-defined modules enable:
- local reasoning;
- explicit ownership;
- host tests;
- replacement of backends;
- smaller interfaces;
- lock-order documentation;
- differential testing;
- future migration to stronger isolation.
A monolithic kernel can be highly disciplined.
Kernel build as evidence
The current makefile's C_OBJECTS_REL is an architectural artifact.
It demonstrates that the same final kernel image contains code from:
metal
network
crypto
graphics
window manager
tools
storage/filesystem
language runtime
compiler
JIT
process/SMP
This is stronger evidence of privilege placement than directory names alone.
Static linking and privileged reachability
The kernel is linked:
with its custom linker script.
The listed objects become part of one freestanding executable.
There is no dynamic userspace service manager separating the major kernel subsystems during production boot.
Kernel initialization graph
kstart initializes major services in process.
There is no boot-time IPC negotiation with independent filesystem, graphics or network servers.
Instead the sequence directly calls:
This is characteristic of the current monolithic placement.
Kernel/user split
The native protection structure can be viewed as:
ring 3
    native user ELF
        |
        | INT 0x80
        v
ring 0
    syscall dispatcher
    process/MM
    filesystem
    graphics
    networking
    drivers
    hardware
The syscall interface is the narrow native hardware privilege crossing.
CLVM split
The CLVM path is instead:
guest bytecode
    |
software VM validation
    |
CLVM SYS dispatcher
    |
kernel services
    |
drivers / hardware
The CPU privilege level need not change when the interpreter executes the guest instruction.
The isolation mechanism is software.
Two application boundaries coexist
ChrisOS therefore has at least two conceptually separate application safety models:
| Model | Boundary | Address model | Entry into services | Isolation mechanism |
|---|---|---|---|---|
| Native ELF | ring 3 → ring 0 | x86 virtual address | INT 0x80 | CPL + page tables |
| CLVM | guest → VM host | VM offset | CL_OP_SYS callback | interpreter bounds/capabilities |
These should never be collapsed into one security statement.
Kernel jobs
The SMP job system distributes kernel work across CPUs.
APs execute job_worker_forever.
A job is a function pointer plus an argument.
Executing a job does not create a new process or user protection domain.
It is privileged kernel work.
Kernel threads
kthread_create builds a separate stack and schedules execution through the kernel job system.
kthread code switches RSP to its allocated stack, calls the thread function and later restores the previous stack.
It does not switch to a user CR3 or ring 3.
Therefore current kernel threads are:
not isolated processes.
Stack separation is not address-space separation
Two kernel threads can have different stacks while sharing:
- kernel globals;
- heap;
- page tables;
- device state;
- filesystem state.
This improves execution-context management but not memory isolation.
SMP architecture
Current SMP is deliberately asymmetric.
Application processors can execute kernel jobs.
The BSP retains ownership of native user-process switching.
The source and locking document enforce:
and syscall_dispatch rejects off-BSP execution.
Why BSP-only user scheduling matters
The process table and current-process state are global.
Restricting user scheduling to one CPU avoids simultaneous mutation of:
- current process;
- user CR3 transition;
- syscall return context;
- some process lifecycle state.
This is an architectural constraint used to reduce concurrency complexity while AP kernel execution continues to evolve.
SMP does not imply multi-core userspace
A system can use multiple CPUs for kernel jobs without scheduling ring-3 processes across those CPUs.
ChrisOS currently does exactly that.
Therefore statements such as "SMP supported" must specify what workload participates.
Shared kernel mappings
Process address spaces copy the upper kernel half.
This means kernel mappings are shared between roots.
A change to shared kernel virtual memory can affect execution on multiple CPUs and multiple CR3s.
That is why TLB shootdown and frame-lifetime rules are part of the trust model.
TLB as a safety problem
Suppose a kernel mapping is removed and its physical page returned to PMM.
If another CPU still has a stale TLB translation, it may continue accessing the old physical page after ownership changed.
Therefore safe reclamation requires:
unmap
    ↓
invalidate / shootdown
    ↓
prove remote CPUs no longer use translation
    ↓
only then reuse physical frame
This is not merely a performance concern.
It is memory ownership.
Fenced CPUs
The current TLB protocol can fence a CPU that fails to acknowledge.
A fenced CPU is prevented from making unsafe forward progress and frame reuse can be quarantined until reuse becomes safe.
This is an example of architecture designed around failure containment inside a monolithic SMP kernel.
Interrupts are asynchronous kernel entry
An interrupt can cause privileged code to run between ordinary instructions.
Therefore even a single-CPU system has concurrency-like reentrancy concerns.
A lock used by normal kernel code may deadlock if the same CPU takes an interrupt and the handler tries to acquire the same lock.
This is why lock documentation includes interrupt-state rules.
Lock order
The repository defines an explicit lock ordering.
Current major rank direction is:
The purpose is to prevent cycles in lock acquisition.
This is architectural documentation, not merely an implementation comment.
Recursive PMM rule
PMM permits controlled same-CPU reentry in specific callback paths.
The outer acquisition disables interrupts.
That prevents an interrupt on the same CPU from unexpectedly reentering PMM while state is inconsistent.
Again, interrupt state is part of the locking model.
Filesystem lock differs
The CFS lock is intentionally a yielding lock rather than simply part of the PMM/MM spinlock order.
Waiters leave interrupts enabled.
The design recognizes that storage progress and IRQ delivery can be needed while one filesystem operation waits.
One universal locking primitive is not appropriate for all subsystems.
Network residual race
The locking document explicitly states that socket table updates occur from BSP syscall and receive paths and that there is no socket lock yet.
Ownership checks do not replace mutual exclusion if those paths become concurrent on different CPUs.
This is a useful example of a documented current limitation.
Audio IRQ synchronization
AC97 combines a spinlock, interrupt-state control and atomics for waiter publication.
That mix exists because device interrupt execution observes shared driver state asynchronously.
A driver boundary is therefore also a concurrency boundary.
Mechanism versus policy
Kernel architecture becomes easier to reason about when mechanism and policy are separated conceptually.
Examples:
mm_map_cr3
    mechanism: install mapping

MM_USER decision
    policy: who may access it

apic_ipi
    mechanism: send interrupt

TLB protocol
    policy: who must acknowledge

pmm_alloc
    mechanism: allocate frame

resource owner
    policy: who returns it

bdev read
    mechanism: block transfer

filesystem
    policy: naming/layout/metadata
Source files may implement both nearby, but the concepts remain distinct.
Resource ownership is architecture
A resource is not safe merely because it was allocated successfully.
It needs:
- an owner;
- a lifetime;
- allowed borrowers;
- synchronization rule;
- release condition;
- failure cleanup.
The repository's RESOURCE_OWNERSHIP document makes these contracts explicit.
Process-owned memory
A process owns its PML4 and user-side page tables.
Owned user leaf frames are tracked.
proc_destroy eventually releases:
- user pages;
- user page-table structures;
- native file descriptors;
- sockets.
This is stronger than merely deleting a process-table slot.
JIT ownership
JIT memory has a more complex lifecycle.
Pages can be writable through one alias and executable through another.
Release requires unmapping, TLB synchronization and only then physical-frame reuse.
The trust boundary includes both W^X policy and TLB lifetime.
Device-owned resources
Some DMA pages live for the full device lifetime.
A device can retain authority over memory even when no CPU code is actively using the buffer.
This is why resource ownership must model hardware actors.
Boot resources
The previous module showed another ownership category:
The same ownership vocabulary continues inside the running kernel.
Failure domains
A kernel model is also a map of failure containment.
Native user fault
A bad user memory access can be attributed to a user process.
The process can be destroyed without necessarily stopping the kernel.
CLVM fault
The VM can report:
- bad address;
- bad jump;
- stack underflow/overflow;
- invalid syscall;
- division errors.
These can terminate or fault the VM context rather than causing arbitrary native memory access when validation works.
Kernel exception
A fatal kernel exception enters panic_exception.
Current policy halts.
IRQ storm
The IRQ code can mask a legacy line after a large hit count to prevent permanent boot livelock.
TLB non-response
The TLB protocol can fence an unresponsive CPU and quarantine reuse.
Different subsystems therefore have different containment mechanisms.
Panic policy
The current panic path:
There is no attempt to restart a failed kernel driver or continue after arbitrary ring-0 corruption.
That is consistent with the current shared privileged domain.
Why microkernel-style restart is not currently available
Restarting an isolated server requires the server to be outside the core protection domain and to have reconstructable resources.
A storage driver currently linked into the kernel can modify arbitrary privileged memory if it contains a wild pointer.
After such corruption, re-running only its init function cannot establish system integrity.
This is the practical difference between source modularity and fault isolation.
Hardware root of trust boundaries
CPU privilege is only one authority mechanism.
Other hardware boundaries include:
- page translation;
- NX;
- DMA/IOMMU;
- PCI bus mastering;
- interrupt routing;
- MSRs;
- control registers;
- device MMIO.
A complete kernel trust model must account for all of them.
User-access bit
MM_USER on every relevant level of a page-table walk permits user access.
The MM code propagates the user bit into parent entries when necessary.
A leaf alone is insufficient if an upper-level entry blocks user access.
This is why page-table helpers belong to the native security TCB.
W^X
The user ELF loader rejects a segment that is simultaneously writable and executable.
It also maps non-executable segments with NX.
This narrows the authority of native user pages.
Kernel/JIT W^X has separate mechanisms documented elsewhere.
Executable validation
The user ELF loader checks:
- ELF magic;
- ELF64;
- little-endian format;
- ET_EXEC;
- x86-64 machine type;
- program-header bounds;
- PT_LOAD only;
- file size not exceeding memory size;
- no W+X load segment;
- page alignment relationship;
- user-load-range policy;
- non-overlapping segments;
- executable entry point.
This loader is a trust-boundary parser because it interprets untrusted executable bytes into page mappings.
Parser code belongs to the TCB
A malformed ELF should be rejected.
It should not trick the kernel into:
- integer overflow;
- mapping kernel addresses as user;
- writing outside file data;
- creating W+X user pages;
- entering a non-executable segment.
Therefore parser correctness is part of process isolation.
Filesystem is privileged
The filesystem frontend, CFS implementation and block-device drivers execute in the kernel domain.
Filesystem metadata corruption can therefore become a kernel integrity problem.
This differs from a microkernel where filesystem parsing might occur in an isolated server.
Network parsing is privileged
Ethernet, IPv4, UDP, TCP and socket logic currently execute in privileged code.
A malformed network packet is therefore input to the kernel TCB.
Length validation and parser bounds are security properties, not merely networking correctness.
Graphics is privileged
The software renderer, graphics resource code, VirtIO-GPU, VirGL support and related device code are linked into the kernel image.
Large graphics code therefore contributes to privileged code surface.
A future architecture could move policy/rendering components out of ring 0 while retaining a narrow device interface, but that is not the current placement.
Window manager is privileged
desktop_run and window-management code are part of the kernel image.
The desktop is not currently a normal isolated ring-3 compositor process.
A window-manager memory bug can therefore affect the kernel domain.
This is an important difference from many production desktop operating systems.
Compiler/toolchain code is privileged in the current image
The makefile links compiler and linker components into kernel.elf.
This includes significant portions of:
- ChrisC compiler;
- CLVM;
- JIT;
- KCC;
- ChrisAsm;
- ChrisLd;
- debugging/tooling.
Self-hosting therefore increases the privileged code surface.
It also gives the system unusual ability to compile and manipulate code internally.
Both facts need to be documented.
Self-hosting and privilege are separate goals
A self-hosted toolchain does not have to execute in ring 0 forever.
Long-term, a compiler could execute as:
- ring-3 native process;
- CLVM application;
- isolated service;
- kernel component.
The current build placement is a present architectural choice, not a fundamental requirement of self-hosting.
Kernel tools are also linked in
Editor, explorer, shell, build tools and related support code appear in the kernel object list.
This shows that the current system is optimized for integrated experimentation rather than minimum TCB size.
Documentation should describe that fact without confusing it with a final immutable architecture.
Experimental architecture and explicit boundaries
For a research OS, a broad privileged image can be useful because it reduces bootstrap complexity.
It enables direct experimentation with:
- page tables;
- graphics;
- drivers;
- compiler internals;
- virtual machines;
- storage;
- networking.
The cost is that each privileged subsystem increases shared failure authority.
The documentation must make that trade-off explicit.
Architecture quality is not determined by one taxonomy label
Calling a kernel monolithic, microkernel or hybrid does not determine whether it is well designed.
Relevant engineering properties include:
- dependency direction;
- interface size;
- ownership clarity;
- synchronization;
- testability;
- fault containment;
- privilege minimization;
- performance;
- observability;
- recoverability.
ChrisOS should be evaluated through those concrete properties.
Current dependency direction
At a high level:
desktop / language / tools
        ↓
graphics / filesystem / network
        ↓
device abstractions
        ↓
MM / PMM / process / IRQ / SMP
        ↓
x86-64 architecture + devices
The actual graph contains cross-links and experimental shortcuts.
A long-term goal should be to make authority flow and dependency direction increasingly explicit.
Core versus policy-heavy code
kernel/metal contains much of the low-level mechanism.
However, not every file in metal is automatically more privileged than every file elsewhere.
A network driver doing DMA can have more physical-memory authority than a pure scheduler helper.
Privilege should be mapped by capability, not directory name.
Authority inventory
A useful architecture review asks which code can perform each operation.
Modify page tables
MM and closely related process code.
Allocate/free physical memory
PMM and callers through PMM APIs.
Reprogram devices
Drivers, PCI/MMIO/port-I/O helpers and hardware gate.
Execute arbitrary kernel function pointers
Job/kthread paths.
Parse untrusted native executables
ELF loader.
Parse untrusted VM bytecode
CLVM.
Parse network data
network stack.
Parse persistent metadata
filesystem.
This inventory is often more useful than a directory tree.
API surface and authority surface differ
A subsystem can expose few functions but possess enormous authority.
For example, a DMA allocator may have a tiny API but can indirectly expose physical memory to hardware.
Conversely, a text renderer may have many helper functions but little authority over page tables.
Security review should weight authority, not just API count.
Native process CR3 ownership
Each process gets an address-space root.
The kernel high half is copied into it.
User leaves are tracked for teardown.
proc_switch changes the current CR3 under the BSP-only invariant.
This is genuine address-space isolation, even though the kernel itself remains monolithic.
Kernel thread address space
Kernel threads do not receive independent user page-table roots.
They use kernel execution context and separate stacks.
Therefore they do not form separate fault domains against kernel memory.
Context versus domain
These concepts should remain separate:
execution context
    register/stack scheduling identity

address space
    page-table translation domain

privilege domain
    CPU authority level

software sandbox
    interpreter-enforced authority
A kernel thread has a distinct execution context without a separate privilege domain.
A CLVM instance has a software sandbox without necessarily a distinct CPU privilege level.
A native process has both a process address space and ring-3 privilege.
Scheduler ownership
Current user scheduling remains BSP-only.
Kernel jobs can execute across CPUs.
This creates two scheduling planes:
Future multi-core user scheduling will require converting process-global invariants into SMP-safe invariants.
What would change for multi-core userspace
A future scheduler that runs user processes on APs would need to revisit at least:
- current-process representation;
- per-CPU current process;
- syscall return context;
- process locks;
- CR3 switching;
- TSS.RSP0 per CPU;
- signal/wakeup equivalents;
- user-copy context;
- process teardown;
- TLB synchronization;
- file/socket table concurrency.
The current BSP-only rule is therefore an explicit simplification boundary.
What would make ChrisOS more microkernel-like
Moving a service into a separate ring-3 process would require more than moving files.
For a driver, the system would need:
- isolated address space;
- IPC;
- interrupt delivery mechanism;
- safe MMIO delegation;
- DMA delegation/IOMMU strategy;
- resource revocation;
- process restart;
- service discovery;
- failure recovery.
Without those mechanisms, a user-space driver architecture is only a source relocation plan.
What would make ChrisOS more hybrid-like
A hybrid direction might keep selected performance-critical services privileged while moving others into isolated domains.
For example, one could imagine:
ring 0:
    scheduler
    MM
    IPC
    selected fast-path drivers

ring 3 services:
    filesystem
    network service
    desktop/compositor
    compiler service
But this is not current ChrisOS.
Documentation must distinguish roadmap ideas from present implementation.
Why no forced redesign is required
A modular monolithic model is a valid systems architecture.
For a research OS focused on understanding low-level mechanisms, it can be an efficient development model.
The important requirement is that documentation remains precise about its fault and trust boundaries.
Observability as part of kernel architecture
Panic output includes:
- CPU index;
- CR3;
- RSP;
- build identity;
- git identity;
- kernel hash.
This is architectural observability.
When isolation is limited, high-quality diagnostics become especially important because a ring-0 failure can terminate the whole system.
Build identity and reproducibility
A kernel panic tied to a build SHA can be connected to exact source.
That matters when the same privileged image contains many rapidly evolving subsystems.
Reproducibility helps distinguish architecture regression from environmental behavior.
Host tests versus privileged integration
Many subsystems have host tests.
Host tests can validate:
- pure algorithms;
- parsers;
- ownership tables;
- filesystem logic;
- VM semantics.
They cannot prove:
- page-table permissions on real CPU execution;
- interrupt behavior;
- CPL transition;
- DMA ordering;
- APIC behavior;
- actual device interaction.
The validation ladder must preserve that distinction.
Validation ladder
For kernel architecture, evidence can progress through:
source inspection
    ↓
host/unit test
    ↓
freestanding compile
    ↓
QEMU integration
    ↓
SMP/device stress
    ↓
ChrisVM differential execution
    ↓
real hardware
Not every feature needs every layer, but claims should state which evidence exists.
Stubs must remain visible as stubs
The current IOAPIC function is still a stub-like implementation that logs the continued PIC routing model.
Architecture documentation must not infer feature completion from a function name.
The same rule applies throughout an experimental OS.
Trust-boundary table
| Boundary | Enforcement | Crosses ring? | Primary risk |
|---|---|---|---|
| native user → syscall | x86 CPL + IDT + paging | yes | bad user input |
| user page → kernel page | page-table U/S | no call required | mapping bug |
| CLVM guest → CLVM SYS | interpreter checks | no | VM escape bug |
| kernel module → kernel module | C API/discipline | no | shared-memory corruption |
| kernel → device MMIO | page mapping + driver | no | device misprogramming |
| driver → DMA memory | device/IOMMU rules | no | physical-memory corruption |
| CPU → CPU shared kernel state | locks/atomics/TLB protocol | no | race/stale translation |
| persistent disk → filesystem | parser/metadata validation | no | kernel metadata corruption |
| network → protocol parser | parser bounds | no | privileged parser bug |
The table shows why "ring 0 versus ring 3" is only one part of the trust model.
Privilege-minimization roadmap
If reducing the TCB becomes a project goal, candidates can be ranked by whether they actually require ring 0.
Possible long-term candidates include:
- desktop/window manager;
- compiler frontends;
- high-level filesystem policy;
- network services;
- some device-management policy.
Candidates that inherently need privilege can still be split into narrow privileged mechanisms and less-privileged policy.
This is a future architectural option, not a current requirement.
Driver isolation is particularly difficult
A driver may need:
- MMIO;
- interrupts;
- DMA;
- PCI configuration;
- physical-memory pinning.
Moving it to user mode safely requires explicit delegation for each of these powers.
The problem is not merely function-call overhead.
It is authority transfer and revocation.
CLVM as an intermediate isolation laboratory
Because CLVM already has:
- guest memory;
- checked offsets;
- system-call dispatch;
- per-slot resources;
- capabilities;
- fault states,
it can serve as a useful environment for experimenting with stronger service contracts.
But CLVM should not be described as equivalent to a hardware-isolated microkernel server.
Its interpreter and bridge remain privileged TCB.
Native ring-3 path as stronger hardware isolation
For components that can run under the native ELF process model, ring 3 provides an architectural boundary independent of interpreter correctness.
That makes the native process path especially important for future privilege separation.
However, the syscall/user-copy surface must mature correspondingly.
User-copy maturity
The repository audit already identifies centralized hostile-pointer validation as unfinished.
Before moving complex services into ring 3, the kernel needs strong primitives for:
- copy from user;
- copy to user;
- string copy with bounded termination;
- range validation;
- overflow-safe spans;
- partial-copy semantics;
- fault handling.
A larger userspace expands the importance of these primitives.
Resource handles instead of raw authority
A strong isolation architecture avoids giving applications raw physical addresses or arbitrary MMIO pointers.
Instead, it can expose handles describing permitted resources.
Current CLVM resource ownership and capability work points in this direction for some operations.
Native userspace can evolve similarly.
Global state is the main modular-monolith pressure point
Modular source becomes difficult to scale when subsystems communicate through unrestricted globals.
Current ChrisOS has several global tables by design.
For each one, documentation should identify:
- initializer;
- owner;
- readers;
- writers;
- lock;
- IRQ context;
- CPU policy;
- teardown;
- failure behavior.
This turns implicit global state into explicit architecture.
Current process table
The process subsystem uses global process state and current-process identity.
BSP-only scheduling is part of its synchronization model.
The correct future transition is not just adding a lock around one function.
The ownership model itself must become per-CPU/SMP-aware.
Current job queue
The job queue has an explicit spinlock and atomic counters.
This is kernel work distribution, not process scheduling.
The queue can be consumed by AP workers.
That separation is architecturally useful.
Current filesystem state
The filesystem frontend selects a backend globally.
CFS uses its own synchronization policy.
This works inside one kernel domain but means filesystem failures and lock mistakes are kernel failures rather than isolated server failures.
Current network state
Network code keeps global protocol state and socket tables.
The locking document explicitly identifies an incomplete socket-locking story if AP receive and BSP mutation become concurrent.
This is a concrete example of modularity ahead of full SMP hardening.
Current graphics state
Graphics has global and per-slot contexts.
Some resources are owned by individual tasks/VM slots, while low-level rendering/device structures remain global.
This is a mixed ownership model inside the same privilege domain.
Current window manager
The window manager and desktop loop execute as kernel code.
desktop_run polls network and VM activity, advances desktop state, presents graphics and halts between ticks.
It is policy-heavy code running at maximum privilege.
That is a present implementation fact.
Current compiler integration
Compiler and JIT code are linked into the kernel.
The JIT additionally manages executable mappings and therefore directly intersects MM/TLB policy.
Compiler correctness and kernel memory-safety concerns are unusually close in this architecture.
Why source atlas matters
Because the kernel image is broad, documentation needs a precise source map.
Generated source atlases help answer:
- where authority lives;
- which source implements a claimed behavior;
- which revision was reviewed;
- whether docs drifted.
This is especially important for AI-assisted evolution of the project.
AI maintenance and architectural contracts
Automated agents can easily preserve syntax while violating architecture.
Machine-checkable contracts help prevent this.
Examples include:
- user scheduling remains BSP-only;
- kernel high half is supervisor-only;
- process ELF pages require MM_USER;
- W+X user PT_LOADs are rejected;
- kernel modules remain linked into one image unless architecture intentionally changes;
- kthread stacks do not imply process isolation;
- CLVM guest offsets are range checked;
- TLB reuse waits for safe invalidation.
The checker in this chapter codifies selected invariants.
Reproducible checker
scripts/check_kernel_model_examples.py validates:
- the production kernel links objects from metal, fs, gfx, net, wm, lang and compiler directories;
- native user entry uses ring-3 GDT selectors and IRETQ;
- syscall vector 0x80 is made user accessible;
- user ELF mappings include MM_USER;
- W+X user PT_LOADs are rejected;
- proc_switch enforces BSP-only user scheduling;
- syscall_dispatch rejects off-BSP execution;
- kernel threads switch stacks but do not switch CR3 or enter ring 3;
- CLVM memory access contains explicit VM-size bounds checks;
- CLVM SYS is software-dispatched;
- panic disables interrupts and halts;
- RESOURCE_OWNERSHIP assigns process resources to teardown paths;
- LOCKING records the kernel lock order and current socket-lock limitation;
- hardware-gate code performs privileged PCI/MMIO/DMA operations inside the kernel image.
This checker validates source architecture contracts.
It does not prove absence of kernel memory-safety bugs.
Current architecture summary
At the reviewed revision:
kernel type:
    modular monolithic

kernel privilege:
    ring 0

major services:
    linked into kernel.elf

native application boundary:
    ring 3 + page tables + INT 0x80

CLVM boundary:
    software VM + bounds checks + SYS dispatcher

kernel jobs:
    ring-0 work on BSP/APs

kernel threads:
    separate stacks, shared privileged domain

native user scheduling:
    BSP-only

fatal kernel fault:
    panic + halt

driver isolation:
    no separate hardware protection domain

IOMMU isolation:
    not assumed

desktop/window manager:
    privileged kernel code

compiler/JIT:
    substantial portions linked into kernel
What ChrisOS is not currently
It is not currently:
- a microkernel with user-space filesystem and driver servers;
- a capability microkernel with hardware-enforced service domains;
- a fully per-CPU native userspace scheduler;
- a restartable driver architecture;
- a minimal-TCB kernel;
- an IOMMU-enforced DMA sandbox;
- a system where the desktop compositor is an isolated user process.
These are useful distinctions because source names alone can suggest stronger isolation than exists.
What ChrisOS already has that supports future evolution
The current codebase already contains useful foundations:
- real ring-3 entry;
- per-process CR3 roots;
- MM_USER mappings;
- user ELF validation;
- user fault containment;
- resource ownership records;
- kernel module interfaces;
- block-device abstraction;
- VM sandboxing;
- capability checks in selected CLVM paths;
- SMP job separation;
- explicit locking documentation;
- TLB shootdown protocol;
- build/source traceability.
These mechanisms make future privilege reduction possible without requiring a complete rewrite of every subsystem at once.
Architecture evolution should preserve facts
A future change should update this chapter if it changes any of the following:
- service privilege placement;
- object linkage into kernel.elf;
- syscall mechanism;
- user scheduling CPU policy;
- CLVM execution domain;
- driver isolation;
- DMA isolation;
- kernel-thread address-space model;
- panic/recovery behavior;
- TCB assumptions.
The label must follow implementation, not the other way around.
Validation boundary
This chapter is reconciled with:
The classification is based on concrete source placement and hardware boundaries, not on naming preference.
Run:
Review triggers
Review when:
- a major service moves out of kernel.elf;
- native ring-3 services expand materially;
- the syscall ABI changes from INT 0x80;
- user scheduling becomes multi-core;
- kernel threads gain separate address spaces;
- CLVM execution moves to native ring 3;
- drivers become isolated services;
- an IOMMU is configured;
- desktop/window manager moves to userspace;
- compiler/JIT privilege placement changes;
- panic policy gains subsystem recovery;
- the makefile object graph changes the privileged image.
Primary references
- Intel 64 and IA-32 Software Developer's Manual, protection and paging.
- AMD64 Architecture Programmer's Manual, long mode and privilege.
- Liedtke, On Micro-Kernel Construction, for microkernel design principles.
- seL4 reference material for capability-oriented microkernel isolation concepts.
- Linux kernel documentation for a mature modular-monolithic comparison point.
- ChrisOS sources and internal architecture documents listed in front matter.