
Virtual memory and address-space construction
About this chapter Frames and address translation
In this chapter
- Virtual memory and address-space construction
- Scope
- Architectural translation model
- Canonical halves and the ChrisOS split
- Page-table pages are physical objects
- Initialization: adopting the active hierarchy
- Creating a kernel mapping
- Creating a mapping in an arbitrary CR3
- Mapping flags and protection
- Dedicated MMIO mappings
- Translation without dereference
- Process ownership is separate from translation
- Demand paging in the current process model
- Unmapping and frame lifetime
- Destroying a process address space
- CR3 switching and TLB state
- Concurrency and lock ordering
- Complexity and memory cost
- Validation evidence
- Current limitations
- Revision boundary
Scope
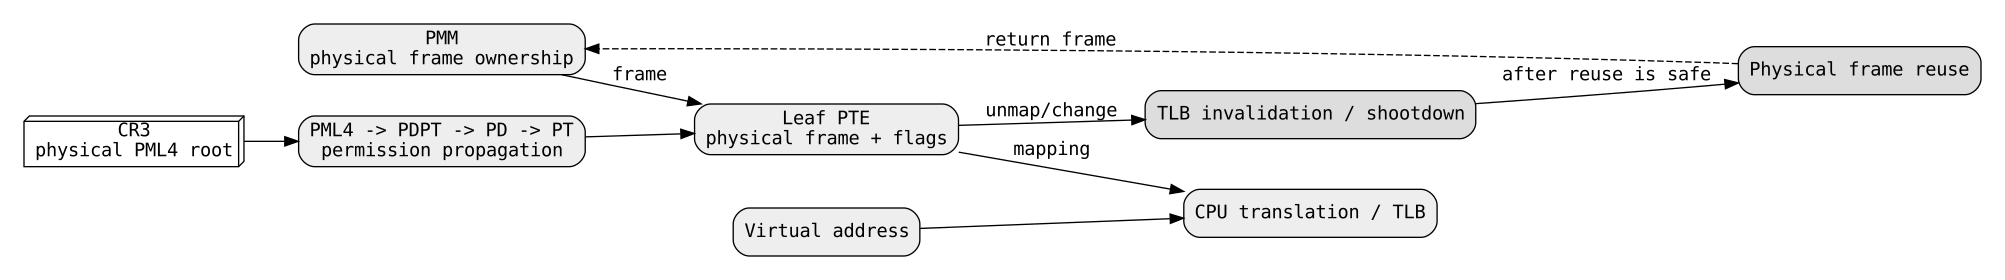
Virtual memory is the mechanism that decouples the address produced by an instruction from the physical frame or device register ultimately accessed. On x86-64, the translation state selected by CR3 is part of the architectural execution context: the same virtual address can resolve to different physical memory in different address spaces, can be inaccessible in one context and valid in another, or can intentionally refer to the same shared kernel mapping.
ChrisOS currently uses the four-level x86-64 paging model already established by the boot environment. The kernel does not discard the boot-time hierarchy and rebuild every kernel mapping from first principles during mm_init. Instead, it reads the active CR3, records its physical root as mm_cr3_phys, makes that hierarchy the kernel address-space authority, and incrementally extends it for MMIO, tests, and process-related mappings.
The current implementation is therefore best understood as three cooperating mechanisms:
- PMM owns physical frames.
- MM owns translation structures and page-table mutations.
- The process layer records which leaf frames belong to each user process.
Those mechanisms intentionally do not collapse into one allocator.
Architectural translation model
For a conventional 4 KiB page in four-level x86-64 paging, a canonical virtual address is decomposed into four 9-bit table indices and a 12-bit byte offset:
63                         48 47    39 38    30 29    21 20    12 11      0
+----------------------------+--------+--------+--------+--------+----------+
| canonical sign extension   | PML4   | PDPT   | PD     | PT     | offset   |
+----------------------------+--------+--------+--------+--------+----------+
                              9 bits   9 bits   9 bits   9 bits   12 bits
Each table contains 512 entries. At eight bytes per entry, one complete page table occupies exactly 4096 bytes, so a page-table page is itself one ordinary PMM frame.
For virtual address V, the current helpers compute:
pml4 = (V >> 39) & 0x1ff
pdpt = (V >> 30) & 0x1ff
pd   = (V >> 21) & 0x1ff
pt   = (V >> 12) & 0x1ff
off  = V & 0xfff
The processor begins at the physical page-table root in CR3. A normal 4 KiB walk follows PML4E -> PDPTE -> PDE -> PTE, then combines the page-aligned frame address in the PTE with the 12-bit offset.
ChrisOS also understands huge-page leaves while translating existing mappings. translate_leaf recognizes a PS leaf at the PDPT level as a 1 GiB mapping and a PS leaf at the PD level as a 2 MiB mapping. The public mapping routines, however, create 4 KiB mappings only. Encountering a huge-page entry in a path that map_4k needs to descend through is treated as a fatal unsupported topology rather than being split automatically.
Canonical halves and the ChrisOS split
With the four-level 48-bit model, PML4 indices 0 through 255 correspond to the lower canonical half and indices 256 through 511 to the upper canonical half.
ChrisOS uses that hardware property directly when constructing a process address space. mm_clone_kernel_space allocates a fresh zeroed PML4 and copies only entries 256..511 from the kernel PML4. The result is:
| Region | PML4 entries | Current ownership model |
|---|---|---|
| User half | 0..255 | Private hierarchy created for the process |
| Kernel half | 256..511 | Shared top-level references copied from kernel |
| PML4 frame | one per process | Allocated from PMM |
| User leaf frames | process-specific | Recorded in Proc.pages |
| Kernel leaf frames | shared/kernel-owned | Not freed by process teardown |
This split is a structural isolation boundary. A new process does not inherit the kernel's lower-half user mappings, while it does inherit the kernel's upper-half translation tree.
The copied entries are references to existing lower-level kernel tables, not deep copies. Consequently, process teardown must never recursively free the upper half. mm_free_user_space enforces exactly that rule by walking only PML4 indices below 256.
Page-table pages are physical objects
Page-table entries contain physical addresses. Kernel code still needs a virtual address to read or modify the page-table page itself.
table_from_phys solves that translation by masking the entry down to its physical frame address and passing it through bootinfo_phys_to_virt. That function applies the boot-provided higher-half direct-map relationship documented in the HHDM chapter.
This creates an important implementation dependency:
page-table entry
      |
      | physical child-table address
      v
table_from_phys
      |
      | HHDM conversion
      v
kernel virtual pointer to the table page
The page-table subsystem therefore depends on both PMM and HHDM: PMM supplies frames for newly created tables; HHDM makes those frames directly writable by the kernel.
Initialization: adopting the active hierarchy
mm_init performs a deliberately small initialization sequence:
- initialize mm_lock;
- initialize the TLB runtime protocol;
- read CR3;
- mask CR3 to obtain the root page-table physical address;
- initialize the dedicated MMIO virtual window cursor;
- mark MM as ready;
- translate the boot framebuffer virtual address through the active tables;
- panic if that framebuffer mapping cannot be recovered.
The key point is what is not done: mm_init does not synthesize the complete kernel page-table tree. It adopts the active hierarchy supplied by the boot path and validates a translation that the rest of the graphical boot depends on.
This makes the bootloader paging contract part of the current kernel-memory contract. A future native loader could change where the initial hierarchy comes from without changing the later MM APIs, but that is not the current implementation.
Creating a kernel mapping
map_4k and map_4k_nosync operate on the kernel root mm_cr3_phys.
The internal map_4k_ex sequence is:
validate MM initialized
validate 4 KiB alignment
acquire mm_lock
walk PML4 -> PDPT -> PD -> PT
allocate and zero missing intermediate tables
install leaf PTE = physical frame | flags | PRESENT
release mm_lock
optionally invalidate the local virtual address with INVLPG
ensure_table allocates an intermediate table with pmm_alloc, clears all 512 entries, and links it with PRESENT | WRITE. Its allocation path is non-recoverable: failure calls panic through alloc_zero_table.
This API is appropriate for kernel setup paths where inability to construct a required translation is currently treated as fatal.
map_4k_nosync omits the final local INVLPG. It is useful only when the caller has a reason to defer synchronization; it does not make the mapping operation otherwise less synchronized, because page-table mutation still occurs under mm_lock.
Creating a mapping in an arbitrary CR3
mm_map_cr3 is the recoverable mapping interface used by user-process construction.
It differs from map_4k in four important ways:
- the caller supplies the destination CR3;
- invalid state or alignment returns -1 rather than panicking;
- missing intermediate tables use alloc_zero_table_try and can report allocation failure;
- when MM_USER is requested, the routine propagates the USER bit through required parent entries.
The last property is essential on x86-64. A user-mode access cannot reach a user leaf merely because the leaf PTE has U/S set. The effective path must permit user access at every traversed level. ensure_table_flags therefore upgrades an existing parent entry with MM_USER when a user mapping descends through it.
All intermediate tables are also linked writable. Leaf permissions remain the caller's responsibility.
Partial construction on allocation failure
The current routine does not implement transactional rollback.
Suppose a new PDPT page is allocated successfully and linked into the PML4, but allocation of a later PD or PT page fails. mm_map_cr3 returns -1, but the already-created intermediate table remains reachable from the address-space root.
That is not an unreachable PMM leak: the table remains part of the hierarchy and can be reused by a later mapping, and mm_free_user_space can eventually reclaim the user-half table tree. It does mean that a failed mapping can still mutate the shape of an address space.
Callers must therefore interpret the return value as "the requested leaf mapping was not installed," not "the address-space tree is bit-for-bit unchanged."
Mapping flags and protection
mm.h exposes the currently used software names for architectural PTE bits:
| Flag | Meaning in current use |
|---|---|
| MM_PRESENT | translation entry is present |
| MM_WRITE | writes are allowed at that level |
| MM_USER | user-mode access is allowed at that level |
| MM_PWT | page-level write-through caching control |
| MM_PCD | page-level cache-disable control |
| MM_NX | instruction fetch is prohibited when NX is active |
The current mapping API ORs PRESENT into installed leaf entries even if the caller already supplied it.
The page-table code does not yet expose a generalized policy object for W^X, copy-on-write, guard-page semantics, memory keys, PCIDs, or per-VMA permissions. Permission policy is still expressed by explicit flags at each call site.
Dedicated MMIO mappings
Memory-mapped devices have different caching and execution requirements from ordinary RAM.
map_mmio_page reserves virtual addresses from a fixed 256-page window beginning at 0xffffffff90000000. Each mapping is created with:
The current design therefore makes device mappings writable, uncached/write-through constrained, and non-executable. The window is monotonic: mmio_next advances one page for each mapping and there is no current MMIO virtual-address free list. Exhausting the 256-page window is fatal.
The physical address must be page aligned.
Translation without dereference
ChrisOS provides two software page walkers.
mm_virt_to_phys walks the kernel hierarchy rooted at mm_cr3_phys. It returns zero when a required entry is absent and handles 1 GiB, 2 MiB, and 4 KiB leaves.
mm_translate generalizes the operation to a caller-provided CR3 and returns both:
- the translated physical address including the page offset;
- the leaf entry flags.
The walker runs under mm_lock so it does not observe a page-table mutation half-completed by another MM operation.
This is a critical distinction from simply dereferencing an untrusted virtual address. Software translation lets validation code inspect whether an address is mapped and what leaf permissions exist before performing an access.
Process ownership is separate from translation
A successful PTE does not establish who owns the physical frame.
Proc maintains an explicit fixed-capacity page list. Each ProcPage stores a virtual page and the corresponding physical frame. proc_commit follows this sequence:
- align the requested virtual address down to 4 KiB;
- return success if the page is already recorded as owned;
- reject the operation if the fixed Proc.pages capacity is exhausted;
- allocate one physical frame from PMM;
- zero all 4096 bytes through the HHDM;
- map it into the process through proc_map_user -> mm_map_cr3;
- on mapping failure, return the frame to PMM;
- on success, append the virtual/physical pair to Proc.pages;
- if the process is current, reload CR3 through mm_flush_tlb.
This ordering makes ownership explicit. PMM allocation precedes mapping; process ownership is recorded only after mapping succeeds.
Demand paging in the current process model
ChrisOS implements a bounded form of demand allocation.
proc_set_vm records a requested VM byte count and commits only the first page. Additional pages can be materialized later by a page fault.
For exception vector 14, irq_dispatch reads CR2 and first calls proc_fault_demand for the current process. proc_fault_demand aligns CR2 to a page and checks whether the fault lies inside one of the process regions it is willing to grow:
- the declared VM region;
- the small stack growth window;
- the heap below heap_brk;
- the process framebuffer range.
If the address is eligible, proc_commit allocates and maps the page. A successful commit returns to the faulting instruction. If demand handling declines the fault and the saved CS indicates user mode, the fault is converted into the user-fault path. Other unresolved page faults ultimately enter the kernel exception panic path.
This is demand allocation, not a general-purpose virtual-memory manager. There is no current swap subsystem, file-backed mmap layer, copy-on-write fork, overcommit policy, VMA tree, or page-replacement algorithm.
Unmapping and frame lifetime
mm_unmap_cr3 clears one 4 KiB leaf in a supplied address space. It does not free the physical frame.
If the supplied CR3 is also the currently active CR3, the function issues a local INVLPG for the virtual address. If the address space is inactive on the current CPU, no local invalidation is necessary for that CPU.
proc_release_user uses this separation deliberately:
for each ProcPage:
    clear PTE with mm_unmap_cr3
    free owned frame with pmm_free
clear process page list
Current user processes run only on the BSP; proc_switch explicitly panics if asked to switch a process from an application processor. That restriction narrows the TLB-coherence problem for private user mappings.
Kernel mappings are different because the kernel half is shared by address spaces and may execute on multiple CPUs. Kernel mapping teardown must use the separate TLB shootdown/quarantine protocol before physical frames are considered safely reusable. That protocol is documented separately.
Destroying a process address space
After leaf frames have been released from the process-owned list, mm_free_user_space destroys the remaining user-half page-table structure.
It walks PML4 entries 0..255 and recursively frees non-huge intermediate table pages. The recursion intentionally stops before treating leaf frame addresses as page-table pages. Finally it frees the process PML4 itself.
Two invariants follow:
- shared upper-half kernel tables are not recursively freed;
- user leaf frames must already have been handled by the process ownership layer.
Violating the second invariant would either leak user frames or risk confusing data frames with page-table frames.
CR3 switching and TLB state
mm_switch writes the supplied physical root directly to CR3. proc_switch updates the global current-process index and then invokes mm_switch with the selected process CR3.
mm_flush_tlb reads CR3 and writes the same value back. In the current no-PCID model this is used as a broad local invalidation mechanism after certain process mapping changes.
Individual kernel mapping operations generally use INVLPG for one virtual page. Multi-CPU invalidation is a separate protocol because a PTE update in memory does not erase translations already cached in another CPU's TLB.
Concurrency and lock ordering
All core page-table traversal and mutation uses mm_lock.
mm_enter is not a plain spin loop: while waiting, it polls the TLB runtime before trying the lock again. This matters because a CPU waiting for MM state must still be capable of participating in an outstanding TLB protocol rather than becoming a non-responsive participant.
The remote shootdown implementation intentionally does not hold mm_lock while waiting for acknowledgements. Its own comment records the deadlock reason: an interrupt on the same CPU could need to map a page, spin forever on mm_lock, and prevent the acknowledgement wait from resuming.
Thus the current synchronization design separates:
- mm_lock for page-table data-structure consistency;
- mm_tlb_busy for serializing publication of shootdown operations;
- the TLB runtime protocol for cross-CPU invalidation and safe frame reuse.
Complexity and memory cost
A four-level 4 KiB page-table walk has constant architectural depth: at most four table lookups.
For software operations:
| Operation | Current asymptotic cost |
|---|---|
| map one 4 KiB page | O(1), fixed four-level walk |
| translate one address | O(1), fixed-depth walk |
| unmap one 4 KiB page | O(1), fixed-depth walk |
| clone kernel top level | O(256) entry copies |
| destroy user table hierarchy | O(number of present user intermediate entries) |
| local INVLPG for one page | O(1) architecturally, hardware cost varies |
| range invalidation | O(number of pages in the range) plus remote coordination |
Memory overhead is sparse. A new mapping can require up to three new intermediate page-table pages plus an already-existing PML4, although neighboring mappings reuse tables. The worst-case sparse overhead is therefore much larger than a densely populated region, while dense sequential mappings amortize each table page across many leaves.
Validation evidence
mm_selftest currently exercises two useful properties:
- a newly allocated PMM frame can be mapped at MM_TEST_VIRT and observed coherently through both the new virtual alias and the HHDM alias;
- the LAPIC physical page can be mapped through map_mmio_page and read through the resulting virtual address.
mm_init also treats successful translation of the boot framebuffer as a required invariant.
These checks demonstrate selected mapping and translation paths. They are not exhaustive validation of every permission combination, huge-page interaction, OOM rollback state, or multiprocessor invalidation race.
Current limitations
The current implementation is intentionally smaller than a production virtual-memory subsystem.
It does not currently provide:
- five-level paging;
- page-table allocation rollback transactions;
- transparent huge-page creation or splitting;
- PCID-aware address-space switching;
- copy-on-write;
- file-backed mappings;
- swap or page replacement;
- NUMA-aware page placement;
- generalized VMAs;
- a reusable MMIO virtual-window allocator;
- complete per-mapping lifetime metadata inside MM itself.
The existing process layer also uses fixed-size page ownership arrays rather than a scalable virtual-memory-area structure.
These are limitations of the present implementation, not claims about what the x86-64 architecture can support.
Revision boundary
This chapter was reconciled against ChrisOS main revision e05a17fd76333114a3fb5c2452f38ca747d4ac56.
At that revision, current behavior is defined by the source paths and symbols in the frontmatter. Future plans should not be read backward into this description. If MM, process ownership, the TLB protocol, or the boot paging contract changes, this chapter must be re-reviewed against the new source revision.