
CLVM JIT architecture and native execution
About this chapter ChrisC and CLVM execution
In this chapter
- CLVM JIT architecture and native execution
- Scope
- Architectural character
- Public entry point
- Launch integration
- Compilation is serialized
- Initial structural scan
- Large-image fallback
- Current truncated-instruction validation gap
- Native code buffer sizing
- x86-64 execution ABI
- Emitter design
- Translation coverage
- Helper path
- Helper-call instrumentation
- Five CLVM opcodes are not implemented by the current JIT helper
- Bytecode-PC to native-offset table
- Indirect dispatch
- Direct branch patching
- Operand stack model
- Call stack model
- Runtime helper stack width
- Native integer arithmetic
- Division correctness gaps
- Floating-point path
- Memory operations
- BAD_ADDRESS fault-PC mismatch
- Other generic-fault collapses
- PRINT semantic difference
- Safepoints
- Safepoint scheduling difference
- Budget model
- Missing executed counter
- VM state transitions
- Helper ABI and native stack alignment
- Syscall context is per CPU
- Compilation-time GC polling
- Hot-reload incompatibility in the current pipeline
- Code-cache lifetime
- Failure behavior
- Complexity
- Cache behavior
- Benchmark evidence
- Native-path validation evidence
- Missing differential cases
- Security boundary
- Current limitations
- Roadmap boundary
- Source map and revision
Scope
The CLVM JIT translates CLV bytecode into x86-64 machine code at application launch.
It is not a tracing JIT, a tiered optimizer, or a profile-guided compiler. The current implementation eagerly translates an entire eligible CLV image before execution and then keeps one native code buffer attached to the application slot.
The execution path is:
CLV image
  |
  v
structural scan
  |
  +---- ineligible ----> interpreter wrapper
  |
  v
native instruction emission
  |
  +---- unsupported-native opcode ----> runtime helper call
  |
  v
bytecode-PC -> native-offset table
  |
  v
branch patching
  |
  v
executable mapping
  |
  v
JitFn(vm, budget, now)
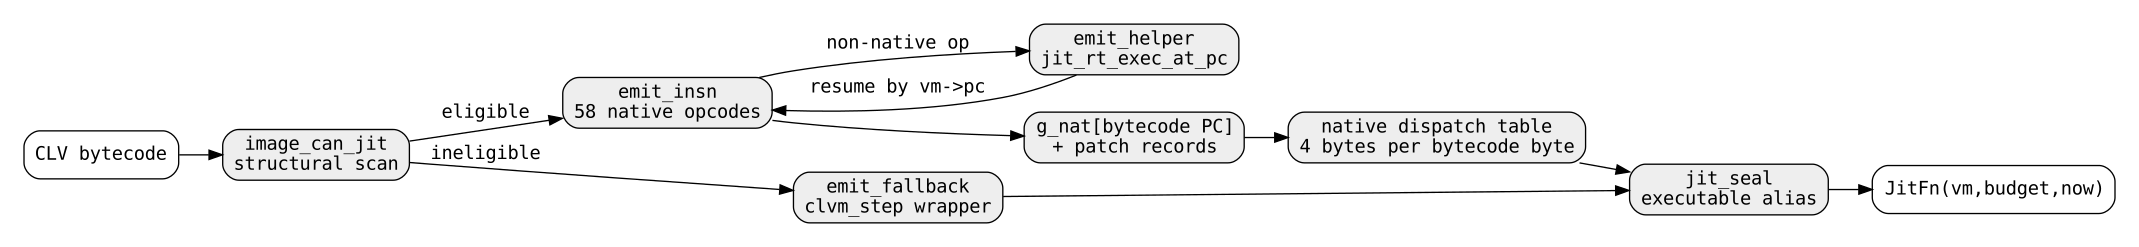
Executable-memory allocation, W/X aliases, TLB publication and reclamation are documented separately in Executable memory, JIT aliases and W^X. This chapter concentrates on translation, dispatch, VM-state preservation, helper fallback, scheduling semantics and correctness.
Architectural character
The JIT is best described as a direct bytecode-to-x86-64 translator with helper fallback.
There is no intermediate SSA graph, optimization pipeline, register allocator, hot-loop detector or speculative specialization layer between CLVM and machine code.
Instead:
- common CLVM opcodes are emitted directly as fixed x86-64 sequences;
- less common opcodes call a C runtime helper;
- direct bytecode branches become patched native branches;
- indirect control flow returns through a native dispatch table indexed by bytecode PC;
- VM stacks and memory remain in the original ClvmVm representation.
This preserves a relatively small semantic gap between the interpreter and native engine, but direct emission means every native opcode implementation must reproduce interpreter behavior explicitly.
Public entry point
The generated function type is:
ClvmStepResult (*JitFn)(
    ClvmVm *vm,
    uint32_t budget,
    uint32_t now
);
The normal application scheduler calls the function through the slot:
slots[i].jit_fn(&slots[i].vm, budget, now)
The current generated code uses the first two arguments.
The now argument exists in the JitFn ABI but is not consumed by the emitted entry sequence at the documented revision.
Time-related syscalls can still obtain system time through their host implementations, but now itself is not a native-code local.
Launch integration
lang_run_internal initializes the ClvmVm and guest backing first.
When debugging is disabled and global no-JIT mode is not active, it attempts:
jit_compile_image(&image, &slot.jit, &slot.jit_fn)
On success:
slot.use_jit = 1
On compilation failure:
slot.use_jit = 0
slot.jit_fn = NULL
and normal execution falls back to clvm_step.
Debug mode deliberately retains the interpreter because source stepping, breakpoint handling and single-instruction execution are implemented around interpreter semantics.
Compilation is serialized
jit_compile.c contains process-global compilation scratch:
g_nat[JIT_MAX_PCS]
g_psite[JIT_MAX_PATCH]
g_ptgt[JIT_MAX_PATCH]
g_npatch
g_fault_ba
g_call_ovf
Therefore jit_compile_image wraps the actual compiler in:
spin_lock(&g_jit_compile_lock)
jit_compile_image_locked(...)
spin_unlock(&g_jit_compile_lock)
Only one native image can be compiled at a time.
Runtime execution of already-generated code is not serialized by this compile lock.
Scratch-space cost
The fixed limits are:
JIT_MAX_PCS   = 1,048,576
JIT_MAX_PATCH = 131,072
g_nat stores one uint32_t per possible bytecode byte, consuming approximately 4 MiB.
The two patch arrays together consume approximately another 1 MiB.
This is static compiler scratch, independent of each application's generated-code allocation.
The design trades memory for simple O(1) bytecode-PC lookup during compilation.
Initial structural scan
image_can_jit scans the code region from bytecode PC zero.
For each opcode it calls insn_len, which assigns a nominal encoded length.
Examples:
| Opcode family | Nominal length |
|---|---|
| no immediate | 1 |
| LDARG/STLOC/LDLOC | 2 |
| JMP/JZ/JNZ/CALL | 3 |
| PUSH / FPUSH | 5 |
| NEWOBJ/LDFLD/STFLD/CALLT/LDSTR | 5 |
| JMP32/JZ32/JNZ32/CALL32 | 5 |
| PUSH64 | 9 |
The scan also rejects native compilation when code_size exceeds JIT_MAX_PCS.
If image_can_jit returns false, the JIT emits a small executable wrapper that calls clvm_step instead of translating the image.
Large-image fallback
CLV permits code images much larger than JIT_MAX_PCS.
The JIT supports those images only through the interpreter-wrapper path.
emit_fallback emits:
native prologue
call clvm_step
native epilogue
and returns that wrapper as JitFn.
As a result, jit_compile_image can report success and the application slot can be marked use_jit even though execution is actually passing through clvm_step.
This is operationally valid but makes use_jit an imprecise observability flag: it means “JitFn installed,” not necessarily “bytecode natively translated.”
Current truncated-instruction validation gap
insn_len checks whether the opcode byte itself is inside code_size, but it does not verify that all immediate bytes implied by that opcode remain inside code_size.
image_can_jit then advances by the nominal length and can accept a final truncated instruction.
For example, a one-byte image containing only CL_OP_PUSH has nominal length five. The scan advances from 0 to 5 and terminates successfully even though the four-byte immediate does not exist inside the logical image.
The native emission path subsequently uses rd_i32/rd_i16 against the source pointer without an independent logical-end check.
Normal compiler-produced CLV images are well formed, but an untrusted malformed image can therefore cause the compiler to read beyond the logical bytecode extent while translating.
The structural scan should require:
pc + instruction_length <= code_size
before accepting each instruction.
A bytecode verifier shared by loader, interpreter and JIT would be a stronger long-term solution.
Native code buffer sizing
Before translation, jit_compile_image_locked estimates:
need = code_size * 64 + 262144
pages = ceil(need / 4096)
The page count is clamped to:
minimum 64 pages
maximum JIT_PAGES = 6144 pages
Thus the normal minimum code allocation is 256 KiB and the maximum is 24 MiB.
This is a sizing heuristic, not a proof.
Every low-level emission still checks JitBuf capacity. If code generation exceeds the buffer or another emission error occurs, native compilation fails and the caller can use the interpreter.
The separate JIT-memory chapter documents the physical/virtual allocation policy.
x86-64 execution ABI
The generated function uses the platform x86-64 calling convention expected by the kernel build.
The first argument, ClvmVm*, arrives in the first integer argument register.
The prologue copies that pointer into RBX:
REG_VM = 3
where register index 3 corresponds to RBX in the emitter's encoding scheme.
RBX then acts as the fixed base register for ClvmVm field access.
The second argument, budget, is saved in a stack local at RBP-16.
The generated prologue reserves three eight-byte locals and saves RBX.
Native sequences access VM fields using compile-time offsetof values such as:
JIT_OFF_PC
JIT_OFF_STATE
JIT_OFF_STACK
JIT_OFF_SP
JIT_OFF_MEM
JIT_OFF_MSZ
JIT_OFF_CALLS
JIT_OFF_CSP
JIT_OFF_FAULT
JIT_OFF_FPC
This makes the generated code tightly coupled to the exact ClvmVm C layout used at compilation time.
There is no stable binary ABI between arbitrary JIT binaries and a differently laid-out ClvmVm; native code exists only for the running kernel image.
Emitter design
jit_emit.c is a small purpose-built x86-64 encoder.
It emits only the instruction forms required by the translator, including:
- register-immediate moves;
- register-register moves;
- arithmetic;
- comparisons/tests;
- conditional and unconditional relative jumps;
- indirect native calls;
- prologue/epilogue sequences;
- fixed-displacement ClvmVm loads/stores.
The JIT does not use an external assembler.
Bytes are written directly into JitBuf through jit_emit.
This keeps the dependency surface small but means encoding correctness is owned by the project.
Translation coverage
CLVM currently defines 72 opcodes.
native_op marks 58 of them for direct x86-64 emission.
The remaining 14 take the helper path.
Directly emitted classes
Native emission includes:
- PUSH/PUSH64;
- integer arithmetic and bitwise operations;
- signed and unsigned comparisons;
- shifts;
- NEG/NOT;
- DUP/DROP/SWAP;
- 8/32/64-bit memory load/store;
- FPUSH and core float arithmetic;
- integer/float conversion;
- direct and indirect branch/call/return;
- HALT;
- SAFEPOINT.
Helper-routed opcodes
The 14 non-native entries are:
PRINT
SYS
FNEG
FEQ
FLT
FLE
LDARG
STLOC
LDLOC
NEWOBJ
LDFLD
STFLD
CALLT
LDSTR
A helper-routed opcode is not automatically equivalent to “supported by the JIT,” because the runtime helper must also implement it.
Helper path
emit_helper writes the current bytecode PC into vm->pc, aligns the native stack, preserves RBX defensively and calls:
jit_rt_exec_at_pc(vm)
jit_rt_exec_at_pc:
- increments the global helper-call counter;
- validates vm->pc;
- fetches one bytecode opcode;
- advances vm->pc;
- executes that opcode through jit_rt_exec_op.
The generated code then checks VM state.
If the helper faulted, waited or halted, the JIT returns the corresponding ClvmStepResult.
Otherwise execution re-enters the native dispatch mechanism at the updated vm->pc.
Helper-call instrumentation
jit_rt_reset_stats and jit_rt_helper_calls expose a global count of helper executions.
test_jit_native uses this instrumentation to verify that a simple integer loop and a simple floating-point program execute with zero helper calls.
The counter is diagnostic global state, not per-VM accounting.
Concurrent JIT execution would therefore mix helper statistics from different VMs.
Five CLVM opcodes are not implemented by the current JIT helper
Although NEWOBJ, LDFLD, STFLD, CALLT and LDSTR are classified as non-native and therefore routed to jit_rt_exec_at_pc, jit_rt_exec_op does not contain cases for them at the reviewed revision.
They fall into the helper default and produce CLVM_FAULT_OPCODE.
The interpreter does implement these five opcodes.
Therefore a CLV image using the IL/object-oriented instruction subset can pass image_can_jit, receive a native JitFn, and later fault when execution reaches one of those operations.
This is a concrete interpreter/JIT coverage gap.
The JIT should either:
- implement the five operations in the helper;
- emit them natively;
- or reject such images during image_can_jit so the whole image uses the interpreter wrapper.
Bytecode-PC to native-offset table
The compiler records:
g_nat[bytecode_pc] = native_offset
only at instruction starts.
After native instruction emission it appends a table containing one uint32_t entry for every byte in the bytecode image.
Operand bytes and other non-instruction-start positions remain zero.
The resulting table consumes:
4 * code_size bytes
inside the generated JIT buffer.
For a one-megabyte eligible CLV image, the dispatch table alone is approximately four MiB.
Indirect dispatch
The generated dispatch stub:
- loads vm->pc;
- rejects pc >= code_size;
- indexes the native-offset table by bytecode PC;
- rejects a zero entry;
- adds the native blob base;
- jumps to that native address.
This serves two roles.
First, CALLI and RET can dynamically transfer using bytecode PCs.
Second, a target into the middle of an immediate field is rejected because its dispatch-table entry is zero.
The table is therefore both a translation map and a coarse instruction-boundary validity map.
Direct branch patching
Direct JMP/Jcc/CALL instructions cannot know their final native displacement while their source instruction is first emitted.
The compiler stores patch records:
g_psite[n] = native_rel32_site
g_ptgt[n]  = target_bytecode_pc
After every bytecode instruction has a native offset, the patch phase verifies:
target < code_size
g_nat[target] != 0
and writes the final relative x86 displacement with jit_patch_rel32.
The fixed patch capacity is 131,072.
An image producing more patch sites fails native compilation.
There is no growable patch vector.
Operand stack model
The JIT does not map the CLVM operand stack to a long-lived native register stack.
Each native operation accesses:
vm->stack
vm->sp
through RBX-relative memory.
Helpers such as emit_pop_rax and emit_pop_rdx load and decrement the VM stack pointer and move stack values into scratch registers.
emit_push_rax checks CLVM_STACK_MAX and writes the result back to the VM stack.
This is less aggressive than register-stack caching, but it has advantages:
- helper transitions see coherent VM state;
- debugger/fault reporting sees the same stack structure;
- indirect dispatch does not require reconstructing hidden native stack state;
- native and interpreted execution can share one ClvmVm representation.
The cost is additional memory traffic around each stack operation.
Call stack model
Direct CALL/CALL32 native sequences keep the CLVM call stack in:
vm->calls[]
vm->csp
rather than mapping source calls to native x86 CALL/RET pairs.
A CLVM call stores the next bytecode PC into vm->calls and branches to the translated target.
RET removes a bytecode return PC and re-enters the dispatch table.
CALLI similarly pops an absolute bytecode target, validates it against code_size, stores the bytecode return address and dispatches by vm->pc.
This design preserves the CLVM call-stack representation across interpreter and JIT modes.
Runtime helper stack width
The core ClvmVm stack is 64-bit.
However, jit_rt_push and jit_rt_pop use int32_t interfaces.
The helper-routed LDARG/LDLOC/STLOC path therefore truncates values to 32 bits even though il_arg and il_loc are int64_t arrays.
For the current ChrisC paths that mainly use the ordinary CLVM stack model this may not surface frequently, but the IL-style VM subset does not have full 64-bit semantic parity in the helper runtime.
A helper API using int64_t consistently would remove this discrepancy.
Native integer arithmetic
ADD, SUB, MUL, bitwise operations, shifts and comparisons are emitted directly as 64-bit x86 operations.
This matches the main interpreter's 64-bit operand-stack model more closely than the older 32-bit helper arithmetic functions.
Unsigned divide/mod use the hardware DIV instruction.
Signed divide/mod use IDIV.
The direct translation is fast, but fault handling is currently not semantically equivalent to the interpreter.
Division correctness gaps
The interpreter defines explicit VM faults:
division by zero       -> CLVM_FAULT_DIV_ZERO
INT64_MIN / -1         -> CLVM_FAULT_DIV_OVERFLOW
The native signed DIV/MOD path behaves differently.
For a zero divisor it branches to a local path that sets the result register to zero and pushes zero.
It does not raise CLVM_FAULT_DIV_ZERO.
The path also does not precheck INT64_MIN / -1 before executing x86 IDIV.
On x86-64 that overflow condition can raise a processor divide exception rather than a contained CLVM fault.
The unsigned UDIV/UMOD path checks zero but branches to the generic fault stub, whose current fault type is CLVM_FAULT_STACK_UNDERFLOW rather than CLVM_FAULT_DIV_ZERO.
These are concrete fault-containment mismatches.
Native divide should branch to dedicated JIT stubs for DIV_ZERO and DIV_OVERFLOW before issuing hardware division.
Floating-point path
FADD, FSUB, FMUL and FDIV are emitted with scalar SSE instructions after moving the low 32-bit float representation into XMM registers.
ITOF and FTOI are also emitted directly.
FNEG and float comparisons currently use the helper runtime.
FDIV zero mismatch
The interpreter and jit_rt_fbinop explicitly detect a floating divisor equal to 0.0 and raise CLVM_FAULT_DIV_ZERO.
The direct native FDIV sequence does not perform this precheck.
With ordinary masked SSE exception state, hardware division can produce IEEE infinity rather than the VM fault expected by the interpreter.
Thus FDIV native behavior is not currently identical to interpreter behavior.
Float stack upper bits
Interpreter float results are commonly converted through int32_t before being stored in the 64-bit VM stack slot, producing sign extension for bit patterns with bit 31 set.
The native FADD/FSUB/FMUL/FDIV sequence moves the result into EAX, which clears the upper 32 bits of RAX before emit_push_rax stores the full 64-bit register.
For later float operations only the low 32 bits matter.
Raw CLVM bytecode that observes the entire 64-bit stack slot through integer operations can nevertheless distinguish the two representations.
This is another reason semantic differential tests should include mixed float/integer bytecode, not only source programs with type-correct float use.
Memory operations
LOAD/STORE, LOADB/STOREB and LOAD64/STORE64 are emitted natively.
The JIT obtains vm->memory and vm->mem_size from ClvmVm.
emit_bounds performs range checking before native dereference.
The implementation is designed for CLVM's current 32-bit-like guest offsets and explicitly clears high pointer bits before checking.
Normal process-backed guest memory is much smaller than four GiB, so this model matches current applications.
The memory chapter documents the guest backing itself.
BAD_ADDRESS fault-PC mismatch
The native bounds-failure stub g_fault_ba does set:
fault = CLVM_FAULT_BAD_ADDRESS
but it writes fault_pc from EAX.
At the point a load/store reaches the bounds check, EAX/RAX contains the guest address being tested, not the bytecode opcode PC.
The interpreter records the bytecode instruction PC in fault_pc.
Therefore JIT BAD_ADDRESS diagnostics currently report an address-like value in fault_pc instead of the source opcode location.
The fix is to emit the known bytecode PC into the fault stub path or maintain separate address/opcode registers.
Other generic-fault collapses
Several native error paths branch to the single fault stub created at compile time.
That stub is initialized as CLVM_FAULT_STACK_UNDERFLOW.
This is correct for operand-stack underflow, but not for every caller.
Examples include:
- invalid CALLI target;
- RET with empty call stack;
- invalid dispatch-table PC/entry;
- UDIV/UMOD zero.
The interpreter has more specific BAD_JUMP, CALL_UNDERFLOW, PC and DIV_ZERO faults.
Consequently native JIT execution can report the wrong fault class even when it successfully contains the error.
Dedicated per-fault stubs would restore diagnostic parity.
PRINT semantic difference
Interpreter PRINT removes the top stack value and records it in the VM print ring through note_print.
The JIT helper implementation currently only pops the value.
It does not update print_ring/print_n.
Therefore debugging/diagnostic history produced by PRINT differs between engines.
This is observable state and should be covered by differential tests.
Safepoints
CL_OP_SAFEPOINT has dedicated native emission.
The generated sequence:
- sets vm->safepoint = 1;
- loads vm->on_safepoint;
- calls it when non-null;
- restores preserved registers;
- clears vm->safepoint.
The helper-call frame includes explicit stack alignment because callbacks can execute code requiring ABI-compliant alignment.
This supports the GC polling callback installed by lang_pipeline.
Safepoint scheduling difference
The interpreter performs an additional freestanding proc_slice_due check after CL_OP_SAFEPOINT and can yield immediately.
The native SAFEPOINT sequence calls on_safepoint but does not perform the corresponding scheduler check.
Also, the interpreter sets vm->safepoint = 1 on several call/object operations, while direct native CALL/CALL32/CALLI sequences do not reproduce every one of those state updates.
The explicit SAFEPOINT opcode still invokes the callback, but safepoint state/scheduling is not fully identical across engines.
Budget model
The interpreter decrements its budget effectively once per decoded opcode because clvm_step's loop iteration corresponds to one instruction.
The JIT does not do that.
The generated function stores budget in a native stack local and decrements it only for a backward unconditional JMP/JMP32 target.
If that counter reaches zero, it stores the loop target in vm->pc and returns CLVM_STEP_SLICE.
This is a backedge budget, not an instruction budget.
Consequences
Typical ChrisC while loops normally contain an unconditional backward edge, so they encounter the check.
However:
- a long straight-line native region can exceed the nominal budget without slicing;
- a loop encoded only with a backward conditional JZ/JNZ does not consume this counter;
- helper-heavy paths have no general per-op budget decrement;
- the meaning of “budget = N” differs materially from clvm_step.
This is an important scheduler contract difference.
A robust JIT should define a budget unit explicitly and enforce it on every loop backedge at minimum, including conditional backedges, or maintain an instruction/estimated-cost counter.
Missing executed counter
The interpreter increments:
vm->executed
for every fetched opcode and uses the counter for periodic process-slice checks.
The native JIT does not update vm->executed for directly emitted instructions.
Therefore the field is not an engine-independent count of executed CLVM instructions.
Diagnostics or policies using vm->executed must account for execution mode.
VM state transitions
The interpreter explicitly enters CLVM_RUNNING and restores CLVM_READY after a normal slice.
Generated native code mainly preserves the incoming state and writes state only for special outcomes such as HALTED or FAULTED.
Its entry block explicitly recognizes WAITING and HALTED, but does not provide the same early FAULTED return contract as clvm_step.
The normal lang_tick path tears down a VM immediately after JIT fault, so re-entering a faulted application is not expected there.
Still, the public JitFn behavior is not a byte-for-byte state-machine clone of clvm_step.
Helper ABI and native stack alignment
emit_helper preserves RBX even though RBX is normally callee-saved in the system ABI.
The source comment records that freestanding helper/syscall code historically clobbered it.
The helper also subtracts eight bytes before the native call to preserve 16-byte stack alignment.
This is important for helper functions that can execute SSE code, including graphics paths.
A stack misalignment here can escalate a VM-level helper call into a CPU exception.
Syscall context is per CPU
Before calling the JIT from lang_tick, ChrisOS executes:
jit_set_sys_context(&vm, &gfx)
jit.c stores the pair in:
g_jit_ctx[SMP_CPU_CAP]
indexed by smp_current_cpu.
This replaced the unsafe design of one global syscall context where a VM running on one CPU could overwrite the context used by another CPU.
The current per-CPU design prevents that specific cross-CPU race.
The generic current JIT helper path normally reaches vm->sys directly, while jit_sys_trampoline remains available as the context-based bridge.
Compilation-time GC polling
While emitting a large image, jit_compile_image_locked calls gc_poll whenever emitted bytecode progress crosses a 64 KiB boundary condition.
This is compile-time cooperation, not runtime bytecode safepoint execution.
It prevents a large native compilation from becoming completely invisible to the GC/service loop for the full compile duration while the global compile lock is held.
Hot-reload incompatibility in the current pipeline
lang_hot_reload reparses the CLV file, rewrites the slot file buffer and reinitializes ClvmVm against the new image.
At the reviewed revision it does not:
- free the previous JitBuf;
- re-run jit_compile_image;
- replace slot.jit_fn;
- disable slot.use_jit.
Therefore a slot that was running through JIT can retain native code generated for the previous bytecode image after hot reload changes vm->code to the new image.
That creates a stale-code hazard.
Native direct instructions still embody old constants, old branch layout and old bytecode-to-native table data, while helper calls may inspect the newly installed vm->code.
Hot reload should either atomically compile and publish a new JIT buffer or force the reloaded slot back to interpreter mode until recompilation completes.
Code-cache lifetime
For ordinary slot shutdown, lang_kill calls jit_free when the slot owns JIT physical memory.
The executable memory chapter documents unmapping, TLB shootdown and quarantine behavior.
There is no cross-application persistent native code cache.
A newly launched application recompiles its image even if an identical CLV was translated previously.
This favors simple ownership over reuse.
Failure behavior
Native compilation can fail because of:
- physical/JIT virtual allocation failure;
- generated buffer exhaustion;
- more than JIT_MAX_PATCH patches;
- invalid direct target discovered during patching;
- emission failure;
- unsupported structural size for native translation.
Not all failures have the same fallback path.
If image_can_jit rejects the image, jit_compile_image may still succeed by installing the interpreter wrapper.
If native emission fails later, jit_compile_image frees the JitBuf and returns -1; lang_pipeline then directly disables JIT and uses clvm_step.
Complexity
Let:
B = bytecode size in bytes
I = decoded instruction count
P = number of direct branch/call patches
Compilation performs:
- structural scan: O(I), bounded by O(B);
- native emission: O(I) plus emitted-byte writes;
- dispatch-table emission: O(B);
- patching: O(P).
Memory includes:
- approximately 5 MiB fixed global translation scratch;
- generated native code;
- a 4B-byte native-offset dispatch table;
- executable-memory allocator metadata.
The compiler has no expensive graph optimization passes.
Its principal costs are linear scanning, byte emission and code-memory allocation.
Cache behavior
Direct native translation removes repeated interpreter opcode decoding and switch dispatch.
The cost shifts toward:
- VM stack loads/stores;
- branch prediction in generated control flow;
- helper transitions;
- the bytecode-PC dispatch table for indirect control flow;
- instruction-cache footprint of expanded native code.
Because the translator can expand one bytecode instruction into tens of x86 bytes, native code has substantially larger instruction footprint than the CLV stream.
The code-size heuristic assumes up to roughly tens of bytes per opcode plus fixed space.
Benchmark evidence
tools/test_jit_bench builds an infinite pixel loop and compares interpreter and JIT execution.
Its configured acceptance threshold is:
MIN_SPEEDUP = 5.0
for that microbenchmark.
The test is useful evidence that the intended native path avoids interpreter overhead on a graphics-oriented loop.
It is not a general claim that all ChrisOS workloads are at least five times faster.
Helper-heavy, syscall-heavy, memory-bound and cache-sensitive programs can have different speedups.
Native-path validation evidence
tools/test_jit_native compiles:
- an integer while loop;
- a basic floating-point arithmetic program.
It resets the helper counter and requires both to halt with:
helper_calls == 0
This directly validates that those common operations are emitted natively.
tools/test_jit_vm compares interpreter and JIT execution state on a loop containing wait and also verifies compilation of the Cube sample when present.
tools/test_doom_jit_diff performs differential interpreter/JIT work on a larger generated workload.
These tests are useful but do not exhaustively cover every opcode/fault combination.
Missing differential cases
The current source inspection identifies several cases that deserve explicit interpreter-versus-JIT regression tests:
- signed DIV/MOD by zero;
- signed INT64_MIN / -1;
- UDIV/UMOD by zero;
- FDIV by positive and negative zero;
- BAD_ADDRESS fault_pc;
- RET underflow fault class;
- invalid CALLI target fault class;
- invalid dispatch PC;
- PRINT ring updates;
- 64-bit IL locals/arguments;
- NEWOBJ/LDFLD/STFLD/CALLT/LDSTR under JIT;
- backward conditional-loop budget exhaustion;
- straight-line budget exhaustion;
- safepoint scheduler yield;
- hot reload while use_jit is active;
- malformed truncated immediate during native compilation.
Without those cases, broad “interpreter/JIT equivalence” should be treated as an engineering goal rather than a proven property.
Security boundary
JIT compilation runs in the kernel and parses guest-provided bytecode into executable machine instructions.
That makes the translator part of the kernel trust boundary.
A bug in the interpreter often results in a contained ClvmFault.
A bug in emitted x86 code can instead execute an invalid kernel memory access or CPU exception directly.
The division-overflow case and truncated-immediate scan illustrate why native translators require stricter validation than an ordinary bytecode switch.
The JIT should ideally consume only verified bytecode.
Current limitations
At the documented revision:
- the JIT targets x86-64 only;
- compilation is whole-image and eager, without profiling/tiering;
- global scratch serializes compilation;
- native translation is limited to code_size <= 1 MiB;
- larger/ineligible images receive an interpreter wrapper while the slot may still be labeled use_jit;
- insn_len/image_can_jit do not reject truncated immediates rigorously;
- 58 of 72 opcodes are directly emitted;
- five helper-routed object/IL opcodes are not implemented by jit_rt_exec_op and fault under JIT;
- helper LDARG/LDLOC/STLOC paths truncate 64-bit values to 32 bits;
- native signed/unsigned division fault behavior differs from the interpreter;
- native FDIV lacks the interpreter's zero-divisor VM fault;
- several native failures collapse to CLVM_FAULT_STACK_UNDERFLOW;
- BAD_ADDRESS fault_pc records the tested address rather than the opcode PC;
- PRINT does not update the interpreter print ring;
- native float results can differ in upper 32 stack bits;
- budget is a partial backedge counter rather than an instruction budget;
- conditional backward branches are not budget-accounted by the dedicated check;
- vm->executed is not incremented for directly emitted instructions;
- JIT safepoint scheduling/state is not fully identical to interpreter behavior;
- hot reload does not rebuild or disable stale native code;
- no persistent cross-slot native code cache exists;
- strict executable-memory W^X is not yet achieved, as documented in jit-memory.
Roadmap boundary
A stronger CLVM JIT can evolve in several independent directions:
- verify the entire bytecode image before native emission;
- generate opcode metadata from one CLVM schema;
- make every interpreter fault have a dedicated native equivalent;
- complete all 72 opcodes or reject unsupported subsets before compilation;
- unify 64-bit helper stack semantics;
- define an engine-independent budget/safepoint contract;
- maintain vm->executed consistently;
- add comprehensive differential fuzzing between interpreter and JIT;
- rebuild JIT code atomically during hot reload;
- replace fixed global scratch with per-compilation state;
- add a reusable code cache keyed by image identity/revision;
- introduce an IR only if optimization goals justify the added complexity;
- add tiering/profile-guided optimization only after semantic parity is strong;
- harden executable-memory publication to strict W^X.
These items are roadmap directions, not current implementation claims.
Source map and revision
compiler/jit/jit_compile.c owns bytecode scanning, native coverage classification, x86-64 instruction selection, branch patch records, native dispatch-table construction and compile locking.
compiler/jit/jit_emit.c is the low-level x86-64 byte emitter.
compiler/jit/jit_runtime.c implements helper execution and JIT/runtime bridge behavior.
compiler/jit/jit.c owns native code memory, executable publication and per-CPU syscall context.
compiler/lang_pipeline.c selects JIT versus interpreter execution, installs runtime context, invokes JitFn and tears code down with the application slot.
compiler/clvm/clvm_vm.c remains the semantic reference engine used for comparison.
All current-behavior claims in this chapter were reconciled against ChrisOS revision e05a17fd76333114a3fb5c2452f38ca747d4ac56.