
Interrupts and symmetric multiprocessing
About this chapter Concurrency and ownership
In this chapter
- Interrupts and symmetric multiprocessing
- Scope
- Interrupt classes
- IDT construction
- ISR normalization
- General-register and SIMD preservation
- PIC initialization
- IRQ dispatch
- End-of-interrupt behavior
- Interrupt-storm protection
- PIT and scheduling signal
- Local APIC role
- Fixed IPI delivery
- IOAPIC status
- SMP limits
- BSP startup sequence
- Limine MP handoff
- AP stack allocation
- AP entry and CR3
- Stack-switch ABI hazard
- AP-local initialization
- Current CPU identity
- Software CPU index versus LAPIC ID
- Waiting for AP online state
- AP interrupt enablement
- Job queue
- SMP job self-test
- User processes remain BSP-only
- Shared-memory synchronization
- Local interrupt exclusion versus SMP exclusion
- TLB integration
- CPU retirement counters versus exact membership
- NMI path
- Concurrency and memory ordering
- Failure modes
- Validation evidence
- Current limitations
- Revision boundary
Scope
Interrupts and symmetric multiprocessing are tightly coupled because an SMP kernel must handle asynchronous events while several processors execute shared kernel code concurrently.
ChrisOS currently has a deliberately hybrid interrupt architecture:
- external device IRQs are routed through the legacy 8259 PIC path;
- those PIC lines remain BSP-oriented;
- each CPU can software-enable its local APIC;
- the LAPIC is used for inter-processor interrupts such as the TLB vector 0xF0;
- the IOAPIC implementation is not complete and currently only reports that PIC routing remains active;
- APs execute kernel jobs, but native user-process switching and syscall execution remain BSP-only.
The result is real multicore kernel execution, but not a fully distributed SMP operating-system scheduler.
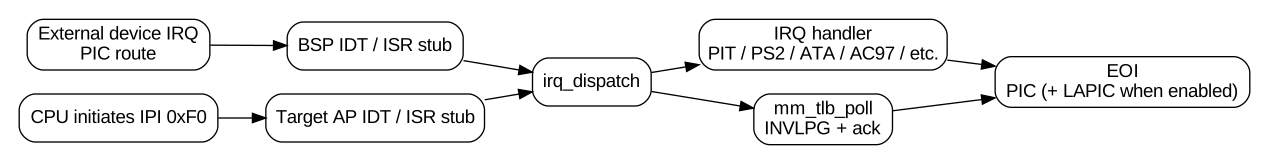
Interrupt classes
Several different architectural events enter privileged code through the vector mechanism.
Exceptions
Exceptions are generated synchronously with instruction execution.
Examples include:
- divide error;
- invalid opcode;
- general protection;
- page fault.
Their meaning is usually tied directly to the instruction that was executing.
Hardware IRQs
Device interrupts are asynchronous from the interrupted instruction stream.
In the current ChrisOS design the programmable interrupt controller maps the legacy hardware lines to vectors:
Inter-processor interrupts
An IPI is generated intentionally by one CPU and delivered to another CPU through the local APIC infrastructure.
The current concrete ChrisOS use is vector 0xF0 for TLB shootdown progress.
NMI
Vector 2 is installed with a dedicated nmi_entry.
NMI is not blocked by the ordinary IF flag.
ChrisOS contains an NMI-compatible TLB stop path and an apic_ipi_nmi helper, but the active TLB fencing implementation at this revision does not call apic_ipi_nmi. CPU retirement currently relies on the AP worker observing that it has been fenced.
That distinction is important when reasoning about failure recovery.
IDT construction
idt_init allocates 256 gates in a statically aligned IDT.
Normal gates are installed with attribute byte:
which represents a present ring-0 interrupt gate.
Vector 2 is replaced with nmi_entry.
syscall_init later changes vector 0x80 to a user-callable gate through idt_set_user_gate, using:
so ring 3 can invoke that vector.
Every gate currently has:
so normal vector entry and the NMI entry do not switch through an Interrupt Stack Table slot in the current implementation.
The IDT object is shared memory, but IDTR is CPU-local architectural state. The BSP loads it during idt_init; every AP later executes idt_load in ap_c_entry.
ISR normalization
idt_stubs.asm generates stubs for all 256 vectors.
Some x86 exceptions push a hardware error code. The assembly distinguishes those from exceptions and interrupts that do not.
For a vector without a hardware error code, the stub pushes:
For a vector with a hardware error code, it pushes only the vector number because the processor has already placed the error value on the stack.
The current set classified as hardware-error-code vectors includes 8, 10, 11, 12, 13, 14, 17, 21, 29 and 30.
This normalization gives C code one common irq_frame prefix.
General-register and SIMD preservation
isr_common saves the general-purpose register state before calling C.
The irq_frame layout begins with:
The stub also reserves storage for FXSAVE, aligns the save area, executes fxsave before irq_dispatch and fxrstor before returning.
That means an interrupt is not allowed to silently destroy the interrupted code's legacy x87/MMX/SSE architectural state.
The stub executes CLD on entry as well, so C handlers run with the direction flag cleared.
Finally it restores registers, removes vector/error slots and executes IRETQ.
Interrupt entry is therefore an ABI boundary: stack shape, alignment and saved state must agree between assembly and C.
PIC initialization
pic_init begins with CLI, then reprograms both 8259 controllers.
The master is remapped to 0x20 and the slave to 0x28.
The cascade relationship is programmed and all IRQ lines are initially masked.
The handler table is also cleared.
Individual subsystems later install handlers and unmask their required lines.
Examples in the current source include:
- PIT on IRQ 0;
- keyboard on IRQ 1;
- PS/2 mouse on IRQ 12;
- ATA DMA on IRQ 14;
- AC97 on its detected legacy IRQ;
- VirtIO-GPU legacy interrupt handling where applicable.
The external-interrupt model is therefore still explicitly PIC-centric.
IRQ dispatch
irq_dispatch first handles non-PIC special cases.
The order includes:
- syscall vector 0x80;
- page fault vector 14;
- other architectural exceptions below 32;
- TLB IPI vector 0xF0;
- generic high vectors;
- PIC vectors 32..47.
For a PIC vector:
The installed function pointer is called when non-null, then irq_eoi is executed.
This centralized table is simple and fixed at 16 legacy IRQ entries.
There is not yet a general interrupt-domain or dynamically allocated vector subsystem.
End-of-interrupt behavior
irq_eoi currently does two things.
If apic_ready() is true, it sends a LAPIC EOI.
Then it sends the required PIC EOI:
- slave then master for IRQ >= 8;
- master only for IRQ < 8.
Because the system is in a hybrid state, this function acknowledges both mechanisms when LAPIC software-enable is active.
External PIC routing has not been replaced by IOAPIC routing.
Interrupt-storm protection
irq_dispatch maintains irq_hits for the legacy hardware lines.
IRQ 0 is deliberately excluded because it is the 60 Hz timer and masking it would stop desktop timing.
For another IRQ, when the hit counter reaches 10,000, ChrisOS masks the line and logs an irq storm message.
This is a coarse protection against a device line that never deasserts and would otherwise keep re-entering the kernel.
The current mechanism is not a rate estimator: it is a cumulative threshold and it does not automatically re-enable the line.
PIT and scheduling signal
pit_init programs channel 0 using the standard PIT input frequency 1,193,182 Hz.
The current boot requests 60 Hz.
Its handler:
- increments the global ticks counter;
- calls proc_on_tick.
proc_on_tick sets the process slice flag.
It does not perform an arbitrary AP-side user-process context switch from the interrupt handler.
User-process switching remains constrained to CPU 0.
Thus the timer participates in process scheduling state without implying an SMP user scheduler.
Local APIC role
apic_init records the LAPIC virtual mapping created by MM, but initially leaves the software-enable flag off.
apic_enable_local writes the spurious-interrupt vector register:
which enables the local APIC with spurious vector 0xFF.
The source comment explicitly states that this does not move legacy device routing away from the 8259 PIC.
The LAPIC is currently important for:
- local APIC state;
- EOI handling while enabled;
- fixed-delivery IPIs;
- available NMI delivery support.
Fixed IPI delivery
apic_ipi receives a destination LAPIC ID and vector.
It programs the ICR high register with the destination and the low register with the vector and level-assert bit.
It then polls the delivery-status bit for at most 100,000 iterations.
The function returns 0 on delivery completion and -1 on timeout/unavailable LAPIC.
The TLB shootdown caller currently ignores this return value and relies on the higher-level generation/acknowledgement protocol for safety.
IOAPIC status
ioapic_init currently contains no redirection-table programming.
It logs that PIC still routes IRQs and identifies full IOAPIC support as a future stage.
Therefore the current architecture must not be described as an IOAPIC-routed SMP interrupt system.
The LAPIC and SMP code are functional without that claim.
SMP limits
smp.h currently defines:
AP_STACK_PAGES     = 4
AP_STACK_VIRT_BASE = 0xffffffff92000000
AP_STACK_STRIDE    = 0x10000
SMP_MAX_APS        = 8
SMP_CPU_CAP        = 16
There is a naming subtlety.
The valid AP software indices are checked as:
and smp_init stops when next >= SMP_MAX_APS.
Therefore with SMP_MAX_APS equal to 8, the current implementation can assign AP indices 1 through 7: up to seven APs plus the BSP, not eight APs plus the BSP.
SMP_CPU_CAP is larger because other per-CPU arrays, including TLB protocol membership, are sized to 16 slots.
This difference should not be hidden behind the constant name.
BSP startup sequence
kstart initializes interrupt and memory prerequisites before SMP.
A simplified current sequence is:
GDT
IDT
syscall gate
PIC
PIT
PS/2
PMM
MM
heap
SSE
process subsystem
graphics
LAPIC mapping/init
IOAPIC placeholder
job queue
SMP bring-up
SMP job self-test
Later, the kernel explicitly executes CLI before storage/install/language initialization.
After those phases finish:
This delayed release is intentional.
The source records that enabling AP interrupts too early interfered with ATA-copy/install behavior.
Limine MP handoff
smp_init reads the current CR3 into kernel_cr3 and resets cpu_online_count to 1.
If nosmp is requested, it skips AP startup and can still software-enable the BSP LAPIC.
Otherwise it obtains the Limine multiprocessor response.
For non-BSP descriptors it first clears goto_address and extra_argument.
It then establishes software-index/LAPIC-ID mappings and prepares APs one by one.
For every accepted AP it:
- assigns next software CPU index;
- stores the boot-published LAPIC ID;
- allocates an AP stack;
- writes the software index into extra_argument;
- uses a compiler barrier;
- publishes ap_entry through goto_address.
The startup protocol therefore uses Limine's AP handoff instead of implementing INIT/SIPI sequencing directly in ChrisOS.

AP stack allocation
Each accepted AP receives four physical pages mapped into its dedicated virtual stack range.
The mapped stack consumes 16 KiB.
The address stride is 64 KiB, leaving unused virtual separation between AP stack regions.
If PMM cannot allocate a stack page, ChrisOS panics.
The stack is required not only for C execution but also for the current CPU-identity mechanism.
AP entry and CR3
ap_entry first writes kernel_cr3.
That gives the AP the translation root used by the initialized kernel.
It then obtains index/LAPIC information from the Limine structure, with a fallback lookup if needed.
Invalid index or missing stack causes the AP to enter a permanent HLT loop.
The function then moves RSP to the dedicated AP stack and calls ap_c_entry.
Stack-switch ABI hazard
The assembly in ap_entry deliberately reloads the software index into EDI after changing RSP.
A source comment records a previous bug: old frame-pointer/spilled local state survived incorrectly across the stack transition, producing an invalid CPU index and causing APs to answer TLB work as CPU 0.
This demonstrates why changing RSP invalidates ordinary assumptions about a compiler-generated function frame.
The implementation treats the switch as a one-way ABI boundary.
AP-local initialization
ap_c_entry performs:
- idt_load;
- SSE/FPU control initialization through sse_bsp_init;
- CPU identity re-evaluation from the stack;
- LAPIC metadata fallback when needed;
- tlb_runtime_online(index);
- atomic increment of cpu_online_count;
- transition into job_worker_forever.
The AP does not enter a user-process scheduler.
Current CPU identity
smp_current_cpu reads RSP.
If RSP is below AP_STACK_VIRT_BASE, the function reports CPU 0.
Otherwise it computes:
and accepts it only when the index is within the AP range and CPU capacity.
This works because AP steady-state execution, normal interrupt entry and the current NMI entry all use the interrupted AP stack: IDT gates have IST=0.
The method is therefore coupled to stack placement.
If future code uses IST stacks, scheduler stacks, nested alternate stacks or stack migration, CPU identity must move to a more explicit CPU-local mechanism or preserve equivalent metadata.
Software CPU index versus LAPIC ID
The software index is not the hardware APIC destination.
ChrisOS keeps a mapping in g_lapic_of_cpu.
smp_lapic_of returns both the stored ID and a known flag.
This separation is important because:
- per-CPU software arrays use compact indices;
- LAPIC ICR delivery needs the hardware destination ID.
A source comment records a historical failure where reading the shared LAPIC mapping on APs could appear to return the BSP ID and later direct a stop request at the desktop CPU.
The current boot-time mapping prefers Limine-published LAPIC IDs.
Waiting for AP online state
After publishing all accepted APs, smp_init computes want = next.
The BSP waits while:
with PAUSE and a bound of 100,000,000 loop iterations.
Afterward it logs the count and proceeds.
There is no panic merely because the count remained below want when the bound expired.
Therefore partial AP bring-up is possible from the control-flow perspective.
The log is part of the evidence needed to distinguish requested APs from actually online APs.
AP interrupt enablement
AP workers initially run with IF clear.
job_worker_forever checks the global g_ap_irq_enable flag.
After the BSP later calls smp_release_ap_irqs, each AP on a subsequent worker iteration:
- software-enables its LAPIC unless noapic;
- executes STI;
- remembers locally that IRQs were enabled.
This creates two different AP readiness states:
- online for polling and kernel jobs;
- interrupt-enabled.
Those states occur at different points in boot.
Job queue
The job subsystem provides the main AP workload.
JOB_QUEUE_CAP is currently 1024.
A global ring stores function pointer + argument entries.
The queue structure is protected by g_q_lock.
g_inflight and g_completed are updated through atomic_add_u32.
An AP repeatedly:
- handles TLB fencing/polling;
- enables interrupts once released;
- polls TLB state;
- takes one job under the queue lock;
- executes it outside the lock;
- updates counters;
- executes PAUSE and loops.
The BSP can also execute job_worker_once while waiting for work to drain.
This is a cooperative kernel work engine, not a preemptive general task scheduler.
SMP job self-test
smp_job_selftest provides runtime validation when at least two CPUs are online.
It first submits 16 simple increment jobs and verifies all 16 complete.
It then performs 32 waves of 128 jobs and checks the final sum after each wave.
Failure to enqueue within a bounded retry count or an incorrect result causes panic.
This validates important pieces of the runtime:
- shared queue operation;
- locking;
- worker execution;
- atomic completion tracking.
It does not prove every interrupt or memory-ordering property of the SMP kernel.
User processes remain BSP-only
The process subsystem has an explicit invariant:
for proc_switch.
Attempting process switching from an AP panics.
syscall_dispatch also rejects syscall execution off BSP.
Therefore native user applications are not currently scheduled across APs.
Parallel execution currently exists mainly for kernel jobs and facilities layered on those workers.
Shared-memory synchronization
Once APs are online, ordinary memory objects can be touched concurrently.
ChrisOS provides a minimal Spinlock:
- acquire through CAS;
- PAUSE while contended;
- release through __sync_lock_release.
It also provides atomic_add_u32.
Those primitives do not define lock ordering automatically.
Each subsystem still needs a synchronization policy.
Local interrupt exclusion versus SMP exclusion
A spinlock alone can deadlock if interrupt context on the same CPU can acquire the same lock while normal code holds it.
spin.h therefore provides irq_save and irq_restore.
irq_save records RFLAGS and executes CLI.
irq_restore re-enables interrupts only if IF had previously been set.
The PMM demonstrates the pattern:
Disabling local interrupts prevents same-CPU interrupt reentry.
It does not prevent another CPU from entering the protected subsystem.
The spinlock supplies inter-CPU exclusion.
TLB integration
SMP correctness extends beyond ordinary locks.
A CPU can retain a stale translation after another CPU unmaps a shared kernel page.
ChrisOS therefore registers each AP in the TLB runtime and integrates TLB polling with workers and interrupt vector 0xF0.
The full protocol is described in the dedicated TLB shootdown chapter.
A critical current fact is that CPU fencing is cooperative in the active path: a fenced AP detects the state in job_worker_forever, performs the pending invalidation, marks itself halted and enters CLI/HLT forever.
Although NMI support exists, the current shootdown code does not send an NMI when fencing.
CPU retirement counters versus exact membership
smp_retire_cpu atomically decrements cpu_online_count but never below 1.
Its cpu parameter is currently not used to maintain an SMP bitmap.
Therefore cpu_online_count is an aggregate status/scheduling counter.
It is not the exact authoritative TLB membership representation.
The TLB protocol keeps its own per-slot ONLINE/FENCED/ABSENT state.
This separation prevents a simple count decrement from being treated as proof that a stale translation is gone.
NMI path
idt_init installs nmi_entry at vector 2.
The NMI stub runs on the interrupted stack because IST is zero.
It calls mm_tlb_nmi_stop.
That helper polls pending TLB work and marks the CPU halted.
For CPU 0 it returns so the BSP continues.
For an AP it can direct the stub into an infinite CLI/HLT loop.
This support code is real, but it is not currently invoked by the TLB retirement sender.
It should be treated as available mechanism, not current normal escalation.
Concurrency and memory ordering
The code uses:
- GCC __sync atomic builtins;
- volatile state;
- explicit compiler barriers;
- PAUSE spin hints;
- x86 interrupt-control instructions.
On x86-64, the hardware memory model is stronger than on many architectures, but compiler ordering and atomic publication still matter.
A correct SMP explanation cannot be reduced to “x86 does not reorder.”
The project currently has implementation-specific synchronization rather than a formal cross-architecture memory model.
Failure modes
Relevant current failures include:
- no Limine MP response;
- AP count beyond the supported software-index range;
- PMM failure during AP stack allocation;
- corrupt software CPU index;
- incorrect stack-switch assumptions;
- wrong CPU-to-LAPIC destination mapping;
- AP never incrementing cpu_online_count;
- AP interrupts enabled too early;
- legacy IRQ line stuck asserted;
- lock reentrancy from interrupt context;
- cross-CPU lock ordering cycles;
- stale TLB translation after reclamation;
- IPI delivery timeout;
- fenced CPU that never reaches its worker loop.
Several source comments correspond to bugs encountered historically, particularly stack identity, wrong LAPIC destination and early interrupt release.
Validation evidence
Current concrete validation includes:
- smp_job_selftest on a multicore boot;
- tools/test_job_saturate.c for queue-full/drain/reuse behavior;
- TLB protocol host tests in tools/test_tlb_proto.c;
- MM/TLB runtime logs;
- bounded AP startup wait and online-count reporting;
- interrupt-driven PIT desktop timing;
- device IRQ paths through installed PIC handlers.
Further useful tests include:
- verify exact CPU indices and LAPIC IDs on systems with sparse APIC identifiers;
- inject AP startup failure;
- force IPI delivery failure;
- stress same lock from process and interrupt contexts;
- run IRQ storms on non-timer lines and verify masking;
- test AP IF release ordering during storage/install;
- run long TLB shootdown churn while AP workers are saturated;
- validate alternate-stack CPU identity before introducing IST.
Current limitations
At the reviewed revision:
- at most seven AP software indices are admitted in addition to the BSP;
- CPU-array capacity and admitted AP count are not the same limit;
- user processes and syscalls are BSP-only;
- external hardware IRQs remain PIC-routed;
- IOAPIC redirection is not implemented;
- CPU identity depends on AP stack geometry;
- AP workers poll a global queue rather than using a general SMP scheduler;
- cpu_online_count is not an exact per-CPU membership map;
- NMI stop support exists but active TLB fencing remains cooperative;
- panic does not implement a coordinated all-CPU stop protocol;
- there is no CPU hotplug/rejoin lifecycle.
These constraints define the current SMP stage more accurately than a binary “multicore supported” label.
Revision boundary
This chapter was reconciled against ChrisOS main revision e05a17fd76333114a3fb5c2452f38ca747d4ac56.
The source-backed model is:
- shared IDT memory with IDTR loaded per AP;
- PIC-routed legacy device IRQs;
- LAPIC-enabled CPUs and fixed IPIs;
- up to seven AP software indices plus BSP under the current bound checks;
- per-AP kernel stacks used for both execution and CPU identity;
- delayed AP IF enablement;
- global locked kernel job queue;
- BSP-only native user execution;
- explicit TLB membership/coherence separate from cpu_online_count;
- available but currently inactive NMI-send escalation for TLB fencing.
Future IOAPIC routing, process migration, IST adoption, CPU-local identity redesign or scheduler changes require a fresh source reconciliation.