
Buses, memory-mapped I/O and DMA
About this chapter Devices and platform discovery
In this chapter
- Buses, memory-mapped I/O and DMA
- Why devices change the memory model
- A bus is a transaction system
- Address, data and control
- Masters, targets and initiators
- Three address spaces must not be conflated
- Port-mapped I/O
- Memory-mapped I/O
- MMIO memory type
- HHDM is not a universal device mapper
- The ChrisOS MMIO window
- volatile and MMIO
- Access width is part of the protocol
- BARs as device address windows
- BAR sizing arithmetic
- What DMA removes from the CPU path
- DMA descriptors
- Descriptor memory is part of the device protocol
- DMA coherence
- Coherent and streaming DMA
- Ordering and coherence are different
- ChrisOS virtqueue barriers
- VirtIO ORDER_PLATFORM
- Device notification is not payload transfer
- Physical contiguity
- DMA address width
- The DMA32 pool
- Bounce buffers
- ATA DMA in ChrisOS
- PRDT example
- AC97 DMA path
- Modern VirtIO DMA helpers
- DMA ownership and lifetime
- Rings are ownership machines
- DMA and interrupts
- Completion races
- MMIO posted writes
- DMA completion is not necessarily storage durability
- IOMMU
- Scatter/gather
- Cache-line sharing with DMA
- Security boundary
- hwgate as a capability boundary
- Current BAR mapping limits
- Current DMA helper limits
- ChrisVM MMIO model
- Current ChrisVM MMIO granularity
- ChrisVM and DMA
- A future ChrisVM DMA transaction
- Memory model interaction
- Why volatile descriptor is not sufficient
- Mapping device memory into user mode
- Bus errors and fault containment
- Reproducible arithmetic in this chapter
- PCI configuration-address example
- DMA32 boundary example
- Address splitting
- Validation boundaries
- Review triggers
- Primary references
Why devices change the memory model
A processor does not operate in isolation. Storage controllers, network cards, audio controllers, GPUs, USB host controllers, interrupt controllers and firmware-visible platform devices all exchange commands, status and data with software. The path between CPU and device is not ordinary function-call state. It crosses architectural buses and interconnects with their own addressing, transaction, ordering, width and ownership rules.
Three concepts are foundational:
- a bus or interconnect transports requests and responses between agents;
- memory-mapped I/O (MMIO) lets a device expose registers in the processor's physical address space;
- direct memory access (DMA) lets a device read or write memory without the CPU copying every payload word through an I/O register.
ChrisOS already uses all three extensively. PCI configuration discovers devices and their resources. MMIO windows expose modern VirtIO capabilities and the LAPIC. DMA buffers carry ATA blocks, AC97 samples, VirtIO descriptors, network frames and GPU resources.
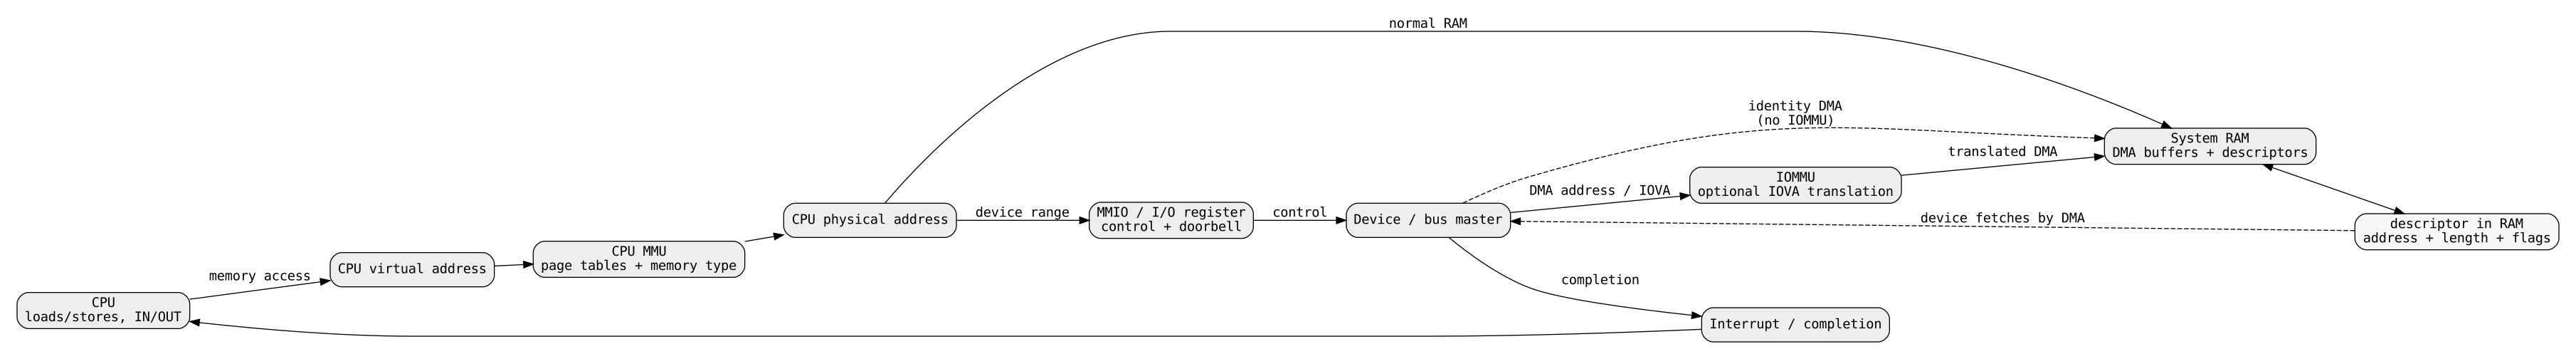
A driver therefore manages two distinct paths:
control path:
CPU -> I/O instruction or MMIO register -> device

data path:
device <-> DMA address -> RAM
Many driver bugs come from confusing those paths.
A bus is a transaction system
The historical word "bus" suggests a shared set of wires, but modern platforms often use switched or point-to-point fabrics. The useful abstraction is a transaction system.
A transaction normally contains some combination of:
- source or requester identity;
- destination or decoded address;
- operation type: read, write, configuration, message;
- transfer width or byte enables;
- payload;
- ordering attributes;
- completion or error status.
Classic front-side buses, PCI, PCI Express, memory controllers and internal SoC fabrics implement these ideas differently.
The CPU does not normally know which transistor-level path reaches a device. Software sees architectural address spaces and ordering contracts.
Address, data and control
A simplified shared bus can be decomposed into:
| Signal class | Purpose |
|---|---|
| address | selects a location or target |
| data | transports the payload |
| command/control | distinguishes read, write, configuration and timing |
| arbitration | chooses which master may initiate a transaction |
| completion/status | reports success, retry or fault |
Real PCIe replaces parallel shared wires with packetized serial links, but the conceptual separation remains valuable.
Masters, targets and initiators
A CPU is not necessarily the only agent capable of initiating memory traffic.
A bus master can start transactions. A DMA-capable PCI device is a bus master when it reads or writes system memory. A target responds to an address or request.
This is why enabling the PCI Bus Master bit matters: without bus-master permission, a controller may expose registers but be prohibited from initiating DMA.
ChrisOS explicitly enables bus mastering for multiple legacy devices. In pci_find_virtio_net, pci_find_ide and pci_find_ac97, the PCI command register is modified before DMA-capable use.
Three address spaces must not be conflated
Low-level software often handles at least three address forms:
- CPU virtual address — the pointer dereferenced by kernel code;
- CPU physical address — the address after page translation;
- DMA or bus address — the address placed into a device descriptor.
On a simple machine without an IOMMU, the DMA address can equal the CPU physical address.
That equality is an implementation property, not a universal identity.
With an IOMMU:
Linux's DMA API makes this distinction explicit: a dma_addr_t is not assumed to be a CPU pointer or even necessarily the same value as a CPU physical address.
Current ChrisOS does not yet expose an IOMMU or IOVA abstraction. Its DMA helpers hand physical RAM addresses directly to devices.
Port-mapped I/O
x86 has a distinct I/O-port address space accessed by instructions such as IN and OUT.
ChrisOS uses it for legacy serial, ATA task-file registers, PCI configuration mechanism #1 through 0xCF8/0xCFC, legacy VirtIO PCI I/O BARs, AC97 I/O BARs and other legacy controllers.
Port I/O is not a normal memory load/store. The instruction explicitly identifies the I/O address space.
For example:
performs PCI configuration access rather than dereferencing RAM.
Memory-mapped I/O
MMIO places device registers into the physical-memory address space.
A CPU load from an MMIO mapping can cause a device register read. A store can cause a command, acknowledgement, doorbell or configuration update.
This makes MMIO syntactically similar to memory while semantically different.
A register can have behaviors impossible for RAM:
- read-to-clear;
- write-one-to-clear;
- write-only;
- side effects on read;
- side effects on specific widths;
- values updated asynchronously by hardware;
- ordering requirements against other registers or DMA memory.
Consequently, MMIO must not be treated as an ordinary cached object.
MMIO memory type
Caching a device-register range as normal write-back memory can be catastrophic. The CPU could satisfy a read from cache instead of reaching the device, combine writes or postpone traffic in ways the device protocol does not permit.
ChrisOS map_mmio_page maps each MMIO page with:
The intent is explicit: writable kernel mapping, execute disabled, and cache-policy bits selected for device mappings.
On x86, however, PWT and PCD alone do not completely define the final memory type on modern processors. Effective type is derived from paging attributes together with PAT and MTRR state. Therefore the precise statement is that ChrisOS requests an uncached-oriented mapping using PWT/PCD; a complete memory-type subsystem would audit PAT/MTRR interaction explicitly.
HHDM is not a universal device mapper
ChrisOS has a Higher-Half Direct Map for RAM. bootinfo_phys_to_virt currently computes:
This is valid only when that physical range is actually represented by the direct mapping with appropriate attributes.
The boot code deliberately warns that HHDM plus the LAPIC physical address is not a valid MMIO mapping and must not be dereferenced.
The LAPIC physical address 0xFEE00000 is device space, not ordinary RAM. ChrisOS instead calls map_mmio_page for it.
This distinction is fundamental:
physical RAM:
phys -> HHDM virtual pointer -> normal RAM access

device MMIO:
phys -> dedicated MMIO page mapping -> volatile register access
Adding an offset is not equivalent to creating the correct page-table and memory-type mapping.
The ChrisOS MMIO window
map_mmio_page allocates one page at a time from a dedicated virtual MMIO window.
The function:
- requires the physical address to be 4-KiB aligned;
- reserves the next virtual page in the MMIO region;
- maps the physical page with writable, non-executable, PWT/PCD attributes;
- returns the new virtual address.
hw_bar_map builds larger device windows by repeatedly calling map_mmio_page on sequential physical pages. Since map_mmio_page advances sequentially, the returned mappings form a contiguous virtual range for that BAR.
The current MMIO allocator is simple and monotonic. There is no unmap/reuse path in hw_bar_map.
volatile and MMIO
hwgate stores a BAR mapping as a volatile byte pointer and reads/writes register widths through volatile pointers.
volatile is necessary at the compiler level so register accesses are not optimized away like ordinary memory. It is not, by itself, a CPU memory fence, a DMA synchronization primitive, an atomic multi-register transaction or a substitute for correct device memory type.
The previous memory-model chapter separates these concerns.
Access width is part of the protocol
A 32-bit device register is not always safely accessible as four 8-bit operations.
Devices may require exact width and alignment. hwgate reflects this by exposing:
and rejecting misaligned 16-bit and 32-bit accesses.
That interface is safer than treating a mapped BAR as an untyped byte array everywhere.
BARs as device address windows
PCI Base Address Registers describe device resources. The next chapter covers PCI/PCIe configuration in detail; here the important abstraction is that a BAR can identify port-I/O space or memory-mapped space.
hw_bar_map rejects I/O BARs and maps memory BARs.
For a memory BAR it:
- reads the raw BAR;
- recognizes 64-bit BAR encoding and reads the upper dword;
- forms the physical base;
- temporarily disables memory-space decoding;
- writes all ones to probe the implemented size mask;
- restores the BAR and command register;
- maps pages into the ChrisOS MMIO window.
This is the point where configuration-space metadata becomes a CPU-usable device-register pointer.
BAR sizing arithmetic
For a conventional naturally sized memory BAR mask, the resource size is obtained by clearing attribute bits, inverting the implemented address mask and adding one.
For example:
hw_bar_map uses the same core arithmetic, but applies project-specific limits:
- an invalid mask falls back to 64 KiB;
- resources smaller than 64 KiB are mapped as at least 64 KiB;
- resources larger than HW_WIN_PAGES × 4096 are capped;
- HW_WIN_PAGES is currently 64, so one window is capped at 256 KiB.
This is adequate for the devices exercised today, not a general-purpose PCI resource manager.
A further limitation is that the size probe is effectively based on the low BAR dword. A fully general 64-bit BAR allocator must handle the complete 64-bit size mask and preserve paired-BAR semantics.
What DMA removes from the CPU path
Without DMA, a storage read might conceptually be:
With DMA:
CPU:
  prepare buffer
  program address + length
  start device

device:
  transfer payload directly to/from RAM

CPU:
  observe completion
The CPU still sets up and synchronizes the operation, but it no longer copies every payload word.
This is essential for high-throughput I/O.
DMA descriptors
A controller needs to know where data lives and how much to transfer. That metadata is often represented by descriptors.
A generic descriptor can contain an address, length, direction/flags, a next-descriptor link and completion ownership.
Different devices encode this differently:
- ATA bus-master IDE uses a PRDT;
- AC97 uses a buffer-descriptor list;
- VirtIO uses descriptor tables plus available/used rings;
- AHCI uses command lists/FIS structures/PRDT entries;
- NVMe uses submission/completion queues and PRP/SGL addressing.
The central pattern is the same: software writes memory that describes future device memory access.
Descriptor memory is part of the device protocol
A common ordering rule is:
1. fill payload
2. fill descriptor
3. make prior memory writes visible
4. publish descriptor/index
5. ring doorbell / notify device
On completion:
1. observe completion index/status
2. order device writes before CPU consumption when required
3. read payload/status
4. recycle descriptor
A queue is therefore both a data structure and a synchronization protocol between CPU and device.
DMA coherence
Two independent questions must be asked.
Address coherence
Can the device reach the address written into the descriptor?
This depends on device address width, bus bridges, IOMMU configuration, DMA masks and reserved low-memory requirements.
Cache coherence
If CPU and device access the same RAM, do CPU caches automatically participate coherently with device traffic?
On many modern x86 platforms, ordinary system-memory DMA is hardware coherent. On other architectures or device arrangements, explicit cache maintenance is required.
Portable driver architecture must not assume that "DMA address is valid" implies "cache visibility is automatic."
Coherent and streaming DMA
A useful systems distinction is:
coherent DMA allocation — CPU and device can exchange control structures without explicit cache clean/invalidate operations for each ownership transfer, although ordering barriers are still required.
streaming DMA mapping — a normal CPU buffer is temporarily handed to a device. On non-coherent systems, ownership transitions can require cache maintenance before and after DMA.
ChrisOS currently allocates ordinary physical pages and relies on the coherent x86/QEMU environment used by the project. It does not expose separate coherent-vs-streaming APIs.
That is an architectural limitation if portability to non-coherent platforms is a goal.
Ordering and coherence are different
Even coherent DMA memory can require a memory barrier.
Coherence means CPU and device eventually agree on the bytes. Ordering answers whether the device is allowed to observe the notification before earlier descriptor writes.
Thus:
VirtIO explicitly specifies ordering requirements around virtqueue publication and notification.
ChrisOS virtqueue barriers
kernel/gfx/virtq.c defines vq_mb. On x86 it emits MFENCE with a compiler memory clobber.
virtq_publish uses barriers around descriptor publication and available-ring index update before later notification performed by the caller.
This makes the intended ownership boundary explicit.
By contrast, the older legacy virtio_net path defines vio_mb as only a compiler barrier.
That is a narrower contract. It has been sufficient for the current x86/QEMU path, but it should not be presented as a general transport barrier for arbitrary hardware or architectures. A mature common VirtIO layer should centralize barriers according to negotiated transport/platform semantics.
VirtIO ORDER_PLATFORM
VirtIO 1.3 distinguishes platform ordering through VIRTIO_F_ORDER_PLATFORM.
When platform ordering is negotiated, the driver must use barriers suitable for the actual platform/device transport.
When it is not negotiated, the specification permits assumptions oriented toward software device implementations and weaker barriers.
This is important for ChrisOS because the project currently moves between QEMU software devices, eventual real PCI hardware and ChrisVM devices implemented by the project itself.
A barrier strategy correct only for QEMU is not automatically a hardware strategy.
Device notification is not payload transfer
A VirtIO notify register or port is a doorbell.
The CPU does not send the whole request through the doorbell. It writes descriptors to DMA-visible RAM, then notifies the device that work is available.
Conceptually:
The device follows the descriptor through DMA.
This distinction is central to high-performance queue design.
Physical contiguity
Some hardware structures require physically contiguous memory. Virtual contiguity is not enough.
ChrisOS hw_dma_alloc calls pmm_alloc_contig and then maps the physical run through the HHDM.
It stores both:
The virtual pointer and physical address refer to the same RAM, but serve different agents.
DMA address width
Legacy devices often cannot address all physical RAM.
A 32-bit DMA engine can address at most:
if no remapper is used.
ChrisOS explicitly reserves a DMA32 pool in pmm_reserve_dma32 and exposes pmm_alloc_dma32 and hw_dma_alloc_low.
The code comment states the current motivation: UHCI requires addresses below 4 GiB in the supported path, while modern VirtIO queues can use higher RAM.
This is exactly why an allocator cannot hand arbitrary physical memory to every device.
The DMA32 pool
pmm_reserve_dma32 searches usable memory for a contiguous run whose end lies below PMM_DMA32_LIMIT.
The allocator then tracks a small bitmap of pages within that reserved run.
This provides deterministic low-address DMA pages rather than hoping the general PMM returns low memory.
For hardware support, every DMA-capable driver should state its addressing mask explicitly. A single "DMA32" pool is useful, but future devices can have other constraints.
Bounce buffers
A bounce buffer is memory that satisfies the device's constraints even if the caller's original buffer does not.
The flow is:
write to device:
caller buffer -> CPU copy -> DMA-safe bounce -> device

read from device:
device -> DMA-safe bounce -> CPU copy -> caller buffer
This costs an extra copy but isolates address/alignment constraints.
ATA DMA in ChrisOS uses a driver-local bounce buffer plus PRDT page.
ATA DMA in ChrisOS
ata_dma_acquire allocates a contiguous 8192-byte-capable payload region and one PRDT page.
It rejects allocations whose physical address exceeds 0xFFFFFFFF.
ata_dma_xfer then:
- copies write data into the bounce buffer when needed;
- writes a PRDT entry containing the DMA physical address;
- writes the PRDT physical address to the bus-master controller;
- clears status;
- programs the ATA command;
- starts the DMA engine;
- waits for IRQ/status completion;
- copies read data back to the caller.
That sequence cleanly separates the API buffer from the device-visible buffer.
PRDT example
The current ATA path stores:
The high bit marks end-of-table in this implementation's PRDT entry.
For 8192 bytes:
The accompanying checker validates this arithmetic.
AC97 DMA path
AC97 allocates one physical page for audio data and one page for its descriptor list.
The BDL stores the payload physical address, and the bus-master register receives the BDL physical address.
This is a simple demonstration of "control via I/O registers, payload via DMA."
There is also a current implementation constraint worth recording: the driver writes those physical addresses into 32-bit fields but obtains them from the general PMM without an explicit DMA32 allocation check. On the present QEMU memory layouts they are low enough. On a machine where the PMM returns pages above 4 GiB, truncation would be possible.
That should be converted into an explicit DMA-addressability rule rather than relying on allocation history.
Modern VirtIO DMA helpers
hwgate provides a more systematic abstraction:
hw_dma_alloc(pages)
hw_dma_alloc_low(pages)
hw_dma_lo(id)
hw_dma_hi(id)
hw_dma_ptr(id)
hw_dma_bytes(id)
A HwDma slot records physical address, HHDM virtual address, page count and allocation state.
Drivers such as modern virtio-blk can place both the low and high 32 bits into 64-bit device addresses.
This is stronger than the legacy pattern of silently truncating to 32 bits.
DMA ownership and lifetime
A device can continue reading or writing memory after the CPU function that initiated the operation returns.
Therefore DMA memory cannot be freed simply because software no longer needs the local pointer.
The lifecycle is typically:
allocate
prepare
publish to device
device owns / may access
completion or cancellation
device no longer accesses
reclaim/free
Freeing or reusing memory before the device stops is a use-after-free performed by hardware.
ChrisOS RESOURCE_OWNERSHIP documentation already treats DMA buffers as driver-owned resources with device-specific lifetimes.
Rings are ownership machines
VirtIO available and used rings can be viewed as explicit ownership transfer.
For a transmit descriptor:
driver owns descriptor/buffer
        |
        | publish to avail
        v
device owns request
        |
        | put completion in used
        v
driver may reclaim
The indices are not merely counters. They delimit which side is permitted to mutate or consume each structure.
This viewpoint generalizes to NVMe and other queue-based devices.
DMA and interrupts
An interrupt often reports that a DMA operation progressed or completed.
The interrupt does not itself move the data.
A common sequence is:
CPU programs descriptor
CPU notifies device
device DMA reads/writes RAM
device posts completion state
device raises interrupt
CPU handler acknowledges device
CPU consumes completion
Polling can replace the last steps, but the memory-ownership protocol remains.
Completion races
Completion can occur before the CPU begins polling.
ChrisOS encountered exactly this class of issue in ATA DMA. The fixed ata_dma_wait logic accepts a completion bit that is already set on the first observation.
The prior buggy assumption was effectively:
That is not a valid hardware protocol unless the device specification guarantees the transition will be sampled.
Drivers must reason from stable status semantics, not from expected wall-clock timing.
MMIO posted writes
Some interconnects permit MMIO writes to be posted: the CPU can retire the write before it physically reaches the device.
When software requires proof that a prior register write reached the device, a device-specific readback or architectural ordering mechanism may be necessary.
A generic memory fence does not universally mean "the peripheral has consumed the command."
This is why hardware manuals often define exact readback/flush sequences.
ChrisOS drivers should document such requirements per controller rather than adding arbitrary delays.
DMA completion is not necessarily storage durability
DMA completion means memory transfer has completed according to the controller protocol.
It does not necessarily mean data is durable on nonvolatile media.
Storage can have controller write caches, device write caches, volatile queues and explicit flush commands.
ATA write code separately issues a flush after write chunks. The storage chapters cover persistence semantics in detail.
IOMMU
An IOMMU translates device-visible addresses to physical memory and can enforce access permissions.
Benefits include device isolation, mapping fragmented pages into contiguous IOVA ranges, supporting devices with limited address width, protecting the kernel from erroneous or malicious DMA and virtualization.
Without an IOMMU, a bus-mastering device given arbitrary physical addresses can potentially access large portions of RAM.
Current ChrisOS contains no IOMMU subsystem. Device addresses are treated as physical addresses. This is acceptable for the current educational/single-owner environment, but it is an explicit trust boundary.
Scatter/gather
Physical contiguity is expensive. Many modern devices support scatter/gather descriptors.
Instead of one contiguous 1 MiB allocation:
the device walks a list of physical segments.
This allows large logical transfers over fragmented physical memory.
VirtIO descriptor chains, AHCI PRDTs, NVMe PRPs/SGLs and network descriptors are all related to this general technique.
ChrisOS hw_dma_alloc currently prefers physically contiguous runs for its general helper. Future higher-throughput drivers should separate "DMA-addressable" from "physically contiguous."
Cache-line sharing with DMA
On non-coherent systems, a DMA buffer sharing a cache line with unrelated CPU data can corrupt ownership assumptions.
A cache clean/invalidate operates at cache-line granularity, not necessarily at the exact byte range.
Therefore robust DMA APIs care about cache-line alignment, direction, ownership transition and avoiding unrelated data in the same line.
The current x86-centric ChrisOS allocator uses pages, which naturally provides generous alignment, but the architecture does not yet model non-coherent DMA maintenance.
Security boundary
DMA is powerful because devices bypass normal CPU load/store execution.
That also makes it dangerous.
A compromised or misprogrammed device can overwrite page tables, kernel code/data, process memory or descriptor rings of another device.
IOMMU domains, device reset, strict lifetime rules and validated descriptor addresses are therefore security mechanisms, not merely performance infrastructure.
A future ChrisOS hardware-hardening phase should treat DMA capability as a privileged resource.
hwgate as a capability boundary
ChrisOS's hwgate layer exposes bounded operations rather than arbitrary device pointers to higher layers.
Examples include mapping a validated PCI BAR, aligned MMIO access, tracked DMA allocation and bounded access to DMA slots.
This design is useful for future capability enforcement because it centralizes sensitive hardware operations.
The current implementation is still kernel-internal and permissive. It is a foundation, not yet an isolation boundary comparable to an IOMMU domain.
Current BAR mapping limits
hw_bar_map currently has finite tables:
Therefore there are at most eight tracked MMIO windows, at most 256 KiB mapped per window, mappings are not reclaimed and resource sizing is intentionally simplified.
These constraints are acceptable for the currently exercised hardware set but should be documented as limits rather than mistaken for PCI architecture limits.
Current DMA helper limits
hwgate currently uses:
A single request can therefore ask for up to 2048 pages, while at most 32 DMA slots are tracked.
Because allocation uses pmm_alloc_contig, large requests can fail from physical fragmentation even when sufficient total memory remains.
A future DMA layer should support segmented mappings and explicit device masks.
ChrisVM MMIO model
ChrisVM implements an MMIO routing table.
chris_mmio_map records base physical address, size, read callback, write callback and device context.
chris_phys_read and chris_phys_write first recognize RAM and framebuffer ranges. If an address is not RAM/framebuffer, the access is dispatched through the MMIO table.
This is the emulator equivalent of physical-address decoding.
guest physical access
        |
        +-- RAM range -> host RAM backing
        |
        +-- framebuffer -> framebuffer backing
        |
        +-- MMIO range -> device callback
This is a strong foundation for emulated devices.
Current ChrisVM MMIO granularity
For non-RAM MMIO, chris_phys_read/write iterate byte by byte and call the MMIO callback with width 1 for each byte.
That is functionally simple, but not sufficient for devices whose register semantics depend on transaction width.
A real 32-bit MMIO read is one architectural access. Four 8-bit callback reads can have different side effects.
Therefore future ChrisVM device fidelity requires preserving the original access width whenever possible and rejecting unsupported split accesses according to each device specification.
ChrisVM and DMA
Current ChrisVM does not expose a generic device-master DMA/IOMMU subsystem comparable to the native hwgate DMA layer.
An emulated device can eventually use guest physical memory helpers to model device reads/writes, but a complete DMA model should add:
- explicit device-initiated memory access API;
- DMA address translation policy;
- address-width validation;
- deterministic completion scheduling;
- ordering relative to MMIO doorbells;
- fault behavior;
- optional IOMMU;
- tracing/replay of DMA transactions.
Without this layer, ChrisVM can emulate register behavior but cannot yet serve as a faithful replacement for QEMU for DMA-heavy ChrisOS devices.
A future ChrisVM DMA transaction
A deterministic emulator design can represent a DMA request as:
device
  -> dma_read/dma_write(iova, length)
  -> IOMMU or identity translator
  -> guest physical memory
  -> completion event
The event scheduler should define when the operation becomes visible relative to CPU steps and interrupts.
That enables reproducible races rather than host-thread timing accidents.
Memory model interaction
The previous chapter described CPU-to-CPU ordering. DMA adds another observer.
Now a synchronization graph can involve:
CPU store to descriptor
        |
        v
memory barrier
        |
        v
MMIO doorbell
        |
        v
device DMA read
        |
        v
device DMA write completion
        |
        v
interrupt/status
        |
        v
CPU load
Each arrow requires a defined ordering rule.
CPU cache coherence alone does not define the whole graph.
Why volatile descriptor is not sufficient
Marking a DMA descriptor volatile can force compiler accesses to remain visible as operations, but it does not guarantee CPU cache clean on non-coherent hardware, device address validity, barrier before notification, correct device ownership, exact transaction width, IOMMU mapping or completion ordering.
DMA correctness requires an API/protocol, not a type qualifier.
Mapping device memory into user mode
Although current ChrisOS drivers are kernel-resident, a mature OS may map device BARs into userspace for frameworks such as graphics or userspace drivers.
That introduces privilege/capability checks, page attributes, range validation, revocation, IOMMU isolation for DMA and an interrupt-delivery mechanism.
Exposing an MMIO pointer without constraining DMA would leave a process able to program the device to access arbitrary physical memory.
Thus MMIO delegation and DMA isolation are coupled security problems.
Bus errors and fault containment
Device access can fail because of absent hardware, unsupported transactions, timeout, malformed descriptors, invalid DMA addresses, IOMMU faults, controller reset or hot-unplug.
Drivers need finite waits and recovery paths.
ChrisOS already uses bounded polling loops in ATA and VirtIO paths. The long-term design should standardize timeout, reset and fault reporting.
Reproducible arithmetic in this chapter
scripts/check_bus_dma_examples.py validates several mechanical contracts:
- PCI configuration mechanism #1 address encoding.
- BAR size-mask inversion for canonical masks.
- 32-bit DMA boundary checks.
- low/high 32-bit splitting and recombination of 64-bit DMA addresses.
- ATA PRDT byte-count/end flag encoding.
- split VirtIO ring offsets for representative queue sizes.
These are not device conformance tests. They ensure that the chapter's numerical examples stay executable.
PCI configuration-address example
The current pci_read/write encode:
bit 31      = enable
bits 23:16  = bus
bits 15:11  = device/slot
bits 10:8   = function
bits 7:2    = dword register number
bits 1:0    = zero
For bus 2, slot 5, function 3, offset 0x14:
The checker confirms the value.
The next chapter explains why this mechanism is legacy PCI configuration and how PCIe ECAM changes configuration-space access.
DMA32 boundary example
A 32-bit device can access a region only if its final byte is not above 0xFFFFFFFF.
For:
the region fits exactly.
At:
it does not.
Checking only the starting address is insufficient.
Address splitting
Modern descriptors often carry a 64-bit DMA address as two little-endian 32-bit fields.
For:
and:
hw_dma_lo and hw_dma_hi implement exactly this decomposition.
Validation boundaries
This chapter is reconciled with ChrisOS main revision da3df29cb397932c43d32373871fb9380e688ade.
It documents what the current code does and distinguishes that from a complete portable DMA subsystem.
In particular, it does not claim that ChrisOS currently provides general IOMMU support, non-coherent DMA cache maintenance, full 64-bit PCI BAR resource sizing, hot-plug resource management, arbitrary hardware portability or ChrisVM device-master DMA fidelity.
These are explicit future architecture requirements.
Review triggers
Review this chapter when any of these change:
- map_mmio_page page attributes or PAT/MTRR handling;
- hw_bar_map sizing/resource management;
- PMM DMA32 reservation;
- hw_dma_* API;
- VirtIO queue barriers;
- ATA or AC97 DMA addressing;
- IOMMU work;
- ChrisVM MMIO access width;
- ChrisVM device-initiated memory access.
Primary references
- Intel 64 and IA-32 Architectures Software Developer's Manual, memory typing and memory-mapped I/O.
- Virtual I/O Device (VIRTIO) Version 1.3, virtqueues, device notification and platform ordering.
- Linux kernel DMA API documentation, DMA addresses, coherent/streaming mappings, masks and IOMMU abstraction.
- PCI/PCI Express configuration and BAR details are developed in the following pci-pcie chapter.