
Parsing and grammars
About this chapter Compiler construction
In this chapter
- Parsing and grammars
- Scope
- Grammar versus parser implementation
- ChrisC parser input
- ChrisC output
- Primary expressions
- Postfix structure
- Unary expressions
- Cast versus parenthesized expression
- Compound literals
- Binary precedence in ChrisC
- Left associativity
- Assignment associativity
- Ternary parsing
- Comma operator
- Calls and argument parsing
- Declarations inside statements
- Typedef-name ambiguity
- Statements and blocks
- For-loop grammar
- Global declarations and functions
- Initializer parsing
- Fail-fast syntax handling
- Semantic work during ChrisC parsing
- KCC parser architecture
- KCC primary/postfix/unary layers
- Precedence climbing in KCC
- Maximal operator choice inside KCC parsing
- Binary associativity in KCC
- Short-circuit operators
- Assignment in KCC
- Ternary in KCC
- `sizeof` and speculative parsing
- KCC declarations
- Function parameters
- Global parsing
- Inline-function treatment
- Constant-expression parser
- Error handling in KCC
- Recursive-descent stack depth
- ChrisAsm grammar
- CLASM grammar
- Parser generators versus current design
- Validation evidence
- Missing parser-focused tests
- Security and robustness
- Current limitations
- Roadmap boundary
- Source map and revision note
Scope
Parsing converts a token or character stream into a structured interpretation of a program.
In ChrisOS there is no generated parser and no shared grammar engine.
The current language tools are implemented by hand:
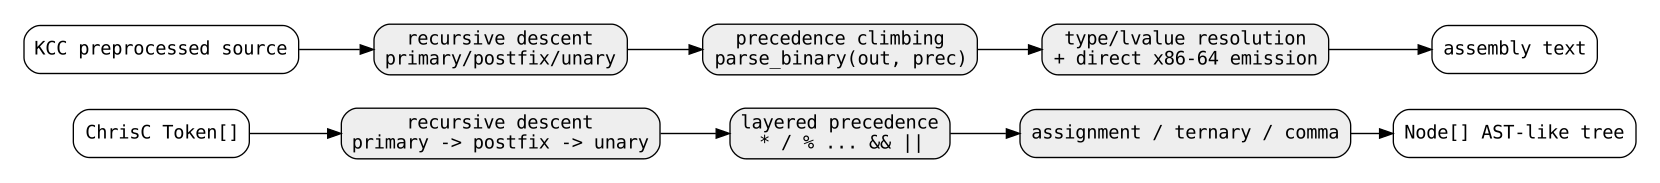
- ChrisC is a recursive-descent parser over an explicit `Token[]` stream and builds AST-like `Node` records.
- KCC combines scanner, recursive descent, precedence climbing and native code generation over a raw preprocessed-source pointer.
- ChrisAsm and CLASM use compact line parsers whose grammar is small enough to decode directly from operands and delimiters.
This chapter documents how those parsers actually recognize language structure, how precedence and associativity are encoded, where syntax and semantics overlap, and where current implementations deliberately support only a project-specific language subset.
Grammar versus parser implementation
A grammar describes valid combinations of language symbols.
A parser is an algorithm that decides whether an input follows that grammar and usually creates some representation of the result.
A simplified expression grammar might be written as:
expression
    := assignment ("," assignment)*

assignment
    := logical_or
     | logical_or "=" assignment

logical_or
    := logical_and ("||" logical_and)*

...
ChrisC implements essentially this style directly through C functions.
KCC represents part of the same precedence structure numerically inside a precedence-climbing parser.
Neither parser is generated from BNF, EBNF, Yacc/Bison or another declarative grammar file.
The source code itself is currently the executable grammar.
ChrisC parser input
ChrisC parsing starts after preprocessing and lexical analysis.
The parser operates on:
Helpers conceptually provide:
- current token lookup;
- conditional token consumption;
- required-token checks;
- diagnostic creation.
Because token kinds and source coordinates were already produced by the lexer, parsing works at the token level rather than on raw characters.
ChrisC output
ChrisC builds nodes in a fixed:
table.
A node stores:
- node kind;
- left/right/third child references;
- next link;
- integer payload;
- source line/column;
- float classification;
- structure/type side information;
- name text.
The representation is AST-like but also contains lowering-specific information.
Parsing and semantic resolution are therefore not completely separated.
Primary expressions
`primary` recognizes the lowest-level expression forms.
Current examples include:
- integer literals;
- float literals;
- string literals;
- parenthesized expressions;
- identifiers;
- enum/constants;
- direct calls;
- function references;
- array indexing;
- member access;
- `_Generic`.
The function does more than grammar recognition.
For identifiers it may immediately consult constant, symbol and function tables.
An unknown variable can therefore fail while building the expression tree.
This is already a semantic operation inside the parser.
Postfix structure
`postfix_expr` repeatedly extends an existing expression.
It handles forms such as:
and related chained access.
The loop structure is important because postfix operations bind tighter than binary operators and can chain left-to-right.
For example:
is constructed by repeatedly wrapping or extending the expression returned by the previous stage.
Unary expressions
`unary` handles prefix constructs including:
It recursively calls itself for prefix operators.
That naturally gives prefix unary operators right-associative nesting.
For example:
parses as:
Cast versus parenthesized expression
A C-like grammar has a classic ambiguity:
could be a parenthesized expression or the beginning of a cast if `x` is a type name.
ChrisC resolves this with:
and then:
If a token sequence after `(` is recognized as a type, `unary` follows the cast path.
Otherwise ordinary `primary` parsing handles it as a parenthesized expression.
This means typedef knowledge participates directly in grammar disambiguation.
Compound literals
After recognizing a cast type, ChrisC also accepts a brace form resembling a compound literal:
The current implementation parses the first relevant assignment expression and consumes additional comma-separated expressions until the closing brace.
Its behavior is project-specific rather than a complete implementation of every standard C initializer rule.
Binary precedence in ChrisC
ChrisC implements most binary precedence as a stack of recursive-descent levels.
The generic:
helper parses the tighter level first and then consumes repeated operators belonging to the current level.
Current order, from tighter to looser, is:
This closely resembles normal C operator precedence for the supported operators.
Left associativity
The `binary` helper starts with:
and repeatedly creates:
nodes.
Therefore operators handled by this helper are left-associative.
For example:
becomes structurally:
not:
Assignment associativity
`assignment_expr` first parses a logical-or expression.
If it sees an assignment or compound-assignment token, the right side is parsed by recursively calling:
This makes assignment right-associative.
Thus:
is interpreted as:
The same mechanism is used for compound assignments in the supported subset.
Ternary parsing
The conditional operator is handled inside `assignment_expr`.
After a condition and `?`, both branches are parsed using assignment-expression logic.
The parser requires the separating colon.
A node stores three children:
The recursive structure allows nested ternaries.
Comma operator
The lowest expression layer is:
It parses one `assignment_expr` and then consumes repeated commas.
Each comma creates an `N_COMMA` node combining the previous left expression and the next assignment expression.
This makes the comma operator left-associative in the AST.
Calls and argument parsing
When an identifier is followed by `(`, ChrisC creates a call node.
Arguments are parsed as:
rather than full comma expressions because comma separates arguments at that grammar level.
Nested calls are first accumulated in a local argument array.
The source comment documents why: direct insertion into the shared argument table previously allowed nested calls to interleave arguments.
This is an example where parser data structure design affects correctness even when the grammar is straightforward.
Declarations inside statements
The statement parser recognizes declarations directly.
It handles project-supported forms involving:
- integer widths;
- floats;
- chars;
- pointers;
- arrays;
- typedef names;
- structures/unions;
- enums;
- qualifiers;
- function-pointer-shaped declarations;
- selected alignment syntax.
Declaration parsing is deeply intertwined with symbol creation.
A successfully parsed local declaration can immediately allocate a symbol-table entry.
Typedef-name ambiguity
In C-like syntax, an identifier can be either an ordinary identifier or a typedef name.
ChrisC resolves this through its typedef table.
Code paths inspect:
and token lookahead to decide whether a statement starts a declaration.
This is another case where pure context-free token grammar is insufficient without semantic parser state.
Statements and blocks
The parser recognizes block structure through braces.
`stmt_or_block` accepts either:
- a braced block;
- one statement wrapped as a block-like node.
The statement parser supports project forms for control flow and declarations, including:
if
while
for
do
switch
case
default
break
continue
return
goto
labels
expression statements
declarations
The exact set evolves with ChrisC’s supported C profile.
For-loop grammar
ChrisC separates:
from the main statement parser.
The initializer can be:
- empty;
- a supported declaration;
- an expression.
The step can be empty or an expression.
This makes the special semicolon/parenthesis structure of `for` explicit instead of trying to reuse a generic statement grammar unchanged.
Global declarations and functions
`parse_decls` drives top-level parsing until `T_EOF`.
It distinguishes among:
- typedef declarations;
- enums;
- structure/union declarations;
- globals;
- arrays;
- function prototypes;
- function definitions.
`parse_type_n` and symbol/type tables participate in these decisions.
Function parsing records parameter and return metadata while also building the body tree.
Initializer parsing
ChrisC contains specialized parser logic for global initializers.
It includes separate paths for:
initialization.
Helpers can count or skip brace-initializer elements while tracking nested parentheses, brackets and braces.
This is not a general parser-recovery system; it is purpose-built initializer traversal.
Fail-fast syntax handling
ChrisC normally stops the current compilation after the first parser failure.
`expect`-style checks report messages such as:
There is no broad panic-mode recovery that synchronizes at the next semicolon and continues producing many independent syntax diagnostics.
Although `ChrisResult` can hold multiple structured diagnostics, the parser is still fundamentally fail-fast for most syntax errors.
Semantic work during ChrisC parsing
ChrisC parsing already resolves or checks several non-syntactic properties.
Examples include:
- unknown variables;
- struct-field existence;
- lvalue suitability for assignment;
- assignment to const;
- function lookup;
- typedef classification;
- some type/float propagation.
Therefore the boundary:
is architectural rather than a clean function boundary in current source.
The next chapter separates these concerns conceptually while documenting where implementation combines them.
KCC parser architecture
KCC parses directly from:
which points into preprocessed source.
It has no materialized token array and no AST.
Parsing helpers simultaneously:
- recognize syntax;
- resolve names and types;
- manage lvalue state;
- emit x86-64 assembly.
The parser is therefore closer to a syntax-directed translator than a frontend producing an independent tree.
KCC primary/postfix/unary layers
KCC still uses recursive-descent structure.
`parse_primary` handles literals, identifiers, parenthesized expressions and function-like names.
`postfix_tail` extends values with calls, indexing, member access and postfix increment/decrement.
`parse_unary` handles prefix operations, casts, address/dereference forms and `sizeof`.
The returned `Val` structure carries both type information and code-generation state.
Precedence climbing in KCC
KCC implements binary precedence through:
It defines operator spellings and numeric precedence values in arrays.
Current groups are:
The parser first handles a unary expression, finds the highest-priority matching operator allowed by the current threshold, then recursively parses the right side with:
This is precedence climbing.
Maximal operator choice inside KCC parsing
Because KCC does not have a separate lexer, `parse_binary` must also protect operator boundaries.
It scans candidate operator strings and prefers the longest matching spelling.
It avoids interpreting one-character operators as prefixes of forms such as:
So some behavior that belongs to lexical analysis in ChrisC is implemented inside the KCC expression parser.
Binary associativity in KCC
The recursion threshold:
makes equal-precedence binary operators group left-associatively.
This matches expected behavior for arithmetic, shift, relational and bitwise operators in the supported subset.
Short-circuit operators
`&&` and `||` are handled specially.
Instead of using ordinary `apply_bin`, parsing emits labels and conditional jumps so the right side executes only when required.
This demonstrates KCC’s tight parse/codegen coupling:
the parser is not merely building syntax; recognizing an operator immediately shapes control-flow assembly.
Assignment in KCC
After the precedence-climbing binary layer returns at top-level precedence, `parse_binary` checks for:
- ternary `?:`;
- compound assignments;
- ordinary assignment.
Assignment right-hand sides call `parse_expr` recursively.
Lvalue checks happen immediately.
The destination `Val` is saved, native code for the right side is emitted, and the result is stored during parsing.
Ternary in KCC
KCC emits branch labels while parsing `?:`.
It parses the yes/no expressions and directly emits jumps around each branch.
There is no ternary AST node.
This means parser success and backend generation are one transaction.
`sizeof` and speculative parsing
KCC’s `parse_sizeof_type` shows a notable consequence of parse/codegen coupling.
When `sizeof` applies to an expression, the parser must determine its type without keeping the emitted code.
The implementation saves assembly and compiler-state values, parses the expression, then restores:
- assembly length;
- overflow state;
- dead-store state;
- temporary count;
- frame state.
This simulates unevaluated-expression parsing by rolling back backend side effects.
An AST or independent typed IR would make this boundary easier to model, but current KCC deliberately uses a smaller direct architecture.
KCC declarations
`parse_base` handles storage/type qualifiers and base types.
It can parse project-supported:
- structs;
- pointers;
- typedef-like known types;
- volatility;
- const;
- unsigned;
- static/extern/inline forms.
Struct-body parsing simultaneously computes field offsets, alignment and total size.
Again, syntax recognition and layout semantics are combined.
Function parameters
`parse_params` parses parameter declarations until the closing parenthesis.
It recognizes project-supported pointer, array and function-pointer-shaped forms.
At the same time it assigns frame offsets for parameters.
Parameters beyond the first six are assigned stack-frame positions consistent with the toolchain’s calling convention model.
This is semantic/backend work performed during parsing.
Global parsing
`parse_global` distinguishes:
- objects;
- arrays;
- function declarations;
- function definitions;
- function pointers;
- initialized globals.
When it recognizes a function definition, it immediately emits:
and then parses statements while emitting the body.
There is no later whole-function AST-to-code pass.
Inline-function treatment
Current KCC handling for some `inline` functions can skip the body rather than compile it as a normal definition.
The parser uses brace-depth scanning to move across the body.
This is project-subset behavior, not a general C inline-semantics implementation.
Constant-expression parser
KCC has a separate constant-expression path:
It is used for cases such as:
- array bounds;
- enum values;
- preprocessing conditions;
- static assertions.
This parser mirrors much of the normal expression precedence but evaluates values directly rather than emitting runtime assembly.
Maintaining two expression parsers creates a consistency burden: supported operators and semantics need to remain aligned.
Error handling in KCC
KCC is also largely fail-fast.
A parse failure records the current:
through `KccDiag`.
There is no broad syntax-error recovery that continues compiling later declarations after an error.
Because parsing and code generation are interwoven, recovering safely would also require rolling back partially emitted assembly and symbol/frame state.
Recursive-descent stack depth
Both ChrisC and KCC use C call-stack recursion for nested syntax.
Deeply nested:
- unary expressions;
- parentheses;
- declarators;
- nested statements;
can therefore consume native/compiler stack.
There is no general explicit parser-stack depth limit for all grammar recursion paths.
Specific structures, such as include depth or some nested declarator scans, have their own bounds.
This should be considered if parsing hostile generated source.
ChrisAsm grammar
ChrisAsm uses a compact:
dispatcher.
The line begins with a directive, label or mnemonic.
Operand parsing then uses helpers for:
- identifiers;
- integers;
- memory operands;
- strings;
- registers.
Instruction-specific branches validate the expected operand grammar and emit machine bytes immediately.
This is effectively a hand-written predictive parser for a small assembly language.
CLASM grammar
CLASM also parses one line at a time.
Its grammar is approximately:
Pass 1 records labels and instruction sizes.
Pass 2 resolves label operands and emits CLVM bytes.
The parser rejects:
- unknown instructions;
- missing operands;
- extra text;
- undefined labels;
- out-of-range short branches.
The grammar is small enough that a parser generator would add little value today.
Parser generators versus current design
A parser generator could provide:
- declarative grammar;
- generated parse tables;
- formal conflict reporting;
- separation between grammar and semantic actions.
ChrisOS currently chooses hand-written parsers because:
- language subsets are evolving with the project;
- code size and dependencies remain small;
- semantic/codegen state is tightly specialized;
- direct source-level debugging is straightforward.
The trade-off is that precedence, recovery and grammar coverage must be maintained manually.
Validation evidence
ChrisC
`test_chrisc_c17.c` exercises:
- declarations;
- calls;
- casts;
- `sizeof`;
- switches;
- loops;
- compound literals;
- `_Generic`;
- structures;
- arrays;
- function pointers;
- multiple translation units.
`test_chrisc_lang.c` compiles and executes programs, validating that parse trees lower to observable CLVM behavior.
`test_fuzz_chrisc.c` supplies pseudo-random malformed source and verifies that the compiler remains usable.
KCC
`test_kcc.c` parses both targeted snippets and real project source.
It exercises:
- globals;
- functions;
- structs;
- pointers;
- arrays;
- expressions;
- volatile operations;
- relocatable calls;
- multi-object linking.
The test therefore validates the combined scanner/parser/codegen path.
Assemblers
`test_chrisasm.c` and `test_clasm.c` exercise their line grammars and rejection paths.
Missing parser-focused tests
The current suite would benefit from direct grammar tests for:
- every precedence boundary;
- left/right associativity;
- deeply nested parentheses;
- nested ternary expressions;
- assignment chains;
- comma expressions;
- typedef-name ambiguity;
- cast-versus-parenthesized-expression ambiguity;
- malformed declarators;
- unmatched braces;
- missing semicolons;
- parser stack-depth stress;
- KCC rollback correctness after failed speculative parsing;
- exact agreement between `ce_expr` and runtime expression precedence;
- deterministic diagnostics for equivalent malformed forms.
Security and robustness
Parser attack surfaces include:
- recursion depth;
- exponential or repeated backtracking;
- inconsistent rollback;
- integer overflow in grammar-derived sizes;
- table exhaustion;
- malformed nesting;
- partial backend state after failure.
ChrisC generally advances over an already-tokenized stream and performs limited local lookahead, so its main parse complexity is close to linear for ordinary input.
KCC also mostly advances a source pointer, but selected lookahead saves/restores parser positions and `sizeof` can snapshot backend state.
Neither parser is currently documented as hardened for arbitrary hostile source.
Current limitations
At the documented revision:
- no declarative grammar file;
- no parser generator;
- syntax and semantics are interleaved in both compilers;
- ChrisC AST nodes contain lowering-specific state;
- KCC has no AST and emits native assembly during parsing;
- both parsers are mostly fail-fast;
- no general syntax-error recovery;
- typedef/type knowledge participates directly in parsing;
- KCC maintains separate runtime-expression and constant-expression parsers;
- speculative KCC parsing can require backend rollback;
- grammar support is project-specific rather than full ISO C;
- deep recursive syntax relies on the C call stack;
- ChrisAsm/CLASM use ad-hoc instruction-specific grammar code rather than one shared parser framework.
Roadmap boundary
Future parser work could include:
- machine-readable language-profile grammars;
- clearer syntax/semantic phase boundaries;
- reentrant parser contexts;
- explicit source-span objects;
- AST validation passes;
- a typed IR boundary before native code generation;
- unified precedence definitions reused by constant/runtime parsers;
- structured parser error codes;
- synchronization-based multi-error recovery;
- recursion-depth guards;
- grammar differential tests;
- parser fuzzing with coverage feedback;
- generated documentation from grammar definitions.
Those remain roadmap items until implemented and validated.
Source map and revision note
ChrisC parsing is concentrated in `compiler/chrisc/chrisc.c`: primary/postfix/unary expression parsing, layered binary precedence, assignment/comma parsing, statements, blocks, declarators and global/function parsing. KCC parsing is in `compiler/kcc/kcc.c`: scanner-on-demand helpers, recursive descent, precedence climbing, constant-expression parsing, declarations and direct x86-64 emission. Assembly line parsers live in `compiler/chrisasm/chrisasm.c` and `compiler/clvm/clasm.c`.
All current-behavior claims in this chapter were reconciled against ChrisOS revision `e05a17fd76333114a3fb5c2452f38ca747d4ac56`.