
Translation Lookaside Buffer: cached translation, invalidation and ChrisOS
About this chapter Frames and address translation
In this chapter
- Translation Lookaside Buffer: cached translation, invalidation and ChrisOS
- Scope
- What the TLB avoids
- TLB state is not the page table
- Local invalidation with INVLPG
- Range invalidation
- CR3 as translation context
- Why map_4k and map_4k_nosync both exist
- Installing a previously absent mapping
- Unmapping is more dangerous than mapping
- JIT mapping lifecycle as a TLB case study
- Per-process private mappings
- Shared kernel mappings
- TLB polling is integrated into lock waiting
- IPI-assisted invalidation
- A zero-byte "shootdown" is not a range flush
- Local flush versus remote shootdown
- Effective permissions and cached translation state
- Page size and invalidation granularity
- Performance model
- Failure modes
- Validation evidence
- Current limitations
- Architectural references and revision boundary
Scope
A page table is the authoritative translation structure in memory, but the processor does not perform a complete four-level page-table walk for every load, store and instruction fetch. Recent translation results are cached in processor translation structures, conventionally discussed through the Translation Lookaside Buffer (TLB).
The TLB is therefore part of the practical state of virtual memory even though it is not represented by a normal C data structure in the kernel.
A useful model is:
virtual address
      |
      v
 translation cache lookup
   /         \
 hit         miss
  |           |
  |      page-table walk
  |           |
  +------> physical address + effective permissions
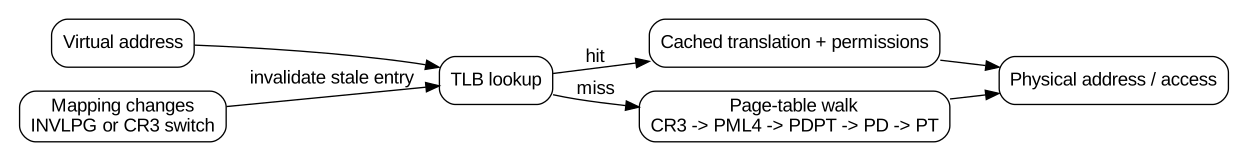
The important operating-system consequence is that changing a PTE in RAM is not, by itself, a complete translation update. Software must also ensure that processors stop using translation state derived from the old mapping when the architectural rules require invalidation.
This chapter explains the local mechanism and how it appears in the current ChrisOS memory subsystem. The multiprocessor coordination protocol is covered separately in TLB shootdown and reclamation.
What the TLB avoids
For a normal 4 KiB page in the four-level x86-64 layout used by ChrisOS, a page-table miss can require the processor to consult:
- the PML4 entry;
- the PDPT entry;
- the page-directory entry;
- the final PTE.
Those paging-structure reads are metadata accesses that exist only to discover where the intended data or instruction resides.
Caching translation results amortizes that work.
At a conceptual level, a cached translation needs enough information to answer questions such as:
- what physical page corresponds to this virtual page;
- which address-space context the translation belongs to;
- whether the access is permitted for the current privilege and access type;
- which page size the translation represents.
The precise internal organization is processor-specific. The OS should reason from the architectural invalidation contract rather than assuming a particular number of entries, associativity, replacement algorithm or hierarchy.
TLB state is not the page table
Consider a mapping:
A CPU accesses V and caches the translation.
The kernel later modifies the page table:
Memory now contains the new PTE, but a processor may still have translation state derived from the old PTE until the required invalidation occurs.
This creates two different notions of state:
Correct VM code must bring them into agreement at the moments required by the architecture and the kernel's reclamation policy.
The most dangerous case is not merely observing old data. It is reusing the old physical frame for a different object while some CPU can still reach it through a stale virtual translation.
That is why TLB coherence is also a resource-lifetime problem.
Local invalidation with INVLPG
ChrisOS uses the x86 INVLPG instruction for page-granular local invalidation.
The primitive appears directly in several paths.
For a kernel 4 KiB mapping, map_4k eventually executes:
after modifying the leaf PTE.
For unmapping, unmap_4k clears the PTE under mm_lock and then invalidates the virtual address locally.
For an arbitrary process CR3, mm_unmap_cr3 invalidates locally only when the supplied CR3 is also the currently active CR3.
That distinction is important.
INVLPG acts on the CPU executing the instruction. It is not a broadcast request to all processors, and it is not an instruction that directly edits another CPU's translation cache.
Therefore:
is sufficient only for the local translation state covered by that operation.
Shared kernel mappings visible on multiple CPUs need an SMP protocol before the corresponding physical memory can be safely reused.
Range invalidation
ChrisOS implements an internal helper named mm_invlpg_span.
It accepts a virtual base and byte count, aligns the first and last addresses to 4 KiB pages, and issues one INVLPG per covered page.
For a range spanning N pages, the cost is O(N) invalidation instructions.
The implementation also protects its address arithmetic against wrapping across the end of the 64-bit virtual-address range.
The current shootdown protocol publishes a virtual range using the same base/byte representation so remote CPUs can execute the same page-by-page invalidation logic.
This is intentionally simple. There is no current heuristic that switches from many INVLPG instructions to a broader context invalidation above some threshold.
CR3 as translation context
CR3 selects the root of the current paging hierarchy.
ChrisOS changes address spaces through mm_switch:
and performs an explicit current-context TLB flush in mm_flush_tlb by reading CR3 and writing the same value back.
At the software level these operations are O(1), but their architectural performance cost is not equivalent to an ordinary register move because translation-cache state is involved.
The current ChrisOS process implementation does not use PCID-aware switching.
That means the code does not preserve multiple tagged process translation contexts through a software-visible PCID policy. The process layer simply writes the process CR3 when switching.
This is a current design simplification.
Why map_4k and map_4k_nosync both exist
map_4k and map_4k_nosync perform the same page-table mutation under mm_lock.
The difference is the final local invalidation.
- map_4k: installs the leaf and executes local INVLPG;
- map_4k_nosync: installs the leaf and omits that invalidation.
The name nosync must not be interpreted as "safe without synchronization in every context."
It means only that this function does not perform the final local INVLPG itself.
A caller using map_4k_nosync must have a reason the missing local invalidation is acceptable or deferred.
The page-table write is still serialized by mm_lock.
Installing a previously absent mapping
A common intuition is that invalidation is needed only when replacing or removing a present mapping. Real translation hardware can also retain paging-related state that makes explicit invalidation relevant when software changes a translation that was previously unusable.
The current JIT code expresses a concrete ChrisOS policy here.
jit_seal maps executable virtual pages that were previously absent. It calls map_4k for every page, and the source comment explicitly states that local INVLPG is used rather than a global CR3-based operation.
The design reasoning is:
- the new executable mapping only needs to become visible locally at seal time;
- a broad global operation previously caused severe runtime failure in this path;
- another CPU that later runs the relevant work will acquire the mapping through its own translation context.
The important documentation rule is to describe the implemented contract rather than generalize this into a universal guarantee for every future mapping producer.
Unmapping is more dangerous than mapping
Adding a new mapping and deleting an old mapping have different lifetime consequences.
If a stale CPU does not yet observe a newly created mapping, it may fault or continue to treat the address as unavailable.
If a stale CPU continues to observe a mapping that has been removed, it may still access the old physical frame.
If that frame is already returned to PMM and reassigned, the stale access becomes an access to an unrelated object.
Therefore the safe teardown order is conceptually:
remove PTE
invalidate translations on every CPU that can have cached it
prove invalidation completion
only then reuse the physical frame
The ChrisOS JIT teardown is the clearest current implementation of this rule.
JIT mapping lifecycle as a TLB case study
The JIT uses two aliases for the same contiguous physical allocation:
- writable HHDM alias in buf->w;
- executable high virtual alias in buf->x.
jit_seal maps the executable alias page by page.
jit_free later:
- clears each executable leaf through unmap_4k;
- performs mm_tlb_shootdown_range over the complete executable virtual span;
- returns the physical frames immediately only if the shootdown reports reuse-safe;
- otherwise sends the frames to the TLB quarantine.
This is a concrete mapping-lifetime invariant:
The TLB protocol is what closes that gap.
Per-process private mappings
Private process mappings have a narrower current concurrency model.
User processes run only on the BSP in the present process scheduler.
mm_unmap_cr3 clears a leaf from a chosen process CR3. It executes INVLPG only if that CR3 is currently active on the local CPU.
During process destruction, proc_destroy first switches away from a dying current process to the kernel CR3, then releases the process pages and page-table hierarchy.
Because the current design does not run the same user address space concurrently across CPUs, private process teardown does not yet require the same per-address-space multiprocessor shootdown model that a general SMP process scheduler would require.
This restriction is part of the present correctness argument.
If user processes become migratable or concurrently runnable on multiple CPUs, address-space membership tracking will have to become part of TLB invalidation.
Shared kernel mappings
The kernel half is shared across process PML4 roots by copying entries 256..511 from the kernel PML4 into each process root.
Consequently, a kernel mapping can matter even when a CPU is not running PID 0.
A processor executing with a process CR3 can still use the shared upper-half translation hierarchy.
This is why shared kernel mapping reclamation is naturally a global CPU-coherence problem rather than simply a "kernel CR3" problem.
The current TLB shootdown membership tracks CPUs, not individual CR3 users.
That matches the present kernel-shared use case.
TLB polling is integrated into lock waiting
mm_enter does not use the generic spin_lock function directly.
While waiting for mm_lock it repeatedly calls mm_tlb_poll and then attempts CAS on the lock word.
This is a liveness property.
A CPU blocked waiting to enter MM should still be able to notice and acknowledge a pending TLB generation. Otherwise the initiating CPU could wait for an acknowledgement from a peer that is itself spinning in memory-management code.
The same pattern exists while acquiring the separate shootdown serialization flag mm_tlb_busy.
Translation coherence is therefore integrated with wait loops, not delegated only to a background timer.
IPI-assisted invalidation
After the LAPIC interrupt path is available, the shootdown initiator can send vector 0xF0 to remote CPUs.
irq_dispatch treats 0xF0 specially:
mm_tlb_poll discovers whether the current CPU has an unseen published generation. If so, it invalidates the published span and acknowledges that generation.
The IPI accelerates progress.
Polling remains present in worker and wait paths, so progress does not rely solely on one delivery path.
The detailed generation and fencing state machine belongs to the shootdown chapter.
A zero-byte "shootdown" is not a range flush
The public mm_tlb_shootdown function currently calls the internal protocol with:
Remote mm_invlpg_span does nothing for a zero-byte range.
Therefore, at the reviewed revision, mm_tlb_shootdown by itself should be understood as publishing/synchronizing a TLB protocol generation with no page-range invalidation payload, not as an implementation of a full architectural TLB flush.
The range API mm_tlb_shootdown_range is the current function that carries a real invalidation span.
This distinction is important because the header-level name alone could suggest stronger behavior than the source implements.
Local flush versus remote shootdown
The current primitives can be classified as follows:
| Mechanism | Scope in current design | Main use |
|---|---|---|
| INVLPG | executing CPU, virtual page | local page invalidation |
| mm_invlpg_span | executing CPU, range | local multi-page invalidation |
| mm_flush_tlb | current CPU/current CR3 reload | broad local current-context refresh |
| mm_switch | current CPU, selects another CR3 | process address-space switch |
| mm_tlb_shootdown_range | participating CPUs, range | shared-mapping reclamation |
| mm_tlb_quarantine | physical-frame lifetime | delay reuse when coherence proof is incomplete |
These mechanisms solve related but different problems.
Effective permissions and cached translation state
Translation is not merely a physical-frame number.
Page-table permission state affects whether an access is permitted.
When the kernel changes permissions on an existing mapping, stale translation state can therefore be dangerous even if the physical frame does not change.
Examples include conceptual transitions such as:
- writable -> read-only;
- executable -> NX;
- user-accessible -> supervisor-only.
The present ChrisOS code has stronger explicit lifecycle handling for mapping removal than a generalized permission-transition API.
There is no current mprotect-like subsystem that centralizes permission changes and their invalidation requirements.
Future permission APIs must treat TLB invalidation as part of the permission transaction.
Page size and invalidation granularity
The ChrisOS mapping routines create 4 KiB leaves.
Its software translation walker can understand inherited 2 MiB and 1 GiB huge pages, but the mutation API does not currently split or create huge mappings.
mm_invlpg_span advances in PMM_PAGE increments, currently 4096 bytes.
Thus the implemented invalidation range machinery is designed around 4 KiB page units even though the inherited boot hierarchy may contain larger leaves.
A generalized huge-page mutation subsystem would need explicit rules for invalidation granularity and splitting.
Performance model
A TLB hit avoids a page-table walk and is therefore a major performance property of virtual memory.
From the kernel's point of view, invalidation has its own cost.
For an N-page range:
For a shootdown involving C participating CPUs, coordination additionally involves:
- publication of shared state;
- selection of remote targets;
- up to O(C) IPI sends;
- remote invalidation work;
- acknowledgement waiting.
The wall-clock cost also depends on interrupt latency, CPU scheduling state and cache-coherence traffic.
This is why production kernels often optimize TLB invalidation aggressively.
The current ChrisOS design prioritizes explicit correctness and diagnosability over sophisticated batching heuristics.
Failure modes
TLB mistakes often survive simple single-CPU testing.
Common failure classes include:
- changing a mapping without invalidating the local stale translation;
- freeing a physical frame before remote CPUs acknowledge;
- assuming an IPI was delivered merely because it was requested;
- waiting forever for a CPU that no longer makes progress;
- treating a CPU count as equivalent to exact shootdown membership;
- reloading a translation context too broadly in a fragile runtime path;
- using a virtual range different from the range actually unmapped.
ChrisOS addresses several of these through explicit shootdown state, polling, fencing and quarantine.
Other risks remain and are documented below.
Validation evidence
The current repository contains a dedicated host-side model test for the shootdown state machine in tools/test_tlb_proto.c.
The MM implementation also has a mapping self-test that verifies a 4 KiB alias reaches the same physical storage as its HHDM alias.
JIT close exercises a real unmap -> shootdown -> free/quarantine sequence at runtime.
The documentation CI additionally checks the source-bound memory-management contracts.
Still useful as future runtime evidence are:
- stress tests repeatedly mapping/unmapping the same VA across all CPUs;
- permission downgrade tests;
- deliberate IPI loss/stall injection;
- huge-page invalidation tests if huge-page mutation is added;
- process migration tests if user scheduling becomes SMP;
- performance measurements comparing INVLPG ranges with alternative invalidation strategies.
Current limitations
At the reviewed revision, ChrisOS does not implement:
- PCID-aware process switching;
- INVPCID;
- a threshold for switching from page-by-page INVLPG to wider invalidation;
- per-address-space CPU residency tracking;
- SMP execution of user processes;
- generalized permission-transition invalidation;
- huge-page creation/split invalidation policy;
- architecture-independent TLB abstraction;
- full-flush semantics in the zero-byte mm_tlb_shootdown wrapper.
The current implementation is a direct x86-64 mechanism built around 4 KiB mappings, CR3 switching, INVLPG and a custom global shootdown protocol.
Architectural references and revision boundary
The architectural concepts in this chapter correspond to x86-64 paging and invalidation behavior described by the Intel 64 and IA-32 Software Developer's Manual, especially the paging and translation-cache sections, and to the equivalent AMD64 architecture documentation.
ChrisOS-specific claims were reconciled against main revision e05a17fd76333114a3fb5c2452f38ca747d4ac56.
In particular, the distinction between local INVLPG, CR3-based local refresh, the range shootdown protocol, BSP-only user processes and JIT frame quarantine is derived from the declared source files rather than inferred from textbook VM behavior.