
CPU datapath and instruction-set architecture
About this chapter Datapath, microarchitecture and ISA
In this chapter
- CPU datapath and instruction-set architecture
- Processor as an architectural machine
- Datapath
- Instruction encoding
- Fetch, decode and execution
- ISA versus ABI
- Privileged architecture
- ChrisOS and architectural contracts
- State transition, observation and implementation
- One addition from bytes to visible state
- Address generation is not a memory load
- The run loop and instruction-pointer ownership
- Exceptions and the need for a commit boundary
- Physical pipelines and the interpreter's limits
- Lifecycle, interrupts and shared ownership
- Evidence and unresolved scope
Processor as an architectural machine
A CPU is not defined merely by the presence of an ALU. At the software boundary it is a state machine governed by an instruction-set architecture (ISA). The ISA specifies encodings and the visible consequences of executing them: register updates, memory accesses, control flow, exceptions and privilege effects.
A minimal architectural state contains a program counter, general registers, status flags and some means of addressing memory. x86-64 additionally exposes segment state, control registers, descriptor tables, model-specific registers and a large exception architecture.
Datapath
The datapath moves and transforms values. Its conceptual components include:
- register storage;
- arithmetic and logic unit;
- shifters and address-generation logic;
- instruction pointer update logic;
- paths to instruction and data memory;
- multiplexers selecting sources and destinations.
A simple register-register addition illustrates the contract:
The ISA may define carry, zero, sign and overflow flags even though the physical circuit that computes them is not visible.
Instruction encoding
Machine code is a byte representation of operations and operands. Assembly language gives symbolic names to those encodings. The assembler therefore does not create semantics; it translates a human-readable representation into the ISA-defined binary form.
Variable-length x86 instructions can contain prefixes, opcode bytes, ModR/M, SIB, displacement and immediate fields. Decode is correspondingly more complex than for many fixed-width RISC encodings.
Fetch, decode and execution
A pedagogical cycle is fetch → decode → execute. Real cores pipeline and overlap these stages, but the architectural result must be consistent with the ordering rules defined by the ISA.
Branches change the next instruction address. Calls additionally preserve a return point according to the software convention and instruction semantics. Loads and stores interact with the memory hierarchy and can fault before producing an architectural result.
ISA versus ABI
The ISA defines processor behavior. An application binary interface (ABI) defines conventions used by software built on top of the ISA: argument registers, caller/callee-saved registers, stack alignment, object formats and symbol rules.
Two operating systems can use the same x86-64 ISA with different syscall ABIs. A compiler must satisfy both the ISA encoding rules and the ABI expected by its environment.
Privileged architecture
Operating systems need mechanisms unavailable to ordinary applications. x86-64 supplies privilege levels and privileged instructions for operations such as changing page-table roots, installing descriptor tables, controlling interrupt state and configuring machine facilities.
The kernel's authority is therefore not a convention enforced by C. It is rooted in CPU privilege checks performed while executing machine instructions.
ChrisOS and architectural contracts
ChrisOS targets x86-64 for its principal kernel. kernel/metal contains code that uses the architecture directly: page-table roots, GDT/IDT installation, interrupt routing and context transitions.
ChrisVM approaches the same architecture from the opposite side. chrisvm/chris_arch.h defines architectural state that ChrisCPU must emulate. chrisvm/cpu/emulator/execute.c interprets decoded operations and updates that state.
This relationship makes the project useful for documentation:
| Kernel operation | Emulator responsibility |
|---|---|
| Execute MOV | Implement data-transfer semantics |
| Load CR3 | Update translation context |
| Receive a page fault | Detect and deliver the exception |
| Write an I/O port | Dispatch the operation to the bus |
The same ISA is a consumer-facing contract for the operating system and a producer-facing contract for the emulator.
State transition, observation and implementation
Let S contain architectural registers, memory and externally observable device state. An instruction is a partial transition T(S, bytes, events) that produces a new state or an architectural exception. The word partial matters: a byte sequence need not be a valid instruction, and a valid load need not name accessible memory. A processor cannot define correctness solely by its arithmetic result. It must also define which effects occur, their order, and which instruction address is reported when execution fails.
An ISA leaves substantial implementation freedom. A physical machine can represent a register using several renamed storage locations; an interpreter can represent it using a C integer. Both must present the prescribed value when software observes that register. Transistor topology, cache capacity and host C structure layout are therefore different layers of description. The shared ChrisArchitectureState describes the emulator's architectural model; it does not describe a fabricated processor's register file or promise a portable serialized snapshot format.
Three kinds of state need separation. Architectural state includes RIP and the general registers. Emulator bookkeeping includes halted, exit_reason, rip_dirty and counters. The surrounding machine owns memory and devices reachable through cpu->machine. Copying the architecture structure preserves only the first category. A reproducible whole-machine checkpoint also needs consistent RAM, pending device activity and emulator state. A copied pointer is not a copy of the pointed-to machine.
One addition from bytes to visible state
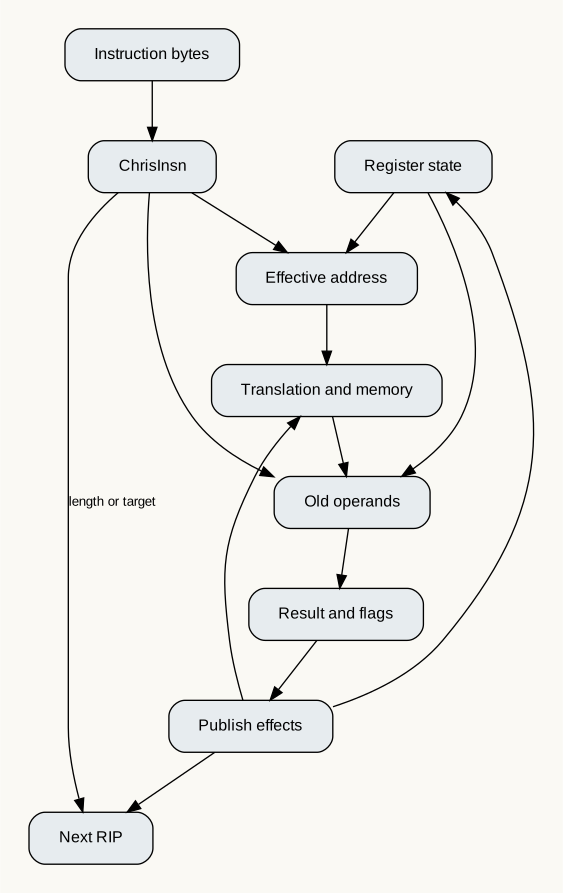
For the long-mode encoding 48 01 d8, the REX.W prefix selects a 64-bit operand. Opcode 01 selects addition with the register/memory operand as destination. ModR/M d8 selects register addressing, source RBX and destination RAX. The byte stream is three bytes long; it is not the three-character string written in an assembly listing.
| Stage | Representation | Required invariant |
|---|---|---|
| Fetch | Bytes at RIP | Reads obey execute-access rules |
| Decode | ChrisInsn |
Length, widths, operands and operation agree |
| Read | Old RAX and RBX | Both are obtained before overwriting RAX |
| Compute | Sum modulo 2⁶⁴ and flags | Signed overflow differs from unsigned carry |
| Write | New RAX and RFLAGS | Untouched architectural fields retain their values |
| Advance | RIP plus three | Applied once if no control transfer or halt supersedes it |
do_alu implements the operand-form distinction. For CHRIS_FORM_RM_REG, it reads the destination through chris_read_rm and the source through chris_read_regop. Because mod == 3, the former also reaches the general register array. chris_flags_bin receives both old operands, the operation, operand size and old flags; it returns new flags and writes the arithmetic result through an output pointer. Finally, chris_write_rm stores that result. CMP and TEST use the flag calculation without writing the result operand.
For old RAX equal to all ones and RBX equal to one, the stored result is zero, CF is set and ZF is set. OF is clear because signed −1 plus signed 1 is representable. The same bit pattern can therefore support distinct signed and unsigned predicates. Conditional branches must consult the relevant flags rather than infer signed order from carry alone. The arithmetic chapter and source probe validate these relationships independently of instruction decoding.
Address generation is not a memory load
An effective address usually combines a base, a scaled index and a signed displacement. chris_eff_addr computes this value from decoded fields. For RIP-relative addressing it uses the instruction's starting RIP plus its decoded length plus displacement. Otherwise it adds the selected base unless no_base is set, then an index shifted by scale unless no_index is set, then displacement. Address size four truncates the result to 32 bits.
This function does not read the memory being addressed. do_lea uses the computed value directly as a register result. A normal memory operand continues into chris_va_read or chris_va_write, where translation and permission checks can fail. This distinction explains why computing an address and dereferencing it are separate operations in both C and machine code. It also prevents attributing data-cache access or a page walk to every arithmetic use of LEA.
The inspected implementation does not add FS or GS bases in chris_eff_addr. Storage for those bases elsewhere in the architecture structure does not establish their participation in memory addressing. A documentation claim about thread-local storage must therefore trace the entire path from an encoded segment override to effective-address calculation, rather than infer support from the existence of an MSR field.
The run loop and instruction-pointer ownership
cpu_run first checks a configured breakpoint against current RIP. It fetches and decodes, formats the instruction and records a trace, clears rip_dirty, then invokes chris_execute. If execution returns an error without already choosing a halt or exit reason, the loop records an exception exit. It advances RIP by the decoded length only when rip_dirty is false and the CPU is not halted.
This flag gives instruction handlers ownership of nonsequential control flow. A taken branch writes its target and marks RIP dirty. A call additionally saves the return address on the stack. A return obtains a target from memory through the stack pointer. An instruction can therefore change control flow and fault on a data access in the same conceptual operation. Correctness depends on the order of those effects, not simply on adding an offset to RIP.
The trace is pushed before execution. Its presence proves that execution was attempted after decode; it does not prove successful retirement. Likewise steps and architectural tsc are incremented near the loop's end. These counters belong to this emulator's execution policy and cannot be interpreted as measurements of a real x86 pipeline's cycles. max_steps bounds loop iterations, not wall-clock duration or transistor switching activity.
Exceptions and the need for a commit boundary
A precise exception lets software identify the faulting instruction and recover using a defined architectural state. Implementations commonly separate preparation from commitment: read and validate inputs, calculate tentative results, then publish effects according to the instruction's rules. This is a conceptual contract; the interpreter does not automatically acquire transactional behavior because its handlers are C functions.
There is a concrete ordering concern in do_alu: it assigns new RFLAGS before attempting the destination write. If the destination is memory and its write fails, flags have already changed. Explaining this sequence is necessary for understanding the current implementation. It is not evidence that x86 permits arbitrary partial effects on a fault. An eventual correction needs instruction-specific fault-order tests, including memory destinations with readable but unwritable mappings.
fetch_insn also reads all 15 possible instruction bytes before decoding. Fifteen is the architectural maximum instruction length, not the number of bytes every instruction requires. A one-byte instruction at the end of an executable page can therefore cause this implementation to touch the next page unnecessarily. If that page is inaccessible, fetch fails before the decoder gets to accept the complete one-byte instruction. Incremental fetch/decode or a carefully specified bounded fetch strategy would address this issue; neither is claimed to be present here.
Physical pipelines and the interpreter's limits
A pipeline places registers between combinational stages so several instructions can occupy different stages simultaneously. In an ideal five-stage machine with equal stage time t, no stalls and one instruction admitted per cycle, n instructions take approximately (n + 4)t after starting from an empty pipeline. A nonoverlapped machine with the same five stages takes approximately 5nt. The first instruction still traverses five stages; improved throughput is not equivalent to fivefold lower individual latency.
Dependencies, branches and memory latency break the ideal schedule. A read-after-write dependency needs the earlier value and is a true data dependency. Write-after-read and write-after-write conflicts can arise from reusing architectural names; register renaming can remove those name conflicts while preserving true dependencies. Branch prediction speculates about future control flow, but incorrect speculation must not become committed architectural state.
ChrisCPU's inspected run loop is a sequential interpreter. It does not model pipeline occupancy, a reorder buffer, speculative cache effects or register renaming. A host processor may employ all those mechanisms while executing the interpreter, but that describes host execution, not an emulated guest microarchitecture. Performance claims must identify which machine they measure.
Lifecycle, interrupts and shared ownership
cpu_create rejects a null machine and a machine that already has a CPU, allocates zeroed CPU storage, copies tracing and breakpoint configuration, resets architectural state and installs the pointer in the machine. Allocation failure returns an error before installation. This establishes a single-CPU ownership relationship in this constructor; the unused CPU identifier is not evidence of multiprocessor execution.
cpu_reset resets architectural state and selected execution fields, including pending-interrupt and STI-delay state. It is not a whole-machine reset of all devices and memory. cpu_get and cpu_set copy the architecture structure. cpu_shutdown marks execution halted and assigns a shutdown exit reason; it does not free the machine. These operations have distinct lifecycle responsibilities and should not be substituted for one another in an embedding application.
Interrupt injection writes one pending flag and one vector. A second injection can replace the stored vector; this is not a queue of arbitrary outstanding events. maybe_irq first consumes a pending STI delay, then considers halt state, pending state and IF. Accepted delivery clears the pending flag and calls the exception/interrupt delivery path. No host-thread synchronization is visible in these functions. A caller cannot infer safe concurrent access merely because the emulated instruction stream is sequential.
Evidence and unresolved scope
The revision declared above binds these observations to the named files. Arithmetic probe results apply to the flag helper, while decoder and register fixtures apply to their own contracts. Documentation builds validate links, metadata and generation; they do not boot ChrisOS or certify privilege isolation. The remaining architectural chapters must develop byte encodings, register aliases, paging, privilege checks, cache coherence and atomic operations before higher-level kernel mechanisms can rely on them without hidden prerequisites.
For normative architecture, consult the Intel Software Developer's Manuals, especially instruction semantics and system programming. The equations for pipeline timing above are explicitly an analytical idealization. The fetch, state-copy and fault-order observations are source findings, not measurements of physical hardware.