
CLVM bytecode format and instruction set
About this chapter ChrisC and CLVM execution
In this chapter
- CLVM bytecode format and instruction set
- Scope
- Design model
- Byte order
- CLV version 1 header
- CLV version 2 header
- Flags
- Checksum
- Loader validation boundary
- Instruction framing
- Complete current opcode map
- Operand-stack order
- Integer representation
- Division faults
- Shift semantics
- Float representation
- Relative branches
- Conditional branches
- Direct calls
- Indirect calls
- CALLT and IL-oriented operations
- SYS encoding
- SAFEPOINT
- HALT and PRINT
- Encoding produced by ChrisC
- CLASM textual assembler
- CLASM operand limits
- Decoder synchronization
- JIT interaction
- Malformed bytecode behavior
- Security boundary
- Complexity
- Validation evidence
- Current limitations
- Roadmap boundary
- Source map and revision
Scope
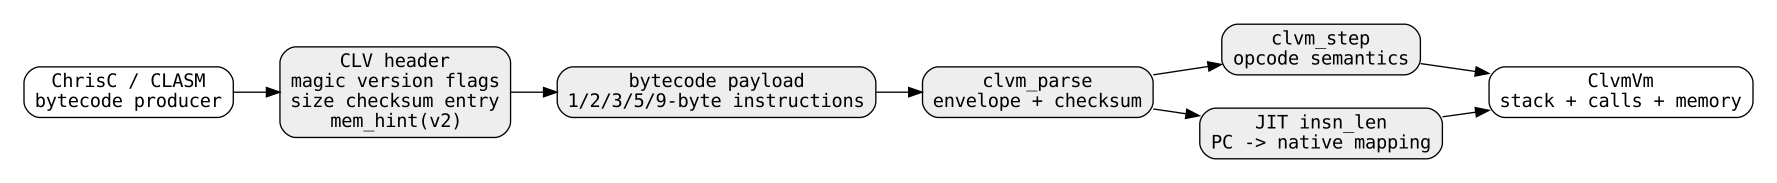
CLVM bytecode is the portable execution representation used by the ChrisC/CLVM path in ChrisOS. It is distinct from x86-64 machine code, distinct from ChrisO native objects, and distinct from the higher-level Node[] representation used inside the ChrisC compiler.
A CLVM program exists at two related layers:
- raw bytecode, a sequence of variable-length CLVM instructions;
- CLV image, a file envelope containing metadata, entry point, checksum, optional memory hint and the bytecode payload.
The runtime validates the CLV envelope, initializes a ClvmVm at the image entry PC, and then interprets or JIT-compiles the instruction stream.
This chapter defines the current encoded representation and instruction semantics. The memory model, syscall ABI and interpreter scheduling policy are covered separately.
Design model
CLVM is a stack-oriented virtual instruction set.
Most arithmetic and logical instructions take operands from the VM operand stack and push their result back onto that stack. Control-flow calls use a second, dedicated return-PC stack. Memory instructions interpret stack values as offsets into guest memory rather than native host pointers.
The machine therefore has three important address/value domains:
- bytecode PC: an offset into the code payload;
- operand value: a signed 64-bit slot in the VM operand stack;
- guest address: an integer offset interpreted against vm->memory.
The bytecode itself does not encode native registers.
This keeps instruction encoding compact and separates the ChrisC compiler from a specific host ISA.
Byte order
All multi-byte fields in the CLV envelope and all immediate operands decoded by the current implementation are little-endian.
clvm_format.c implements rd16, rd32, wr16 and wr32 explicitly byte by byte.
clvm_vm.c similarly reconstructs 32-bit and 64-bit immediates from little-endian byte sequences.
The format therefore does not depend on the host compiler's struct packing or the host CPU's native alignment rules.
No C structure is directly cast over the CLV file header.
CLV version 1 header
Version 1 uses a 16-byte header.
| Offset | Size | Field |
|---|---|---|
| 0 | 4 | magic: ASCII CLVM |
| 4 | 1 | version = 1 |
| 5 | 1 | flags |
| 6 | 2 | entry PC, little-endian u16 |
| 8 | 4 | code size, little-endian u32 |
| 12 | 4 | bytecode checksum, little-endian u32 |
| 16 | code_size | bytecode payload |
The v1 writer limits code size to 65535 bytes and requires entry < code_size.
The file size must be exactly:
16 + code_size
There are no trailing sections in the current v1 format.
CLV version 2 header
Version 2 expands the header to 24 bytes.
| Offset | Size | Field |
|---|---|---|
| 0 | 4 | magic: ASCII CLVM |
| 4 | 1 | version = 2 |
| 5 | 1 | flags |
| 6 | 2 | reserved, currently written as zero |
| 8 | 4 | code size, little-endian u32 |
| 12 | 4 | bytecode checksum, little-endian u32 |
| 16 | 4 | entry PC, little-endian u32 |
| 20 | 4 | guest-memory hint, little-endian u32 |
| 24 | code_size | bytecode payload |
Version 2 raises the entry-point range and allows the runtime to receive a memory-size hint.
CLVM_MAX_CODE is currently 16 MiB, so v2 code_size must be nonzero and no greater than that bound.
The current parser reads but does not assign independent semantics to the two reserved bytes at offsets 6-7.
Flags
The currently defined image flag is:
CLVM_FLAG_GAME = 0x01
CLVM_KNOWN_FLAGS contains only that flag.
clvm_parse rejects any image whose flags contain bits outside the known mask.
The presence of a game flag is image metadata; it does not modify opcode decoding.
Runtime components can use image metadata to select policy such as viewport or execution behavior, but the bytecode instruction encoding remains the same.
Checksum
Both image versions store a 32-bit FNV-1a checksum over the bytecode payload only.
The implementation starts with:
2166136261
For every code byte:
hash = (hash XOR byte) * 16777619 mod 2^32
clvm_parse recomputes the checksum and rejects an image when it differs from the header.
This protects against accidental corruption and malformed file transfer.
It is not a digital signature and does not authenticate a publisher.
Loader validation boundary
clvm_parse validates the image envelope.
It checks:
- non-null input and output pointers;
- minimum header size;
- CLVM magic;
- supported image version;
- known flag mask;
- code size;
- exact file-size agreement;
- entry point inside code;
- checksum.
The loader does not perform a full semantic verification pass over the instruction stream.
For example, it does not prove at load time that every branch targets the beginning of an instruction, that every execution path has a valid stack height, or that every immediate operand is fully present.
Those properties are handled later by execution checks, compiler construction rules, JIT compilation constraints and tests.
A future verifier could make the boundary stronger.
Instruction framing
Every instruction begins with one opcode byte.
Instruction length is determined by the opcode.
The current decoder uses five length classes:
| Total bytes | Encoding |
|---|---|
| 1 | opcode only |
| 2 | opcode + u8 |
| 3 | opcode + signed relative i16 |
| 5 | opcode + 32-bit immediate/relative field |
| 9 | opcode + 64-bit immediate |
The JIT's insn_len function is one executable statement of these widths.
The interpreter obtains operands with fetch, which checks that the requested immediate bytes still fit inside code_size.
A missing operand therefore becomes CLVM_FAULT_TRUNCATED when that instruction executes.
Complete current opcode map
The current opcode space is contiguous from 0x00 through 0x47.
The table below records the encoded length and principal operation.
| Hex | Mnemonic | Bytes | Principal effect |
|---|---|---|---|
| 00 | NOP | 1 | no state change |
| 01 | PUSH | 5 | push sign-extended i32 |
| 02 | ADD | 1 | a,b -> a+b |
| 03 | SUB | 1 | a,b -> a-b |
| 04 | MUL | 1 | a,b -> a*b |
| 05 | DIV | 1 | signed division |
| 06 | DUP | 1 | duplicate top value |
| 07 | 1 | pop into VM print ring | |
| 08 | HALT | 1 | halt VM |
| 09 | JMP | 3 | relative i16 jump |
| 0A | JZ | 3 | pop condition; jump if zero |
| 0B | CALL | 3 | relative i16 call |
| 0C | RET | 1 | return through call stack |
| 0D | LOAD | 1 | guest 32-bit signed load |
| 0E | STORE | 1 | guest 32-bit store |
| 0F | DROP | 1 | discard top if present |
| 10 | SWAP | 1 | exchange top two values |
| 11 | EQ | 1 | signed/integer equality |
| 12 | LT | 1 | signed less-than |
| 13 | JNZ | 3 | pop condition; jump if nonzero |
| 14 | MOD | 1 | signed remainder |
| 15 | NE | 1 | inequality |
| 16 | LE | 1 | signed <= |
| 17 | GT | 1 | signed > |
| 18 | GE | 1 | signed >= |
| 19 | NEG | 1 | arithmetic negation |
| 1A | LOADB | 1 | guest unsigned byte load |
| 1B | STOREB | 1 | guest byte store |
| 1C | CALLI | 1 | pop absolute bytecode target and call |
| 1D | UDIV | 1 | unsigned 64-bit division |
| 1E | UMOD | 1 | unsigned 64-bit remainder |
| 1F | ULT | 1 | unsigned < |
| 20 | SYS | 1 | pop syscall ID and dispatch |
| 21 | JMP32 | 5 | relative i32 jump |
| 22 | JZ32 | 5 | pop condition; relative i32 jump if zero |
| 23 | JNZ32 | 5 | pop condition; relative i32 jump if nonzero |
| 24 | CALL32 | 5 | relative i32 call |
| 25 | PUSH64 | 9 | push raw 64-bit immediate |
| 26 | LOAD64 | 1 | guest 64-bit load |
| 27 | STORE64 | 1 | guest 64-bit store |
| 28 | FLOAD | 1 | load 32-bit float bits |
| 29 | FSTORE | 1 | store low 32-bit float bits |
| 2A | FPUSH | 5 | push 32-bit float bit pattern |
| 2B | FADD | 1 | binary float addition |
| 2C | FSUB | 1 | binary float subtraction |
| 2D | FMUL | 1 | binary float multiplication |
| 2E | FDIV | 1 | binary float division |
| 2F | FNEG | 1 | float negation |
| 30 | FTOI | 1 | float-to-integer conversion |
| 31 | ITOF | 1 | integer-to-float conversion |
| 32 | FEQ | 1 | float equality |
| 33 | FLT | 1 | float < |
| 34 | FLE | 1 | float <= |
| 35 | AND | 1 | bitwise AND |
| 36 | OR | 1 | bitwise OR |
| 37 | XOR | 1 | bitwise XOR |
| 38 | SHL | 1 | left shift, count masked to 0..63 |
| 39 | SHR | 1 | logical right shift |
| 3A | SAR | 1 | arithmetic right shift |
| 3B | NOT | 1 | bitwise complement |
| 3C | LDARG | 2 | push indexed IL argument |
| 3D | STLOC | 2 | pop into indexed IL local |
| 3E | LDLOC | 2 | push indexed IL local |
| 3F | NEWOBJ | 5 | allocate guest object bytes |
| 40 | LDFLD | 5 | 64-bit field load at immediate offset |
| 41 | STFLD | 5 | 64-bit field store at immediate offset |
| 42 | CALLT | 5 | call absolute u32 bytecode PC |
| 43 | LDSTR | 5 | push u32 immediate as a VM value |
| 44 | SAFEPOINT | 1 | runtime safepoint |
| 45 | ULE | 1 | unsigned <= |
| 46 | UGT | 1 | unsigned > |
| 47 | UGE | 1 | unsigned >= |
Opcodes outside the implemented switch produce CLVM_FAULT_OPCODE when interpreted.
Operand-stack order
Binary operations pop the right operand first and then the left operand.
If the conceptual stack is:
[..., a, b] <- b is top
then ADD produces:
[..., a + b]
SUB produces a-b, DIV produces a/b and comparison instructions compare a against b.
This order matters for compiler lowering.
STORE-style instructions also use explicit stack order.
For STORE and STORE64, the address is at the top of the stack and the value immediately below it:
[..., value, address] -> [...]
STOREB follows the same convention.
STFLD differs only by adding an immediate field offset to the popped object address; its conceptual input is:
[..., object, value] -> [...]
because the implementation pops value first and object second.
Integer representation
The operand stack stores int64_t entries.
PUSH reads a four-byte immediate and sign-extends it from int32_t to int64_t.
PUSH64 reads all eight immediate bytes.
LOAD reads four guest-memory bytes, interprets them as a 32-bit integer bit pattern, casts through int32_t and pushes the sign-extended result.
LOADB pushes a value in the range 0..255.
LOAD64 preserves all 64 bits.
Signed and unsigned arithmetic use the same stack storage; the opcode selects whether values are interpreted through signed or uint64_t arithmetic/comparison rules.
Division faults
DIV, MOD, UDIV and UMOD reject a divisor of zero with CLVM_FAULT_DIV_ZERO.
Signed DIV and MOD additionally detect the two's-complement overflow case:
INT64_MIN / -1
and fault with CLVM_FAULT_DIV_OVERFLOW.
This avoids relying on undefined or host-specific trap behavior for that edge case.
Shift semantics
SHL, SHR and SAR mask the shift count with 63.
Therefore only the low six bits of the right operand select the shift distance.
SHR converts the left operand to uint64_t before shifting, implementing logical right shift.
SAR operates on the signed int64_t value, implementing the current arithmetic-right-shift behavior of the runtime.
Float representation
CLVM does not have a separate float stack.
Single-precision floating-point values are carried as their 32-bit IEEE-style bit pattern inside the low 32 bits of a 64-bit operand slot.
FPUSH reads a four-byte immediate bit pattern.
FLOAD and FSTORE transfer four bytes between guest memory and the operand representation.
For float arithmetic, the interpreter copies the low 32-bit pattern through the Fbits union and performs host float arithmetic.
FADD, FSUB, FMUL and FDIV then place the resulting 32-bit pattern back onto the VM stack.
FEQ, FLT and FLE push integer boolean results.
FTOI numerically converts the reconstructed float to an integer value.
ITOF converts the integer operand to float and pushes the resulting float bit pattern.
FDIV checks reconstructed divisor == 0.0f and reports CLVM_FAULT_DIV_ZERO.
The instruction set currently models single-precision values; this is not an encoded double-precision VM format.
Relative branches
JMP, JZ, JNZ and CALL contain a signed 16-bit displacement.
Their 32-bit forms contain a signed 32-bit displacement.
The relative base is the PC after the complete instruction has been fetched.
For a branch beginning at byte offset P with encoded length L:
target = P + L + displacement
The interpreter implements this because fetch advances vm->pc over the immediate before jump_rel16 or jump_rel32 adds the relative value.
Both jump helpers reject targets below zero or at/above code_size.
The target must be inside the code payload.
The helpers do not independently prove that the target points to an instruction boundary.
Conditional branches
JZ/JNZ and JZ32/JNZ32 always consume one condition value.
JZ branches when that value is zero.
JNZ branches when it is nonzero.
If the condition says not to branch, execution continues at the already advanced fall-through PC.
This makes the stack effect deterministic regardless of whether the branch is taken.
Direct calls
CALL and CALL32 use the same relative-target calculation as their corresponding jumps.
Before transfer, they push the post-instruction PC onto the dedicated vm->calls array.
The operand stack is not used to store the return PC.
RET pops from vm->calls and restores vm->pc.
The current return stack has 64 entries.
CALL on a full return stack faults with CLVM_FAULT_CALL_OVERFLOW.
RET on an empty return stack faults with CLVM_FAULT_CALL_UNDERFLOW.
Indirect calls
CALLI has no encoded immediate.
It pops an absolute bytecode target from the operand stack.
The interpreter checks:
0 <= target < code_size
then records the current PC in the return stack and sets vm->pc to that target.
This is the bytecode primitive used for indirect/function-pointer-style control transfer.
The value is a CLVM bytecode offset, not a native host function pointer.
CALLT and IL-oriented operations
CLVM also contains a small group of instructions used by its IL/managed-style facilities:
- LDARG;
- LDLOC;
- STLOC;
- NEWOBJ;
- LDFLD;
- STFLD;
- CALLT;
- LDSTR.
LDARG uses a one-byte index and accepts only indexes below 16.
LDLOC and STLOC accept only indexes below 32.
These correspond to fixed arrays in ClvmVm.
NEWOBJ contains a u32 size; zero is normalized to a 16-byte allocation. It allocates through clvm_guest_malloc and pushes the resulting guest offset.
LDFLD/STFLD contain a u32 byte offset and transfer 64-bit fields relative to a guest object address.
CALLT contains an absolute 32-bit code target and stores the return PC before transfer. The current interpreter assigns that immediate to vm->pc directly; an out-of-range value is consequently detected by the following instruction fetch as a PC fault rather than by the same immediate range check used by CALLI.
LDSTR pushes its u32 immediate as a VM value. The core interpreter does not itself dereference or type that value as a string.
These operations should not be confused with the ordinary ChrisC calling convention, which uses its own guest-memory argument scratch area.
SYS encoding
SYS has no immediate operand.
The syscall identifier is itself a stack value.
Conceptually:
[..., syscall arguments..., id]
    SYS
The VM pops id and calls the registered ClvmSysFn.
The callback may consume additional arguments and may push a result.
Therefore SYS does not have one universal stack delta; its complete stack contract is defined by the selected syscall ID.
If no callback exists or the callback rejects the operation, the interpreter reports CLVM_FAULT_BAD_SYS.
The numeric syscall ABI is documented separately.
SAFEPOINT
SAFEPOINT is one byte and has no operand-stack effect.
The interpreter marks vm->safepoint, calls on_safepoint when installed, clears the flag and can yield when scheduler policy requests a slice boundary.
Calls and allocation/syscall operations can also mark safepoint-related state.
The bytecode opcode provides an explicit runtime coordination point without changing program values.
HALT and PRINT
HALT transitions the VM to CLVM_HALTED and returns CLVM_STEP_HALT.
PRINT is not a direct dependency on a terminal device. It pops one value and records it through note_print in a bounded print ring inside ClvmVm.
That distinction keeps the core VM independent from a concrete console backend.
Encoding produced by ChrisC
ChrisC does not emit textual assembly and then invoke CLASM for its normal compiler path.
chrisc.c writes bytecode directly into its output buffer through emitter helpers.
One-byte instructions are emitted directly.
PUSH-style helpers append little-endian immediate bytes.
Branches reserve a displacement and patch it after the target PC becomes known.
The compiler selects 16-bit or wider branch forms where required by its lowering rules.
Function calls are patched against the recorded bytecode entry of the target function.
This direct emitter is one reason the instruction format must remain synchronized with the interpreter and JIT decoders.
CLASM textual assembler
compiler/clvm/clasm.c provides a separate textual assembler for CLVM.
It uses an OpInfo table containing mnemonic, opcode, encoded size and operand class.
The assembler operates in two passes.
Pass 1:
- parses instructions;
- computes bytecode PCs;
- records labels.
Pass 2:
- emits opcode bytes;
- writes immediate values;
- resolves labels into relative displacements.
For label branches:
rel = label_address - (instruction_pc + instruction_size)
Three-byte branches require rel in [-32768, 32767].
Five-byte branch forms write the 32-bit relative displacement.
The label named main becomes the assembler result entry point; otherwise entry defaults to zero.
CLASM operand limits
CLASM's numeric parser currently parses signed 32-bit values.
For PUSH64, the assembler writes the low 32 bits and sign-extends them into the high 32 bits.
Consequently textual CLASM PUSH64 is currently a sign-extended i32 source literal, even though the encoded VM instruction itself carries a full 64-bit immediate.
Other bytecode producers can encode arbitrary 64-bit PUSH64 bit patterns.
This distinction is between assembler frontend capability and bytecode capability.
Decoder synchronization
Several components need to agree on instruction width:
- interpreter operand fetch;
- JIT pre-scan and native-code generation;
- debugger/disassembly helpers;
- textual CLASM;
- compiler branch patching.
The JIT's insn_len currently recognizes:
- PUSH/FPUSH as 5 bytes;
- short jumps/calls as 3;
- LDARG/STLOC/LDLOC as 2;
- object/field/CALLT/LDSTR and long jumps/calls as 5;
- PUSH64 as 9;
- everything else as 1.
A bytecode-format change that modifies instruction width must update every decoder/producer that depends on those lengths.
This is a compatibility obligation, not merely a compiler implementation detail.
JIT interaction
The JIT uses bytecode PC as the stable VM control-flow identity.
During compilation it builds a mapping from bytecode PCs to generated native offsets.
Native implementations of branch/call opcodes must preserve CLVM-visible state such as vm->pc and vm->calls.
Instructions outside the JIT's direct-native set can be executed through helper paths while preserving the same ClvmVm semantics.
The JIT pre-scan is not a full bytecode verifier. Its primary purpose is to walk instruction widths and determine whether the image fits JIT constraints.
The interpreter remains the definitive per-opcode semantic implementation for paths handled through helpers.
Malformed bytecode behavior
Malformed images can fail at different boundaries.
Envelope defects fail in clvm_parse.
Execution defects can become VM faults:
| Defect | Current result |
|---|---|
| unknown executed opcode | CLVM_FAULT_OPCODE |
| missing immediate bytes | CLVM_FAULT_TRUNCATED |
| branch target outside code | CLVM_FAULT_BAD_JUMP |
| operand stack underflow | CLVM_FAULT_STACK_UNDERFLOW |
| operand stack overflow | CLVM_FAULT_STACK_OVERFLOW |
| return stack underflow/overflow | corresponding call fault |
| invalid guest address | CLVM_FAULT_BAD_ADDRESS |
| rejected syscall | CLVM_FAULT_BAD_SYS |
The VM records both fault kind and fault PC.
This gives the debugger/runtime a deterministic failure description rather than allowing normal interpreter memory operations to continue on invalid state.
Security boundary
The bytecode format alone is not a security sandbox.
Security depends on the combination of:
- CLV envelope validation;
- opcode bounds checks;
- guest-memory range checks;
- bounded VM stacks;
- syscall pointer validation;
- syscall ownership/capability checks;
- process/runtime isolation policy.
The checksum prevents accidental corruption but not malicious modification.
Likewise, accepting a syntactically valid opcode stream does not prove that its later syscalls are authorized.
Bytecode validation and syscall authorization are separate layers.
Complexity
Image parsing is O(code_size) because checksum validation reads the entire payload.
Instruction decode during interpretation is O(1) per ordinary instruction, excluding variable-cost syscalls and memory-copy services.
CLASM is effectively O(source_size + emitted_code_size) across its two linear passes, with bounded label-table searches that are small under the assembler's fixed limits.
Branch execution is constant time.
The fixed instruction encoding avoids variable-length prefix parsing of the type required by x86.
The trade-off is lower encoding density for some operations and dependence on an operand stack.
Validation evidence
tools/test_fuzz_clvm.c repeatedly feeds random short buffers into clvm_parse and verifies that loader errors remain inside the defined ClvmLoadError range. It also writes a valid image and verifies a successful parse round trip.
tools/test_clasm.c compiles textual CLASM and verifies generated bytecode and entry behavior.
tools/test_jit_vm.c compiles ChrisC into CLVM and compares important interpreter/JIT execution state.
tools/test_editor_vi.c contains its own instruction-length decoding for diagnostics/regression work and exercises call-stack overflow behavior across interpreter and JIT.
The broader ChrisC tests execute generated CLVM programs, providing indirect coverage of arithmetic, branches, calls, loads/stores and syscall emission.
These tests provide evidence for implemented behavior. They do not constitute a formal proof that every arbitrary byte stream is safe or semantically valid.
Current limitations
At the documented revision:
- there is no standalone full bytecode verifier before execution;
- CLV images contain a single code payload rather than a general section table;
- symbols, relocations and debug maps are not embedded as first-class CLV sections;
- checksum is FNV-1a, not cryptographic authentication;
- v1 entry is limited to 16 bits;
- v2 still uses a simple flat header and payload;
- branch targets are range-checked but are not globally proven to be instruction boundaries by clvm_parse;
- ordinary VM stack effects are not statically checked;
- CALLT target validation occurs through subsequent execution rather than the same immediate check as CALLI;
- CLASM numeric literals are i32-limited even for encoded PUSH64;
- float bytecode models single precision;
- decoder width knowledge exists in multiple components and must remain synchronized.
Roadmap boundary
A future bytecode revision could add:
- a formal verifier pass;
- explicit section tables;
- embedded symbols and source maps;
- relocation/module metadata;
- capability or import declarations;
- bytecode feature/version flags;
- stronger integrity/authenticity metadata;
- typed stack verification;
- exact instruction-boundary maps;
- larger or structured constant pools.
Any such change would require explicit versioning because the byte stream is consumed by the compiler, loader, interpreter, JIT, debugger and tooling.
Until implemented, the current v1/v2 format and opcode map described above are the operative contract.
Source map and revision
The image constants, opcode numbers and public image structures are defined in compiler/clvm/clvm.h.
Header encoding, decoding and checksum validation are implemented in compiler/clvm/clvm_format.c.
Instruction execution and runtime fault behavior are implemented in compiler/clvm/clvm_vm.c.
Textual assembly encoding is implemented in compiler/clvm/clasm.c.
ChrisC's direct bytecode producer is implemented in compiler/chrisc/chrisc.c.
The JIT's instruction-width decoder and bytecode-to-native mapping are implemented in compiler/jit/jit_compile.c.
All current-behavior claims in this chapter were reconciled against ChrisOS revision e05a17fd76333114a3fb5c2452f38ca747d4ac56.