
Branch prediction and speculative execution
About this chapter Datapath, microarchitecture and ISA
In this chapter
- Branch prediction and speculative execution
- Scope
- Why control hazards reduce throughput
- Direction prediction and target prediction
- Static prediction
- One-bit dynamic predictor
- Two-bit saturating counters
- Local and global history
- Gshare
- Predictor aliasing
- Branch Target Buffer
- Return Address Stack
- Indirect branch prediction
- Speculative fetch
- Speculative execution
- Branch resolution
- Recovery from misprediction
- Predictor training timing
- Predictor accuracy and MPKI
- Accuracy is workload-dependent
- Control flow in current ChrisCPU
- Current ChrisCPU has no predictor state
- A minimal predictor architecture for future ChrisCPU
- Prediction record per in-flight branch
- Flush invariants
- Exception interaction
- Interrupt interaction
- Predictor state and context changes
- Speculation and side channels
- Determinism
- Validation strategy
- Metrics
- Complexity
- Current limitations
- Roadmap boundary
- Revision record
Scope
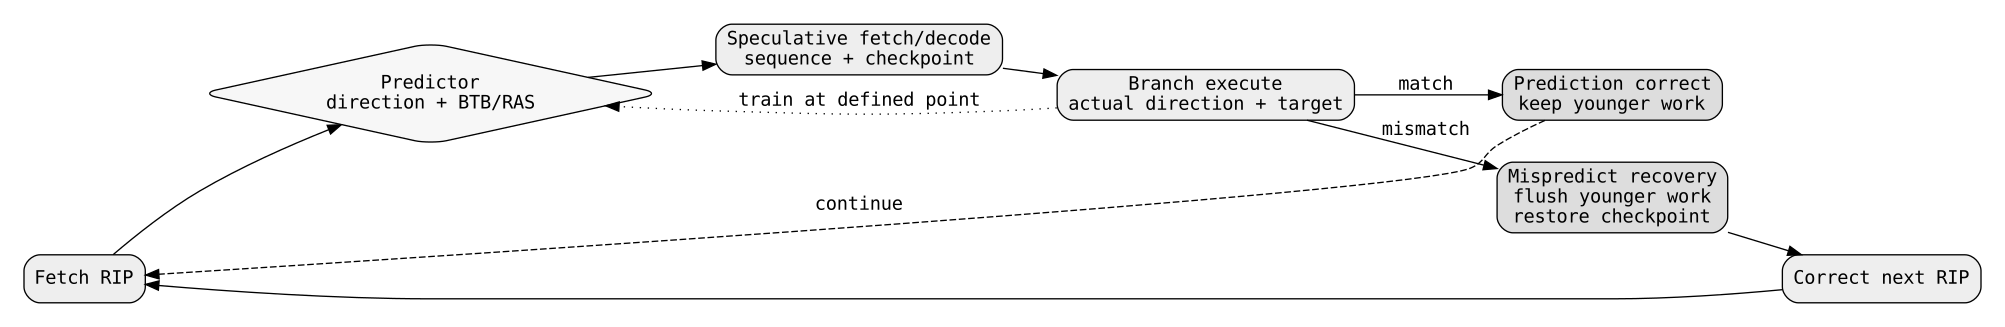
A pipelined processor must decide what to fetch before every older branch has necessarily reached the point where its true direction and target are known. A branch predictor is a microarchitectural mechanism that guesses future control flow so the front end can continue supplying useful work. Speculation is the broader act of allowing operations based on that guess to proceed before the guess is architecturally confirmed.
Prediction is not part of the x86-64 architectural state. Correct software cannot depend on a particular predictor algorithm, table size or history length. The architectural requirement is that a wrong prediction must be recoverable: instructions from an incorrect path must not commit architectural effects.
The current ChrisCPU implementation does not predict branches. It executes one architectural instruction at a time, resolves control flow synchronously and only then starts the next iteration. The theory in this chapter therefore describes real processor microarchitecture and a possible future timing-oriented ChrisCPU backend, not current interpreter behavior.
Why control hazards reduce throughput
Consider a five-stage teaching pipeline where a conditional branch is resolved in EX. When the branch enters IF, the processor does not yet know whether the next architectural instruction is:
fallthrough = branch_rip + branch_length
or:
target = fallthrough + signed_displacement
If fetch waits until EX determines the branch, the front end can lose several cycles per branch. If branches occur with frequency B and each unresolved branch introduces P lost cycles, an idealized CPI contribution is:
CPI_control = B * P
With prediction accuracy A and misprediction recovery cost M, a simplified contribution becomes:
CPI_mispredict = B * (1 - A) * M
This is a teaching model. Real machines overlap work, branch resolution occurs at different depths for different branch types, multiple branches can be in flight and front-end bandwidth can create additional penalties.
The important conclusion is structural: prediction matters because modern pipelines need a next fetch address before the true control-flow decision is always available.
Direction prediction and target prediction
A conditional branch creates at least two questions.
- Direction: will the branch be taken?
- Target: if taken, what address should fetch use?
For a direct relative Jcc, the target can often be computed from the decoded displacement. However, the front end may need a target before complete decode. A Branch Target Buffer (BTB) can cache control-flow targets keyed by fetch address.
Indirect jumps and calls are harder because their target depends on a register or memory operand. Returns are special indirect branches whose targets often follow call-stack structure and can be predicted by a Return Address Stack (RAS).
A practical front end therefore separates several predictor roles:
| Structure | Typical purpose |
|---|---|
| Direction predictor | Predict taken/not-taken for conditional branches |
| BTB | Predict target and often branch presence/type |
| RAS | Predict return targets |
| Indirect predictor | Predict register/memory-derived targets |
| History state | Capture recent branch behavior for correlation |
These structures are implementation choices, not ISA-visible resources.
Static prediction
The simplest strategy does not learn from runtime behavior.
Examples include:
- always not taken;
- always taken;
- backward taken, forward not taken;
- compiler-supplied hints on architectures that support meaningful hints.
Static prediction has almost no training state and is easy to reproduce in a simulator. Its limitation is obvious: it cannot adapt to program phase or data-dependent branch behavior.
Static prediction is a reasonable first step for a teaching pipeline because it tests redirect and flush correctness before dynamic predictor state is introduced.
One-bit dynamic predictor
A one-bit predictor stores the previous observed outcome for each indexed branch.
State:
0 = predict not taken
1 = predict taken
Update:
state <- actual_outcome
For a loop branch that is taken many times and not taken once at loop exit, a one-bit predictor often mispredicts twice across repeated invocations:
- once on exit, because the previous iterations were taken;
- once on the first iteration of the next invocation, because the exit trained the predictor to not taken.
This motivates hysteresis.
Two-bit saturating counters
A common teaching predictor uses four states:
00 strongly not taken
01 weakly not taken
10 weakly taken
11 strongly taken
The most significant bit forms the prediction. Taken increments the counter up to 11; not-taken decrements it down to 00.
Pseudocode:
predict = counter >= 2

if actual_taken:
    counter = min(counter + 1, 3)
else:
    counter = max(counter - 1, 0)
The predictor needs two consecutive opposite outcomes to move from a strong state to predicting the other direction. This reduces sensitivity to isolated loop exits.
If a table has N two-bit entries, raw direction state costs 2N bits, excluding tags or metadata. If the table is indexed by low branch-address bits without tags, unrelated branches can alias the same entry. Aliasing may help accidentally, do no harm, or degrade accuracy.
Local and global history
Some branches correlate with their own recent outcomes. Others correlate with different branches.
A local-history predictor can maintain, per branch or per index, a shift register of recent outcomes. That history indexes a pattern table.
A global-history predictor maintains a single recent sequence of branch outcomes:
GHR = ((GHR << 1) | actual_taken) & history_mask
A pattern table indexed by GHR can learn cross-branch correlation. However, different static branches then share the same history patterns unless the branch address is also incorporated.
Gshare
Gshare combines the branch address and global history, commonly using XOR:
index = (branch_index_bits XOR GHR) & mask
The intuition is that address bits distinguish static branches while GHR captures recent path history. XOR spreads combinations across the pattern table without requiring a two-dimensional structure.
For a table of 2^k counters and k-bit history, storage includes:
- 2^(k+1) bits for two-bit counters;
- k bits for the global history register;
- optional tags or confidence metadata if the design adds them.
Increasing k can improve correlation capacity but also increases table size and can increase destructive aliasing when the table is too small relative to working-set behavior.
Predictor aliasing
A finite predictor maps a large address/history space into a smaller table. Therefore different contexts inevitably collide.
If two branches map to the same counter and prefer opposite outcomes, they can repeatedly overwrite each other's learned state. This is destructive aliasing.
Tagged predictors reduce some forms of aliasing by storing partial identity information. More advanced designs combine multiple history lengths and tables. The principle remains the same: prediction is a storage-allocation problem as well as a statistical one.
In a simulator, aliasing should be deliberate and reproducible. A predictor with an unbounded dictionary keyed by full RIP behaves differently from finite hardware and may hide conflicts that real predictors experience.
Branch Target Buffer
A BTB predicts that a fetch address corresponds to a control-flow instruction and supplies a likely target.
A conceptual entry might contain:
| Field | Meaning |
|---|---|
| valid | entry can participate in lookup |
| tag | distinguishes addresses sharing an index |
| target | predicted destination |
| type | conditional, jump, call, indirect, return |
| metadata | replacement/confidence information |
On a hit, the front end may redirect before the instruction is fully decoded. On a miss, fetch may continue sequentially until decode or execution discovers the control transfer.
A BTB is not the same as a direction predictor. A conditional branch can be predicted not taken even when a BTB entry exists. Conversely, a branch predicted taken requires a usable target.
Return Address Stack
Calls and returns have stack-like control flow:
call function
    ...
    ret
A RAS predicts returns by pushing the fallthrough address of a call and popping it on a return.
Conceptually:
on predicted call:
    RAS.push(call_rip + call_length)

on predicted return:
    target = RAS.top()
    RAS.pop()
Real behavior becomes difficult with exceptions, unusual control transfers, stack overflow/underflow, speculative calls, wrong-path execution and context changes. A speculative RAS may need checkpoint or recovery logic so wrong-path pushes and pops can be undone.
The architectural call stack in memory and the microarchitectural RAS are different structures. Software correctness depends on the former, not on predictor state.
Indirect branch prediction
An indirect branch target is obtained from architectural state rather than from a fixed encoded displacement. Examples include:
- jump through a function pointer;
- virtual dispatch;
- switch dispatch;
- indirect call;
- return.
A simple predictor can remember the last target for a branch address. More advanced predictors include history because the target often depends on execution path.
Indirect prediction is especially sensitive to aliasing because both branch identity and target identity matter.
Speculative fetch
Once a prediction exists, fetch can proceed from the predicted next RIP before the branch is resolved.
A speculative instruction must carry enough identity to be invalidated if necessary. Useful metadata can include:
- sequence number or age;
- predicted next RIP;
- prediction source/type;
- predictor index used;
- history snapshot;
- branch checkpoint identifier;
- valid bit.
This is microarchitectural bookkeeping. The instruction's architectural meaning remains unchanged.
Speculative execution
Prediction becomes more valuable when younger instructions are allowed to decode or execute before older branches resolve. That is speculative execution.
The central safety rule is:
Speculative work may consume internal resources and produce transient microarchitectural state, but it must not irreversibly modify architectural state before the speculation is validated.
In an in-order pipeline, this can mean delaying side effects until a stage after branch resolution. In an out-of-order machine, speculative results typically live in physical registers, queues and reorder structures until retirement.
Memory and device effects require particular care. A wrong-path MMIO write must not escape simply because its address and data were computed.
Branch resolution
A conditional branch is resolved when the processor knows:
- the actual condition outcome;
- the correct target or fallthrough;
- whether the prediction matched.
For a Jcc-like branch:
actual_taken = condition(RFLAGS)

if actual_taken:
    actual_next = branch_rip + length + displacement
else:
    actual_next = branch_rip + length
A misprediction occurs if either direction or predicted target differs from the actual next address.
Resolution can happen earlier or later depending on where operands and flags become available. Moving branch execution earlier reduces penalty but may increase front-end complexity or require additional forwarding paths.
Recovery from misprediction
A correct recovery mechanism must:
- identify the branch whose prediction failed;
- compute the correct next RIP;
- invalidate all younger wrong-path instructions;
- restore speculative metadata changed by those instructions;
- redirect fetch;
- preserve older valid instructions and committed architectural state.
In a minimal scalar pipeline, "invalidate younger instructions" may simply clear valid bits in IF/ID and ID/EX.
In a predictor with speculative global history, recovery also needs to restore history. A branch checkpoint can save the pre-branch history value, or the design can reconstruct it using ordered metadata.
With register renaming and out-of-order execution, recovery additionally restores a rename-map checkpoint or rebuilds it from committed state. That is covered in the next chapter.
Predictor training timing
A subtle design choice is when predictor state is updated.
Options include:
- when the branch executes;
- when the branch becomes non-speculative;
- at retirement.
Updating early can make learning available sooner but requires undo or contamination policy when the updating branch itself is later squashed by an older misprediction or exception.
For a first ChrisCPU timing model, training at architectural retirement is easier to reason about. It may be less realistic than some physical designs, but it gives a clean invariant: only non-squashed branches train permanent predictor state.
If speculative history is needed for prediction before retirement, it should be held separately from committed predictor history or checkpointed.
Predictor accuracy and MPKI
Accuracy is:
accuracy = correct_predictions / total_predictions
Accuracy can be misleading when branch frequency varies. Another useful metric is mispredictions per thousand instructions:
MPKI = 1000 * mispredictions / retired_instructions
A predictor can have high percentage accuracy and still cause meaningful performance loss if branches are frequent and the recovery penalty is large.
A simplified lost-cycle estimate is:
lost_cycles ~= mispredictions * average_recovery_penalty
This excludes secondary effects such as cache pollution, instruction-window disruption and lost memory-level parallelism.
Accuracy is workload-dependent
No predictor has one universal accuracy. Results depend on:
- code structure;
- input data;
- compiler transformations;
- inlining;
- address placement;
- branch working set;
- history length;
- table size;
- context switching;
- phase changes.
Therefore a ChrisCPU predictor benchmark should report the workload, instruction count, branch count and configuration rather than present one percentage as a property of the predictor itself.
Control flow in current ChrisCPU
The current interpreter resolves control flow synchronously.
For conditional branches, do_jcc computes the signed relative displacement and calls chris_cc_true using the current architectural RFLAGS. If the condition is true, it writes the target to arch.rip and sets rip_dirty. If the condition is false, it leaves RIP unchanged and cpu_run advances RIP by the decoded instruction length.
Direct or indirect jump execution in do_jmp writes the destination and marks rip_dirty.
do_call computes the next architectural RIP, pushes it through the emulator stack path, writes the destination and marks rip_dirty.
do_ret pops the destination, updates RSP according to the instruction and writes RIP.
The loop therefore never needs a guessed architectural RIP. Before the next iteration begins, the current instruction's actual control-flow effect is already known.
Current ChrisCPU has no predictor state
The reviewed ChrisCpu structure contains execution, IRQ, tracing, TLB-generation and break-state fields, but no fields corresponding to:
- branch history table;
- pattern history table;
- BTB;
- RAS;
- indirect-target predictor;
- prediction confidence;
- speculative history;
- branch checkpoints;
- misprediction counters.
Searches of the current source revision also show no implementation of a reorder buffer or rename map that could hold deeper speculative state.
This absence is an important architectural boundary. A trace of current ChrisCPU shows actual executed control flow, not predicted and subsequently squashed paths.
A minimal predictor architecture for future ChrisCPU
A first timing model should prefer an explicit, inspectable predictor over a complex design.
A useful initial configuration:
1024-entry direction table
2-bit saturating counters
256-entry tagged BTB
16-entry RAS
static fallback on BTB miss
Possible structures:
typedef struct {
    uint8_t counter;
} BranchCounter;

typedef struct {
    bool valid;
    uint64_t tag;
    uint64_t target;
    uint8_t type;
} BtbEntry;

typedef struct {
    BranchCounter pht[1024];
    BtbEntry btb[256];
    uint64_t ras[16];
    unsigned ras_top;
} BranchPredictor;
This is conceptual, not current source.
The predictor should be configured independently from architectural state so differential functional execution remains possible.
Prediction record per in-flight branch
Every predicted branch should retain a record sufficient for validation:
| Field | Purpose |
|---|---|
| branch_rip | identity of the branch |
| predicted_taken | direction prediction |
| predicted_target | predicted next address |
| fallthrough | sequential next address |
| predictor_index | entry used for training |
| history_before | recovery/checkpoint state |
| sequence | instruction age |
| valid | branch still in flight |
At resolution, the machine compares prediction against actual outcome and target.
A single boolean "was predicted" is insufficient when tables, histories and recovery state exist.
Flush invariants
A future speculative ChrisCPU should enforce:
- No wrong-path instruction can retire.
- No wrong-path store, MMIO or port-I/O effect can become externally visible.
- A misprediction removes every younger instruction and no older instruction.
- Fetch resumes at the correct architectural next RIP.
- Predictor recovery does not restore state older than the branch checkpoint.
- Exceptions from squashed instructions are not delivered architecturally.
- A branch trains the predictor according to a defined policy exactly once.
These invariants are testable independently of prediction accuracy.
Exception interaction
Suppose a younger speculative instruction generates a page fault while an older branch later proves that the instruction was on the wrong path. The fault must not be delivered architecturally.
Therefore exception information produced by speculative instructions has to be attached to the instruction record, not immediately applied to committed machine state.
This is a significant difference from the current functional path, where helpers such as memory translation can invoke chris_raise directly during execution. A future speculative backend must either:
- provide non-committing semantic helpers that return fault descriptors; or
- execute against shadow/speculative state and defer architectural exception injection.
Reusing side-effecting functional helpers without this separation would make speculation difficult to roll back correctly.
Interrupt interaction
External interrupts should be recognized at a defined architectural boundary. Prediction state may contain many younger speculative instructions when an interrupt becomes eligible.
A simple model can:
- stop accepting new speculative work;
- retire older instructions to a chosen boundary;
- flush younger instructions;
- deliver the interrupt using committed architectural state;
- resume fetch at the handler RIP.
More aggressive machines can use more complex rules, but architectural visibility must remain precise.
Predictor state and context changes
Branch predictor structures are normally microarchitectural rather than process-owned architectural state. Sharing or partitioning policies have performance and security implications.
For an educational emulator, possible policies include:
- preserve predictor state across guest context switches;
- flush predictor state on selected privilege transitions;
- maintain per-address-space predictor state;
- make behavior configurable for experiments.
The chosen policy should be documented because it changes benchmark behavior even though architectural correctness remains the same.
Speculation and side channels
Speculative instructions can affect microarchitectural state even when their architectural results are later discarded. Cache fills, predictor updates and resource contention can create timing differences observable by later code.
This is the general class of issue highlighted by speculative-execution attacks such as Spectre. The essential lesson for a simulator is not to claim security merely because wrong-path instructions do not retire. If the simulator models timing-visible caches or predictor state, speculative updates may themselves become observable.
A first functional teaching model can deliberately avoid modeling these side channels. If timing and shared microarchitectural state are later added, the security boundary must be revisited explicitly.
Determinism
A documentation-oriented simulator should be reproducible.
Predictor behavior should therefore avoid hidden randomness unless a deterministic seed is part of configuration. Configuration should record:
- table sizes;
- history length;
- initial counter state;
- replacement policy;
- RAS depth;
- context-flush policy;
- training point.
A trace can then include prediction decisions:
cycle 1042
RIP 0xffffffff80001230
JNE +0x24
predicted: taken -> 0xffffffff80001256
actual: not-taken -> 0xffffffff80001236
recovery: flush seq > 801
This makes the microarchitecture inspectable.
Validation strategy
Validation should separate correctness from quality of prediction.
Correctness tests
- always-taken branch;
- always-not-taken branch;
- alternating branch;
- nested calls and returns;
- direct jump;
- indirect jump;
- misprediction followed by a store on the wrong path;
- misprediction followed by a fault on the wrong path;
- branch whose flags are forwarded from an older instruction;
- interrupt arriving while speculative work exists.
The committed architectural result must match the current functional interpreter.
Predictor-state tests
For a two-bit counter:
start = 01
T -> 10
T -> 11
N -> 10
N -> 01
N -> 00
N -> 00
For global history, verify bit shifting and masking exactly.
For BTB, verify index/tag behavior and replacement.
For RAS, verify nested calls, overflow policy, underflow policy and recovery from a squashed speculative call.
Differential execution
Run the same program under:
- functional ChrisCPU;
- timing ChrisCPU with prediction disabled;
- timing ChrisCPU with prediction enabled.
Architectural retirement sequence should be equivalent. Cycle counts and speculative traces are allowed to differ.
Metrics
A timing backend should expose, at minimum:
- retired instructions;
- conditional branches;
- predicted branches;
- correct predictions;
- direction mispredictions;
- target mispredictions;
- BTB hits/misses;
- RAS hits/misses;
- pipeline flush count;
- cycles lost to control recovery.
Derived values include accuracy, MPKI and average recovery penalty.
These counters should not be mixed with architectural TSC unless the emulator explicitly defines a timing model for TSC.
Complexity
A direct-mapped predictor-table lookup is O(1). A set-associative BTB with A ways is O(A) in a straightforward software simulator. RAS push/pop is O(1).
History-based predictors can remain O(1) per branch if their index calculation and number of tables are fixed.
The larger cost in a detailed simulator is usually not predictor lookup itself but maintaining speculative instruction state, checkpoints and recovery.
Current limitations
At the reviewed revision, ChrisCPU does not model:
- branch direction prediction;
- BTB target prediction;
- return prediction;
- speculative fetch;
- wrong-path decode or execution;
- branch checkpoints;
- predictor training;
- branch misprediction penalty;
- predictor side channels.
Current branch execution is functional and synchronous.
Roadmap boundary
A safe implementation sequence is:
- add explicit branch classification and actual outcome/target records;
- implement static prediction in a timing-only backend;
- prove flush and recovery against the functional interpreter;
- add two-bit direction counters;
- add a tagged BTB;
- add RAS prediction for call/return;
- add global history and gshare as an optional predictor;
- make speculative history checkpointing explicit;
- integrate predictor state with future rename/ROB checkpoints;
- only then consider more complex indirect or multi-table predictors.
Prediction sophistication should never outrun recovery correctness.
Revision record
This chapter was reconciled against ChrisOS main revision e05a17fd76333114a3fb5c2452f38ca747d4ac56. Current implementation claims are limited to the declared source files. Predictor algorithms, timing equations and speculative structures are architectural theory and proposed future design, not claims that ChrisCPU currently implements them.