
Compiler construction pipeline in ChrisOS
About this chapter Compiler construction
In this chapter
- Compiler construction pipeline in ChrisOS
- Scope
- Why the stages matter
- Pipeline A: ChrisC to CLVM
- ChrisC resource model
- Preprocessing in ChrisC
- Lexical analysis in ChrisC
- Parsing and internal representation
- Semantic state in ChrisC
- ChrisC code generation
- No relocatable-object stage in ChrisC
- CLVM assembly path
- CLVM image creation
- Integration cap versus format cap
- Runtime image policy
- Debug/source maps
- Execution after CLVM compilation
- Guest-compiler path and bootstrap behavior
- What lang_make_cc proves
- Pipeline B: KCC to native ELF64
- KCC preprocessing
- KCC parsing and semantic model
- KCC backend
- ChrisAsm
- Local versus external fixups
- ChrisO object format
- ChrisO serialization
- KCC inside ChrisOS
- ChrisLd
- Entry-point selection
- Relocation support
- ELF output
- Why ChrisO exists instead of direct ELF objects
- Two different notions of “linking”
- Diagnostics
- Failure propagation
- Optimization model
- ABI boundaries
- Reentrancy and concurrency limits
- Memory ownership
- Validation: ChrisC path
- ChrisC fuzz smoke
- Validation: native path
- What the tests do not yet prove
- Current limitations
- Roadmap boundary
- Source map and revision note
Scope
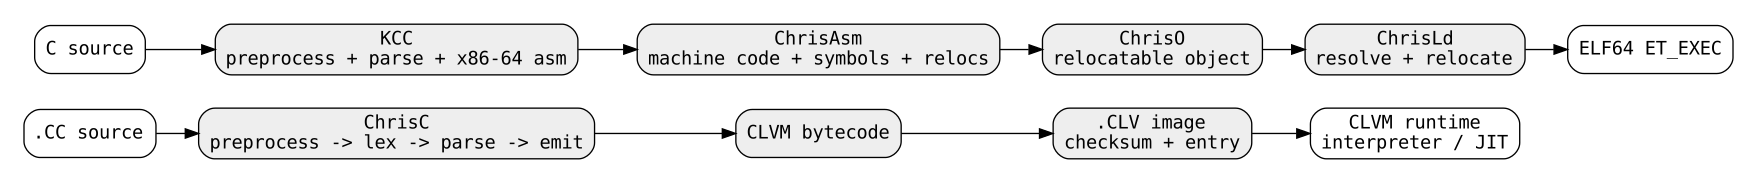
ChrisOS does not have one monolithic compiler pipeline.
It currently has two distinct translation families:
- ChrisC / CLVM, used for applications, drivers and other code that executes through the CLVM runtime.
- KCC / ChrisAsm / ChrisO / ChrisLd, used to translate a project-specific C profile into native x86-64 code and final ELF64 executables.
Those pipelines share compiler concepts, but they do not share one frontend, one intermediate representation or one object format.
The first path is fundamentally a virtual-machine pipeline:
.CC source
   -> ChrisC preprocessing
   -> tokens
   -> internal syntax/semantic structures
   -> CLVM bytecode
   -> .CLV image
   -> CLVM interpreter or JIT
The native path is fundamentally a separate-compilation pipeline:
C source
   -> KCC preprocessing/parsing
   -> textual x86-64 assembly
   -> ChrisAsm
   -> ChrisO relocatable object
   -> ChrisLd
   -> ELF64 ET_EXEC
   -> native x86-64 execution
A third source form, .CVA, is CLVM assembly and goes through clasm_compile directly to CLVM bytecode.
This chapter maps the standard compiler stages onto those concrete implementations and records the current boundaries between implemented behavior and roadmap.
Why the stages matter
The usual textbook decomposition remains useful:
source text
 -> preprocessing
 -> lexical analysis
 -> parsing
 -> semantic checks
 -> intermediate representation
 -> code generation
 -> object/image generation
 -> linking/loading
 -> execution
But real compilers can combine stages.
ChrisOS does that aggressively.
ChrisC has explicit tokens and node structures, but it emits CLVM bytecode without a separate reusable SSA-style IR.
KCC has preprocessing, type/symbol state and parser/code-generation logic, but emits assembly text directly rather than first building a general optimizer IR.
Therefore the actual implementation should not be documented as if it were LLVM-like merely because the conceptual compiler pipeline contains an “IR” stage.
Pipeline A: ChrisC to CLVM
Source entry points
The core frontend API is declared in:
Important entry points include:
chrisc_compile is the simplest in-memory interface.
chrisc_compile_ex adds a source path and callback-driven include/file loading.
chrisc_compile_files_ex compiles multiple source paths inside one compiler invocation and can report progress.
The operating-system integration lives mainly in:
where editor, filesystem, CLVM image, process, debugger and execution concerns are connected.
ChrisC resource model
ChrisC is a large static compiler context rather than a graph of heap-allocated compiler objects.
Important fixed limits in the current source include:
source buffer          4 MiB
tokens                 262,144
nodes                  131,072
symbols                16,384
functions              4,096
struct definitions     1,024
include depth          16
source map entries     8,192
reported diagnostics   8
Those are implementation ceilings, not language-standard guarantees.
The compiler also owns large static translation-unit, include-cache, token, AST-like node and lookup-table buffers.
Preprocessing in ChrisC
chrisc_compile_ex starts by resetting compiler state and then builds an expanded translation unit.
The current preprocessing machinery includes concepts such as:
- include loading through a callback;
- include caching;
- macros;
- conditional preprocessing state;
- pragma-once tracking;
- file/line mapping;
- built-in definitions.
The expanded text is stored in compiler-owned buffers.
Line mapping is retained so later diagnostics and debug-map entries can refer back to original files and lines.
Lexical analysis in ChrisC
After preprocessing, ChrisC calls its lexer over the expanded source.
The token model includes identifiers, integer and floating literals, strings, C-like keywords, operators and punctuation.
The current token enum covers constructs including:
- arithmetic and comparison;
- pointers and address operators;
- structures and unions;
- enums and typedefs;
- loops and switch;
- goto/labels;
- casts and sizeof;
- static assertions and alignment forms;
- qualifiers such as const, volatile and restrict;
- selected C11/C17-style constructs used by the project.
The presence of a token does not by itself imply complete ISO C conformance.
ChrisC remains a project compiler with its own supported profile.
Parsing and internal representation
ChrisC stores parsed program structure in a fixed node array.
The node model includes forms for:
- blocks and declarations;
- assignments;
- control flow;
- integer/float/string expressions;
- calls;
- unary/binary operations;
- indexing;
- field access;
- pointer dereference/addressing;
- switch/case;
- labels/goto;
- casts;
- function pointers;
- inline assembly nodes.
This is an AST-like internal representation.
It is useful to call it an internal syntax tree or node representation rather than a general-purpose IR.
It is source-language-oriented and tightly coupled to the CLVM code generator.
Semantic state in ChrisC
ChrisC keeps explicit tables for:
- symbols;
- functions;
- structures;
- typedefs;
- constants/enums;
- scopes;
- function pointers;
- global initializers;
- labels/gotos;
- source files;
- source maps.
Type-related state includes widths, pointer information, signedness, float state, structure IDs and array metadata.
Semantic checks and code-generation decisions are therefore interleaved with this compiler-specific representation rather than isolated behind a separate typed-IR interface.
ChrisC code generation
After preprocessing, lexing and parsing, chrisc_compile_ex calls the emitter.
The output is CLVM bytecode written directly into a caller-provided buffer.
ChrisResult returns metadata including:
- bytecode size;
- entry PC;
- variable count;
- primary diagnostic;
- up to eight structured diagnostics;
- source-file list;
- PC-to-source mapping;
- ABI major/minor;
- exported function names, PCs and argument counts.
This result is more than a success flag: it is the bridge between compilation, debugger mapping and runtime image creation.
No relocatable-object stage in ChrisC
ChrisC does not currently emit one relocatable object per translation unit and then run a CLVM linker.
Multi-file compilation is handled inside one compiler context through:
The resulting output is one bytecode program.
This differs fundamentally from the native ChrisO path.
The distinction matters for:
- incremental builds;
- symbol visibility;
- separate compilation;
- binary interfaces;
- linker diagnostics.
CLVM assembly path
.CVA source files use:
instead of ChrisC.
The CLVM assembler is a two-pass assembler.
Pass 1 discovers labels and byte offsets.
Pass 2 emits opcodes and resolves relative branches.
It supports both short and 32-bit branch forms for relevant opcodes.
The default entry is the address of label:
if present, otherwise zero.
Thus the VM pipeline accepts both high-level ChrisC and low-level CLVM assembly as source languages.
CLVM image creation
Raw CLVM bytecode is wrapped into a .CLV image.
Two image layouts are supported.
Version 1
The v1 header is 16 bytes and stores a 16-bit entry value.
It is used by lang_pipeline when code size and entry fit the legacy limit.
Version 2
The v2 header is 24 bytes and carries:
- 32-bit code size;
- 32-bit checksum;
- 32-bit entry;
- memory hint.
The common image magic is:
and the payload checksum is FNV-1a over bytecode.
The loader rejects:
- bad magic;
- unsupported versions;
- unknown flags;
- invalid code size;
- entry outside bytecode;
- checksum mismatch.
Integration cap versus format cap
CLVM itself defines:
but lang_pipeline.c currently allocates:
for the integrated compiler code buffer.
Therefore the operating-system compilation path has a lower practical code-size ceiling than the file format/parser maximum.
These two limits should not be conflated.
Runtime image policy
emit_game_clv sets:
for generated application images.
If generated code is larger than 200,000 bytes, the integration currently sets:
to accommodate Doom-sized guest heaps.
Otherwise the memory hint can remain zero.
The runtime then decides how much CLVM memory to attach to the application.
Debug/source maps
ChrisC produces PC-to-source mappings.
lang_pipeline writes accompanying map/debug data and loads it into runtime slots for debugger operations such as:
- source line lookup;
- breakpoints;
- stepping;
- call-stack naming;
- watch expressions.
Source mapping is therefore part of the practical compiler contract, not an optional documentation artifact.
Execution after CLVM compilation
A .CLV image is parsed before execution.
The normal runtime can execute through:
- the CLVM interpreter;
- the CLVM JIT path where selected.
The compiled artifact is still CLVM bytecode in both cases.
The JIT is a runtime backend, not a second ChrisC frontend.
That separation is important:
Guest-compiler path and bootstrap behavior
For .CC files, lang_compile_file first attempts:
This path loads:
and executes that guest compiler inside a CLVM process.
The source and destination path are supplied as an application argument.
After the guest compiler finishes, the output file is read and validated with:
If the guest compiler path fails, the in-kernel ChrisC path remains available as a fallback in lang_compile_file.
What lang_make_cc proves
lang_make_cc invokes the guest compiler on selected source files, including a compiler source path that produces:
This is real bootstrap/self-hosting infrastructure.
It demonstrates that a compiler artifact can execute inside CLVM and produce another CLVM artifact.
It does not, by itself, prove:
- bit-for-bit compiler fixed-point convergence;
- reproducible builds;
- trusting-trust resistance;
- full source-equivalence across bootstrap stages.
Those would require explicit stage comparison and provenance tests.
Pipeline B: KCC to native ELF64
The native pipeline starts with:
or:
from:
Its output is not final ELF.
Its output is an in-memory:
after assembly.
KCC preprocessing
KCC contains its own preprocessor.
Its state includes fixed tables for:
- object-like and function-like macros;
- macro parameters;
- typedefs;
- enums;
- structure definitions;
- symbols.
Current predefined macros include:
KCC also supports a project-oriented include path and selected built-in headers.
It should therefore be described as a self-contained freestanding C-profile compiler, not as a wrapper around a host C preprocessor.
KCC parsing and semantic model
KCC has explicit Type, StructDef, Sym and Val structures.
It tracks properties such as:
- scalar kind;
- pointer state;
- size/alignment;
- struct identity;
- array dimensions;
- volatility;
- function pointers;
- lvalue location;
- frame offsets;
- global symbol names.
Its parser and code generator are closely coupled.
There is no persistent general optimizer IR between parsing and textual assembly generation.
KCC backend
KCC emits x86-64 assembly text into:
The assembly buffer is limited to:
The preprocessed-source buffer is also:
After a successful compile unit, KCC calls:
Therefore kcc_compile_named already includes the assembler stage internally.
kcc_last_asm() exposes the generated assembly for tests and diagnostics.
ChrisAsm
ChrisAsm is a project assembler for the x86-64 subset needed by the native toolchain.
It emits:
- machine-code section bytes;
- symbols;
- relocations;
- BSS size;
into a ChrisoImage.
Current section model:
The first three use in-memory byte buffers.
BSS is represented by size without stored payload bytes.
Local versus external fixups
ChrisAsm resolves same-section local labels internally.
External or object-level references become ChrisO symbols and relocations.
For example, a call to an undefined symbol is represented with an x86-64 relocation such as:
rather than being silently patched to zero.
That distinction is the foundation for separate compilation.
ChrisO object format
ChrisO is the project’s relocatable object representation.
Version 2 includes:
- section sizes;
- symbol table;
- relocation table;
- BSS size.
A symbol record is 80 bytes.
A v2 relocation record is 20 bytes.
Current fixed maxima include:
The object model distinguishes:
bindings and function/object/notype symbol kinds.
ChrisO serialization
chriso_write serializes a ChrisoImage into the custom ChrisO file format.
chriso_read accepts current v2 and legacy v1.
The native host driver:
performs:
It does not itself run ChrisLd.
Linking is a separate stage.
KCC inside ChrisOS
The kernel also contains:
which can submit a KCC job for a source path.
The worker:
- reads source from the filesystem;
- compiles to
ChrisoImage; - serializes ChrisO;
- writes a
.CHRISOfile.
The job path currently uses 64-KiB source/output work buffers.
This is an orchestration limit on top of the compiler/assembler limits.
ChrisLd
ChrisLd consumes one or more ChrisoImage objects.
chrisld_link_objects supports up to:
in one link operation.
It:
- packs sections from all objects;
- detects duplicate global definitions;
- resolves undefined/global symbols;
- computes final addresses;
- applies relocations;
- creates ELF64 headers and program headers;
- selects an entry point;
- returns final ELF bytes.
Entry-point selection
ChrisLd prefers a defined symbol named:
If no such symbol is found, it searches for:
If neither is present, the default entry initially remains the supplied load address.
That behavior is part of the current linker implementation and should be treated explicitly by callers.
Relocation support
Current linker relocation handling includes:
plus NONE.
The linker rejects unsupported relocation types, invalid relocation sites, unresolved symbols and displacement/value overflows.
ELF output
ChrisLd emits:
Depending on sections, output has one or two loadable segments.
A text-only image can use one executable/readable segment.
When writable data/BSS exists, the linker emits a separate writable segment.
chrisld_validate checks important properties, including that a PT_LOAD segment is not both writable and executable.
Why ChrisO exists instead of direct ELF objects
The current architecture uses ChrisO as a smaller project-controlled object ABI.
That lets ChrisAsm and KCC implement:
- section ownership;
- symbols;
- unresolved references;
- relocations;
without implementing the complete ELF relocatable-object specification.
ChrisLd is the boundary where these custom objects become a standard ELF executable.
Two different notions of “linking”
It is important not to use one word ambiguously.
ChrisC / CLVM
Multi-file source is combined within one compiler invocation.
There is no current per-source CLVM relocatable object stage.
KCC / native
Each compilation can produce a ChrisO object.
ChrisLd performs actual object-level symbol resolution and relocation.
Only the second path currently provides classic separate compilation.
Diagnostics
ChrisC
ChrisResult contains:
- a legacy primary diagnostic;
- up to eight structured diagnostics;
- file;
- line/column;
- ranges;
- severity;
- message.
The OS integration converts compiler diagnostics into editor status and serial output.
KCC
KCC exposes one current:
with:
- file;
- line;
- column;
- severity;
- message.
ChrisAsm and ChrisLd
These later native stages usually return coarse success/failure codes rather than rich structured diagnostics.
Therefore diagnostic quality currently decreases after KCC.
A future toolchain should retain source/object/link context through every stage.
Failure propagation
A compiler pipeline is only correct if failures stop the pipeline.
Examples in the current implementation:
- ChrisC returns failure on preprocessing/lexing/parsing/emission errors;
- CLVM image writers reject invalid entry/code sizes;
clvm_parserejects malformed or corrupted images;- KCC returns an error diagnostic when preprocessing/parsing/codegen fails;
- KCC converts ChrisAsm rejection into a compiler diagnostic;
- ChrisAsm rejects unknown/unsupported assembly;
- ChrisO read/write rejects malformed or undersized objects;
- ChrisLd rejects unresolved symbols, duplicate globals, relocation overflow and malformed layout;
chrisld_validaterejects malformed or unsafe ELF layout conditions it checks.
Silent continuation is not the intended contract.
Optimization model
Neither current pipeline contains a reusable SSA optimizer framework.
ChrisC emits CLVM instructions from its source-oriented representation.
KCC emits textual assembly from parser/type/symbol state.
Local optimizations can and do exist inside these backends, but they are backend-coupled.
For example, native tests inspect generated assembly behavior around volatile versus non-volatile storage.
That is different from having a target-independent optimization IR with formal passes such as:
Those are not current architectural stages.
ABI boundaries
The two pipelines also target different ABIs.
ChrisC / CLVM ABI
The output obeys:
- CLVM opcode encoding;
- CLVM call/stack rules;
- CLVM memory model;
- CLVM SYS/builtin interface;
- image entry and flags.
Native ABI
KCC/ChrisAsm/ChrisLd must obey:
- x86-64 instruction encoding;
- project calling conventions;
- stack-frame rules;
- section/symbol conventions;
- relocation semantics;
- final ELF memory layout.
Correct parsing alone is therefore insufficient.
A compiler can parse a valid source program and still be wrong if its emitted ABI behavior is wrong.
Reentrancy and concurrency limits
Both major compiler implementations rely heavily on file-static mutable state.
ChrisC has a global compiler object and large global translation buffers.
KCC has global preprocessing, symbol, assembly and parser state.
ChrisAsm also uses file-static section/fixup buffers.
These APIs should not currently be treated as naturally reentrant or safe for concurrent independent compilation calls without higher-level serialization.
This is especially relevant because the kernel exposes KCC through a job system.
A job interface does not automatically make the underlying compiler state parallel-safe.
Memory ownership
ChrisC writes bytecode into caller-provided output storage.
KCC calls ChrisAsm, which allocates section payloads for the returned ChrisoImage.
ChrisO serialization copies those section bytes into a caller-provided output buffer.
ChrisLd also writes final ELF into caller-provided storage.
The pipeline therefore mixes static compiler state, allocated object sections and caller-owned artifact buffers.
Ownership must be handled explicitly by orchestration code.
Validation: ChrisC path
The current test tree contains broad ChrisC coverage.
Examples include tests for:
- arrays;
- functions;
- pointers;
- structures;
- strings;
- floating point;
- includes;
- language semantics;
- Doom-related compilation;
- application/game source.
test_chrisc_lang.c compiles source snippets to CLVM bytecode and executes them in the VM to verify runtime semantics.
This is stronger than checking only that bytecode was emitted.
ChrisC fuzz smoke
test_fuzz_chrisc.c feeds deterministic pseudo-random printable source text to the compiler.
It requires the compiler to return only its documented success/failure classes and then confirms a known-valid program still compiles.
This is useful crash-resistance smoke testing.
It is not a proof of parser correctness or a coverage-guided security fuzz campaign.
Validation: native path
test_kcc.c does more than compile toy snippets.
It compiles real project files such as parts of:
and checks:
- expected symbols;
- BSS/rodata output;
- relocations;
- structure layout behavior;
- volatile access behavior;
- multi-object linking with stubs.
test_chrisasm.c verifies machine encoding and relocation creation.
test_chriso.c verifies basic serialization/deserialization.
test_chrisld.c verifies:
- single-object ELF;
- multi-object symbol resolution;
- undefined-symbol rejection;
- duplicate-global rejection;
- read-only/executable versus writable segment layout;
- BSS address resolution.
What the tests do not yet prove
The current validation does not prove:
- full ISO C conformance for ChrisC or KCC;
- equivalence between ChrisC and KCC on common source;
- deterministic output across all host/platform combinations;
- self-hosting fixed-point convergence;
- thread-safe concurrent compilation;
- complete relocation/ELF coverage;
- optimization correctness under a formal IR;
- malicious-input hardening of every parser and object reader.
Those remain separate engineering problems.
Current limitations
At the documented revision:
- two largely independent compiler stacks;
- no shared frontend;
- no shared semantic/type system;
- no shared target-independent IR;
- no SSA pipeline;
- ChrisC multi-file compilation is monolithic rather than object/link based;
- CLVM integrated compiler buffer is 4 MiB despite a 16-MiB format ceiling;
- ChrisC and KCC rely on large fixed tables/buffers;
- ChrisC exposes at most eight structured diagnostics per compile result;
- KCC exposes one current diagnostic;
- ChrisAsm/ChrisLd errors are mostly coarse status returns;
- native KCC assembly/preprocessor buffers are 256 KiB;
- ChrisAsm section buffers are 64 KiB each;
- ChrisO has fixed symbol/relocation maxima;
- ChrisLd links at most 32 objects in one call;
- compiler internals are heavily global and non-reentrant;
- no unified build graph/incremental dependency database;
- no standard ELF relocatable-object frontend in the native path;
- bootstrap infrastructure exists but fixed-point/reproducibility proof is not yet part of the documented validation contract.
Roadmap boundary
A stronger compiler architecture could add:
- an explicit common typed IR where useful;
- separate frontend/semantic/backend interfaces;
- reusable optimization passes;
- object-level CLVM separate compilation if needed;
- richer diagnostic propagation through assembler and linker;
- structured linker error reports;
- reentrant compiler contexts;
- dynamic resource growth instead of large compile-time ceilings;
- dependency-aware incremental builds;
- deterministic-build tests;
- bootstrap stage comparison;
- differential execution between interpreter/JIT and native backends where semantics overlap;
- corpus-based and coverage-guided fuzzing;
- explicit language-profile specifications for ChrisC and KCC.
Those are roadmap items until present in source and validation.
Source map and revision note
The ChrisC frontend/backend is implemented primarily in compiler/chrisc/chrisc.c with public contracts in chrisc.h. compiler/lang_pipeline.c integrates compilation with filesystem paths, CLVM image creation, guest-compiler bootstrap, debugger maps and runtime execution. CLVM assembly/image handling is in compiler/clvm.
The native pipeline is implemented by compiler/kcc, compiler/chrisasm and compiler/chrisld. ChrisoImage is the custom relocatable-object boundary. tools/kcc_main.c provides a host KCC driver, and kernel/metal/kcc_job.c exposes in-system compilation to a kernel job.
All claims about current behavior in this chapter were reconciled against ChrisOS revision e05a17fd76333114a3fb5c2452f38ca747d4ac56.