
ChrisFS directories and path resolution
About this chapter ChrisFS structures and recovery
In this chapter
- ChrisFS directories and path resolution
- Scope
- Directory inode model
- Persistent dirent ABI
- Entries per block
- Maximum structural directory capacity
- Empty-entry representation
- Redundant type field
- Dirent flags
- Name comparison
- Path object
- Path length
- Component limits
- Maximum depth
- Root syntax
- Syntax explicitly rejected
- No dot entries
- Rooted traversal
- WALK permission
- Directory lookup
- Error masking during block scan
- Directory lookup complexity
- Directory size field
- Adding an entry
- Free-slot reuse
- Removing an entry
- Directory emptiness
- Creating a directory
- Creating a file entry
- Listing
- Target-directory permission gap in listing
- Rename semantics
- Rename is add-then-remove
- Directory-cycle bug in rename
- Unlink
- rmdir
- fsck directory traversal
- fsck scans only direct directory blocks
- Duplicate-name detection resets per block
- No dirent-type cross-check
- No orphan-inode reference accounting
- Validation evidence
- Complexity profile
- Current limitations
- Roadmap boundary
- Source map and revision note
Scope
ChrisFS directories are ordinary directory inodes whose data blocks contain fixed-size directory entries.
There is no separate B-tree, hash table, directory inode format or directory index. Name lookup is a linear scan over directory blocks and entries.
The current directory layer combines four responsibilities:
- persistent dirent encoding;
- path parsing;
- rooted traversal;
- namespace mutation.
The implementation is deliberately compact, but that simplicity makes several correctness properties depend on scan order, inode state and higher-level serialization.
This chapter documents ChrisOS revision e05a17fd76333114a3fb5c2452f38ca747d4ac56.
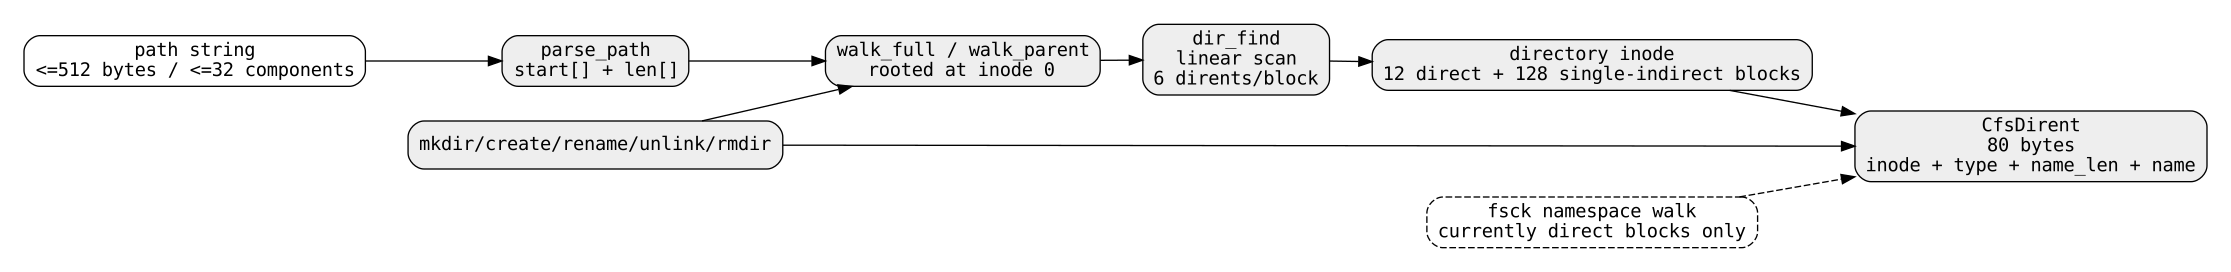
Directory inode model
A directory uses the same CfsInode structure as a file.
Its distinguishing field is:
Directory data lives in normal data-region blocks allocated through file_lba.
The current implementation limits directories to:
So directories use direct and single-indirect addressing only.
Double- and triple-indirect directory blocks are not part of the directory traversal contract.
Persistent dirent ABI
A CfsDirent occupies:
with this on-disk layout:
| Offset | Size | Field |
|---|---|---|
| 0 | 4 | inode |
| 4 | 1 | type |
| 5 | 1 | name_len |
| 6 | 2 | flags |
| 8 | 64 | name |
| 72 | 8 | reserved zero padding |
The encoder zeros all 80 bytes before storing fields.
The persistent name area is exactly:
Names are stored as length-delimited byte sequences, not NUL-terminated strings on disk.
Entries per block
With 512-byte sectors:
Six entries consume:
leaving:
in each directory data sector.
Those final 32 bytes are not part of any dirent.
Maximum structural directory capacity
At 140 directory blocks and six entries per block:
This is a structural ceiling.
The practical filesystem also has only 2047 non-root inode slots, so total object count across the entire filesystem is lower than the sum of independent per-directory maxima.
Empty-entry representation
Runtime directory code treats an entry as populated when:
A removed dirent is fully zeroed.
Because inode 0 is reserved for root and root is never represented as a child directory entry, using inode zero as the empty-entry marker is compatible with the current namespace model.
Redundant type field
Each dirent stores a one-byte type.
dir_add writes the child's inode type into that field.
However, normal lookup and listing do not trust it as authoritative:
dir_findreturns the inode number;- callers load the inode;
list_dir_inodeloads the child inode and reportsinode.type.
fsck also does not currently compare:
against:
So the dirent type is redundant metadata that can become stale without being detected.
Dirent flags
The 16-bit dirent flags field is encoded and decoded but has no active namespace semantics at the documented revision.
New entries are zero-initialized, so flags are normally zero.
There is no feature negotiation around nonzero dirent flags.
Name comparison
name_equal performs:
- exact length comparison;
- byte-for-byte comparison.
Therefore names are:
- case-sensitive;
- byte-sensitive;
- not Unicode-normalized;
- not locale-aware.
The path tests explicitly verify that:
are distinct names.
Path object
The parser fills a PathParts structure containing:
The parser does not allocate memory or copy path components.
Instead, offsets and lengths refer directly into the original caller string.
The original path must therefore remain valid for the duration of the operation.
Path length
The maximum accepted path text is:
A path of exactly 512 non-NUL bytes is accepted if its components otherwise satisfy the rules.
A 513-byte path is rejected with:
The NUL terminator is not counted in the 512-byte limit.
Component limits
The maximum component size is:
A component of 64 bytes is accepted.
A 65-byte component returns:
Maximum depth
The maximum number of path components is:
A 33-component path is rejected with:
The host path test verifies the 33-component failure case.
Root syntax
The parser accepts:
as root.
For ordinary paths it accepts either:
or:
Both are resolved from root.
ChrisFS has no current-working-directory state in the filesystem layer.
A path without a leading slash is still root-relative.
Syntax explicitly rejected
The parser rejects:
- repeated separators such as
A//B; - trailing slash such as
A/B/; - backslash;
.;..;- too many components;
- oversized components.
After stripping one leading slash, another immediate slash is treated as an empty component and rejected.
So:
is invalid.
No dot entries
Directories do not contain synthetic:
entries.
The parser rejects those components instead of resolving them.
There is also no stored parent pointer in the directory inode.
This simplifies the format but means ancestor relationships must be inferred by walking directory entries from root.
Rooted traversal
All lookup starts at:
walk_full resolves every component.
walk_parent resolves every component except the final leaf and returns:
- parent inode ID;
- final component index.
Creation, unlink, mkdir, rmdir and rename use the parent form because the leaf may not yet exist.
WALK permission
For intermediate path components, traversal requires:
on the child directory being entered.
For:
the traversal checks WALK on A and B.
It does not perform an explicit WALK check on root before the first lookup.
The final object does not need WALK unless another component follows it.
Directory lookup
dir_find:
- loads the directory inode;
- verifies it is a directory;
- scans block numbers 0 through 139;
- resolves each block with
file_lba(..., alloc=0); - reads each existing block;
- scans six dirents;
- compares name length and bytes;
- returns the first matching inode ID.
If the stored inode ID is outside the fixed inode table, lookup returns:
Error masking during block scan
A significant current behavior is that several directory scans use:
This occurs in helpers such as:
dir_find;dir_count;dir_addscanning;dir_remove;list_dir_inode.
That treats every failed block resolution as if the directory block were simply absent.
But file_lba(..., alloc=0) can fail for reasons other than “this logical directory block is unallocated,” including corruption or pointer-table I/O failure.
Therefore some underlying errors can be masked into:
CFS_ENOENT;- lower entry counts;
- omitted listing entries;
- later allocation attempts.
The directory layer needs a distinct “hole/not allocated” result if it wants to skip missing blocks safely without swallowing corruption and I/O errors.
Directory lookup complexity
There is no name index.
Worst-case lookup scans:
For a path of depth d, repeated lookup is approximately:
in the simple worst case.
The fixed directory limit keeps this bounded, but it remains linear.
Directory size field
The directory inode size is not the byte size of allocated directory blocks.
dir_add increases it by:
for every inserted entry.
dir_remove decreases it by 80 when possible.
It therefore behaves as:
rather than allocated storage size.
Lookup, listing and emptiness checks do not rely on this field as the sole source of truth.
Adding an entry
dir_add first scans all existing directory blocks for an empty dirent.
It remembers the first free slot.
If no free slot exists, it scans block numbers 0..139 again and asks file_lba(..., alloc=1) for the first missing block.
When a new block is allocated:
- the directory inode is persisted so the new pointer survives;
- slot 0 of that block becomes the insertion target.
The new dirent stores:
- inode ID;
- inode type;
- name length;
- name bytes.
The parent directory size is then increased by 80 and its inode is written.
Free-slot reuse
Deleted entries are zeroed but the containing block remains allocated.
A later dir_add reuses the first free slot encountered.
This avoids immediate block churn, but it also means directory block allocation only grows unless the directory inode itself is eventually released.
There is no compaction pass.
Removing an entry
dir_remove scans linearly for the matching name.
On match it:
- zeroes the complete 80-byte dirent;
- writes the containing sector;
- subtracts 80 from directory size when possible;
- writes the directory inode.
It does not:
- shift later entries;
- free an empty directory block;
- prune a now-empty indirect pointer block.
That design explains why a directory can retain many allocated blocks after its live entry count becomes small.
Directory emptiness
dir_count scans directory blocks and counts entries satisfying:
cfs_rmdir requires the result to be zero.
This is a scan-based emptiness check; it does not simply test:
which is safer when size metadata and entries disagree.
Creating a directory
cfs_mkdir:
- parses the path;
- resolves the parent;
- checks WRITE permission on the parent;
- verifies the destination name does not already exist;
- starts a journal transaction;
- allocates an inode;
- changes its type from FILE to DIR;
- inserts it into the parent;
- increments filesystem generation;
- commits the journal.
If parent insertion fails after allocation, it attempts to zero the new inode.
The new directory initially has no data block. Its first data block is allocated only when the first child is added.
Creating a file entry
cfs_create is similar, but it currently does not wrap its inode-allocation + dirent-insertion sequence in jnl_begin/jnl_commit.
That means namespace creation has weaker crash coverage than mkdir.
It does attempt local rollback by zeroing the allocated inode if dir_add fails.
Listing
cfs_list lists root by calling:
cfs_list_at resolves the target path and calls list_dir_inode.
For every active dirent, listing:
- copies the name to a temporary NUL-terminated buffer;
- loads the child inode;
- calls the user callback with:
- name;
- child inode size;
- child inode type.
The callback return value is propagated immediately when nonzero.
This supports early-stop iteration.
Target-directory permission gap in listing
Path traversal checks WALK only on intermediate directories.
After cfs_list_at resolves the target directory, list_dir_inode does not call:
on that target directory.
Therefore listing a directory does not currently require an explicit READ or WALK permission on the directory being listed, provided the path to it can be resolved.
This is a permission-policy gap relative to a stricter directory access model.
Rename semantics
cfs_rename supports both same-directory rename and cross-directory moves within one mounted ChrisFS instance.
It:
- resolves source and destination parents;
- checks WRITE on source parent;
- checks WRITE on destination parent if different;
- resolves source;
- rejects an existing destination;
- loads the source inode;
- inserts a destination dirent pointing to the same inode;
- removes the source dirent;
- increments filesystem generation.
No file data or inode block tree is copied.
Rename is add-then-remove
The ordering is:
There is no surrounding journal transaction and no rollback if the remove step fails.
A failure after destination insertion can therefore leave both names pointing to the same inode.
ChrisFS does not otherwise define hard-link semantics, so this is a partial-rename failure state.
Directory-cycle bug in rename
There is currently no ancestor check when moving directories.
Consider:
A rename such as:
can resolve destination parent A/B, insert a dirent in B that points back to inode A, then remove A from root.
The result is a cycle:
Because directories have no stored parent pointer, preventing this requires an explicit descendant/ancestor test before the move.
That check is absent in the current rename implementation.
Unlink
cfs_unlink only accepts regular files.
It requires:
- WRITE on the parent directory;
- WRITE on the target file.
It starts a journal transaction, removes the dirent, releases the inode and its blocks, increments filesystem generation, then commits.
Calling unlink on a directory returns:
rmdir
cfs_rmdir requires:
- target is not root;
- target is a directory;
- WRITE on parent;
- WRITE on target directory;
dir_count == 0.
It removes the parent dirent and releases the directory inode.
Unlike unlink and mkdir, the current rmdir path is not wrapped in journal begin/commit.
The inode-release limitation for directories that once grew into the single-indirect range is documented in the inode chapter: indirect directory data blocks can remain leaked after rmdir.
fsck directory traversal
fsck has a separate directory graph walk.
It validates:
- dirent inode ID range;
- dirent name length;
- child inode checksum;
- directory recursion cycles;
- duplicate names in part of the scanned namespace.
However, the current implementation has important coverage gaps.
fsck scans only direct directory blocks
check_dirents loops:
which is only:
Runtime directories can use 140 blocks.
Therefore entries stored in the single-indirect portion are not visited by the fsck namespace walk.
The pointer/data blocks themselves can still be seen by the generic inode block-ownership traversal, but their dirents are not checked for:
- invalid inode references;
- name errors;
- directory recursion;
- cycles.
Duplicate-name detection resets per block
Inside each direct directory block, fsck resets its local name count before scanning six entries.
So duplicate names within one block can be detected.
But the remembered-name set is not retained across blocks.
Two equal names stored in different directory blocks can therefore pass this duplicate-name check.
At runtime, dir_find returns whichever matching entry appears first in scan order.
No dirent-type cross-check
fsck loads the referenced inode but does not compare its type with the redundant type byte stored in the dirent.
A dirent can therefore say FILE while pointing at a DIR inode, or the reverse, without that mismatch being reported.
Runtime listing reports the actual inode type, which hides the stale dirent type from callers.
No orphan-inode reference accounting
fsck scans every inode for block ownership and separately walks directories from root.
It does not maintain a complete inode-reference map that requires every allocated non-root inode to be reachable from the root namespace.
An allocated inode with valid blocks but no dirent can therefore escape direct “orphan inode” reporting.
Likewise, multiple dirents can reference the same file inode without a dedicated link-count invariant because ChrisFS has no link-count field.
Validation evidence
tools/test_cfs_paths.c covers the core intended namespace behavior:
- root directories;
- nested file paths;
- one optional leading slash;
- case-sensitive names;
- root and nested listing;
- same-directory rename;
- cross-directory rename;
- unlink;
- non-empty rmdir rejection;
- successful empty rmdir;
- rejection of
.; - rejection of
..; - 33-component depth rejection;
- remount persistence;
- final fsck.
The test does not currently cover:
- 64/65-byte component boundary;
- 512/513-byte path boundary;
- repeated slash;
- trailing slash;
- directory capacity near 840 entries;
- directory blocks beyond the 12 direct blocks;
- duplicate names across blocks after corruption;
- rename of a directory into its own descendant;
- target-directory listing permissions;
- injected pointer-table I/O failure during directory scans.
Complexity profile
Lookup
with a fixed structural maximum of 840 entries.
Add
Worst case performs one full scan for reusable slots and another scan for a missing block:
with a larger constant than lookup.
Remove
Path resolution
For depth d:
There is no cached dentry/path layer in ChrisFS itself.
Current limitations
At the documented revision:
- names are raw case-sensitive bytes;
- no Unicode normalization;
- no
.or..; - no current working directory;
- no parent pointer;
- 64-byte component limit;
- 512-byte path limit;
- 32-component depth limit;
- linear name lookup;
- 840-entry structural directory ceiling;
- dirent type and flags are weak/redundant metadata;
- no per-directory block checksum;
- no indexing;
- no directory block compaction or shrink;
- some
file_lbafailures are masked as missing blocks during scans; - listing does not require permission on the target directory itself;
- create/rmdir/rename are not uniformly journaled;
- rename can leave duplicate namespace links on partial failure;
- rename can create directory cycles by moving a directory into its descendant;
- fsck namespace validation covers only 12 direct directory blocks;
- fsck duplicate-name detection is block-local;
- fsck does not compare dirent type with inode type;
- fsck does not enforce complete inode reachability from root;
- rmdir can leak indirect directory data blocks as described in the inode chapter.
Roadmap boundary
A stronger directory layer should consider:
- a distinct “unallocated logical block” result instead of masking arbitrary lookup errors;
- indexed or hashed directory lookup;
- explicit target-directory permission checks;
- transactional create/rmdir/rename;
- rename rollback;
- descendant-cycle prevention;
- directory block compaction/pruning;
- complete fsck traversal of single-indirect directory blocks;
- duplicate-name validation across the entire directory;
- dirent/inode type consistency checks;
- allocated-inode reachability checks;
- explicit link-count semantics if multiple names are ever supported;
- targeted boundary and corruption tests for path parsing and large directories.
These remain roadmap items until implemented and covered by reproducible tests.
Source map and revision note
kernel/fs/cfs_format.h defines the persistent 80-byte dirent ABI. kernel/fs/cfs.h defines path limits and PathParts. kernel/fs/cfs.c implements parsing, traversal, lookup, listing and namespace mutation. kernel/fs/cfs_fsck.c implements the current directory graph validation. tools/test_cfs_paths.c provides the primary host-side namespace evidence.
All current-behavior claims in this chapter were reconciled against ChrisOS revision e05a17fd76333114a3fb5c2452f38ca747d4ac56.