
Arquitetura do JIT CLVM e execução nativa
Sobre este capítulo Execução ChrisC e CLVM
Neste capítulo
- Arquitetura do JIT CLVM e execução nativa
- Escopo
- Caráter arquitetural
- Entry point público
- Integração no launch
- Compilation serializada
- Structural scan inicial
- Fallback para imagens grandes
- Gap atual de validação de instrução truncada
- Sizing do native code buffer
- ABI x86-64 da execução
- Design do emitter
- Cobertura de translation
- Helper path
- Instrumentação de helper calls
- Cinco opcodes CLVM não implementados pelo helper atual
- Tabela bytecode-PC para native offset
- Indirect dispatch
- Patching de direct branches
- Modelo da operand stack
- Modelo da call stack
- Largura da stack no runtime helper
- Integer arithmetic nativa
- Gaps de correção em division
- Floating-point path
- Memory operations
- Mismatch de fault_pc em BAD_ADDRESS
- Colapso de outros faults no stub genérico
- Diferença em PRINT
- Safepoints
- Diferença de scheduling em safepoint
- Modelo de budget
- Counter executed ausente
- VM state transitions
- Helper ABI e stack alignment
- Syscall context por CPU
- GC polling durante compilation
- Incompatibilidade atual com hot reload
- Lifetime do code cache
- Failure behavior
- Complexidade
- Cache behavior
- Evidência de benchmark
- Evidência de native path
- Casos diferenciais faltantes
- Security boundary
- Limitações atuais
- Fronteira de roadmap
- Mapa de source e revisão
Escopo
O JIT do CLVM traduz bytecode CLV para machine code x86-64 no lançamento da aplicação.
Não é tracing JIT, tiered optimizer nem compiler profile-guided. A implementação atual traduz antecipadamente uma imagem CLV elegível inteira antes da execução e mantém um native code buffer associado ao application slot.
O fluxo é:
imagem CLV
  |
  v
structural scan
  |
  +---- não elegível ----> wrapper do interpreter
  |
  v
emissão de instruções nativas
  |
  +---- opcode não nativo ----> runtime helper
  |
  v
tabela bytecode-PC -> native offset
  |
  v
patch de branches
  |
  v
executable mapping
  |
  v
JitFn(vm, budget, now)
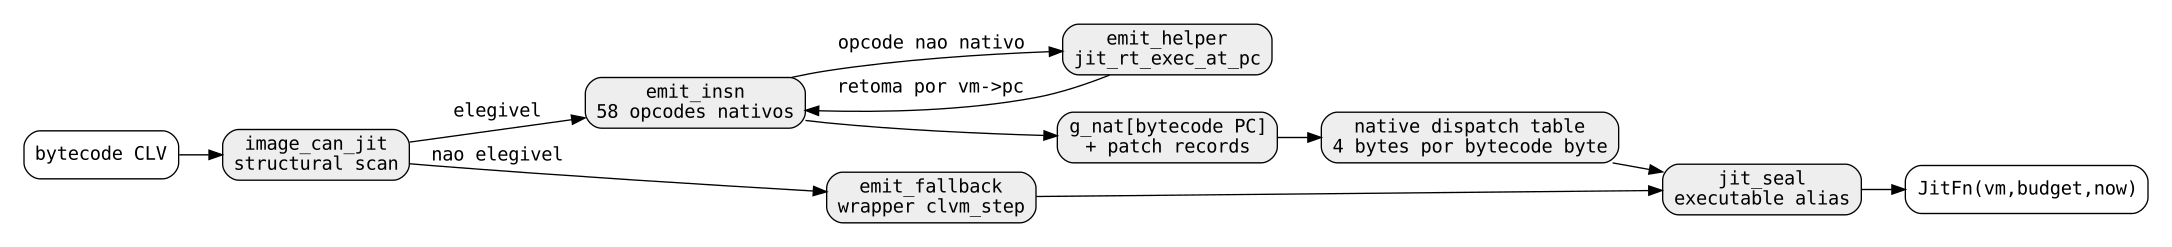
Allocation de executable memory, aliases W/X, TLB publication e reclamation estão documentados separadamente em Executable memory, JIT aliases and W^X. Este capítulo trata de translation, dispatch, preservação de VM state, helper fallback, scheduling semantics e correção.
Caráter arquitetural
O JIT é um tradutor direto de bytecode para x86-64 com helper fallback.
Não há SSA graph intermediário, optimization pipeline, register allocator, detector de hot loops ou speculative specialization entre CLVM e machine code.
Em vez disso:
- opcodes CLVM comuns recebem fixed x86-64 sequences;
- opcodes menos comuns chamam C runtime helper;
- direct bytecode branches tornam-se native branches com patch posterior;
- indirect control flow retorna por native dispatch table indexada pelo bytecode PC;
- VM stacks e memory continuam no formato original de ClvmVm.
O design reduz a distância semântica em comparação com JIT otimizador complexo, mas direct emission exige que cada native opcode reproduza explicitamente o comportamento do interpreter.
Entry point público
O generated function type é:
ClvmStepResult (*JitFn)(
    ClvmVm *vm,
    uint32_t budget,
    uint32_t now
);
Scheduler normal chama:
slots[i].jit_fn(&slots[i].vm, budget, now)
O generated code atual usa os dois primeiros argumentos.
O argumento now existe no JitFn ABI, mas não é consumido pela emitted entry sequence na revisão documentada.
Time-related syscalls ainda podem obter tempo pelos host implementations, mas now não é um native-code local.
Integração no launch
lang_run_internal inicializa ClvmVm e guest backing primeiro.
Quando debug está desligado e global no-JIT mode não está ativo, tenta:
jit_compile_image(&image, &slot.jit, &slot.jit_fn)
Em success:
slot.use_jit = 1
Em compilation failure:
slot.use_jit = 0
slot.jit_fn = NULL
e execução usa clvm_step.
Debug mode mantém deliberadamente interpreter porque source stepping, breakpoints e single-instruction execution são implementados em torno das semantics do interpreter.
Compilation serializada
jit_compile.c contém process-global scratch:
g_nat[JIT_MAX_PCS]
g_psite[JIT_MAX_PATCH]
g_ptgt[JIT_MAX_PATCH]
g_npatch
g_fault_ba
g_call_ovf
Por isso jit_compile_image envolve compiler real com:
spin_lock(&g_jit_compile_lock)
jit_compile_image_locked(...)
spin_unlock(&g_jit_compile_lock)
Somente uma native image é compilada de cada vez.
Runtime execution de código já gerado não é serializada por esse lock.
Custo do scratch
Limites:
JIT_MAX_PCS   = 1.048.576
JIT_MAX_PATCH = 131.072
g_nat guarda um uint32_t para cada possível byte do bytecode, consumindo aproximadamente 4 MiB.
Os dois patch arrays juntos consomem aproximadamente mais 1 MiB.
É compiler scratch estático, separado da generated-code allocation de cada aplicação.
O design troca memória por lookup O(1) simples de bytecode PC durante compilation.
Structural scan inicial
image_can_jit percorre code region a partir de PC zero.
Para cada opcode chama insn_len, que atribui nominal encoded length.
| Família | Tamanho nominal |
|---|---|
| sem immediate | 1 |
| LDARG/STLOC/LDLOC | 2 |
| JMP/JZ/JNZ/CALL | 3 |
| PUSH / FPUSH | 5 |
| NEWOBJ/LDFLD/STFLD/CALLT/LDSTR | 5 |
| JMP32/JZ32/JNZ32/CALL32 | 5 |
| PUSH64 | 9 |
Scan também rejeita native compilation quando code_size excede JIT_MAX_PCS.
Se image_can_jit retorna false, JIT gera pequeno executable wrapper que chama clvm_step em vez de traduzir a image.
Fallback para imagens grandes
CLV permite code images maiores que JIT_MAX_PCS.
JIT suporta essas imagens apenas por interpreter-wrapper path.
emit_fallback gera:
native prologue
call clvm_step
native epilogue
e entrega esse wrapper como JitFn.
Assim jit_compile_image pode retornar success e application slot pode ficar use_jit mesmo quando execução real passa por clvm_step.
É operacionalmente válido, mas torna use_jit flag imprecisa: significa “JitFn instalado”, não necessariamente “bytecode traduzido nativamente.”
Gap atual de validação de instrução truncada
insn_len verifica se o opcode byte está dentro de code_size, mas não prova que todos os immediate bytes exigidos pelo opcode continuam dentro de code_size.
image_can_jit avança pelo nominal length e pode aceitar uma instrução final truncada.
Exemplo: imagem de um byte contendo apenas CL_OP_PUSH recebe nominal length cinco. Scan vai de 0 para 5 e termina com success, embora o immediate de quatro bytes não exista no logical image.
Native emission depois usa rd_i32/rd_i16 sem novo logical-end check.
CLVs produzidos normalmente pelo compiler são bem formados, mas malformed untrusted image pode fazer compiler ler além do logical bytecode extent durante translation.
Structural scan deve exigir:
pc + instruction_length <= code_size
antes de aceitar cada instrução.
Um bytecode verifier comum a loader, interpreter e JIT seria solução mais forte.
Sizing do native code buffer
Antes da translation, jit_compile_image_locked estima:
need = code_size * 64 + 262144
pages = ceil(need / 4096)
Page count é limitado a:
mínimo 64 pages
máximo JIT_PAGES = 6144 pages
Logo allocation normal mínima é 256 KiB e máxima 24 MiB.
É sizing heuristic, não prova.
Cada low-level emit continua verificando capacidade de JitBuf. Se generated code excede buffer ou ocorre outro emission error, native compilation falha e caller pode usar interpreter.
O capítulo jit-memory documenta physical/virtual allocation.
ABI x86-64 da execução
Generated function usa calling convention x86-64 esperada pelo kernel.
Primeiro argumento, ClvmVm*, chega no primeiro integer argument register.
Prologue copia pointer para RBX:
REG_VM = 3
RBX vira fixed base register para acesso aos fields de ClvmVm.
Segundo argumento, budget, é salvo em stack local RBP-16.
Prologue reserva três locals de oito bytes e preserva RBX.
Native sequences acessam VM fields por offsetof compilado:
JIT_OFF_PC
JIT_OFF_STATE
JIT_OFF_STACK
JIT_OFF_SP
JIT_OFF_MEM
JIT_OFF_MSZ
JIT_OFF_CALLS
JIT_OFF_CSP
JIT_OFF_FAULT
JIT_OFF_FPC
Generated code fica fortemente acoplado ao exact C layout de ClvmVm usado naquele kernel build.
Não existe stable binary ABI para usar JIT blob em kernel com layout diferente.
Design do emitter
jit_emit.c é pequeno x86-64 encoder específico.
Emite apenas instruction forms necessários ao translator:
- register-immediate moves;
- register-register moves;
- arithmetic;
- comparisons/tests;
- conditional/unconditional relative jumps;
- indirect native calls;
- prologue/epilogue;
- fixed-displacement ClvmVm loads/stores.
JIT não depende de external assembler.
Bytes são escritos diretamente em JitBuf por jit_emit.
Isso reduz dependencies, mas encoding correctness pertence ao projeto.
Cobertura de translation
CLVM define atualmente 72 opcodes.
native_op marca 58 para direct x86-64 emission.
Os outros 14 usam helper path.
Classes emitidas diretamente
Native emission inclui:
- PUSH/PUSH64;
- integer arithmetic/bitwise;
- signed/unsigned comparisons;
- shifts;
- NEG/NOT;
- DUP/DROP/SWAP;
- loads/stores de 8/32/64 bits;
- FPUSH e core float arithmetic;
- integer/float conversion;
- direct/indirect branch, call e return;
- HALT;
- SAFEPOINT.
Opcodes roteados para helper
Os 14 non-native são:
PRINT
SYS
FNEG
FEQ
FLT
FLE
LDARG
STLOC
LDLOC
NEWOBJ
LDFLD
STFLD
CALLT
LDSTR
Helper-routed não significa automaticamente “suportado pelo JIT”; runtime helper também precisa implementar o opcode.
Helper path
emit_helper grava current bytecode PC em vm->pc, alinha native stack, preserva RBX defensivamente e chama:
jit_rt_exec_at_pc(vm)
jit_rt_exec_at_pc:
- incrementa global helper-call counter;
- valida vm->pc;
- lê um bytecode opcode;
- avança vm->pc;
- executa opcode em jit_rt_exec_op.
Generated code então verifica VM state.
Se helper faultou, entrou em wait ou halt, JIT retorna ClvmStepResult correspondente.
Caso contrário reentra no native dispatch pelo vm->pc atualizado.
Instrumentação de helper calls
jit_rt_reset_stats e jit_rt_helper_calls expõem count global de helpers.
test_jit_native usa isso para exigir que integer loop simples e floating-point program básico terminem com zero helper calls.
Counter é diagnostic global state, não per-VM accounting.
Concurrent JIT execution mistura estatísticas de VMs diferentes.
Cinco opcodes CLVM não implementados pelo helper atual
NEWOBJ, LDFLD, STFLD, CALLT e LDSTR são classificados como non-native e enviados a jit_rt_exec_at_pc, mas jit_rt_exec_op não possui cases correspondentes na revisão analisada.
Caem no default do helper e produzem CLVM_FAULT_OPCODE.
Interpreter implementa os cinco.
Logo CLV usando esse subset IL/object-oriented pode passar image_can_jit, receber native JitFn e faultar quando atingir uma dessas operações.
É coverage gap concreto entre interpreter/JIT.
O JIT deve:
- implementar os cinco no helper;
- emiti-los nativamente;
- ou rejeitar essas images em image_can_jit para usar interpreter wrapper inteiro.
Tabela bytecode-PC para native offset
Compiler registra:
g_nat[bytecode_pc] = native_offset
somente nos instruction starts.
Depois da emissão das native instructions acrescenta table com um uint32_t para cada byte da bytecode image.
Operand bytes e posições que não iniciam instrução permanecem zero.
A table consome:
4 * code_size bytes
dentro do generated JIT buffer.
Para CLV elegível de um MiB, somente dispatch table ocupa aproximadamente quatro MiB.
Indirect dispatch
Generated dispatch stub:
- lê vm->pc;
- rejeita pc >= code_size;
- indexa native-offset table por bytecode PC;
- rejeita zero entry;
- soma native blob base;
- salta ao native address.
Isso tem duas funções.
CALLI/RET podem transferir dinamicamente usando bytecode PCs.
E target no meio de immediate field é rejeitado porque table entry é zero.
A table é translation map e coarse instruction-boundary validity map.
Patching de direct branches
JMP/Jcc/CALL diretos não conhecem displacement final quando first emitted.
Compiler registra:
g_psite[n] = native_rel32_site
g_ptgt[n]  = target_bytecode_pc
Depois que todo instruction start tem native offset, patch phase verifica:
target < code_size
g_nat[target] != 0
e escreve displacement x86 final com jit_patch_rel32.
Fixed capacity é 131.072 patches.
Image que exceda isso falha native compilation.
Não existe growable patch vector.
Modelo da operand stack
JIT não mantém CLVM operand stack como native register stack persistente.
Cada native operation acessa:
vm->stack
vm->sp
pela memória relativa a RBX.
emit_pop_rax/emit_pop_rdx carregam e decrementam VM stack pointer; emit_push_rax verifica CLVM_STACK_MAX e grava de volta.
É menos agressivo que register-stack caching, mas oferece:
- coherent VM state nos helper transitions;
- mesmo stack structure para debugger/fault reporting;
- indirect dispatch sem reconstruir hidden native state;
- uma representação ClvmVm compartilhada por interpreter/JIT.
Custo é mais memory traffic por stack operation.
Modelo da call stack
CALL/CALL32 nativos mantêm CLVM call stack em:
vm->calls[]
vm->csp
em vez de mapear source calls para pares x86 CALL/RET.
CLVM call salva next bytecode PC em vm->calls e salta ao translated target.
RET remove bytecode return PC e reentra no dispatch table.
CALLI retira absolute bytecode target, valida contra code_size, salva bytecode return address e faz dispatch por vm->pc.
Isso preserva representação da call stack CLVM entre engines.
Largura da stack no runtime helper
Core ClvmVm stack é 64-bit.
Porém jit_rt_push/jit_rt_pop usam interfaces int32_t.
Helper-routed LDARG/LDLOC/STLOC portanto truncam valores para 32 bits, embora il_arg/il_loc sejam arrays int64_t.
Nos paths ChrisC atuais, que usam majoritariamente ordinary CLVM stack, isso pode aparecer pouco, mas IL-style VM subset não possui full 64-bit semantic parity no helper runtime.
API de helper consistentemente int64_t eliminaria a diferença.
Integer arithmetic nativa
ADD, SUB, MUL, bitwise operations, shifts e comparisons usam x86 64-bit diretamente.
Isso acompanha o operand-stack model de 64 bits do main interpreter melhor que antigas helper functions de 32 bits.
Unsigned divide/mod usa hardware DIV.
Signed divide/mod usa IDIV.
Direct translation é rápida, mas fault handling não é equivalente ao interpreter.
Gaps de correção em division
Interpreter define VM faults explícitos:
divisão por zero       -> CLVM_FAULT_DIV_ZERO
INT64_MIN / -1         -> CLVM_FAULT_DIV_OVERFLOW
Native signed DIV/MOD funciona diferente.
Divisor zero vai para path local que zera result register e empilha zero.
Não gera CLVM_FAULT_DIV_ZERO.
Também não faz precheck de INT64_MIN / -1 antes de x86 IDIV.
Em x86-64 essa condição pode gerar processor divide exception em vez de contained CLVM fault.
Unsigned UDIV/UMOD verifica zero, mas desvia para generic fault stub, cujo tipo atual é CLVM_FAULT_STACK_UNDERFLOW, não CLVM_FAULT_DIV_ZERO.
São mismatches concretos de fault containment.
Native divide deve usar dedicated stubs DIV_ZERO/DIV_OVERFLOW antes do hardware division.
Floating-point path
FADD, FSUB, FMUL e FDIV usam scalar SSE depois de mover low 32-bit float representation para XMM.
ITOF/FTOI também são diretos.
FNEG e float comparisons usam helper.
Mismatch de FDIV por zero
Interpreter e jit_rt_fbinop detectam floating divisor 0.0 e geram CLVM_FAULT_DIV_ZERO.
Direct native FDIV não faz esse precheck.
Com SSE exception state normalmente mascarado, hardware division pode produzir IEEE infinity em vez do VM fault esperado.
Logo FDIV native não é semanticamente idêntico ao interpreter.
Upper bits de float na stack
Interpreter float result costuma passar por int32_t antes de entrar em 64-bit VM slot, produzindo sign extension quando bit 31 está ligado.
Native FADD/FSUB/FMUL/FDIV move result para EAX, o que zera upper 32 bits de RAX antes de emit_push_rax armazenar 64 bits.
Para float operations posteriores apenas low 32 importam.
Raw CLVM que observe slot inteiro por integer op pode distinguir engines.
Differential tests devem incluir mixed float/integer bytecode, não somente source type-correct.
Memory operations
LOAD/STORE, LOADB/STOREB e LOAD64/STORE64 são nativos.
JIT obtém vm->memory e vm->mem_size de ClvmVm.
emit_bounds faz range check antes do dereference nativo.
Implementação assume atuais guest offsets efetivamente 32-bit e limpa high pointer bits antes do check.
Normal process-backed guest memory é muito menor que quatro GiB.
Guest backing é tratado no capítulo clvm-memory.
Mismatch de fault_pc em BAD_ADDRESS
Bounds-failure stub g_fault_ba configura:
fault = CLVM_FAULT_BAD_ADDRESS
mas grava fault_pc a partir de EAX.
No bounds check, EAX/RAX contém guest address testado, não bytecode opcode PC.
Interpreter registra opcode PC em fault_pc.
Assim JIT BAD_ADDRESS diagnostics reportam valor semelhante a address em fault_pc em vez da posição da instrução.
Fix deve carregar known bytecode PC no fault path ou separar register de address e opcode.
Colapso de outros faults no stub genérico
Vários native error paths usam o único fault stub criado no compile.
Esse stub é CLVM_FAULT_STACK_UNDERFLOW.
É correto para operand-stack underflow, mas não para todos os callers.
Exemplos:
- invalid CALLI target;
- RET com call stack vazia;
- invalid dispatch-table PC/entry;
- UDIV/UMOD por zero.
Interpreter possui BAD_JUMP, CALL_UNDERFLOW, PC e DIV_ZERO específicos.
JIT pode portanto conter o erro, mas reportar fault class incorreta.
Dedicated fault stubs restaurariam diagnostic parity.
Diferença em PRINT
Interpreter PRINT remove top value e registra no VM print ring por note_print.
JIT helper atual apenas faz pop.
Não atualiza print_ring/print_n.
Logo diagnostic history de PRINT difere entre engines.
É observable state e merece differential test.
Safepoints
CL_OP_SAFEPOINT tem direct native emission.
Sequence:
- vm->safepoint = 1;
- carrega vm->on_safepoint;
- chama callback quando non-null;
- restaura registers;
- vm->safepoint = 0.
Helper-call frame preserva stack alignment porque callback pode executar SSE code.
Isso suporta GC polling callback instalado pelo lang_pipeline.
Diferença de scheduling em safepoint
Interpreter faz proc_slice_due adicional depois de CL_OP_SAFEPOINT e pode yield imediatamente.
Native SAFEPOINT chama on_safepoint, mas não faz scheduler check equivalente.
Além disso, interpreter marca vm->safepoint em algumas call/object operations, enquanto direct native CALL/CALL32/CALLI não reproduz todos esses state updates.
Explicit SAFEPOINT ainda chama callback, porém safepoint state/scheduling não é totalmente equivalente.
Modelo de budget
Interpreter consome budget efetivamente uma vez por decoded opcode.
JIT não.
Generated function salva budget em native stack local e o decrementa apenas quando há backward unconditional JMP/JMP32.
Quando chega a zero, grava loop target em vm->pc e retorna CLVM_STEP_SLICE.
É backedge budget, não instruction budget.
Consequências
Typical ChrisC while loops normalmente têm unconditional backward edge e passam pelo check.
Entretanto:
- long straight-line native region pode ultrapassar nominal budget sem slice;
- loop codificado apenas com backward conditional JZ/JNZ não consome counter;
- helper-heavy paths não possuem general per-op budget decrement;
- “budget = N” tem significado materialmente diferente de clvm_step.
JIT robusto deve definir explicit budget unit e aplicá-lo ao menos em todo loop backedge, incluindo conditional, ou manter estimated/instruction-cost counter.
Counter executed ausente
Interpreter incrementa:
vm->executed
para todo fetched opcode e usa counter em periodic process-slice checks.
Native JIT não atualiza vm->executed para direct emitted instructions.
Portanto field não é engine-independent instruction count.
Diagnostics/policies que usam vm->executed precisam considerar execution mode.
VM state transitions
Interpreter entra explicitamente em CLVM_RUNNING e volta a CLVM_READY após normal slice.
Generated code preserva majoritariamente incoming state e escreve state para outcomes como HALTED/FAULTED.
Entry block reconhece WAITING e HALTED, mas não oferece o mesmo early FAULTED contract de clvm_step.
lang_tick normal destrói VM imediatamente após JIT fault, então reentry de faulted app não é esperado ali.
Mesmo assim JitFn público não é clone exato da state machine de clvm_step.
Helper ABI e stack alignment
emit_helper preserva RBX mesmo sendo callee-saved no ABI usual.
O comentário no source registra que freestanding helpers/syscalls historicamente o clobberaram.
Helper também subtrai oito bytes antes da call para garantir 16-byte stack alignment.
Isso importa em helpers que executam SSE, incluindo graphics.
Stack misalignment pode transformar VM helper call em CPU exception.
Syscall context por CPU
Antes de chamar JIT em lang_tick:
jit_set_sys_context(&vm, &gfx)
jit.c guarda par em:
g_jit_ctx[SMP_CPU_CAP]
indexado por smp_current_cpu.
Isso evita design anterior de single global context no qual VM de uma CPU poderia substituir context usado em outra.
O current generic helper path normalmente alcança vm->sys diretamente; jit_sys_trampoline continua disponível como bridge baseado nesse contexto.
GC polling durante compilation
Enquanto emite image grande, jit_compile_image_locked chama gc_poll periodicamente quando bytecode progress cruza condição de 64 KiB.
É compile-time cooperation, não runtime bytecode safepoint.
Evita que grande compilation permaneça totalmente invisível ao GC/service loop durante todo período do global compile lock.
Incompatibilidade atual com hot reload
lang_hot_reload reparses CLV, sobrescreve slot file buffer e reinicializa ClvmVm com nova image.
Na revisão analisada não:
- libera antigo JitBuf;
- executa novamente jit_compile_image;
- substitui slot.jit_fn;
- desativa slot.use_jit.
Portanto slot em JIT pode manter native code gerado para bytecode anterior depois de hot reload atualizar vm->code.
Isso cria stale-code hazard.
Direct native instructions ainda incorporam old constants, old branch layout e old dispatch table; helper calls podem consultar o novo vm->code.
Hot reload deve compilar/publicar novo JIT buffer atomicamente ou forçar slot reloaded para interpreter até recompilation.
Lifetime do code cache
Em shutdown normal, lang_kill chama jit_free quando slot possui JIT physical memory.
Unmapping/TLB/reclamation estão no capítulo jit-memory.
Não existe persistent native cache compartilhado entre apps.
Novo launch recompila image mesmo que CLV idêntico já tenha sido traduzido.
Isso favorece ownership simples.
Failure behavior
Native compilation pode falhar por:
- physical/JIT virtual allocation failure;
- buffer exhaustion;
- mais de JIT_MAX_PATCH patches;
- invalid direct target detectado no patch;
- emission failure;
- structural size não suportado.
Fallback depende do ponto.
Se image_can_jit rejeita, jit_compile_image pode ainda ter success instalando interpreter wrapper.
Se native emission falha mais tarde, jit_compile_image libera JitBuf e retorna -1; lang_pipeline desativa JIT e chama clvm_step.
Complexidade
Defina:
B = bytecode size em bytes
I = número de decoded instructions
P = direct branch/call patches
Compilation faz:
- structural scan: O(I), limitado por O(B);
- native emission: O(I) mais emitted-byte writes;
- dispatch-table emission: O(B);
- patching: O(P).
Memory inclui:
- cerca de 5 MiB de fixed global scratch;
- native code;
- dispatch table de 4B bytes;
- executable-memory metadata.
Não existem graph optimization passes caros.
Principais custos são linear scan, byte emission e code-memory allocation.
Cache behavior
Native translation remove repeated interpreter decode e switch dispatch.
Custo muda para:
- VM stack loads/stores;
- native branch prediction;
- helper transitions;
- bytecode-PC dispatch table em indirect control flow;
- instruction-cache footprint maior.
Um bytecode op pode virar dezenas de x86 bytes, então native footprint cresce bastante em relação ao CLV stream.
Sizing heuristic reflete essa expansão.
Evidência de benchmark
tools/test_jit_bench constrói infinite pixel loop e compara interpreter/JIT.
Threshold configurado:
MIN_SPEEDUP = 5.0
para esse microbenchmark.
É evidência útil de que intended native path remove interpreter overhead nesse loop gráfico.
Não significa que todo workload ChrisOS tenha speedup >=5x.
Helper-heavy, syscall-heavy, memory-bound e cache-sensitive code pode ter resultado diferente.
Evidência de native path
tools/test_jit_native compila:
- integer while loop;
- basic floating-point arithmetic.
Reseta helper counter e exige halt com:
helper_calls == 0
Isso valida direct native emission desses common paths.
tools/test_jit_vm compara interpreter/JIT state em loop com wait e verifica compilation do Cube sample quando presente.
tools/test_doom_jit_diff realiza differential work interpreter/JIT em workload maior.
Os testes são relevantes, mas não cobrem exaustivamente todos opcode/fault pairs.
Casos diferenciais faltantes
Source inspection indica necessidade de regressions explícitas para:
- signed DIV/MOD por zero;
- INT64_MIN / -1;
- UDIV/UMOD por zero;
- FDIV por +0/-0;
- BAD_ADDRESS fault_pc;
- RET underflow fault class;
- invalid CALLI target;
- invalid dispatch PC;
- PRINT ring;
- 64-bit IL locals/arguments;
- NEWOBJ/LDFLD/STFLD/CALLT/LDSTR em JIT;
- backward conditional-loop budget;
- straight-line budget;
- safepoint scheduler yield;
- hot reload com use_jit ativo;
- malformed truncated immediate durante compilation.
Sem esses casos, “interpreter/JIT equivalence” deve ser engineering goal, não propriedade já provada.
Security boundary
JIT compilation executa no kernel e transforma guest-provided bytecode em executable machine instructions.
Translator faz parte da kernel trust boundary.
Bug no interpreter normalmente vira contained ClvmFault.
Bug no emitted x86 pode gerar invalid kernel memory access ou CPU exception diretamente.
Division overflow e truncated-immediate scan mostram por que native translator precisa de validação mais forte que ordinary bytecode switch.
Idealmente JIT deve consumir apenas verified bytecode.
Limitações atuais
Na revisão documentada:
- JIT é x86-64;
- whole-image eager compilation, sem profiling/tiering;
- global scratch serializa compilation;
- native translation limitada a code_size <= 1 MiB;
- images maiores recebem interpreter wrapper enquanto slot pode continuar marcado use_jit;
- insn_len/image_can_jit não rejeitam rigorosamente truncated immediates;
- 58 de 72 opcodes são direct native;
- cinco helper-routed object/IL opcodes não existem em jit_rt_exec_op;
- helper LDARG/LDLOC/STLOC trunca 64-bit values;
- native signed/unsigned division fault behavior difere do interpreter;
- native FDIV não possui zero-divisor VM fault;
- vários native failures viram CLVM_FAULT_STACK_UNDERFLOW;
- BAD_ADDRESS fault_pc recebe tested address em vez de opcode PC;
- PRINT não atualiza interpreter print ring;
- native float results podem diferir nos upper 32 stack bits;
- budget é partial backedge counter, não instruction budget;
- conditional backward branches não recebem dedicated budget check;
- vm->executed não aumenta para direct native instructions;
- JIT safepoint/scheduling não é totalmente igual ao interpreter;
- hot reload não recompila nem desativa stale native code;
- não existe persistent cross-slot native code cache;
- strict W^X ainda não é completo, como documentado em jit-memory.
Fronteira de roadmap
Um JIT CLVM mais forte pode:
- verificar bytecode inteiro antes de emission;
- gerar opcode metadata a partir de schema único;
- criar native fault stub para cada interpreter fault;
- completar todos 72 opcodes ou rejeitar subset antes de compile;
- unificar helper stack em 64 bits;
- definir budget/safepoint contract independente do engine;
- manter vm->executed consistentemente;
- adicionar differential fuzzing completo interpreter/JIT;
- rebuild atomically durante hot reload;
- substituir global scratch por per-compilation state;
- criar reusable code cache keyed por image identity/revision;
- introduzir IR apenas se optimization goals justificarem complexidade;
- adicionar tiering/profile-guided optimization somente após forte semantic parity;
- endurecer executable publication para strict W^X.
São direções futuras até existirem em source/tests.
Mapa de source e revisão
compiler/jit/jit_compile.c controla bytecode scan, native coverage classification, x86-64 instruction selection, patch records, native dispatch table e compile locking.
compiler/jit/jit_emit.c é low-level x86-64 byte emitter.
compiler/jit/jit_runtime.c implementa helper execution e JIT/runtime bridge.
compiler/jit/jit.c controla native code memory, executable publication e per-CPU syscall context.
compiler/lang_pipeline.c escolhe JIT/interpreter, instala runtime context, chama JitFn e libera code com application slot.
compiler/clvm/clvm_vm.c continua sendo reference semantic engine para comparação.
Todas as afirmações de comportamento atual deste capítulo foram reconciliadas com ChrisOS revision e05a17fd76333114a3fb5c2452f38ca747d4ac56.